What Top Stories Inside AI Overviews Means For Publishers And Brands In 2026 And Beyond via @sejournal, @gregjarboe

John Shehata, CEO of NewzDash, found something in July that a lot of publishers threatening to block Google’s AI don’t realize is already happening underneath them. Google has started folding entire Top Stories carousels directly inside AI Overviews, and the robots.txt directive most publishers reach for first does nothing to stop it.

Shehata posted on LinkedIn that nearly one in six U.S. trending news queries now place Top Stories inside AI Overviews, and followed it with a full data breakdown on the NewzDash SEO for News blog.
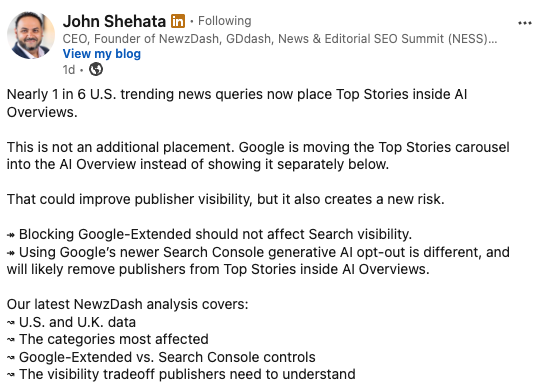
Screenshot from LinkedIn, July 2026

Google Has Run This Play Before

The topic he is describing is not new in kind, but it is new in mechanism. In 2006, John and I spoke on a panel about “Vertical Creep Into Regular Search Results” at the Search Engine Strategies New York conference. We discussed how Google was quietly pulling what appeared in Google News into its main web results before Universal Search formally arrived. Danny Sullivan called that May 2007 rollout the most radical change Google had ever shipped to its results, blending video, images, books, and news into a single ranked list instead of 10 blue links. Google’s own announcement framed it the same way, describing a shift toward one integrated set of results rather than separate verticals users had to hunt through individually.

Nineteen years later, Google is doing it again. This time the destination isn’t a blended results page. It’s an AI-generated answer.

What NewzDash’s Data Shows

According to NewzDash’s tracking, among trending news queries where Google displays Top Stories at all, 15.5% in the U.S. and 17.46% in the UK now show that carousel embedded inside the AI Overview rather than as its own standalone module below it. Entertainment queries lead both countries, clearing 35% in the U.S. and 31.5% in the UK. World News hits nearly 32% in the U.S. Health and Science queries barely register. Shehata’s data also shows the two placements are mutually exclusive. When Top Stories lives inside the AI Overview, Google is not also running a separate carousel further down the page for the same query.

That distinction matters more than it sounds like it should, because it reframes the entire opt-out conversation publishers have been having since AI Overviews launched.

Google-Extended Is Not An AI Overviews Opt-Out

Most publishers who want out point their robots.txt at Google-Extended and consider the matter settled. It isn’t. Google’s own crawler documentation states plainly that Google-Extended governs specified AI training and grounding uses, things like feeding future Gemini models or grounding certain Vertex AI responses, and explicitly does not affect a site’s inclusion in Google Search or function as a ranking signal. Blocking it does not remove a publisher from AI Overviews, AI Mode, standard Top Stories, or Top Stories embedded inside an AI Overview. Shehata is right to keep hammering on this, because the confusion is not a fringe misunderstanding. It’s the default assumption across the industry.

The Control That Reaches AI Overviews Is A Different One Entirely

Google began testing a generative AI exclusion inside Search Console in June, currently limited to a subset of UK site owners. It lets an eligible publisher exclude their links and content from AI Overviews, AI Mode, and generative Discover features specifically, without touching their eligibility for traditional Search. Google’s support documentation says an excluded site’s content won’t appear in those features and won’t even be used as an input for generating a response. Choose that setting and, by Shehata’s reading, you almost certainly lose your spot in the embedded Top Stories carousel too, since it’s just a collection of publisher links riding inside one of the covered surfaces.

Google has not confirmed what happens next at the layout level. Would the AI Overview keep showing an embedded carousel built from the publishers who remained opted in? Would Google fall back to a standalone Top Stories module instead? Nobody outside Mountain View knows yet, and Shehata is careful to label this a high-confidence interpretation rather than a documented outcome. That kind of restraint is rarer than it should be in AI SEO commentary right now, and it’s a large part of why I trust his data over the louder takes circulating on the same topic.

The Bigger Story Is Trust

I think the bigger story here is not the mechanics of Google-Extended versus the Search Console control, even though publishers genuinely need to understand that difference before they touch a setting. The bigger story is that AI Overviews’ central problem has always been trust, not visibility. Users don’t yet have a reliable way to know whether an AI-generated answer is drawing on something a credible newsroom actually reported or synthesizing something thinner. Pulling Top Stories, with its named publishers, real bylines, and direct links, into the body of the AI Overview instead of stacking it below a wall of generated text is a genuine, if incomplete, answer to that problem. I’ve watched Google reshuffle where news lives in its results since the “vertical creep” days of 2006. This is the first move in the AI Overview era that looks aimed at rebuilding trust rather than just reducing clicks to the open web.

Although this is my considered opinion, it comes with a caveat. A step in the right direction is not the same as a finished solution, and Google’s refusal to document what happens to publishers who opt out is exactly the kind of ambiguity that erodes the trust this move is supposed to build.

3 Things To Do This Week

For SEO practitioners managing news clients or in-house newsroom sites, three things are worth doing this week rather than waiting for Google to clarify the layout question.

First, separate your controls before you touch either one. Audit whether your site currently blocks Google-Extended, uses the new Search Console generative AI exclusion, or neither, and document which surfaces each one actually governs. Treating them as interchangeable is how a site accidentally forfeits AI Overview visibility while believing it only opted out of training data.

Second, if you have access to the Search Console exclusion, test it on a URL-prefix property or a single section before applying it sitewide. Google’s control supports inheritance between parent and child properties, which means a news publisher can trial the exclusion on, say, an opinion vertical and watch what happens to that section’s Top Stories eligibility before deciding whether the tradeoff is worth it domain-wide.

Third, start pulling Google’s generative AI performance reports in Search Console now, and pair them with a tool like NewzDash that tracks how often your URLs surface inside Top Stories carousels versus embedded AI Overview placements. You cannot make an informed opt-out decision without a baseline for how much visibility is actually at stake, and that baseline needs to exist before you flip the setting, not after.

Twenty years ago, “vertical creep” meant publishers had to figure out how a blended results page would treat their headlines. Today, it means figuring out how a generated answer treats them instead. The mechanism changed, but the need for publishers to understand exactly what they’re opting into, and out of, did not. John Shehata is doing the unglamorous work of documenting that shift in real time, and until Google says otherwise, his data is the closest thing the industry has to ground truth.

More Resources:


Featured Image: PeopleImages/Shutterstock

https://www.searchenginejournal.com/what-top-stories-inside-ai-overviews-means-for-publishers-and-brands-in-2026-and-beyond/584175/


What Opting Out Of Google’s AI Search Features Means Now via @sejournal, @MattGSouthern

Google is rolling out a Search Console setting that lets you pull your content out of AI Overviews, AI Mode, and Discover’s AI features without leaving Search. That’s a choice we haven’t had before, and regulators in the UK now require Google to offer it.

Whether to use it is a harder question than it seems because the tradeoffs keep stacking up. Tracking data released this week by NewzDash, which sells news-visibility tracking to publishers, found Top Stories carousels rendering inside AI Overviews on U.S. trending news results. That means opting out of AI could mean opting out of Top Stories.

Here’s what the new Search Console setting does, how it got here, and what’s worth knowing before you touch it.

What The Control Covers

The Search generative AI control lives under Settings in Search Console. Google is rolling it out to a subset of website owners, so not every account has it yet. The default option to include your website lets content appear as links and helps ground AI responses in AI Overviews, AI Mode, and Discover’s generative AI features, with whatever impressions and traffic that brings. Excluding your site removes it from those features, links included.

Google said it would begin respecting these changes on June 17. Changes generally take a few days to process, then content should drop out within one to two days, though caching can delay it.

The setting isn’t a ranking or inclusion signal anywhere else in Search, so using it shouldn’t affect regular results. It doesn’t override separate choices in Merchant Center or Google Ads, so Shopping participation stays its own decision. And it doesn’t touch AI training, which runs through a different control.

The choice began appearing on accounts outside the UK in July. Jamie Indigo, Director of Technical SEO at Cox Automotive, flagged the setting on a U.S. account on LinkedIn: “Search generative AI controls in Google Search Console. I’m not even British and it’s not even my birthday!”

How The Opt-Out Choice Took Shape

Until this year, there was no way to keep a page out of Google’s AI features without keeping it out of Search.

Robots.txt, noindex, and snippet directives have been around long before AI Overviews. None of these tools specifically separate generative features from others.

For example, Nosnippet removes content from AI Overviews, but it also takes out traditional snippets at the same time. This all-or-nothing approach was something Google acknowledged in January, when it mentioned it was exploring ways to opt out of AI features.

Google-Extended has addressed some of this issue. The robots.txt token controls whether crawled content can be used for training future Gemini models that power Gemini Apps and the Vertex AI API for Gemini, and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. It didn’t control whether content could appear in AI Overviews or AI Mode. Google’s crawler docs say Google-Extended doesn’t affect a site’s inclusion in Search and isn’t a ranking signal.

The Search Console setting offers a different choice by removing a site from Google’s AI features and nothing else. It was born through a regulator and a product team working on the same problem at once.

Google made a statement in January that landed the same day the UK’s Competition and Markets Authority opened a consultation on requiring AI opt-outs. In June, the CMA imposed a conduct requirement requiring Google to give websites more control over how their content is used in generative AI, and Google began testing the toggle with UK properties the same week. In the UK, this requirement makes the control obligations mandatory, with deadlines extending into next year.

When Traditional Features Sit Inside AI Surfaces

Google’s setting treats AI features and regular results as separate things. The issue with that is Google’s results don’t always separate AI and organic results. When a Top Stories carousel from organic search renders inside an AI Overview, one toggle may control both.

John Shehata, CEO and founder of NewzDash and GDdash, put a number on it: “Nearly 1 in 6 U.S. trending news queries now place Top Stories inside AI Overviews.” The 15.5% rate applies to tracked results where Google displayed Top Stories, not to all queries NewzDash tracked. The UK figure is 17.46%.

Additionally, he found the embedded carousel and the standalone version didn’t appear together. NewzDash hasn’t published sample sizes or collection dates alongside the figures.

Kyle Sutton, Head of SEO and AI Discovery at The Washington Post, sees the same pattern anecdotally. He wrote in a comment on Shehata’s post: “Anecdotally, seems we’re all seeing it a lot more often.” His comment doesn’t confirm NewzDash’s rate or how it was measured.

Shehata connects it to the new control: “Using Google’s newer Search Console generative AI opt-out is different, and will likely remove publishers from Top Stories inside AI Overviews.”

That’s his interpretation, which Google hasn’t officially confirmed. According to Google’s help page, sites that are excluded won’t show up in AI features. As of now, Google’s help page doesn’t say how the control handles a traditional feature that’s shown within an AI feature.

If his understanding is correct, choosing to opt out could mean missing out on placements that were never advertised as AI features.

What To Check Before Opting Out

Before anyone touches the new Search Console settings, there are three things to check:

  1. How much visibility your site gets from AI features
  2. Which of Google’s controls governs what.
  3. How the tradeoffs could affect your business.

Start with where your site shows up in AI features today. The generative AI performance report, also rolling out to a subset of accounts, shows impressions from AI features by page, country, device, and date. It combines AI Overviews and AI Mode, and it carries no clicks and no queries.

Broader analytics can show Google organic referrals, time on site, and conversions, but they can’t assign visits to either AI feature. In practice, that means there’s no clean baseline for AI traffic or conversions to weigh the decision against.

The CMA’s requirement says more data should come. Its interpretive notes list impressions, click-throughs, and click-through rate as metrics Google should provide, delivered “through a commonly accessible platform.”

I wrote about that gap when the setting launched without the data to use it. The reports only cover impressions today.

Vahe Arabian, founder and editor-in-chief of State of Digital Publishing, described the working answer this month: “The job isn’t picking a favourite dashboard; it’s blending them into one scorecard.”

Next, sort out which lever controls what. Here’s what the differences are:

  • The Search generative AI control affects links and grounding inside Search and Discover AI features.
  • Google-Extended controls specified Gemini model training, including training for models used in Search generative AI responses, plus grounding in Gemini Apps and Grounding with Google Search on Vertex AI.

Notably, Google-Extended does not determine what content shows up in Search. Search visibility is governed by factors like crawling, indexing, and preview controls, from Googlebot rules to noindex tags and snippet directives. Robots.txt only manages crawling, not content removal from Search. Shehata’s post highlighted the same distinction regarding Google-Extended.

Finally, weigh the variables that matter for your business. For news publishers, Top Stories exposure is one of the things the toggle may control. For ecommerce sites, site content and Merchant Center or Ads participation are separate decisions, because the control doesn’t override either.

For any business, the question is what showing up in AI features is worth against the traffic it may replace, and the honest answer is that the numbers to settle it don’t exist yet.

One argument against opting out has been on record since before the control shipped. Writing earlier this year, while the CMA was still weighing the requirement, Rahul Jain, CEO and co-founder of Noble, argued on LinkedIn: “Opting out of Google’s AI Overviews will hurt most publishers more than it helps.”

His reasoning is that exclusion takes websites away from where the attention is, rather than safeguarding them. Noble sells services designed to help brands appear in AI-generated answers.

The Limits Of The Available Controls

The Search Console control works at the property level, and page-level controls for grounding in generative Search features aren’t due until March 2027 under the CMA’s timeline.

In a recent paper published in the Journal of European Competition Law and Practice this spring, University of Oxford researcher Spencer Cohen and UCL competition-law PhD candidate Todd Davies shared their thoughts that this type of remedy might not be enough.

“We argue that forcing Google to let websites opt-out of appearing in AI Overviews would be ineffective,” Davies, who the paper discloses worked at Google as a software engineer until 2022, wrote in a LinkedIn post summarizing the paper. Their case is that an opt-out doesn’t protect publisher business models or create meaningful choice over how content is used.

Whether the control gives businesses a real choice or a symbolic one depends on data that doesn’t exist yet and placements that are still moving.

Looking Ahead: Click Data & Page-Level Controls Are Coming

Here’s what you can expect in the coming year regarding the decision.

The CMA requires Google to share click data and click-through rates, along with tools for publishers to assess those clicks, with most of these measures starting in December.

By March 2027, Google is required to offer more detailed page-level controls for generative Search features, providing a more precise option than the current property-based settings. Additionally, Google will need to report on its compliance every six months during the first year, moving to annual reports if the regulator is generally satisfied.

The two main things to keep an eye on are whether Google broadens these controls and reports beyond the current group of website owners, and whether the embedded Top Stories pattern becomes more widespread in tracked data. NewzDash has said it plans to test the opt-out effect directly.

Currently, the choice is available, but it’s not clear what the cost of using it might be, and the schedule for measuring that cost is in place.

More Resources:


Featured Image: Golden Dayz/Shutterstock

https://www.searchenginejournal.com/what-opting-out-of-googles-ai-search-features-means-now/584321/


Cloudflare’s PACT Is Not Live Yet – Decide Which Track Your Traffic Needs via @sejournal, @slobodanmanic

Cloudflare and the three major browser makers want to prove there is a human behind your traffic. They announced how on June 22, 2026, as more and more of that traffic comes from agents with no human behind it at all. PACT answers the case where a person is in the loop. The case the web is moving toward, an agent acting on its own, is something PACT doesn’t touch.

On June 22, Cloudflare announced PACT (Private Access Control Tokens) with Mozilla Firefox, Google Chrome, Microsoft Edge, and Shopify. The idea: A website that has, in Cloudflare’s words, “strong knowledge of personhood” issues an anonymous token, and your browser carries that token to other websites to prove a human is in the loop, or that a bot is an authorized agent. It is meant to replace CAPTCHAs and forced logins. Cloudflare’s reason is the agentic shift itself: The internet is moving from human-driven clicks to agent activity, and the old binary of block-or-allow no longer fits.

If this sounds like a tracking nightmare, one website vouching for you and the proof trailing you around the web, it is the exact thing PACT is built to avoid. The tokens are anonymous and unlinkable by design, the same approach behind the privacy-preserving tokens that already stand in for CAPTCHAs on much of the web: The website that issues one cannot see where you spend it, the website you hand it to cannot tie it back to you, and two uses cannot be linked. The aim is to prove a human is present without the logins, CAPTCHAs, and fingerprinting that do that invasively today. The harder question is who gets to be a trusted issuer of personhood, which is real power over who counts as human online, and it concentrates with the same few infrastructure companies.

3 Rival Browsers Backing 1 Protocol Is The Signal

Getting Chrome, Firefox, and Edge into the same room on anything at the access layer is rare, and adding Cloudflare and Shopify means the proposal spans the browser, the network edge, and a major commerce platform at once. When that group commits to a shared protocol, it tends to become real eventually, the way Privacy Pass and passkeys did. So PACT is worth watching.

It is also, today, only a proposal. The collaborators have committed to developing it and submitting it for standardization. Nothing has been released, there is no origin trial, and there is no version your website can check against this quarter. That gap between a serious coalition and a usable protocol is usually measured in years.

PACT Answers Whether A Human Is Present, Not Whether An Agent Is Allowed

PACT verifies that a human is present. That is the human-directed case: A person clicks something, or points an agent at a task, and there is a person in the loop to vouch for. It is a real case, and proving it cleanly without CAPTCHAs or tracking would be a genuine improvement.

Detecting a real human is worth doing, and as bots flood the web it gets more valuable, not less. A clean human signal is what anyone fighting fraud, fake accounts, or manipulated reviews wants, and the rarer real people get in the traffic, the more that signal is worth. But PACT answers only one of the two questions the agentic web is splitting along. Once no human is driving, you still have to know whether the autonomous agent is allowed to be here, acting for whom, permitted to do what. PACT does not answer that. By design, it answers the other one.

That second question has its own track, and other people are building it. Google registered its web agent under a verifiable identity. Web Bot Auth lets identifiable crawlers sign their requests. Estonia moved to issue agents state-backed ID codes with scoped permissions, view, edit, or pay, up to a limit. Those are all attempts to identify and authorize the agent itself. PACT is the personhood track. The access layer is splitting into two, and they are not interchangeable.

Decide Which Track Your Traffic Needs

There is nothing to implement, because nothing is live yet. The useful move while this is still a proposal is to figure out which track your traffic actually needs, because they are different problems with different infrastructure. If your risk is fraud and abuse from traffic pretending to be people, you want the personhood track, and PACT is the thing to follow. If your future is agents transacting on your website on a customer’s behalf, you want the authorization track, and PACT will not help you. Most websites have never had to separate those two, because until this year, a visitor was a person by default.

PACT is a real answer to a real question: Is there a person here? The mistake will be reading it as an answer to the question the agentic web actually turns on, which is what to do with an agent when there is no person behind it. That one is still open, and it is the one worth watching.

More Resources:


This post was originally published on No Hacks.


Featured Image: xiaobaiv/Shutterstock

https://www.searchenginejournal.com/cloudflares-pact-is-not-live-yet-decide-which-track-your-traffic-needs/580328/


Social Search Data For All, AI-Detected Pages Rank Lower – SEO Pulse via @sejournal, @MattGSouthern

Welcome to this week’s Pulse: updates on your search data sources, AI-flagged pages in rankings, and potential impacts of opting out of Google’s AI features.

Here’s what you need to know for your work.

Google Opens Search Console Social Reporting To Everyone

Google made Search Console platform properties available to everyone worldwide, three weeks after the limited rollout began.

Key Facts

Platform properties let you link an Instagram, TikTok, X, or YouTube account to Search Console and see which Google queries send people to your posts across Search, Discover, and Google News. Google also published a guide to analyzing social and video performance, including annotations for testing whether title or caption rewrites change search results.

Why This Matters

Search data about content on platforms you don’t own used to be a blind spot. Now, you can identify which searches bring up your social posts with the same reports you use for your website, and evaluate how changes affect that data. The reporting covers Google surfaces only, so views inside the apps themselves aren’t part of it.

Read our full coverage: Google Opens Search Console Social Reporting To Everyone

Heavily AI-Flagged Pages Still Rank Across Google’s Top 10

New data from Ahrefs shows that AI-heavy pages appear in every spot within Google’s top 10 rankings. However, pages its detector reads as mostly AI-written tend to rank lower compared to those with less AI-generated text.

Key Facts

The scores are provided by Ahrefs’ own detector, which it sells through Site Audit and Site Explorer, and the samples didn’t measure depth, originality, or accuracy. Last year’s analysis found that the correlation between AI scores and position was only 0.011 and didn’t show any clear link. Now, the latest report suggests that increased AI use tends to be associated with lower search positions.

Why This Matters

The data shows a connection rather than a cause-and-effect relationship. Ryan Law, one of the report’s co-authors, says it appears the quality tends to decrease as AI usage goes up, rather than Google directly responding to AI-generated content. Remember, while a high detector score could mean that a page warrants a closer look, it doesn’t mean the page is inherently poor or that Google has taken any action against it.

What SEO Professionals Are Saying

John Ozuysal, founder of House of Growth, wrote on LinkedIn that the data reflects how the content gets made:

“And most AI-generated content is lazy. Single-shot prompts. Paraphrasing what already exists. Zero original insight.

Your information gain score is effectively zero when you’re just copying and reorganizing what’s already ranking.”

He summed it up saying: “The problem is not using AI to scale; many people are multiplying 1000 by 0 and expecting something.”

Read our full coverage: Heavily AI-Flagged Pages Still Rank Across Google’s Top 10

AI Opt-Out May Cost Sites A Google Top Stories Spot

Google is displaying the Top Stories carousel within AI Overviews instead of as a separate module lower on the page, based on tracking data from NewzDash, a company that provides visibility tracking for news publishers.

Key Facts

In tracked news searches featuring Top Stories, 15.5% in the U.S. and 17.46% in the U.K. showed the carousel within the AI Overview. Interestingly, a separate Top Stories carousel never appeared alongside an AI Overview in the tracked results. Google’s Search Console setting for opting out of AI features covers AI Overviews and is rolling out to more site owners beyond the initial UK test.

Why This Matters

NewzDash founder John Shehata reads an opt-out as dropping a site from any Top Stories carousel rendered inside an AI Overview, a read he calls high-confidence rather than proven. No click data yet compares the two carousel versions, so what an opt-out gives up there isn’t measurable yet.

Read our full coverage: AI Opt-Out May Cost Sites A Google Top Stories Spot

Google’s Mueller: Fix Conflicting Metadata, Don’t Test It

Google’s John Mueller mentioned that there isn’t a publicly set order for resolving conflicting metadata, and he suggests that sites with conflicts should focus on fixing them rather than trying to see which source comes out on top.

Key Facts

The conversation started on Bluesky, where Sebastián Galanternik inquired about which source Google considers accurate when a feed and on-page structured data conflict on product availability. Mueller responded that sites with inconsistent metadata “should fix it, not analyze if it’ll work regardless,” noting that the weights and filters used can change over time.

Why This Matters

Keeping signals consistent across your feed, structured data, and visible page content is within your control. Rather than hoping Google chooses the right signal, you can help Google get it right by providing the same details across all surfaces.

Read our full coverage: Google’s Mueller: Fix Conflicting Metadata, Don’t Test It

Theme Of The Week: The Decisions Arrive Before The Data

Google continues to hand over controls and reports, but the information needed to interpret them is still incomplete. Platform properties reveal how social posts perform in search results, yet only on Google’s own surfaces. Ahrefs data links AI-flagged pages to lower rankings, but it doesn’t explain why. The AI opt-out feature provides a true control, and according to NewzDash, its cost includes a Top Stories placement with no click data yet, while Google keeps its process for resolving conflicting metadata undisclosed.

In all cases, the decision-making burden falls on you before the relevant data is available, making you rely more on your inputs and internal measurements.

Top Stories Of The Week

More Resources

Featured Image: Depiction Images/Shutterstock

https://www.searchenginejournal.com/seo-pulse-social-search-data-for-all-ai-detected-pages-rank-lower/584337/


Google May Treat Search Box Pages As A Site Quality Issue via @sejournal, @martinibuster

Google’s John Mueller and Martin Splitt discussed what happens when spammers abuse website search functions to create thousands of spammy search pages. They said that Google begins to treat those pages as hacked.

Website Search Spam And Quality Issues

Virtually every website has a search function, and something that’s not clearly understood is that using the search bar generates a search results page that contains the search query. What’s surprising is that it’s normal behavior for these web pages to generate a URL that can be used to access that search, creating a situation where a spammer can use the search bar to generate thousands of web pages containing mentions of a spammy brand, the URL, and spam-related keywords.

Google’s Mueller said that website search spam can become a quality issue if the spam pages can be indexed or are indexable. Mueller used the example of entering text into a search box to generate a web page that contains that spammy text, which is something that can happen.


Mueller says search spam can become a quality issue:

“There is one place where you could run into quality issues though with search results pages. Namely, if you let people search for things that are totally irrelevant to your website and your search results page includes those terms on those search results page and is indexable.

…And it’s not so much that someone has hacked your website to do this because your website is doing that freely and basically saying like, oh, you search for photos, here’s a photo. But because it’s accessible for any search term that comes up, it’s suddenly a liability. It’s more like a vector for other people to spam.”

That last bit about a search box becoming a vector for spamming is correct, if the web page allows those auto-generated pages to be indexed.

Google May Flag Internal Search Pages As Hacked

The other useful information that Mueller and Splitt shared is that they flag these kinds of spammed pages as if they are hacked, explaining that these kinds of pages can show up in Google’s search results.

Mueller explained:

“And we’ve seen that happen that people do that at scale. They will try to recognize common CMSs that don’t have their search results pages blocked and go off and link to thousands of sites with millions of pages, all with maybe some adult terms and a phone number or pharmaceuticals and a phone number or something else and a telegram address or some other kind of contact mechanism where the goal is not so much that people go to your site and kind of see your photos, but rather that in the search results they’ll see for these pharmaceuticals call this number.

And sometimes that does show up for these kind of queries. And when we see that happen, we might flag that as hacked. So in Search Console, you might see that as something that is flagged as hacked.”

Google Can Catch Spammed Search Result Pages Algorithmically

Mueller also explained that Google can algorithmically catch these kinds of pages and block them from showing up in search results. From the site owner’s side, this can feel like a win because Google handled it. Mueller cautions against assuming that the problem is taken care of.

How To Prevent Search Box Spam

Google’s Mueller and Splitt recommended two approaches for preventing search spam from becoming an issue:

  1. Prevent crawling
  2. Prevent indexing

Prevent Crawling

The first recommendation is to use a robots.txt to prevent Google and other search engines from crawling the auto-generated search box web pages.

Mueller and Splitt list four reasons to block indexing with robots.txt:

  1. Google doesn’t need to crawl search pages.
  2. It prevents infinite crawling.
  3. It reduces server load.
  4. It prevents crawl budget waste.

Regarding infinite crawling, Martin Splitt said that some implementations of search boxes can turn into an infinite “crawl space” where the search box keeps autogenerating web pages through a “did you mean” feature that’s triggered in response to Google’s crawling those search pages.

Splitt explains:

“So we learned a bunch of stuff about search results on websites. So they can be infinite crawl spaces because we can basically generate pages upon pages of these and maybe we even link to like, did you mean, and then we create even more that the crawler sinks into. And it sounds like they’re relatively easy to get rid of with robots.txt and or no index.”

The infinite crawl space issue is also linked to increased server load and putting stress on the website crawl budget.

John Mueller explained how infinite crawling, server load, and crawl budget waste are linked:

“And all of that basically means we find, or we could potentially find an infinite number of pages on your site. And I know some people are like, wow, if I had an infinite number of pages in Google, then I would be king.

But having an infinite number of pages known to Google is not a good thing because Google will try to crawl all of those pages. And you can imagine what happens when we see, I don’t know, 100 million pages that are new from Martin Split will go off and try to crawl those. So that’s something where then suddenly crawl budget becomes a question and your server load and your server’s like, oh my gosh.”

Those are all the reasons why Mueller and Splitt recommend using robots.txt to prevent crawling of search box pages. More precisely, they say to use as broad and general a robots.txt rule as possible that can catch all variations of auto-generated search box pages.

Noindex Directive

Mueller and Splitt mention using the robots noindex directive but say that robots.txt is both easier and the cleanest way to handle search box web pages.

Watch Episode 113 of Search Off The Record

[embedded content]

Featured Image by Shutterstock/Tirachard Kumtanom

https://www.searchenginejournal.com/google-may-treat-search-box-pages-as-a-site-quality-issue/584419/


WP Engine Partners With BigCommerce To Scale WordPress Stores via @sejournal, @martinibuster

WP Engine announced Commerce Connect, a partnership with BigCommerce that enables ecommerce stores to scale to the next level without any downtime or changes to SEO. Most importantly, Commerce Connect is not about replacing platforms but enabling a safe way to modernize and grow to the next level while preserving everything about the brand.

What WP Engine announced is about helping ecommerce stores migrate their business without downtime while also preserving SEO. Scaling and modernizing an ecommerce store can negatively impact search visibility, but WP Engine’s Commerce Connect solves that problem by preserving all of the WordPress SEO, design, and user experience, making the choice to scale a business an easy one.

Heather Brunner, Chairwoman and CEO at WP Engine, explained:

“Growing ecommerce brands shouldn’t have to choose between the WordPress experience they’ve invested in and the commerce capabilities they need to scale, our partnership with BigCommerce gives brands the flexibility to scale confidently, adapt as their business evolves, and build for what’s next.”

That part about “what’s next” is important because of the profound changes introduced by AI shopping, which Commerce Connect can address.

The official announcement shares how Commerce Connect works:

“By connecting BigCommerce’s enterprise commerce platform with WP Engine’s platform, high-growth midmarket brands can scale their ecommerce capabilities while leveraging the power of WordPress.

Keeping content and commerce connected also helps brands maintain consistent product information across their digital experiences, creating richer shopping journeys while strengthening product visibility as AI-powered search and discovery continue to evolve.”

Interview With VP of Product At WP Engine

Search Engine Journal had the opportunity ask more questions about Commerce Connect, Keith Fafel, VP of Product at WP Engine provided answers that should help ecommerce stores understand how the new product can help them.

Not About Replacing Platforms

What are the signs that a WordPress-based ecommerce store may need to modernize and step up to a more capable ecommerce solution? What advantages does Commerce Connect provide merchants who find themselves outgrowing WooCommerce and are ready to grow their business to the next level?

Fafel explained that this is not about replacing WordPress:

“We see WP Engine Commerce Connect for BigCommerce as solving a broader growth and platform challenge, while helping growing brands scale with confidence. It’s not about replacing one platform with another. Each ecommerce solution takes a different approach to helping brands create a successful online store. We want to keep growing the WordPress ecosystem, and this solution provides optionality for scaling ecommerce sites.

WP Engine Commerce Connect for BigCommerce provides several advantages to merchants. The biggest advantage is that it enables them to preserve the WordPress experiences they’ve already built while adding the enterprise commerce capabilities needed to support larger catalogs, higher traffic, and continued growth.”

How Commerce Connect Preserves SEO

Many businesses invest heavily in content, SEO, and custom WordPress experiences before they outgrow their ecommerce platform. How does this partnership help them preserve those investments while continuing to grow?

WP Engine’s Keith Fafel responded:

“WP Engine Commerce Connect for BigCommerce preserves build investments by allowing brands to keep their existing WordPress content, themes, custom designs, URL structures, and SEO foundation. Instead of rebuilding the consumer-facing experience, brands can modernize the commerce platform underneath it, reducing disruption while gaining the scalability and capabilities needed for continued growth.”

A Safe Path To Scale Ecommerce And Keep What Works

How does this partnership change what’s possible for WordPress merchants that wasn’t practical before?

Fafel answered:

“This partnership gives growing WordPress brands a new path to scale. Instead of choosing between preserving the digital experiences they’ve built or adopting more advanced commerce capabilities, they can now do both. This means merchants can continue to scale while preserving the content, design, SEO, and customer experiences that drive their business. This solution provides WP Engine customers with a choice for how they operate and scale their ecommerce business, while keeping them in the WordPress ecosystem.”

That is an interesting answer because it underlines that Commerce Connect is not a replacement for WordPress, it’s a way to preserve all the things that work with the WordPress platform while also modernizing and scaling.

What Kinds Of Business Benefit From Commerce Connect?

I asked WP Engine’s Keith Fafel to tell us what kinds of businesses stand to benefit the most from WP Engine Commerce Connect for BigCommerce, and what are the characteristics of a brand that needs to modernize with Commerce Connect.

Fafel explained that high-growth brands that feel they’re reaching the limits of their current platform stand to benefit:

“WP Engine Commerce Connect for BigCommerce is designed for high-growth, mid-market brands generating <$1M in GMV that are reaching the next stage of their ecommerce journey. They typically have established WordPress websites with significant investments in content, design, and SEO, and are experiencing growing product catalogs, higher traffic, and more complex commerce needs.

Rather than rebuilding what already works, these businesses want a way to modernize their commerce capabilities while preserving the digital experiences that have helped drive their growth.”

What capabilities do businesses typically discover they need as they scale and how does BigCommerce provide that?

Fafel answered:

“As merchants grow, they typically need to support larger product catalogs, higher traffic volumes, more complex operations, and need greater flexibility to adapt as their business evolves. Through our partnership with BigCommerce, the platform gives brands an enterprise-ready commerce foundation that scales with those needs, while allowing them to preserve the WordPress experiences that already drive their business.”

Learn more about Commerce Connect here.

Featured Image by Shutterstock/Dilok Klaisataporn

https://www.searchenginejournal.com/wp-engine-bigcommerce-wordpress-stores/584343/


AI Search Isn’t Replacing Google, It’s Layering On Top – Similarweb Data via @sejournal, @gregjarboe

Rand Fishkin, the co-founder and CEO of SparkToro, posted on LinkedIn on July 24, 2026, to say that Similarweb’s newest report would “probably infuriate” two groups at once. The AI zealots who are certain every marketing dollar should already be chasing chatbot visibility. And the AI skeptics who’ve suspected the hype was overblown but never had the receipts to prove it to a boss suffering from what Rand calls AI derangement syndrome.

Most industry reports comfort one camp and annoy the other. This one, Similarweb’s “2026 Generative AI Landscape: The Evolution of AI Search,” manages to hand both sides a data point that undercuts their certainty. I read all 38 pages because I’m into ground-truthing, and I want to walk through why Rand is right, what the report actually shows, and what you should do differently tomorrow morning because of it.

The Number That Should Worry The AI Zealots

Similarweb tracked audience overlap between ChatGPT and Google between March and May 2026, and 461 million of ChatGPT’s 494 million users (95%) also use Google in the same window. Almost nobody has left Google for ChatGPT. They’ve added ChatGPT to a Google habit that hasn’t budged.

Zoom out further, and the gap gets starker. Search still pulls 3.3 billion average monthly unique visitors worldwide. AI chatbots, even after growing 57% year over year, sit at 655 million. So, search is still roughly five times the size of the entire AI chatbot category combined. If your 2026 budget deck assumes AI search has already eclipsed traditional search, the math in this report says otherwise.

Citations tell the same story from a different angle. Only 6.8% of ChatGPT answers in the U.S. included a link to an external source as of May 2026. That’s up more than fivefold from around 1% a year earlier, which is genuinely fast growth, but it also means 93 out of every 100 ChatGPT answers still send nobody anywhere. Ethan Smith of Graphite makes a sharper point in the report about how users are folding those same prompting habits back into Google itself, with average search length climbing steadily since AI Mode launched. People aren’t abandoning search boxes. They’re just typing longer sentences into them.

The Number That Should Worry The AI Skeptics

Now for the half of the report that punctures the other side’s confidence. Average monthly web visits across generative AI platforms hit 9.5 billion between June 2025 and May 2026, up 70% year over year. App downloads worldwide climbed to 2.7 billion, up 134%. Half of all generative AI users are now 35 or older, compared to 61% under 34 just two years ago, which is the clearest signal I’ve seen that this isn’t a Gen Z fad running out its trend cycle. Michael Horrocks of Miro puts it plainly in the report: “Growth concentrated in younger demographics can fade with trends; growth spreading into older generations is often what durable, mainstream adoption looks like.”

Meta AI’s own disclosed numbers back that up from a completely different angle. Publicly reported monthly active users went from 384 million in September 2024 to 1.2 billion by March 2026, more than tripling in 18 months, entirely by riding inside Instagram, Facebook, WhatsApp, and Messenger rather than as a standalone destination anyone had to seek out. And ChatGPT ad penetration in the U.S. jumped from 14% of desktop chats in May 2026 to 26% just one month later. Whatever you think about the maturity of AI search, advertisers clearly don’t think it’s a toy.

My read is that both camps are pattern-matching off the piece of the data that confirms what they already believed, and both are ignoring the half that complicates it. AI search hasn’t replaced anything. It has stacked a new, fast-growing, unevenly distributed layer on top of a search ecosystem that was already there, and the practitioners who will win the next two years are the ones measuring the stack instead of arguing about which layer matters more.

Why The Disconnect Between Citations And Clicks Matters More Than Either Camp Realizes

The most useful chart in the whole deck, and the one I think gets underappreciated in the LinkedIn debate, comes from Aleyda Solis of Orainti. She points out that 65% of the URLs ChatGPT cites sit two or three folders deep, the pages doing the actual evidentiary work behind an AI answer. But 58.8% of the referral traffic that AI sends back to sites lands on the homepage, not the cited page at all. Cited pages and clicked pages are almost entirely different populations of URLs.

That single data point should reorganize how agencies report AI performance to clients. If you’re only tracking whether your deep product or blog content gets cited, you’re missing the fact that the humans who actually click through are landing somewhere else entirely and need their own conversion path. Rand makes a related point in the report itself, comparing this to how 20th-century advertisers proved billboard and radio spend worked by measuring lift in store visits rather than counting who glanced at the sign. The mechanism has changed. The discipline of measuring downstream behavior instead of surface impressions hasn’t.

3 Things To Change In Your Strategy This Week

1. Split your reporting into two separate metrics. Track citation rate and citation folder depth as one key performance indicator that measures whether AI trusts your content enough to use it as evidence. Track referral landing pages and downstream conversion as a completely separate KPI that measures what actually happens once a human clicks through. Conflating the two in a single dashboard is how brands miss both problems at once.

2. Stop treating “AI visibility” as a single category. Similarweb’s brand visibility index shows how category-specific this already is. CeraVe leads beauty at an index of 100 while NYX Cosmetics sits at 19 in the same category. Kevin Indig of Growth Memo argues in the report that share of voice is the metric that matters here because it’s a relative comparison in a stochastic system, not an absolute score. Pull your own category’s leaderboard before you assume you’re winning or losing.

3. Match your content to the platform’s actual audience, not the platform’s overall size. The affinity data shows ChatGPT skews toward everyday consumers researching restaurants, health, and fashion; Claude users are 25 times more likely than the average searcher to visit university sites and skew heavily toward professionals and students, and Gemini users over-index on graphics, security, and hardware content. A single piece of “AI-optimized” content aimed at all three is aimed at none of them.

The Bottom Line

I don’t think the AI zealots are wrong that something structural is shifting. Nine and a half billion monthly visits and a fivefold jump in citation rates in under a year are not a rounding error. But I also don’t think the skeptics are wrong that most of the industry’s AI panic is running well ahead of the actual traffic numbers, given that Google still commands five times the audience of every AI chatbot combined and 95 out of every 100 ChatGPT users never left Google in the first place. Rand’s post nailed the discomfort because the data refuses to let either side keep its story simple. The brands that will actually benefit from this report aren’t the ones picking a side. They’re the ones pulling the citation and referral numbers for their own category this quarter and building a strategy around what the data says rather than what the argument on LinkedIn says.

More Resources:


Featured Image: Rawpixel.com/Shutterstock

https://www.searchenginejournal.com/ai-search-isnt-replacing-google-its-layering-on-top-similarweb-data/583378/


89% Of AI Search Demand Has No Clear Owner: Use This Before The Window Closes via @sejournal, @gregjarboe

Kevin Indig just settled an argument that’s been running in half-finished form since AI Overviews launched. Does topical authority that rewards brands for going deep on a subject instead of wide, actually carry over into AI search? Or is ChatGPT enough of a blank slate that a generalist brand can walk in and grab a category cold?

Indig got access to six months (January-June 2026) of ChatGPT answers data from Semrush, spanning 1,094 U.S. categories, five prompts per category, more than 50,000 brands, and over 600,000 citations. He published the breakdown in his Growth Memo Substack on July 20, with the headline finding on LinkedIn the same day. His answer is that topical authority does matter in AI search, and the reason is durability. Once a brand earns an outsized share of mentions in a category, it tends to hold onto it.

Screenshot from LinkedIn, July 2026

That’s the tidy version. The messier and more useful version, buried a few paragraphs into his post, is that almost none of the market has settled yet.

The Categories That Matter Most Are The Ones Nobody Owns

Indig built three buckets. A category has a clear owner when one brand shows up in at least four of five test prompts and beats the runner-up by five percentage points or more. It’s an emerging leader when a brand leads at least three prompts without hitting that gap. Everything else, meaning no brand leads even three of five prompts, counts as unsettled.

Run those definitions across the full dataset, and June 2026 looks wide open. Only 15.2% of categories had a clear owner. Just over half, 53.7%, were open fields with multiple credible contenders and no brand close to locking the door.

Indig ranked all 1,094 categories by estimated AI search volume and split them into two even groups. The higher-volume half accounts for 98% of all AI search demand in the sample, and it has the lower owner rate of the two, 11.3% versus 19% for the lower-volume half. Stack that up and 89.3% of estimated AI search demand sits inside categories with no clear owner yet. The categories worth the most money to occupy are, right now, the least decided.

I’ve spent the past three years watching SEOs debate whether topical authority is a real algorithmic force or a convenient story agencies tell clients to justify a content calendar. Indig’s data is the first thing I’ve seen that actually resolves the question with a real number. Topical authority is real in AI search, and the brands still treating category focus as optional are giving away nine-figure categories to whoever bothers to show up consistently across all five prompt types. 

Owners Are Hard To Dethrone, But Only When The Lead Is Wide

The second half of Indig’s analysis is where the strategy gets sharper. He tracked month-over-month leadership changes across the same categories and found that a clear owner held first place in 90.4% of comparisons.

The switches that did happen were concentrated almost entirely in categories where the lead was already thin. Categories where the leader changed had a median lead of just 1.3 percentage points going into the switch. Categories where the leader held on had a median lead more than double that, 2.9 points. Growth trajectory told Indig almost nothing on its own. He shows three examples where a leading brand trended upward month over month and still got overtaken, because a competitor simply grew faster or closed a narrow gap. The lesson isn’t that momentum is meaningless. It’s that a one- or two-point lead is not a lead worth defending yet, and a brand sitting in that range should assume it’s still in a fight.

Indig also found something that undercuts a common assumption about how ownership gets built. Citations and brand mentions turned out to be only weakly related, with a slightly negative correlation of -0.229. The most frequently cited domain in a category was rarely the same as the most frequently mentioned brand, matching up only 20.8% of the time. But the most mentioned brand was cited at least once 69.9% of the time. Getting cited a lot doesn’t automatically make you the brand ChatGPT reaches for by default. That’s a meaningful distinction for anyone whose GEO strategy currently starts and ends with “get more citations.”

Owners did share some traits versus their runner-up: higher branded search volume in 55.7% of pairs, higher organic traffic in 48.4%, and a higher Semrush Authority Score in 52.5%. Indig is careful to call these correlations rather than a formula. A brand doesn’t earn ChatGPT’s default answer by buying branded search volume. It earns it by being the source ChatGPT’s training and retrieval keep landing on when the model tries to answer all five variations of a question, the definition, the comparison, the alternatives list, the use case, and the buying decision. 

How To Use This Before The Window Closes

Here’s where I’d point a practitioner’s next quarter of work, adapted from Indig’s framework and my own Citation Share of Voice approach to tracking AI mentions.

  • Pick your battlefield first, then measure it properly. List the 10 to 20 categories where your brand actually needs to be the default answer. For each one, track the same five prompt types Semrush used, a definition question, a comparison, an alternatives list, a use case, and a buying question, not just your brand name in isolation.
  • Sort by lead size, not by whether you’re currently “winning.” A category where you lead by 1.5 points is not a category you’ve won. Treat anything under roughly 3 points as contested and put real resourcing behind closing the remaining prompt gaps, since Indig’s data shows that’s the exact range where turnover happens.
  • Stop chasing citations as the whole strategy. Use citations to earn your way into the answer set, then shift budget toward the specific content types, comparison pages, proof points, third-party coverage, and clear positioning, that determine whether you’re the brand actually named once you’re in the room.

The GEO conversation over the past year has fixated almost entirely on citation counts because citations are the easiest thing to drop into a dashboard. Indig’s data says citations are a door, not the room. Practitioners who keep optimizing for the door while a competitor optimizes for being the name ChatGPT actually says out loud are going to lose categories they thought they were winning.

The window Indig describes won’t stay open. Eighty-nine percent of demand sitting in unsettled categories is an unusually generous head start, and the brands that move on it in the next few quarters, rather than treating this as one more report to bookmark, are the ones that will still be the default answer when somebody runs this same study in 2027.

More Resources:


Featured Image: Roman Samborskyi/Shutterstock

https://www.searchenginejournal.com/89-of-ai-search-demand-has-no-clear-owner-use-this-before-the-window-closes/583255/


European Search Strategy Goes Beyond Google & Bing via @sejournal, @motokohunt

If you approach European search strategy as a single, unified market, you’ll miss how fragmented and how regulated discovery actually is across the region. This article is the European companion to my recent look at APAC search strategy. Google is still dominant almost everywhere, but the mechanics behind that dominance and the forces chipping away at it look nothing like a single-engine story.

A quick scope note: Europe isn’t one market; it’s dozens of them, and no single column can do justice to them all. The examples below lean on Germany, the Czech Republic, the UK, and France, where the shifts described here are furthest along. Southern and Eastern Europe warrant their own article.

In Germany’s search market, Google’s at around 80%, but Bing now has a genuine 10% share, and Yahoo, DuckDuckGo, and Ecosia split the rest. Local engine Ecosia deserves a second look as it just posted its best-ever home-market number, which tracks with how seriously German consumers take privacy and sustainability as buying criteria, not just marketing copy.

In Czechia, another local engine, Seznam.cz, holds around a 12% share, compared with Google’s 81%. No other EU country has a domestic engine anywhere close to double digits.

Bing’s real strength doesn’t even show up in the combined mobile-desktop number people usually quote. Look at desktop alone, where enterprise laptops and default Windows installs live, and Bing’s share climbs to several times its overall figure. Microsoft keeps pushing that gap wider by baking Copilot further into Edge and Windows 11.

Local engines holding real share here comes down to two things: privacy preferences and regulation, not a data quirk. Regulation is the bigger factor. The Digital Markets Act (DMA), AI Act, and GDPR get treated like paperwork everywhere else. Here, they change what shows up in search results. A ruling can hand a rival engine access it never had, or pull a feature off the market entirely, and both things have already happened this year. Search teams used to worry about ranking. Now they need to worry about whether they’re even allowed to be visible in a given market, and how quickly that can change under them.

The Forces Reshaping Discovery In Europe

1. AI-Driven Answer Systems, On A Delayed Timeline

AI Overviews have been deployed in most EU markets well after the U.S. and 200+ other countries.  Many of the new features shown at Google I/O routinely carry an unstated “not available in Europe” footnote tied to DMA and AI Act review. That lag is real but closing: ChatGPT, Perplexity, and Mistral’s Le Chat are already seeing meaningful EU usage, and once regulatory sign-off catches up, adoption within Google’s own results is likely to move fast.

2. Marketplaces And Comparison Engines Absorbing The Query

Many product searches in Europe never touch Google at all. Someone looking for a jacket or a blender just opens their local version of Amazon or goes straight to Zalando, Otto, or Allegro depending on the country. Comparison sites like Idealo and Kelkoo also attract consumers from Google. AI is dramatically accelerating this shift. Marketplace search bars now handle much of the query understanding themselves, and shopping assistants may pull product data directly from marketplace listings and feeds instead of going to a brand’s own site. That means titles, structured attributes, and review counts on a marketplace listing are doing real SEO work now, whether a brand treats them that way or not. Most teams still hand that off to whoever manages the Amazon account and never connect it back to discoverability at all.

3. Regulation As A Strategic Constraint And Opportunity

Regulation challenges appear in Europe on two fronts simultaneously. Under Article 6(11) of the DMA, the Commission adopted a binding decision on July 16, 2026 specifying how Google must share anonymized ranking, query, click, and view data with rival engines and AI chatbot providers. Sharing starts in January 2027, and it hands Google’s competitors a dataset advantage no regulator has enforced elsewhere.

In the UK, the Competition and Market’s Authority’s (CMA) Strategic Market Status designation on Google in October 2025 has produced requirements that enable local publishers to opt out of AI Overviews without losing organic visibility, provide clear attribution and engagement metrics, and let users port search data to authorized third parties.

The other large change that has strategic opportunities is created by potential legal exposure for incorrect or slanderous AI Overviews. The GDPR and AI Act carry real teeth, creating transparency rules for user-facing AI taking effect on August 2, 2026. In May 2026, a Munich Regional Court ruling found Google directly liable for false AI Overview claims that wrongly linked two publishers to scams, treating the summaries as Google’s own authored speech rather than neutral search results. This means the legal shield that’s always protected the search engines doesn’t automatically cover generative answers. The ruling is under appeal and not settled law, but if it holds, its reasoning plausibly extends to any answer engine that synthesizes claims about real businesses.

The upside for brands is this legal exposure will result in avoiding any reference it cannot  verify. This means those brands with a detailed, consistent, and machine-readable identity have a genuine visibility advantage they can start to take advantage of or at least start closing any gaps.

Answer-Layer Visibility And Europe’s Tokenization Problem

As AI Overviews, Perplexity, ChatGPT, and Le Chat expand in the region, visibility increasingly depends on being selected and cited as a source. This challenge requires brands to structure content for clean extraction with clear definitions, direct comparisons, and well-supported claims. Attribution matters more here too, given how aggressively European publishers and regulators are litigating AI training and citation.

There’s a technical layer beneath this that rarely comes up: how well a language tokenizes. Most LLM tokenizers are trained on English-heavy corpora, and Asia has a structural advantage here despite looking less familiar; Chinese and Japanese characters are individually dense with meaning and have huge training corpora behind them, so character-aware tokenizers handle them reasonably well; Korean’s agglutination got years of dedicated tokenizer investment from Naver and Kakao specifically.

European language processing seems like it should tokenize similarly to English, since it shares the same character set; while it uses the same generic tokenizer, the grammar doesn’t match, and it fragments quietly. Turkish and Hungarian are the most at risk, as these languages stack case, tense, and possession onto a single root and require splitting one semantic unit into several tokens that may change meaning. German’s compound nouns get cut at statistically common boundaries rather than at the boundary between component ideas. For brands publishing in German, Hungarian, or Turkish, this isn’t solved by translation alone or by using more declarative sentences that tokenize more cleanly, but by ensuring there is incremental and critical geo-specific content. It’s a genuinely new localization discipline, and almost nobody is doing it systematically yet.

Measurement Needs To Catch Up

Another critical challenge for brands is consent banners. They are blocking the measurement and implementation work itself. When a user declines consent, that session’s AI-referral and conversion data often just isn’t captured, and the gap skews toward more privacy-conscious users rather than at random. The same frameworks increasingly gate tag-manager script execution broadly, which means schema deployed via Google Tag Manager can silently fail to fire for a meaningful share of visitors, not just analytics pixels. Teams should confirm schema fires pre-consent, or move critical structured data into the page’s actual source rather than a gated script. Server-side tagging is the real fix, but it’s an infrastructure project, not a quick one.

What To Do Next

  • Deepen regulatory monitoring. Implement a quarterly review of DMA proceedings, the Munich ruling’s appeal status, UK CMA deadlines, and AI Act phase-ins, tracked jointly by search/content and legal.
  • Put a marketplace and comparison-engine audit on this quarter’s roadmap. Listing quality, structured attributes, and review coverage on Amazon’s EU storefronts and relevant comparison engines, treated with on-site technical-issue urgency.
  • Monitor and fix consent-gated schema and dynamic scripts. Confirm structured data and other scripts are not failing to load, then invest in tokenization-aware rewrites; no point optimizing content a bot never sees.
  • Rebuild the analytics stack in priority order. Segment by engine and discovery type, track AI referrals explicitly, treat server-side tagging as the real fix for consent-driven data loss.
  • Tighten entity clarity now. Ahead of any Munich appeal outcome, by implementing consistent naming and verifiable claims, make it easier for an increasingly liability-conscious answer engine to cite you rather than hedge you out.

Content teams should leverage their learnings and content that already performs well in the U.S. or APAC as a proof point for European implementations. This allows the teams to adapt to local regulatory context, currency, and examples and not start from scratch.

Closing Thought

Europe gets called slow to adopt AI, and the delayed feature launches make that easy to believe on the surface. Look closer, though, and search is moving under the same AI-driven pressure as everywhere else, just routed through a different set of pipes: engines most global teams never budget for, marketplaces that absorb the query before Google sees it, and a regulatory layer that occasionally opens a door or closes one. Regulation is worth watching, but it’s the smaller half of the problem. The bigger one is distribution itself. The teams that figure out where discovery is actually happening and build for those specific channels will be ahead of those still treating Europe as one Google-shaped market.

More Resources:


Featured Image: xtock/Shutterstock

https://www.searchenginejournal.com/european-search-strategy-goes-beyond-google-bing/581780/


Google Opens Search Console Social Reporting To Everyone via @sejournal, @MattGSouthern

  • Platform properties are now open to everyone, three weeks after the rollout began.
  • Google published a guide on reading the Search data behind social and video posts.
  • Search Console now reports on content you publish off your own site.

Search Console platform properties are now open to everyone worldwide, and Google has published a guide to reading your social and video search data.

https://www.searchenginejournal.com/google-opens-search-console-social-reporting-to-everyone/584144/