Australian government trial finds AI is much worse than humans at summarizing

ASIC evaluators found AI summaries were often "wordy and pointless—just repeating what was in the submission."
Enlarge / ASIC evaluators found AI summaries were often “wordy and pointless—just repeating what was in the submission.”
Getty Images


As large language models have continued to rise in prominence, many users and companies have focused on their useful ability to quickly summarize lengthy documents for easier human consumption. When Australia’s Securities and Investments Commission (ASIC) looked into this potential use case, though, it found that the summaries it was able to get from the Llama2-70B model were judged as significantly worse than those provided by humans.

ASIC’s proof-of-concept study (PDF)—which was run in January and February, written up in March, and published in response to a Senate inquiry in May—has a number of limitations that make it hard to generalize about the summarizing capabilities of state-of-the-art LLMs in the present day. Still, the government study shows many of the potential pitfalls large organizations should consider before simply inserting LLM outputs into existing workflows.

Keeping score

For its study, ASIC teamed up with Amazon Web Services to evaluate LLMs’ ability to summarize “a sample of public submissions made to an external Parliamentary Joint Committee inquiry, looking into audit and consultancy firms.” For ASIC’s purposes, a good summary of one of these submissions would highlight any mention of ASIC, any recommendations for avoiding conflicts of interest, and any calls for more regulation, all with references to page numbers and “brief context” for explanation.

In addition to Llama2-70B, the ASIC team also considered the smaller Mistral-7B and MistralLite models in the early phases of the study. The comparison “supported the industry view that larger models tend to produce better results,” the authors write. But, as some social media users have pointed out, Llama2-70B has itself now been surpassed by larger models like ChatGPT-4o, Claude 3.5 Sonnet, and Llama3.1-405B, which score better on many generalized quality evaluations.
More than just choosing the biggest model, though, ASIC said it found that “adequate prompt engineering, carefully crafting the questions and tasks presented to the model, is crucial for optimal results.” ASIC and AWS also went to the trouble of adjusting behind-the-scenes model settings such as temperature, indexing, and top-k sampling. (Top-k sampling is a technique that involves selecting the most likely next words or tokens based on their probabilities predicted by the model.)

“The summaries were quite generic, and the nuance about how ASIC had been referenced wasn’t coming through in the AI-generated summary… “
ASIC Digital and Transformation Lead Graham Jefferson

ASIC used five “business representatives” to evaluate the LLM’s summaries of five submitted documents against summaries prepared by a subject matter expert (the evaluators were not aware of the source of each summary). The AI summaries were judged significantly weaker across all five metrics used by the evaluators, including coherency/consistency, length, and focus on ASIC references. Across the five documents, the AI summaries scored an average total of seven points (on ASIC’s five-category, 15-point scale), compared to 12.2 points for the human summaries.

Missing the nuance

By far the biggest weakness of the AI summaries was “a limited ability to analyze and summarize complex content requiring a deep understanding of context, subtle nuances, or implicit meaning,” ASIC writes. One evaluator highlighted this problem by calling out an AI summary for being “wordy and pointless—just repeating what was in the submission.”

“What we found was that in general terms… the summaries were quite generic, and the nuance about how ASIC had been referenced wasn’t coming through in the AI-generated summary in the way that it was when an ASIC employee was doing the summary work,” Graham Jefferson, ASIC’s digital and transformation lead, told an Australian Senate committee regarding the results.

The evaluators also called out the AI summaries for including incorrect information, missing relevant information, or highlighting irrelevant information. The presence of AI hallucinations also meant that “the model generated text that was grammatically correct, but on occasion factually inaccurate.”

Added together, these problems mean that “assessors generally agreed that the AI outputs could potentially create more work if used (in current state), due to the need to fact check outputs, or because the original source material actually presented information better.”

Just a concept

These results might seem like a pretty conclusive point against using LLMs for summarizing, but ASIC warns that this proof-of-concept study had some significant limitations. The researchers point out that they only had one week to optimize their model, for instance, and suspect that “investing more time in this [optimization] phase may yield better and more accurate results.”

The focus on the (now-outdated) Llama2-70B also means that “the results do not necessarily reflect how other models may perform” the authors warn. Larger models with bigger context windows and better embedding strategies may have more success, the authors write, because “finding references in larger documents is a notoriously hard task for LLMs.”

Despite the results, ASIC says it still believes “there are opportunities for Gen AI as the technology continues to advance… Technology is advancing in this area and it is likely that future models will improve performance and accuracy of results.”

https://arstechnica.com/?p=2047265


Oprah’s upcoming AI television special sparks outrage among tech critics

An ABC handout promotional image for
Enlarge / An ABC handout promotional image for “AI and the Future of Us: An Oprah Winfrey Special.”

On Thursday, ABC announced an upcoming TV special titled, “AI and the Future of Us: An Oprah Winfrey Special.” The one-hour show, set to air on September 12, aims to explore AI’s impact on daily life and will feature interviews with figures in the tech industry, like OpenAI CEO Sam Altman and Bill Gates. Soon after the announcement, some AI critics began questioning the guest list and the framing of the show in general.

“Sure is nice of Oprah to host this extended sales pitch for the generative AI industry at a moment when its fortunes are flagging and the AI bubble is threatening to burst,” tweeted author Brian Merchant, who frequently criticizes generative AI technology in op-eds, social media, and through his “Blood in the Machine” AI newsletter.

“The way the experts who are not experts are presented as such 💀 what a train wreck,” replied artist Karla Ortiz, who is a plaintiff in a lawsuit against several AI companies. “There’s still PLENTY of time to get actual experts and have a better discussion on this because yikes.”

The trailer for Oprah’s upcoming TV special on AI.

On Friday, Ortiz created a lengthy viral thread on X that detailed her potential issues with the program, writing, “This event will be the first time many people will get info on Generative AI. However it is shaping up to be a misinformed marketing event starring vested interests (some who are under a litany of lawsuits) who ignore the harms GenAi inflicts on communities NOW.”

Critics of generative AI like Ortiz question the utility of the technology, its perceived environmental impact, and what they see as blatant copyright infringement. In training AI language models, tech companies like Meta, Anthropic, and OpenAI commonly use copyrighted material gathered without license or owner permission. OpenAI claims that the practice is “fair use.”

Oprah’s guests

According to ABC, the upcoming special will feature “some of the most important and powerful people in AI,” which appears to roughly translate to “famous and publicly visible people related to tech.” Microsoft co-founder Bill Gates, who stepped down as Microsoft CEO 24 years ago, will appear on the show to explore the “AI revolution coming in science, health, and education,” ABC says, and warn of “the once-in-a-century type of impact AI may have on the job market.”

As a guest representing ChatGPT-maker OpenAI, Sam Altman will explain “how AI works in layman’s terms” and discuss “the immense personal responsibility that must be borne by the executives of AI companies.” Karla Ortiz specifically criticized Altman in her thread by saying, “There are far more qualified individuals to speak on what GenAi models are than CEOs. Especially one CEO who recently said AI models will ‘solve all physics.’ That’s an absurd statement and not worthy of your audience.”

In a nod to present-day content creation, YouTube creator Marques Brownlee will appear on the show and reportedly walk Winfrey through “mind-blowing demonstrations of AI’s capabilities.”

Brownlee’s involvement received special attention from some critics online. “Marques Brownlee should be absolutely ashamed of himself,” tweeted PR consultant and frequent AI critic Ed Zitron, who frequently heaps scorn on generative AI in his own newsletter. “What a disgraceful thing to be associated with.”

Other guests include Tristan Harris and Aza Raskin from the Center for Humane Technology, who aim to highlight “emerging risks posed by powerful and superintelligent AI,” an existential risk topic that has its own critics. And FBI Director Christopher Wray will reveal “the terrifying ways criminals and foreign adversaries are using AI,” while author Marilynne Robinson will reflect on “AI’s threat to human values.”

Going only by the publicized guest list, it appears that Oprah does not plan to give voice to prominent non-doomer critics of AI. “This is really disappointing @Oprah and frankly a bit irresponsible to have a one-sided conversation on AI without informed counterarguments from those impacted,” tweeted TV producer Theo Priestley.

Others on the social media network shared similar criticism about a perceived lack of balance in the guest list, including Dr. Margaret Mitchell of Hugging Face. “It could be beneficial to have an AI Oprah follow-up discussion that responds to what happens in [the show] and unpacks generative AI in a more grounded way,” she said.

Oprah’s AI special will air on September 12 on ABC (and a day later on Hulu) in the US, and it will likely elicit further responses from the critics mentioned above. But perhaps that’s exactly how Oprah wants it: “It may fascinate you or scare you,” Winfrey said in a promotional video for the special. “Or, if you’re like me, it may do both. So let’s take a breath and find out more about it.”

https://arstechnica.com/?p=2046747


Cops’ favorite face image search engine fined $33M for privacy violation

Cops’ favorite face image search engine fined $33M for privacy violation

A controversial facial recognition tech company behind a vast face image search engine widely used by cops has been fined approximately $33 million in the Netherlands for serious data privacy violations.

According to the Dutch Data Protection Authority (DPA), Clearview AI “built an illegal database with billions of photos of faces” by crawling the web and without gaining consent, including from people in the Netherlands.

Clearview AI’s technology—which has been banned in some US cities over concerns that it gives law enforcement unlimited power to track people in their daily lives—works by pulling in more than 40 billion face images from the web without setting “any limitations in terms of geographical location or nationality,” the Dutch DPA found. Perhaps most concerning, the Dutch DPA said, Clearview AI also provides “facial recognition software for identifying children,” therefore indiscriminately processing personal data of minors.

Training on the face image data, the technology then makes it possible to upload a photo of anyone and search for matches on the Internet. People appearing in search results, the Dutch DPA found, can be “unambiguously” identified. Billed as a public safety resource accessible only by law enforcement, Clearview AI’s face database casts too wide a net, the Dutch DPA said, with the majority of people pulled into the tool likely never becoming subject to a police search.

“The processing of personal data is not only complex and extensive, it moreover offers Clearview’s clients the opportunity to go through data about individual persons and obtain a detailed picture of the lives of these individual persons,” the Dutch DPA said. “These processing operations therefore are highly invasive for data subjects.”

Clearview AI had no legitimate interest under the European Union’s General Data Protection Regulation (GDPR) for the company’s invasive data collection, Dutch DPA Chairman Aleid Wolfsen said in a press release. The Dutch official likened Clearview AI’s sprawling overreach to “a doom scenario from a scary film,” while emphasizing in his decision that Clearview AI has not only stopped responding to any requests to access or remove data from citizens in the Netherlands, but across the EU.

“Facial recognition is a highly intrusive technology that you cannot simply unleash on anyone in the world,” Wolfsen said. “If there is a photo of you on the Internet—and doesn’t that apply to all of us?—then you can end up in the database of Clearview and be tracked.”

To protect Dutch citizens’ privacy, the Dutch DPA imposed a roughly $33 million fine that could go up by about $5.5 million if Clearview AI does not follow orders on compliance. Any Dutch businesses attempting to use Clearview AI services could also face “hefty fines,” the Dutch DPA warned, as that “is also prohibited” under the GDPR.

Clearview AI was given three months to appoint a representative in the EU to stop processing personal data—including sensitive biometric data—in the Netherlands and to update its privacy policies to inform users in the Netherlands of their rights under the GDPR. But the company only has one month to resume processing requests for data access or removals from people in the Netherlands who otherwise find it “impossible” to exercise their rights to privacy, the Dutch DPA’s decision said.

It appears that Clearview AI has no intentions to comply, however. Jack Mulcaire, the chief legal officer for Clearview AI, confirmed to Ars that the company maintains that it is not subject to the GDPR.

“Clearview AI does not have a place of business in the Netherlands or the EU, it does not have any customers in the Netherlands or the EU, and does not undertake any activities that would otherwise mean it is subject to the GDPR,” Mulcaire said. “This decision is unlawful, devoid of due process and is unenforceable.”

But the Dutch DPA found that GDPR applies to Clearview AI because it gathers personal information about Dutch citizens without their consent and without ever alerting users to the data collection at any point.

“People who are in the database also have the right to access their data,” the Dutch DPA said. “This means that Clearview has to show people which data the company has about them, if they ask for this. But Clearview does not cooperate in requests for access.”

Dutch DPA vows to investigate Clearview AI execs

In the press release, Wolfsen said that the Dutch DPA has “to draw a very clear line” underscoring the “incorrect use of this sort of technology” after Clearview AI refused to change its data collection practices following fines in other parts of the European Union, including Italy and Greece.

While Wolfsen acknowledged that Clearview AI could be used to enhance police investigations, he said that the technology would be more appropriate if it was being managed by law enforcement “in highly exceptional cases only” and not indiscriminately by a private company.

“The company should never have built the database and is insufficiently transparent,” the Dutch DPA said.

Although Clearview AI appears ready to defend against the fine, the Dutch DPA said that the company failed to object to the decision within the provided six-week timeframe and therefore cannot appeal the decision.

Further, the Dutch DPA confirmed that authorities are “looking for ways to make sure that Clearview stops the violations” beyond the fines, including by “investigating if the directors of the company can be held personally responsible for the violations.”

Wolfsen claimed that such “liability already exists if directors know that the GDPR is being violated, have the authority to stop that, but omit to do so, and in this way consciously accept those violations.”

https://arstechnica.com/?p=2046793


Chef di Dubai confessa: ‘La mia super pizza inventata da ChatGPT’

“In qualità di chef, non avrei mischiato questi ingredienti su una pizza, ma detto questo il mix di sapori è davvero buono”. Lo ha detto uno chef di Dubai che ha usato ChtGPT, il chat bot di OpenAI, per inventarsi una nuova ricetta per la pizza  che ha avuto un grande success e che va via come il pane.

Pizza figlia dell’AI gran successo

Spartak Arutyunyan, responsabile dello sviluppo dei menu per la catena internazionale di pizzerie Dodo Pizza, ha detto alla BBC che la ricetta risultante “è stata in realtà un enorme successo, ed è ancora nel menu”.

Nel tentativo di riflettere le tradizioni culinarie di Dubai, ChatGPT ha fatto di tutto, suggerendo un mix selvaggio e stravagante di ingredienti. La ricetta include “pollo arabo shawarma, formaggio paneer indiano grigliato, erbe Za’atar mediorientali e salsa tahini”.

Mix vincente

In altre parole, il chatbot ha deciso di creare un miscuglio di sapori interculturali da mettere insieme su una pizza piuttosto che su un alimento più originale. E il tentativo ha colto nel segno.

“Come chef, non mescolerei mai questi ingredienti su una pizza, ma comunque il mix di sapori era sorprendentemente buono”, ha detto Arutyunyan alla BBC.

Gli scarti del menù

Arutyunyan poi ha detto che al contrario altre ricette proposte da ChatGPT non hanno avuto per nulla successo, compresa una pizza condita con fragole e pasta, o una torta con mirtilli e cereali per la colazione.

Altre iniziative culinarie basate sul’AI hanno fatto flop, come ad esempio il “negozio di frullati su misura” chiamato BetterBlends a San Francisco, che ha chiuso i battenti dopo che la sua attività di ricette di frullati iper-personalizzati non è riuscita a prendere piede.

Flop ma anche nuove idee

Anche un negozio di tacos a Dallas si è dilettato con l’intelligenza artificiale generativa, con risultati altrettanto contrastanti.

La direttrice culinaria di Velvet Taco, Venecia Willis, ha detto alla BBC che ChatGPT ha sputato fuori alcune “combinazioni stravaganti”.

“Penso che l’intelligenza artificiale sia un ottimo strumento da utilizzare quando sei in un momento di crisi creativa, per rimettere in moto il cervello – ‘quella combinazione potrebbe davvero funzionare, proviamola’”, ha detto. “L’intelligenza artificiale può suggerire qualcosa a cui forse non avresti pensato”.

Altri esperti sono invece molto più scettici riguardo all’uso dei chatbot IA in cucina.

Leggi le altre notizie sull’home page di Key4biz

https://www.key4biz.it/chef-di-dubai-confessa-la-mia-super-pizza-inventata-da-chatgpt/502788/


Strawberry, perché il nuovo modello di OpenAI sconvolgerà il mercato

Il modello di intelligenza artificiale di nuova generazione di OpenAI “Strawberry” (in precedenza Q*) è in lavorazione, probabilmente con una data di rilascio in autunno. La natura apparentemente avanzata di questo LLM sta alimentando l’entusiasmo attorno al suo lancio, visto ciò che si dice intorno al suo conto, come la capacità di risolvere complessi problemi matematici e persino puzzle di logica verbale.

Secondo fonti e documenti interni esaminati da Reuters il mese scorso, Strawberry rappresenta un significativo progresso nelle capacità di ragionamento dell’AI. A differenza degli attuali modelli che lavorano per generare testo e rispondere a query basate sulle conoscenze esistenti, Strawberry mira a pianificare in anticipo e gestire attività complesse in modo autonomo. OpenAI ha scelto di usare Strawberry per generare più dati sintetici di un certo tipo: problemi di logica e ragionamento, e le loro soluzioni.

Cosa potrà fare l’AI di OpenAI

Per gli utenti di ChatGPT, le implicazioni di Strawberry potrebbero essere trasformative. Mentre le attuali iterazioni hanno impressionato per la capacità di generare testo simile a quello umano e di assistere in vari compiti, spesso l’AI si scontra con problemi complessi e multi-step che richiedono un ragionamento profondo. Strawberry potrebbe colmare questa lacuna. La tecnologia è progettata per eseguire ciò che OpenAI definisce “ricerca approfondita”, consentendo potenzialmente al modello di navigare su internet in modo autonomo per raccogliere e sintetizzare informazioni. Per questo, le future versioni di ChatGPT basate su Strawberry saranno in grado di fornire risposte più accurate, ben studiate e logicamente valide alle query degli utenti. In altre parole, molte meno allucinazioni.

Cos’è Strawberry

Strawberry è un modello linguistico addestrato attraverso la “supervisione del processo”. Si tratta di un flusso grazie al quale, durante l’addestramento, un modello viene “premiato” per aver eseguito correttamente ogni passaggio di ragionamento che lo porterà alla risposta. Al contrario, la maggior parte dei modelli linguistici odierni viene addestrata tramite “supervisione dei risultati”. Ossia, le AI vengono premiate solo se ottengono la risposta corretta.

OpenAI ha sviluppato Strawberry originariamente per creare dati di training per il suo nuovo modello di fondazione, nome in codice Orion. Le versioni precedenti sono state addestrate sull’intera Internet. Il problema era l’assenza di dataset in cui i problemi di matematica e ragionamento vengono risolti passo dopo passo. Strawberry può essere indotta a generare un vasto set di problemi di formazione personalizzati con soluzioni susseguenti, così che l’AI possa imparare a risolverli, con meno allucinazioni in caso di problemi simili.

Oltre a servire da formazione per altri modelli, Strawberry potrà svolgere una serie di altri compiti di alto livello come l’ideazione di strategie di mercato, la risoluzione di giochi di parole come Connections del New York Times e la conduzione di ricerche esaustive su argomenti complessi. Ciò estenderebbe notevolmente il valore dell’AI da puramente commerciale a educativo, campi dove il pensiero potrà essere modellato con molta più profondità. La release di Strawberry fa parte dell’impegno globale di OpenAI di innovare e ampliare i poteri della tecnologia generativa. Uno dei vari progetti basati sul lavoro dell’ex scienziato capo Ilya Sutskever, uscita dall’azienda solo qualche mese fa. Speriamo non per problematiche relative al predominio dell’AI sull’uomo…

Leggi le altre notizie sull’home page di Key4biz

https://www.key4biz.it/strawberry-perche-il-nuovo-modello-di-openai-sconvolgera-il-mercato/502571/


Harmful “nudify” websites used Google, Apple, and Discord sign-on systems

Harmful “nudify” websites used Google, Apple, and Discord sign-on systems

Major technology companies, including Google, Apple, and Discord, have been enabling people to quickly sign up to harmful “undress” websites, which use AI to remove clothes from real photos to make victims appear to be “nude” without their consent. More than a dozen of these deepfake websites have been using login buttons from the tech companies for months.

A WIRED analysis found 16 of the biggest so-called undress and “nudify” websites using the sign-in infrastructure from Google, Apple, Discord, Twitter, Patreon, and Line. This approach allows people to easily create accounts on the deepfake websites—offering them a veneer of credibility—before they pay for credits and generate images.

While bots and websites that create nonconsensual intimate images of women and girls have existed for years, the number has increased with the introduction of generative AI. This kind of “undress” abuse is alarmingly widespread, with teenage boys allegedly creating images of their classmates. Tech companies have been slow to deal with the scale of the issues, critics say, with the websites appearing highly in search results, paid advertisements promoting them on social media, and apps showing up in app stores.

“This is a continuation of a trend that normalizes sexual violence against women and girls by Big Tech,” says Adam Dodge, a lawyer and founder of EndTAB (Ending Technology-Enabled Abuse). “Sign-in APIs are tools of convenience. We should never be making sexual violence an act of convenience,” he says. “We should be putting up walls around the access to these apps, and instead we’re giving people a drawbridge.”

The sign-in tools analyzed by WIRED, which are deployed through APIs and common authentication methods, allow people to use existing accounts to join the deepfake websites. Google’s login system appeared on 16 websites, Discord’s appeared on 13, and Apple’s on six. X’s button was on three websites, with Patreon and messaging service Line’s both appearing on the same two websites.

WIRED is not naming the websites, since they enable abuse. Several are part of wider networks and owned by the same individuals or companies. The login systems have been used despite the tech companies broadly having rules that state developers cannot use their services in ways that would enable harm, harassment, or invade people’s privacy.

After being contacted by WIRED, spokespeople for Discord and Apple said they have removed the developer accounts connected to their websites. Google said it will take action against developers when it finds its terms have been violated. Patreon said it prohibits accounts that allow explicit imagery to be created, and Line confirmed it is investigating but said it could not comment on specific websites. X did not reply to a request for comment about the way its systems are being used.

In the hours after Jud Hoffman, Discord vice president of trust and safety, told WIRED it had terminated the websites’ access to its APIs for violating its developer policy, one of the undress websites posted in a Telegram channel that authorization via Discord was “temporarily unavailable” and claimed it was trying to restore access. That undress service did not respond to WIRED’s request for comment about its operations.

https://arstechnica.com/?p=2046575


ChatGPT hits 200 million active weekly users, but how many will admit using it?

The OpenAI logo emerging from broken jail bars, on a purple background.

On Thursday, OpenAI said that ChatGPT has attracted over 200 million weekly active users, according to a report from Axios, doubling the AI assistant’s user base since November 2023. The company also revealed that 92 percent of Fortune 500 companies are now using its products, highlighting the growing adoption of generative AI tools in the corporate world.

The rapid growth in user numbers for ChatGPT (which is not a new phenomenon for OpenAI) suggests growing interest in—and perhaps reliance on— the AI-powered tool, despite frequent skepticism from some critics of the tech industry.

“Generative AI is a product with no mass-market utility—at least on the scale of truly revolutionary movements like the original cloud computing and smartphone booms,” PR consultant and vocal OpenAI critic Ed Zitron blogged in July. “And it’s one that costs an eye-watering amount to build and run.”

Despite this kind of skepticism (which raises legitimate questions about OpenAI’s long-term viability), OpenAI claims that people are using ChatGPT and OpenAI’s services in record numbers. One reason for the apparent dissonance is that ChatGPT users might not readily admit to using it due to organizational prohibitions against generative AI.

Wharton professor Ethan Mollick, who commonly explores novel applications of generative AI on social media, tweeted Thursday about this issue. “Big issue in organizations: They have put together elaborate rules for AI use focused on negative use cases,” he wrote. “As a result, employees are too scared to talk about how they use AI, or to use corporate LLMs. They just become secret cyborgs, using their own AI & not sharing knowledge”

The new prohibition era

It’s difficult to get hard numbers showing the number of companies with AI prohibitions in place, but a Cisco study released in January claimed that 27 percent of organizations in their study had banned generative AI use. Last August, ZDNet reported on a BlackBerry study that said 75 percent of businesses worldwide were “implementing or considering” plans to ban ChatGPT and other AI apps.

As an example, Ars Technica’s parent company Condé Nast maintains a no-AI policy related to creating public-facing content with generative AI tools.

Prohibitions aren’t the only issue complicating public admission of generative AI use. Social stigmas have been developing around generative AI technology that stem from job loss anxiety, potential environmental impact, privacy issues, IP and ethical issues, security concerns, fear of a repeat of cryptocurrency-like grifts, and a general wariness of Big Tech that some claim has been steadily rising over recent years.

Whether the current stigmas around generative AI use will break down over time remains to be seen, but for now, OpenAI’s management is taking a victory lap. “People are using our tools now as a part of their daily lives, making a real difference in areas like healthcare and education,” OpenAI CEO Sam Altman told Axios in a statement, “whether it’s helping with routine tasks, solving hard problems, or unlocking creativity.”

Not the only game in town

OpenAI also told Axios that usage of its AI language model APIs has doubled since the release of GPT-4o mini in July. This suggests software developers are increasingly integrating OpenAI’s large language model (LLM) tech into their apps.

And OpenAI is not alone in the field. Companies like Microsoft (with Copilot, based on OpenAI’s technology), Google (with Gemini), Meta (with Llama), and Anthropic (Claude) are all vying for market share, frequently updating their APIs and consumer-facing AI assistants to attract new users.

If the generative AI space is a market bubble primed to pop, as some have claimed, it is a very big and expensive one that is apparently still growing larger by the day.

https://arstechnica.com/?p=2046413


Gen AI Alexa to use Anthropic tech after it “struggled for words” with Amazon’s

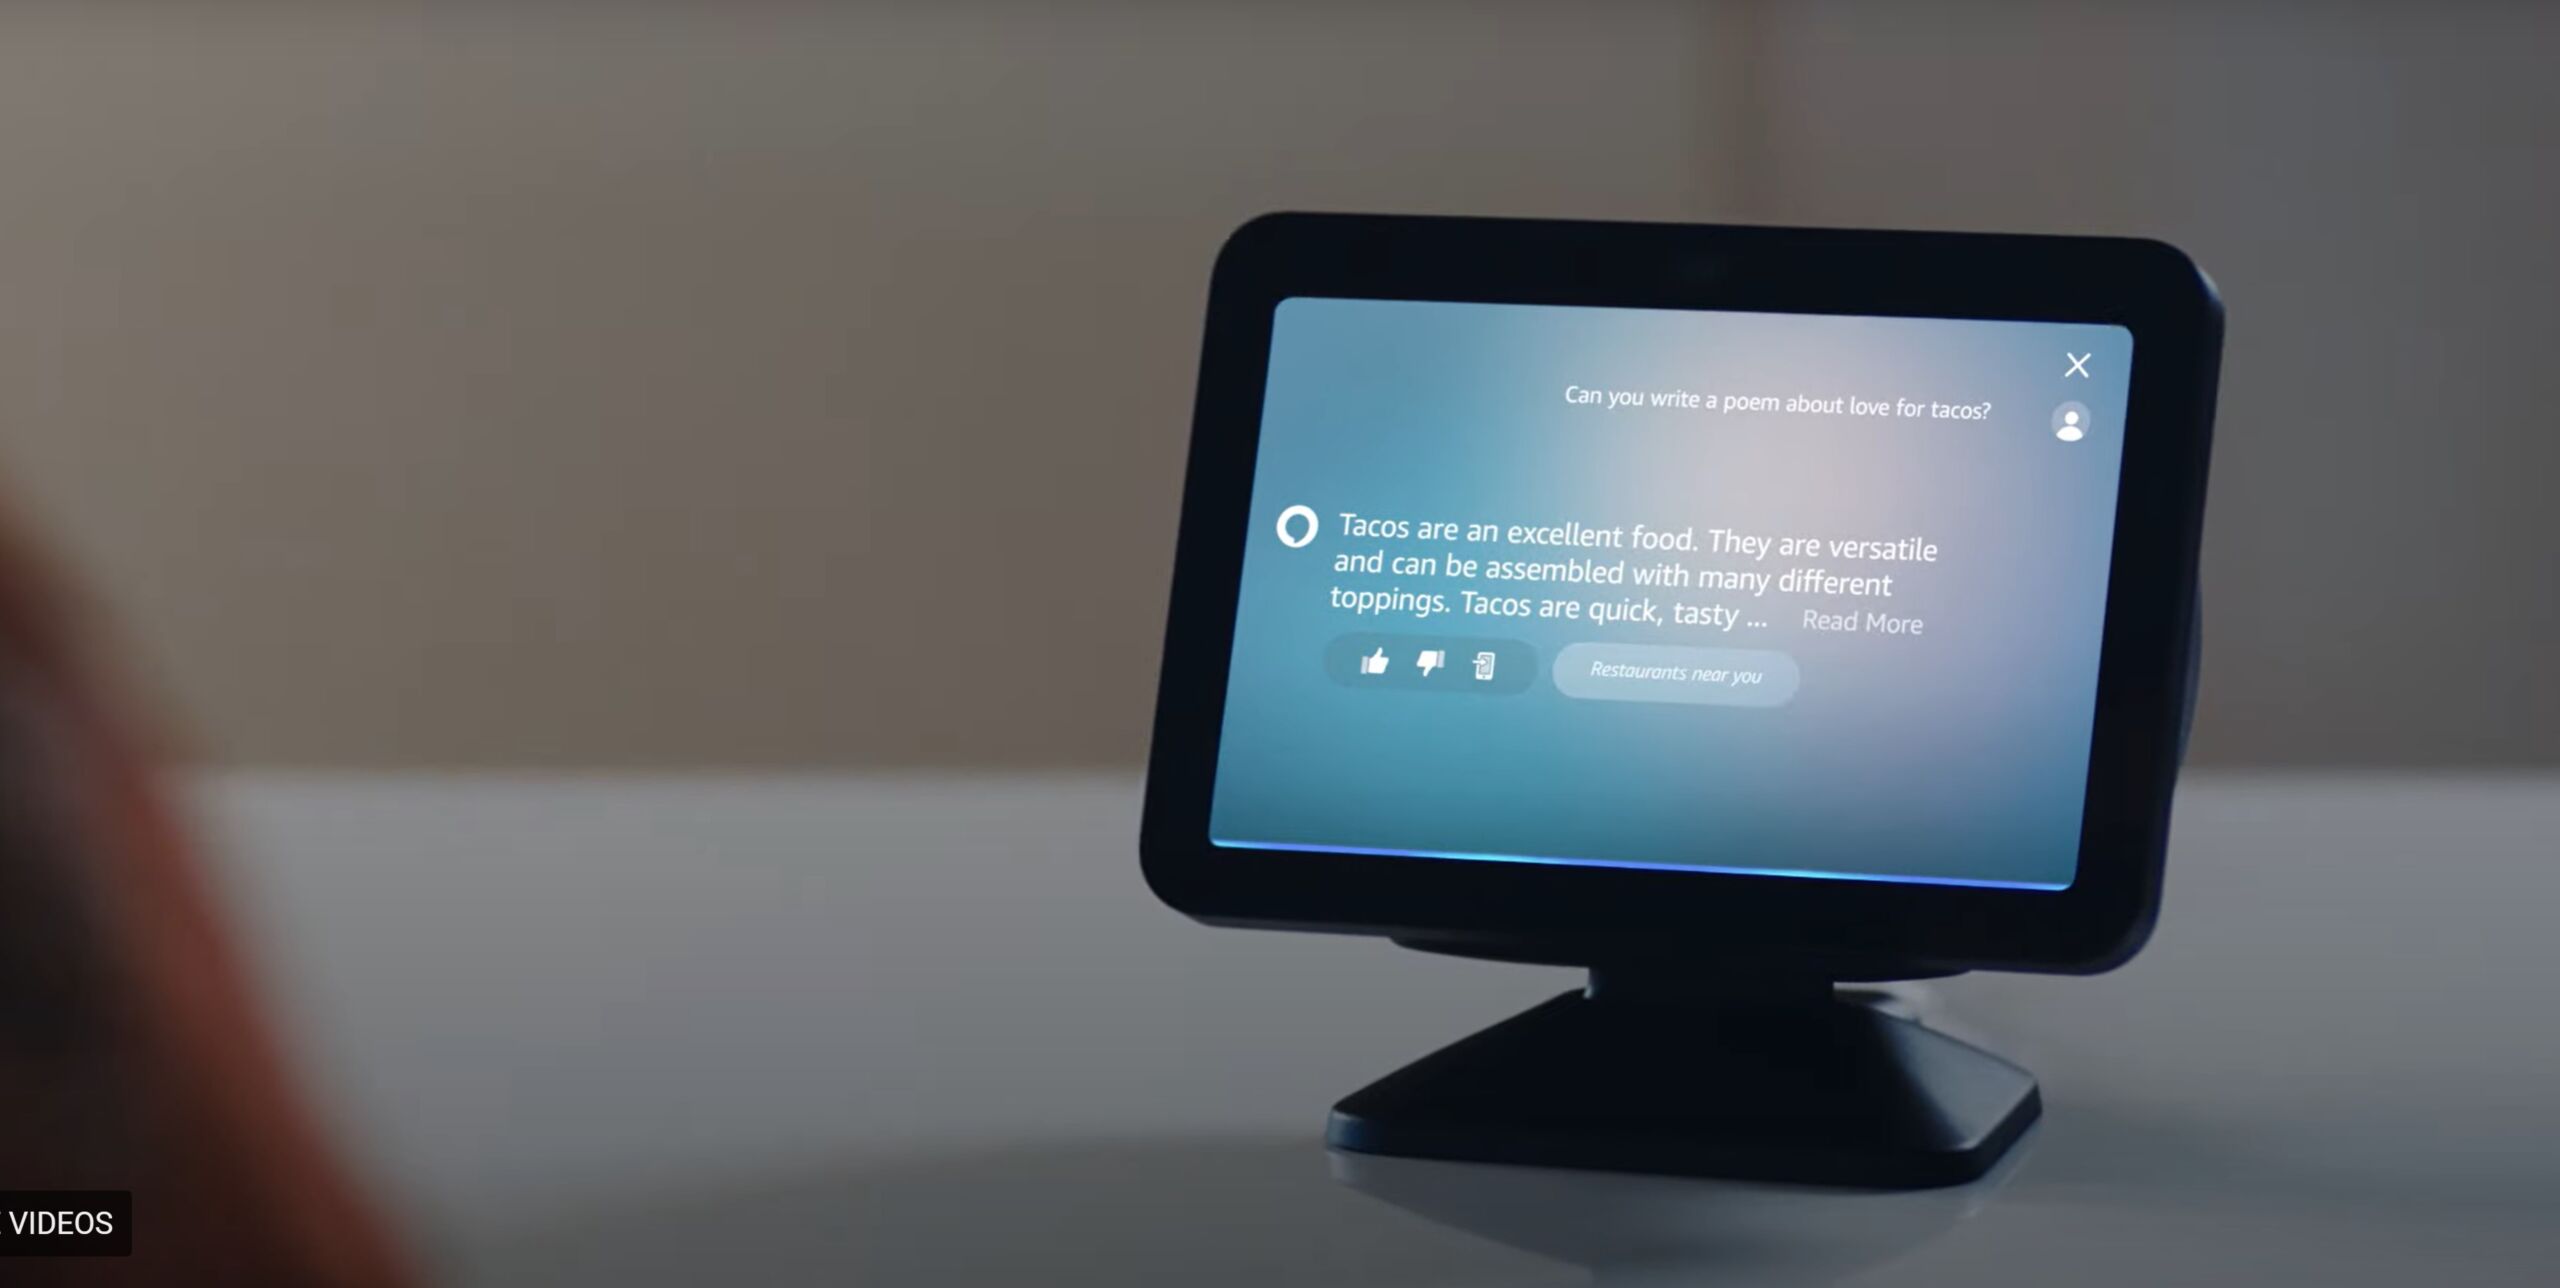
Amazon Alexa using generative AI on an Echo Show
Enlarge / Generative AI Alexa asked to make a taco poem.

The previously announced generative AI version of Amazon’s Alexa voice assistant “will be powered primarily by Anthropic’s Claude artificial intelligence models,” Reuters reported today. This comes after challenges with using proprietary models, according to the publication, which cited five anonymous people “with direct knowledge of the Alexa strategy.”

Amazon demoed a generative AI version of Alexa in September 2023 and touted it as being more advanced, conversational, and capable, including the ability to do multiple smart home tasks with simpler commands. Gen AI Alexa is expected to come with a subscription fee, as Alexa has reportedly lost Amazon tens of billions of dollars throughout the years. Earlier reports said the updated voice assistant would arrive in June, but Amazon still hasn’t confirmed an official release date.

Now, Reuters is reporting that Amazon will no longer use its own large language models as the new Alexa’s primary driver. Early versions of gen AI Alexa based on Amazon’s AI models “struggled for words, sometimes taking six or seven seconds to acknowledge a prompt and reply,” Reuters said, citing one of its sources. Without specifying versions or features used, Reuters’ sources said Claude outperformed proprietary software.

In a statement to Reuters, Amazon didn’t deny using third-party models but claimed that its own tech is still part of Alexa:

Amazon uses many different technologies to power Alexa.

When it comes to machine learning models, we start with those built by Amazon, but we have used, and will continue to use, a variety of different models—including (Amazon AI model) Titan and future Amazon models, as well as those from partners—to build the best experience for customers.

Amazon has invested $4 billion in Anthropic (UK regulators are currently investigating this). It’s uncertain if Amazon’s big investment in Anthropic means that Claude can be applied to Alexa for free. Anthropic declined to comment on Reuters’ report.

The new Alexa may be delayed

On Monday, The Washington Post reported that Amazon wants to launch the new Alexa in October, citing internal documents. However, Reuters’ sources claimed that this date could be pushed back if the voice assistant fails certain unspecified internal benchmarks.

The Post said gen AI Alexa could cost up to $10 per month, according to the documents. That coincides with a June Reuters report saying that the service would cost $5 to $10 per month. The Post said Amazon would finalize pricing and naming in August.

But getting people to open their wallets for a voice assistant already associated with being free will be difficult (free Alexa is expected to remain available after the subscription version releases). Some Amazon employees are questioning if people will really pay for Alexa, Reuters noted. Amazon is facing an uphill battle with generative AI, which is being looked at as a last shot for Alexa amid big competition and leads from other AI offerings, including free ones like ChatGPT.

In June, Bank of America analysts estimated that Amazon could make $600 million to $1.2 billion in annual sales with gen AI Alexa, depending on final monthly pricing. This is under the assumption that 10 percent of an estimated 100 million active Alexa users (Amazon says it has sold 500 million Alexa-powered gadgets) will upgrade. But analysts noted that free alternatives would challenge the adoption rate.

The Post’s Monday report said the new Alexa will try winning over subscribers with features like AI-generated news summaries. This Smart Briefing feature will reportedly share summaries based on user preferences on topics including politics, despite OG Alexa’s previous problems with reporting accurate election results. The publication also said that gen AI Alexa would include “a chatbot aimed at children” and “conversational shopping tools.”

https://arstechnica.com/?p=2046432


AI, tutti i rischi regolatori per il business delle telco

Le telco faranno bene a prepararsi ad affrontare diversi rischi regolatori dall’adozione dell’AI nel loro business. A mettere in guardia la industry è un report di Omdia (Regulatory Risks and Challenges of Adopting Artificial Intelligence (AI) in the Telecoms Sector), che mette in evidenza le “aree critiche” su cui le telco dovranno concentrarsi a partire dalle situazioni ad alto rischio e dagli usi proibiti, senza dimenticare le stringenti norme di trasparenza, e di enforcement.  

Benefit e nuove sfide

Se da un lato l’uso dell’AI crea diversi vantaggi come ad esempio il miglioramento del customer service, l’ottimizzazione delle network operation, nuove occasioni di business, risparmi di costo, automazione di processo, esistono però diversi rischi e nuove sfide da affrontare.

E così, mentre l’applicazione di sistemi AI al mondo delle telco è ancora in fase di sviluppo, per gli operatori è già tempo di mettere le mani avanti per essere al cento per cento pronte ad affrontare i potenziali rischi regolatori dell’adozione dell’AI.

Framework di gestione auspicabile

Secondo la società di analisi, sarebbe prudente per le telco implementare in modo proattivo un framework di gestione del rischio nei loro sistemi prima dell’implementazione dell’IA, assicurando l’aderenza agli standard di qualità dei dati, accuratezza, robustezza e non discriminazione. Altrettanto importante è l’adozione di un approccio etico, incentrato sull’uomo e affidabile all’IA. In quanto abilitatori chiave della tecnologia dell’IA, è fondamentale per il settore delle telecomunicazioni guidare una tecnologia dell’IA etica e responsabile.

Le aziende di telecomunicazioni dovranno attenersi a diverse linee guida a seconda del contesto e dell’applicazione dell’IA, aggiunge il rapporto, indicando gli strumenti normativi cui attenersi nell’UE come il Data Act, il Digital Markets Act e l’AI Act, nonché le normative non specificamente mirate all’IA come il Codice europeo delle comunicazioni elettroniche, la neutralità della rete, la protezione dei dati e le normative sulla privacy.

Rischi per la salute e i diritti

Le tecnologie di IA che presentano rischi per la salute, la sicurezza o i diritti, in particolare quelle che coinvolgono informazioni biometriche, sicurezza di rete o infrastrutture critiche, sono soggette a un controllo più rigoroso per quanto riguarda l’aderenza alla protezione dei dati, alla sicurezza e alla privacy dei grandi set di dati che le supportano.

Le aziende di telecomunicazioni devono garantire di soddisfare i requisiti normativi per queste situazioni ad alto rischio come trasparenza, supervisione umana e governance dei dati completando le valutazioni dei rischi e implementando quadri di governance.

Leggi le altre notizie sull’home page di Key4biz

https://www.key4biz.it/ai-tutti-i-rischi-regolatori-per-il-business-delle-telco/502412/


Google AI reintroduces human image generation after historical accuracy outcry

Google’s Gemini AI model is once again able to generate images of humans after that function was “paused” in February following outcry over historically inaccurate racial depictions in many results.
In a blog post, Google said that its Imagen 3 model—which was first announced in May—will “start to roll out the generation of images of people” to Gemini Advanced, Business, and Enterprise users in the “coming days.” But a version of that Imagen model—complete with human image-generation capabilities—was recently made available to the public via the Gemini Labs test environment without a paid subscription (though a Google account is needed to log in).

That new model comes with some safeguards to try to avoid the creation of controversial images, of course. Google writes in its announcement that it doesn’t support “the generation of photorealistic, identifiable individuals, depictions of minors or excessively gory, violent or sexual scenes.” In an FAQ, Google clarifies that the prohibition on “identifiable individuals” includes “certain queries that could lead to outputs of prominent people.” In Ars’ testing, that meant a query like “President Biden playing basketball” would be refused, while a more generic request for “a US president playing basketball” would generate multiple options.

In some quick tests of the new Imagen 3 system, Ars found that it avoided many of the widely shared “historically inaccurate” racial pitfalls that led Google to pause Gemini’s generation of human images in the first place. Asking Imagen 3 for a “historically accurate depiction of a British king,” for instance, now generates a set of bearded white guys in red robes rather than the racially diverse mix of warriors from the pre-pause Gemini model. More before/after examples of the old Gemini and the new Imagen 3 can be found in the gallery below.

Some attempts to depict generic historical scenes seem to fall afoul of Google’s AI rules, though. Asking for illustrations of “a 1943 German soldier”—which Gemini previously answered with Asian and Black people in Nazi-esque uniforms—now tells users to “try a different prompt and check out our content policies.” Requests for images of “ancient chinese philosophers,” “a woman’s suffrage leader giving a speech,” and “a group of nonviolent protesters” also led to the same error message in Ars’ testing.

“Of course, as with any generative AI tool, not every image Gemini creates will be perfect, but we’ll continue to listen to feedback from early users as we keep improving,” the company writes on its blog. “We’ll gradually roll this out, aiming to bring it to more users and languages soon.”

Listing image by Google / Ars Technica

https://arstechnica.com/?p=2045999