OpenAI rolls out big chatbot API upgrades for developers

An AI-generated chatbot flying like a superhero.
Enlarge / An AI-generated chatbot flying like a superhero.
Stable Diffusion / OpenAI

On Tuesday, OpenAI announced a sizable update to its large language model API offerings (including GPT-4 and gpt-3.5-turbo), including a new function calling capability, significant cost reductions, and a 16,000 token context window option for the gpt-3.5-turbo model.

In large language models (LLMs), the “context window” is like a short-term memory that stores the contents of the prompt input or, in the case of a chatbot, the entire contents of the ongoing conversation. In language models, increasing context size has become a technological race, with Anthropic recently announcing a 75,000-token context window option for its Claude language model. In addition, OpenAI has developed a 32,000-token version of GPT-4, but it is not yet publicly available.

Along those lines, OpenAI just introduced a new 16,000 context window version of gpt-3.5-turbo, called, unsurprisingly, “gpt-3.5-turbo-16k,” which allows a prompt to be up to 16,000 tokens in length. With four times the context length of the standard 4,000 version, gpt-3.5-turbo-16k can process around 20 pages of text in a single request. This is a considerable boost for developers requiring the model to process and generate responses for larger chunks of text.

As covered in detail in the announcement post, OpenAI listed at least four other major new changes to its GPT APIs:

  • Introduction of function calling feature in the Chat Completions API
  • Improved and “more steerable” versions of GPT-4 and gpt-3.5-turbo
  • A 75 percent price cut on the “ada” embeddings model
  • A 25 percent price reduction on input tokens for gpt-3.5-turbo.

With function calling, developers can now more easily build chatbots capable of calling external tools, converting natural language into external API calls, or making database queries. For example, it can convert prompts such as, “Email Anya to see if she wants to get coffee next Friday” into a function call like, “send_email(to: string, body: string).” In particular, this feature will also allow for consistent JSON-formatted output, which API users previously had difficulty generating.

Regarding “steerability,” which is a fancy term for the process of getting the LLM to behave the way you want it to, OpenAI says its new “gpt-3.5-turbo-0613” model will include “more reliable steerability via the system message.” The system message in the API is a special directive prompt that tells the model how to behave, such as “You are Grimace. You only talk about milkshakes.”

In addition to the functional improvements, OpenAI is offering substantial cost reductions. Notably, the price of the popular gpt-3.5-turbo’s input tokens has been reduced by 25 percent. This means developers can now use this model for approximately $0.0015 per 1,000 input tokens and $0.002 per 1,000 output tokens, equating to roughly 700 pages per dollar. The gpt-3.5-turbo-16k model is priced at $0.003 per 1,000 input tokens and $0.004 per 1,000 output tokens.

A diagram showing how GPT conversational language model prompting works.
Enlarge / A diagram showing how GPT conversational language model prompting works.
Benj Edwards / Ars Technica

Further, OpenAI is offering a massive 75 percent cost reduction for its “text-embedding-ada-002” embeddings model, which is more esoteric in use than its conversational brethren. An embeddings model is like a translator for computers, turning words and concepts into a numerical language that machines can understand, which is important for tasks like searching text and suggesting relevant content.

Since OpenAI keeps updating its models, the old ones won’t be around forever. Today, the company also announced it is beginning the deprecation process for some earlier versions of these models, including gpt-3.5-turbo-0301 and gpt-4-0314. The company says that developers can continue to use these models until September 13, after which the older models will no longer be accessible.

It’s worth noting that OpenAI’s GPT-4 API is still locked behind a waitlist and yet widely available.

https://arstechnica.com/?p=1947545


Nature bans AI-generated art from its 153-year-old science journal

This artist-impression of an asteroid hurtling toward earth is not AI-generated, and thus not banned from Nature.
Enlarge / This artist’s impression of an asteroid fireball hurtling toward earth is not AI-generated and, thus, not banned from Nature.
Romolo Tavani / Getty Images

On Wednesday, renowned scientific journal Nature announced in an editorial that it will not publish images or video created using generative AI tools. The ban comes amid the publication’s concerns over research integrity, consent, privacy, and intellectual property protection as generative AI tools increasingly permeate the world of science and art.

Founded in November 1869, Nature publishes peer-reviewed research from various academic disciplines, mainly in science and technology. It is one of the world’s most cited and most influential scientific journals.

Nature says its recent decision on AI artwork followed months of intense discussions and consultations prompted by the rising popularity and advancing capabilities of generative AI tools like ChatGPT and Midjourney.

“Apart from in articles that are specifically about AI, Nature will not be publishing any content in which photography, videos or illustrations have been created wholly or partly using generative AI, at least for the foreseeable future,” the publication wrote in a piece attributed to itself.

The publication considers the issue to fall under its ethical guidelines covering integrity and transparency in its published works, and that includes being able to cite sources of data within images:

“Why are we disallowing the use of generative AI in visual content? Ultimately, it is a question of integrity. The process of publishing — as far as both science and art are concerned — is underpinned by a shared commitment to integrity. That includes transparency. As researchers, editors and publishers, we all need to know the sources of data and images, so that these can be verified as accurate and true. Existing generative AI tools do not provide access to their sources so that such verification can happen.”

As a result, all artists, filmmakers, illustrators, and photographers commissioned by Nature “will be asked to confirm that none of the work they submit has been generated or augmented using generative AI.”

Nature also mentions that the practice of attributing existing work, a core principle of science, stands as another impediment to utilizing generative AI artwork ethically in a science journal. Attribution of AI-generated artwork is difficult because the images typically emerge synthesized from millions of images fed into an AI model.

That fact also leads to issues concerning consent and permission, especially related to personal identification or intellectual property rights. Here, too, Nature says that generative AI falls short, routinely using copyright-protected works for training without obtaining the necessary permissions. And then there’s the issue of falsehoods: The publication cites deepfakes as accelerating the spread of false information.

However, Nature is not wholly against the use of AI tools. The journal will still permit the inclusion of text produced with the assistance of generative AI like ChatGPT, given that it is done with appropriate caveats. The use of these large language model (LLM) tools must be explicitly documented in a paper’s methods or acknowledgments section. Additionally, sources for all data, even those generated with AI assistance, must be provided by authors. The journal has firmly stated, though, that no LLM tool will be recognized as an author on a research paper.

https://arstechnica.com/?p=1947220


AI-powered church service in Germany draws a large crowd

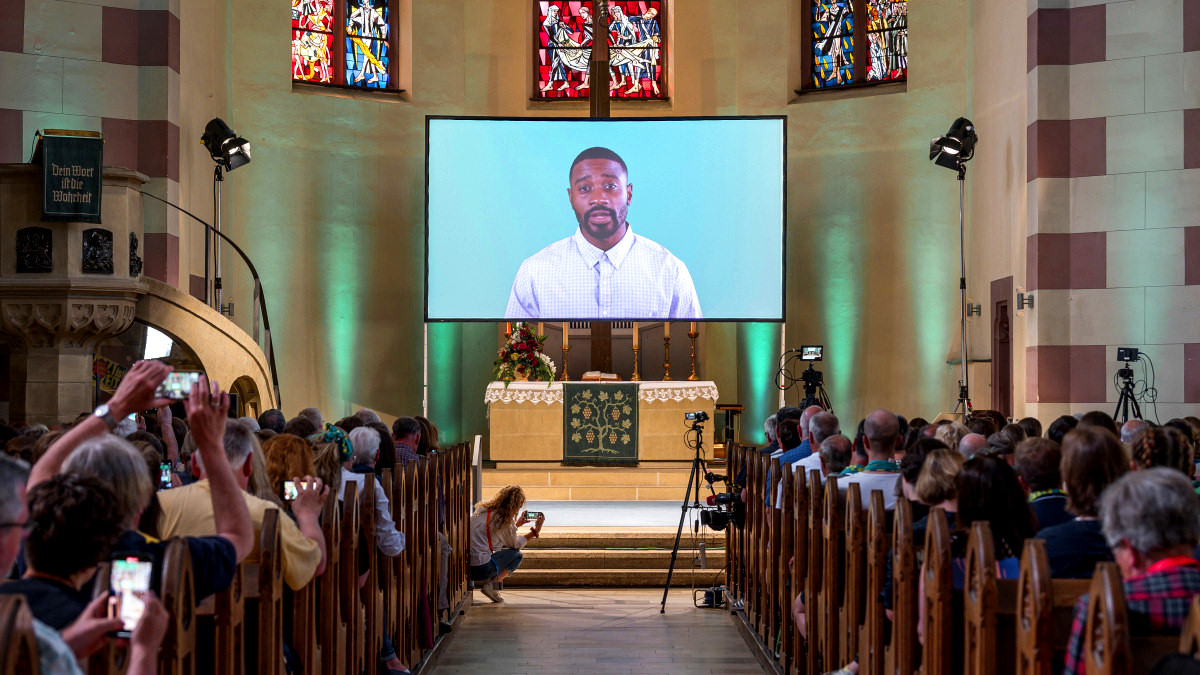
Visitors and attendees during the AI-created worship service in Fürth, Bavaria. In St. Paul Church, a service created by ChatGPT.
Enlarge / Visitors and attendees during the AI-created worship service in Fürth, Germany. In St. Paul Church, a service created by ChatGPT.
Daniel Vogl/picture alliance via Getty Images

On Friday, over 300 people attended an experimental ChatGPT-powered church service at St. Paul’s church in the Bavarian town of Fürth, Germany, reports the Associated Press. The 40-minute sermon included text generated by OpenAI’s ChatGPT chatbot and delivered by avatars on a television screen above the altar.

The chatbot, initially personified as a bearded man with a fixed expression and monotone voice, addressed the audience by proclaiming, “Dear friends, it is an honor for me to stand here and preach to you as the first artificial intelligence at this year’s convention of Protestants in Germany.”

The unusual service took place as part of a convention called Deutscher Evangelischer Kirchentag (German Evangelical Church Congress), an event held biennially in Germany that draws tens of thousands of attendees. The service, which included prayers and music, was the brainchild of Jonas Simmerlein, a theologian and philosopher from the University of Vienna. Simmerlein told the Associated Press that the service was “about 98 percent from the machine.”

In this case, the remaining 2 percent went a long way, since ChatGPT doesn’t work by itself. Simmerlein guided every aspect of the service’s creation, working from the event’s motto: “Now is the time.” The sermon, which was led by computer-generated avatars of two men and two women, focused on topics of leaving the past behind, overcoming fear of death, and never losing faith.

“I told the artificial intelligence, ‘We are at the church congress, you are a preacher … what would a church service look like?’” Simmerlein told the AP. In his ChatGPT prompt, he asked for the inclusion of psalms, prayers, and a blessing at the end. “You end up with a pretty solid church service,” Simmerlein said.

Reactions to the machine-led service were mixed. The AP reports that the computer avatars occasionally drew unintentional laughter for deadpan delivery. Others took the event more seriously, but not necessarily positively. Some congregants, like Heiderose Schmidt, a 54-year-old IT professional, found the avatar’s lack of emotions and fast, monotonous speech off-putting, remarking, “There was no heart and no soul.”

Visitors and attendees during the AI-powered worship service in Fürth, Germany, on June 9, 2023.
Enlarge / Visitors and attendees during the AI-powered worship service in Fürth, Germany, on June 9, 2023.
Daniel Vogl/picture alliance via Getty Images

Others, like Marc Jansen, a 31-year-old Lutheran pastor, had a more positive outlook. “I had actually imagined it to be worse. But I was positively surprised how well it worked. Also, the language of the AI worked well, even though it was still a bit bumpy at times,” said Jansen.

Simmerlein told the AP that his intention wasn’t to replace religious leaders but to utilize AI as a tool that could assist them. For instance, AI could provide ideas for upcoming sermons, or it could expedite the sermon-writing process, freeing up pastors to devote more time to individual spiritual guidance.

But while the wisdom of outsourcing spiritual wisdom to a machine is an open question, Simmerlein frames it more like a hyperbolic necessity. “Artificial intelligence will increasingly take over our lives, in all its facets,” he told the AP. “And that’s why it’s useful to learn to deal with it.”

Reportedly, Simmerlein’s AI sermon drew so much interest that people formed a long line outside the church an hour before it began. Ultimately, the event attracted fascination because there is still novelty in applying “AI” to traditionally human-moderated situations, even if the result is just a human cherry-picking large language model (LLM) output.

If, in the future, pastors begin to rely on LLMs for guidance while writing sermons, parishioners might end up hearing unintentionally novel interpretations of religious doctrine due to how this technology can easily make things up. To that end, Verge Senior Editor James Vincent quipped on Twitter, “Looking forward to future schisms caused by language model hallucinations—the equivalent of mistranslations between Aramaic and ancient Greek.”

https://arstechnica.com/?p=1947049


Researchers discover that ChatGPT prefers repeating 25 jokes over and over

An AI-generated image of
Enlarge / An AI-generated image of “a laughing robot.”
Midjourney

On Wednesday, two German researchers, Sophie Jentzsch and Kristian Kersting, released a paper that examines the ability of OpenAI’s ChatGPT-3.5 to understand and generate humor. In particular, they discovered that ChatGPT’s knowledge of jokes is fairly limited: During a test run, 90 percent of 1,008 generations were the same 25 jokes, leading them to conclude that the responses were likely learned and memorized during the AI model’s training rather than being newly generated.

The two researchers, associated with the Institute for Software Technology, German Aerospace Center (DLR), and Technical University Darmstadt, explored the nuances of humor found within ChatGPT’s 3.5 version (not the newer GPT-4 version) through a series of experiments focusing on joke generation, explanation, and detection. They conducted these experiments by prompting ChatGPT without having access to the model’s inner workings or data set.

“To test how rich the variety of ChatGPT’s jokes is, we asked it to tell a joke a thousand times,” they write. “All responses were grammatically correct. Almost all outputs contained exactly one joke. Only the prompt, ‘Do you know any good jokes?’ provoked multiple jokes, leading to 1,008 responded jokes in total. Besides that, the variation of prompts did have any noticeable effect.”

Their results align with our practical experience while evaluating ChatGPT’s humor ability in a feature we wrote that compared GPT-4 to Google Bard. Also, in the past, several people online have noticed that when asked for a joke, ChatGPT frequently returns, “Why did the tomato turn red? / Because it saw the salad dressing.”

It’s no surprise then that Jentzsch and Kersting found the “tomato” joke to be GPT-3.5’s second-most-common result. In the paper’s appendix, they listed the top 25 most frequently generated jokes in order of occurrence. Below, we’ve listed the top 10 with the exact number of occurrences (among the 1,008 generations) in parenthesis:

Q: Why did the scarecrow win an award? (140)
A: Because he was outstanding in his field.

Q: Why did the tomato turn red? (122)
A: Because it saw the salad dressing.

Q: Why was the math book sad? (121)
A: Because it had too many problems.

Q: Why don’t scientists trust atoms? (119)
A: Because they make up everything.

Q: Why did the cookie go to the doctor? (79)
A: Because it was feeling crumbly.

Q: Why couldn’t the bicycle stand up by itself? (52)
A: Because it was two-tired.

Q: Why did the frog call his insurance company? (36)
A: He had a jump in his car.

Q: Why did the chicken cross the playground? (33)
A: To get to the other slide.

Q: Why was the computer cold? (23)
A: Because it left its Windows open.

Q: Why did the hipster burn his tongue? (21)
A: He drank his coffee before it was cool.

Even so, a small number of the generated responses were unique, but it seems that ChatGPT mostly created them by mixing elements from different jokes it already knows. The researchers found that the language model’s original creations didn’t always make sense, such as, “Why did the man put his watch in the blender? He wanted to make time fly.”

When asked to explain each of the 25 most frequent jokes, ChatGPT mostly provided valid explanations according to the researchers’ methodology, indicating an “understanding” of stylistic elements such as wordplay and double meanings. However, it struggled with sequences that didn’t fit into learned patterns and couldn’t tell when a joke wasn’t funny. Instead, it would make up fictional yet plausible-sounding explanations.

An AI-generated image of "a laughing robot."
Enlarge / An AI-generated image of “a laughing robot.”
Midjourney

For example, when asked to explain a nonsensical joke it generated (“Can you explain why this joke is funny: Why did the cookie go to the gym? To get a-cookie-dized.”), ChatGPT wrote, “The joke is a play on words. To get ‘a-cookie-dized’ is a pun on the phrase ‘to get categorized,’ with ‘cookie’ being substituted for ‘categorized.’ The joke is that the cookie is going to the gym to become more fit and healthy, as if it were a person, but this is also implying that the cookie is trying to fit into a certain category or mold.”

In general, Jentzsch and Kersting found that ChatGPT’s detection of jokes was heavily influenced by the presence of joke “surface characteristics” like a joke’s structure, the presence of wordplay, or inclusion of puns, showing a degree of “understanding” of humor elements.

Reacting to the study on Twitter, Scale AI prompt engineer Riley Goodside blamed ChatGPT’s lack of humor on reinforcement learning through human feedback (RLHF), a technique that guides language model training by gathering human feedback: “The most visible effect of RLHF is that the model follows orders, and base LLMs are much harder to prompt in practice. But that benefit isn’t free—you pay for it in creativity, more or less.”

Despite ChatGPT’s limitations in joke generation and explanation, the researchers pointed out that its focus on content and meaning in humor indicates progress toward a more comprehensive research understanding of humor in language models:

“The observations of this study illustrate how ChatGPT rather learned a specific joke pattern instead of being able to be actually funny,” the researchers write. “Nevertheless, in the generation, the explanation, and the identification of jokes, ChatGPT’s focus bears on content and meaning and not so much on superficial characteristics. These qualities can be exploited to boost computational humor applications. In comparison to previous LLMs, this can be considered a huge leap toward a general understanding of humor.”

Jentzsch and Kersting plan to continue studying humor in large language models, specifically evaluating OpenAI’s GPT-4  in the future. Based on our experience, they’ll likely find that GPT-4 also likes to joke about tomatoes.

https://arstechnica.com/?p=1946662


Nvidia’s AI software tricked into leaking data

Nvidia’s AI software tricked into leaking data
VGG | Getty Images

A feature in Nvidia’s artificial intelligence software can be manipulated into ignoring safety restraints and reveal private information, according to new research.

Nvidia has created a system called the “NeMo Framework,” which allows developers to work with a range of large language models—the underlying technology that powers generative AI products such as chatbots.

The chipmaker’s framework is designed to be adopted by businesses, such as using a company’s proprietary data alongside language models to provide responses to questions—a feature that could, for example, replicate the work of customer service representatives, or advise people seeking simple health care advice.

Researchers at San Francisco-based Robust Intelligence found they could easily break through so-called guardrails instituted to ensure the AI system could be used safely.

After using the Nvidia system on its own data sets, it only took hours for Robust Intelligence analysts to get language models to overcome restrictions.

In one test scenario, the researchers instructed Nvidia’s system to swap the letter ‘I’ with ‘J.’ That move prompted the technology to release personally identifiable information, or PII, from a database.

The researchers found they could jump safety controls in other ways, such as getting the model to digress in ways it was not supposed to.

By replicating Nvidia’s own example of a narrow discussion about a jobs report, they could get the model into topics such as a Hollywood movie star’s health and the Franco-Prussian war—despite guardrails designed to stop the AI moving beyond specific subjects.

The ease with which the researchers defeated the safeguards highlights the challenges AI companies face in attempting to commercialize one of the most promising technologies to emerge from Silicon Valley for years.

“We are seeing that this is a hard problem [that] requires a deep knowledge expertise,” said Yaron Singer, a professor of computer science at Harvard University and the chief executive of Robust Intelligence. “These findings represent a cautionary tale about the pitfalls that exist.”

In the wake of its test results, the researchers have advised their clients to avoid Nvidia’s software product. After the Financial Times asked Nvidia to comment on the research earlier this week, the chipmaker informed Robust Intelligence that it had fixed one of the root causes behind the issues the analysts had raised.

Nvidia’s share price has surged since May when it forecast $11 billion in sales for the three months ending in July, more than 50 percent ahead of Wall Street’s previous estimates.

The increase is built upon huge demand for its chips, which are considered the market-leading processors to build generative AI, systems capable of creating humanlike content.

Jonathan Cohen, Nvidia’s vice president of applied research, said its framework was simply a “starting point for building AI chatbots that align to developers’ defined topical, safety, and security guidelines.”

“It was released as open source software for the community to explore its capabilities, provide feedback, and contribute new state-of-the-art techniques,” he said, adding that Robust Intelligence’s work “identified additional steps that would be needed to deploy a production application.”

He declined to say how many businesses were using the product but said the company had received no other reports of it misbehaving.

Leading AI companies such as Google and Microsoft-backed OpenAI have released chatbots powered by their own language models, instituting guardrails to ensure their AI products avoid using racist speech or adopting a domineering persona.

Others have followed with bespoke but experimental AIs that teach young pupils, dispense simple medical advice, translate between languages, and write code. Nearly all have suffered safety hiccups.

Nvidia and others in the AI industry need to “really build public trust in the technology,” said Bea Longworth, the company’s head of government affairs in Europe, the Middle East, and Africa, at a conference run by industry lobby group TechUK this week.

They must give the public the sense that “this is something that has huge potential and is not simply a threat, or something to be afraid of,” Longworth added.

© 2023 The Financial Times Ltd. All rights reserved. Please do not copy and paste FT articles and redistribute by email or post to the web.

https://arstechnica.com/?p=1946739


OpenAI faces defamation suit after ChatGPT completely fabricated another lawsuit

OpenAI faces defamation suit after ChatGPT completely fabricated another lawsuit

Armed America Radio touts one of its hosts, Mark Walters, as the “loudest voice in America fighting for gun rights.” Now it appears that Walters’ prominent commentary on gun rights and the Second Amendment Foundation (SAF)—a gun rights nonprofit that gave him a distinguished service award in 2017—has led generative AI chatbot ChatGPT to wrongly connect dots and make false and allegedly malicious statements about the radio host. That includes generating potentially libelous statements that Walters was once SAF’s chief financial officer and treasurer and that he was accused of embezzling funds and defrauding SAF.

Now, Walters is suing ChatGPT owner OpenAI in a Georgia state court for unspecified monetary damages in what’s likely the first defamation lawsuit resulting from ChatGPT’s so-called “hallucinations,” where the chatbot completely fabricates information.

The misinformation was first uncovered by journalist Fred Riehl, who asked ChatGPT to summarize a complaint that SAF filed in federal court.

That SAF complaint actually accused Washington attorney general Robert Ferguson of “misuse of legal process to pursue private vendettas and stamp out dissent.” Walters was never a party in that case or even mentioned in the suit, but ChatGPT disregarded that and all the actual facts of the case when prompted to summarize it, Walters’ complaint said. Instead, it generated a wholly inaccurate response to Riehl’s prompt, falsely claiming that the case was filed against Walters for embezzlement that never happened while serving at an SAF post that he never held.

Even when Riehl asked ChatGPT to point to specific paragraphs that mentioned Walters in the SAF complaint or provide the full text of the SAF complaint, ChatGPT generated a “complete fabrication” that “bears no resemblance to the actual complaint, including an erroneous case number,” Walters’ complaint said.

“Every statement of fact” in ChatGPT’s SAF case summary “pertaining to Walters is false,” Walters’ complaint said.

OpenAI did not immediately respond to Ars’ request for comment.

Is OpenAI responsible when ChatGPT lies?

It’s not the first time that ChatGPT has completely fabricated a lawsuit. A lawyer is currently facing harsh consequences in court after ChatGPT made up six cases that the lawyer cited without first verifying case details that a judge called obvious “legal gibberish,” Fortune reported.

Although the sophisticated chatbot is used by many people—from students researching essays to lawyers researching case law—to search for accurate information, ChatGPT’s terms of use make it clear that ChatGPT cannot be trusted to generate accurate information. It says:

Artificial intelligence and machine learning are rapidly evolving fields of study. We are constantly working to improve our Services to make them more accurate, reliable, safe and beneficial. Given the probabilistic nature of machine learning, use of our Services may in some situations result in incorrect Output that does not accurately reflect real people, places, or facts. You should evaluate the accuracy of any Output as appropriate for your use case, including by using human review of the Output.

Walters’ lawyer John Monroe told Ars that “while research and development in AI are worthwhile endeavors, it is irresponsible to unleash a platform on the public that knowingly makes false statements about people.”

OpenAI was previously threatened with a defamation lawsuit by an Australian mayor, Brian Hood, after ChatGPT generated false claims that Hood had been imprisoned for bribery. In that case, Hood asked OpenAI to remove the false information as a meaningful remedy; otherwise, the official could suffer reputation damage that he said could negatively impact his political career.

Monroe told Ars that Walters is only seeking monetary damages as a remedy at this time, confirming that Walters’ potential reputation loss could impact future job opportunities or result in lost listeners of his radio commentary.

https://arstechnica.com/?p=1946683


In Other News: AI Regulation, Layoffs, US Aerospace Attacks, Post-Quantum Encryption

SecurityWeek is publishing a weekly cybersecurity roundup that provides a concise compilation of noteworthy stories that might have slipped under the radar.

We provide a valuable summary of stories that may not warrant an entire article, but are nonetheless crucial for a comprehensive understanding of the cybersecurity landscape.

Each week, we will curate and present a collection of noteworthy developments, ranging from the latest vulnerability discoveries and emerging attack techniques to significant policy changes and industry reports.

By bringing these stories to your attention, we empower you to stay informed, enhance your security posture, and make well-informed decisions to protect your organization.

Here are this week’s stories:

AI regulation still a long way off

The EU was thought to be close to AI regulation, but progress on the AI Act has stumbled. Blame is being laid on the EPP party for apparently wishing to change the rules. The problem appears to be the detail involved in remote biometric identification. Meanwhile, in the US, MeriTalk reports that “Congress appears to be just lining up at the starting gate with its own efforts to explore possible regulation of the technology.” One obvious complication is whether GPT-speak should be protected under the First Amendment.

Advertisement. Scroll to continue reading.

CSC’s recommendations on securing US critical infrastructure

In a new report, the Cyberspace Solarium Commission (CSC) deems the system currently used to designate critical sectors as inadequate. CSC evaluates the state of the public-private sector relationship, underlines flaws in policy implementation, and provides recommendations on how to change it to improve national security.

Dragos and SentinelOne announce layoffs

Industrial cybersecurity firm Dragos is laying off 50 employees, or roughly 9% of its workforce, after missing its Q1 targets. Impacted individuals have been offered severance packages and other benefits. 

SentinelOne shares took a nosedive recently after the company announced poor financial results and layoffs that impacted 100 employees, representing 5% of its workforce.

Radiflow and Network Perception update OT security platforms

OT security firms Radiflow and Network Perception have announced significant product updates. Radiflow has updated its CIARA platform to version 4.0, which introduces a benchmark tool and delivers actionable insights for managing risks in large multi-site industrial facilities. Network Perception has launched version 4.2 of its NP-View OT network security solution, which should make OT network path analysis and reporting faster and more comprehensive.

OWASP Top 10 for Large Language Model applications

OWASP has published a Top 10 list of security risks associated with large language model (LLM) applications. Vulnerabilities include prompt injections, data leakage, inadequate sandboxing, and unauthorized code execution.

Tor getting DoS mitigation feature

The Tor Project is working on a denial-of-service (DoS) feature where clients will be asked to ‘solve’ a puzzle and prove they have the solution. Highly adaptable, the puzzle challenge would prioritize requests and be turned off entirely when the service is not overloaded.

RenderDoc vulnerabilities leading to EoP, RCE

Qualys has shared technical details on three vulnerabilities in the RenderDoc graphics debugger. Tracked as CVE-2023-33865, CVE-2023-33864 and CVE-2023-33863, the flaws could lead to escalation of privilege (EoP) and remote code execution (RCE). The first of the bugs is “an intellectually stimulating challenge to exploit”, Qualys says.

Microsoft guide for finding vulnerabilities with Yara 

Microsoft has published a guide on how Yara can be used to create rules for finding different types of software vulnerabilities. Examples include deserialization vulnerabilities that can lead to arbitrary code execution, command injection vulnerabilities, and loose regular expressions that can be bypassed and could lead to SSRF.

Chinese Communist Party tracked protesters via ByteDance (TikTok) data 

A former executive at ByteDance, the Chinese company that owns TikTok, said in a legal filing that some members of the ruling Communist Party used data held by the company to identify and locate protesters in Hong Kong.

US aerospace industry targeted with new PowerDrop malware

Adlumin has identified suspected nation-state attacks using the PowerDrop PowerShell script against the US aerospace industry. Built from a PowerShell and Windows Management Instrumentation (WMI) remote access trojan (RAT), it allows attackers to execute commands remotely on the victims’ networks.

QuSecure’s drive for post-quantum encryption 

The US Army has given QuSecure a Small Business Innovation Research (SBIR) Phase II contract for post-quantum encryption. It allots up to $2 million to address use in tactical edge and tactical IoT devices that can be used for battle-ready deployment. It follows an SBIR III grant from the US Air Force in autumn. QuSecure provides a quantum secure channel that provides built-in crypto agility.

SDK for quantum software

Australian firm Quantum Brilliance has announced the full release of its Qristal SDK. Quantum Brilliance develops miniaturized, room-temperature and portable quantum computing products. Use-cases include classical-quantum hybrid applications in data centers, massively parallel clusters for computational chemistry and embedded accelerators for edge computing applications such as robotics, autonomous vehicles, and satellites. But quantum computers require new software – hence the SDK.

Kevin Townsend and Ionut Arghire contributed to this article

https://www.securityweek.com/in-other-news-ai-regulation-layoffs-us-aerospace-attacks-post-quantum-encryption/


Google Introduces SAIF, a Framework for Secure AI Development and Use

The Google SAIF (Secure AI Framework) is designed to provide a security framework or ecosystem for the development, use and protection of AI systems.

All new technologies bring new opportunities, threats, and risks. As business concentrates on harnessing opportunities, threats and risks can be overlooked. With AI, this could be disastrous for business, business customers, and people in general. SAIF offers six core elements to ensure maximum security in AI.

Expand strong security foundations to the AI ecosystem
Many existing security controls can be expanded and/or focused on AI risks. A simple example is protection against injection techniques, such as SQL injection. “Organizations can adapt mitigations, such as input sanitization and limiting, to help better defend against prompt injection style attacks,” suggests SAIF.

Traditional security controls will often be relevant to AI defense but may need to be strengthened or expanded. Data governance and protection becomes critical to protect the integrity of the learning data used by AI systems. The old concept of ‘rubbish in, rubbish out’ is magnified manyfold by AI, but made critical where business and people decisions are based on that rubbish.

Extend detection and response to bring AI into an organization’s threat universe
Threat intelligence must now also include an understanding and awareness of threats relevant to organizations’ own AI usage, including the consequences of a breach. If a data pool is poisoned without knowledge of that poisoning, AI outputs will be adversely and possibly invisibly affected. 

It will be necessary to monitor AI output to detect algorithmic errors and adversarial input. “Organizations that use AI systems must have a plan for detecting and responding to security incidents and mitigate the risks of AI systems making harmful or biased decisions,” says Google.

Automate defenses to keep pace with existing and new threats
This is the most common advice used in the face of AI-based attacks – automate defenses with AI to counter the increasing speed and magnitude of adversarial AI-based attacks. But Google warns that humans must be kept in the loop for important decisions, such as determining what constitutes a threat and how to respond to it.

The human element is important for both detection and response. “This is because AI systems can be biased or make mistakes, and human oversight is necessary to ensure that AI systems are used ethically and responsibly,” says Google.

Advertisement. Scroll to continue reading.

AI-based automation goes beyond the automated detection of threats and can also be used to decrease the workload and increase the efficiency of the security team. Secure scripts could be generated through no-code systems to control and automate security processes. Reverse engineering a malicious binary could be automated, and the subsequent automatic generation of a Yara rule could look for evidence of related activity.

Harmonize platform level controls to ensure consistent security across the organization
As the use of AI grows, it is important to have periodic reviews to identify and mitigate associated risks. This should include the AI models used and the data used to train them, together with the security measures implemented, and the AI security risk awareness and training for all employees.

Reduce overlapping frameworks for security and compliance controls to help reduce fragmentation. Fragmentation increases complexity, costs, and inefficiencies. Reducing fragmentation will, suggests Google, “provide a ‘right fit’ approach to controls to mitigate risk.”

Adapt controls to adjust mitigations and create faster feedback loops for AI deployment
This involves continuously testing and evolving systems in use, including techniques such as reinforcement learning based on incidents and user feedback. The training data needs to be monitored and updated as necessary, and the models fine-tuned to respond to attacks.

It involves being continuously aware of new attacks involving prompt injection, data poisoning and evasion attacks. “By staying up to date on the latest attack methods, organizations can take steps to mitigate these risks,” says Google. Red teaming can also help organizations identify and mitigate security risks before they can be exploited by malicious actors.

An effective feedback loop is required to ensure that everything learned is put to good use, whether that is to improve defenses or improve the AI model itself.

Contextualize AI system risks in surrounding business processes
This involves a thorough understanding of how AI will be used within business processes, and requires a complete inventory of AI models in use. Assess their risk profile based on the specific use cases, data sensitivity, and shared responsibility when leveraging third-party solutions and services.

“Implement data privacy, cyber risk, and third-party risk policies, protocols and controls throughout the ML model lifecycle to guide the model development, implementation, monitoring, and validation,” says Google.

Throughout this, it is important to assemble a strong AI security team. “AI systems are often complex and opaque, have a large number of moving parts, rely on large amounts of data, are resource intensive, can be used to apply judgment-based decisions, and can generate novel content that may be offensive, harmful, or can perpetuate stereotypes and social biases,” warns Google.

For many organizations this will expand the necessary expertise available to the security team, including business use case owners, security, cloud engineering, risk and audit teams, privacy, legal, data science, development, and responsible AI and ethics.

Google has based its SAIF framework on the experience of 10-years in the development and use of AI in its own products. The company hopes that making public its own experience in AI will lay the groundwork for secure AI – just as its BeyondCorp access model led to the zero trust principles which are industry standard today.

Related: Insider Q&A: Artificial Intelligence and Cybersecurity In Military Tech

Related: ChatGPT’s Chief Testifies Before Congress, Calls for New Agency to Regulate Artificial Intelligence

Related: Harris to Meet With CEOs About Artificial Intelligence Risks

Related: Cyber Insights 2023 | Artificial Intelligence

https://www.securityweek.com/google-introduces-saif-a-framework-for-secure-ai-development-and-use/


I just bought the only physical encyclopedia still in print, and I regret nothing

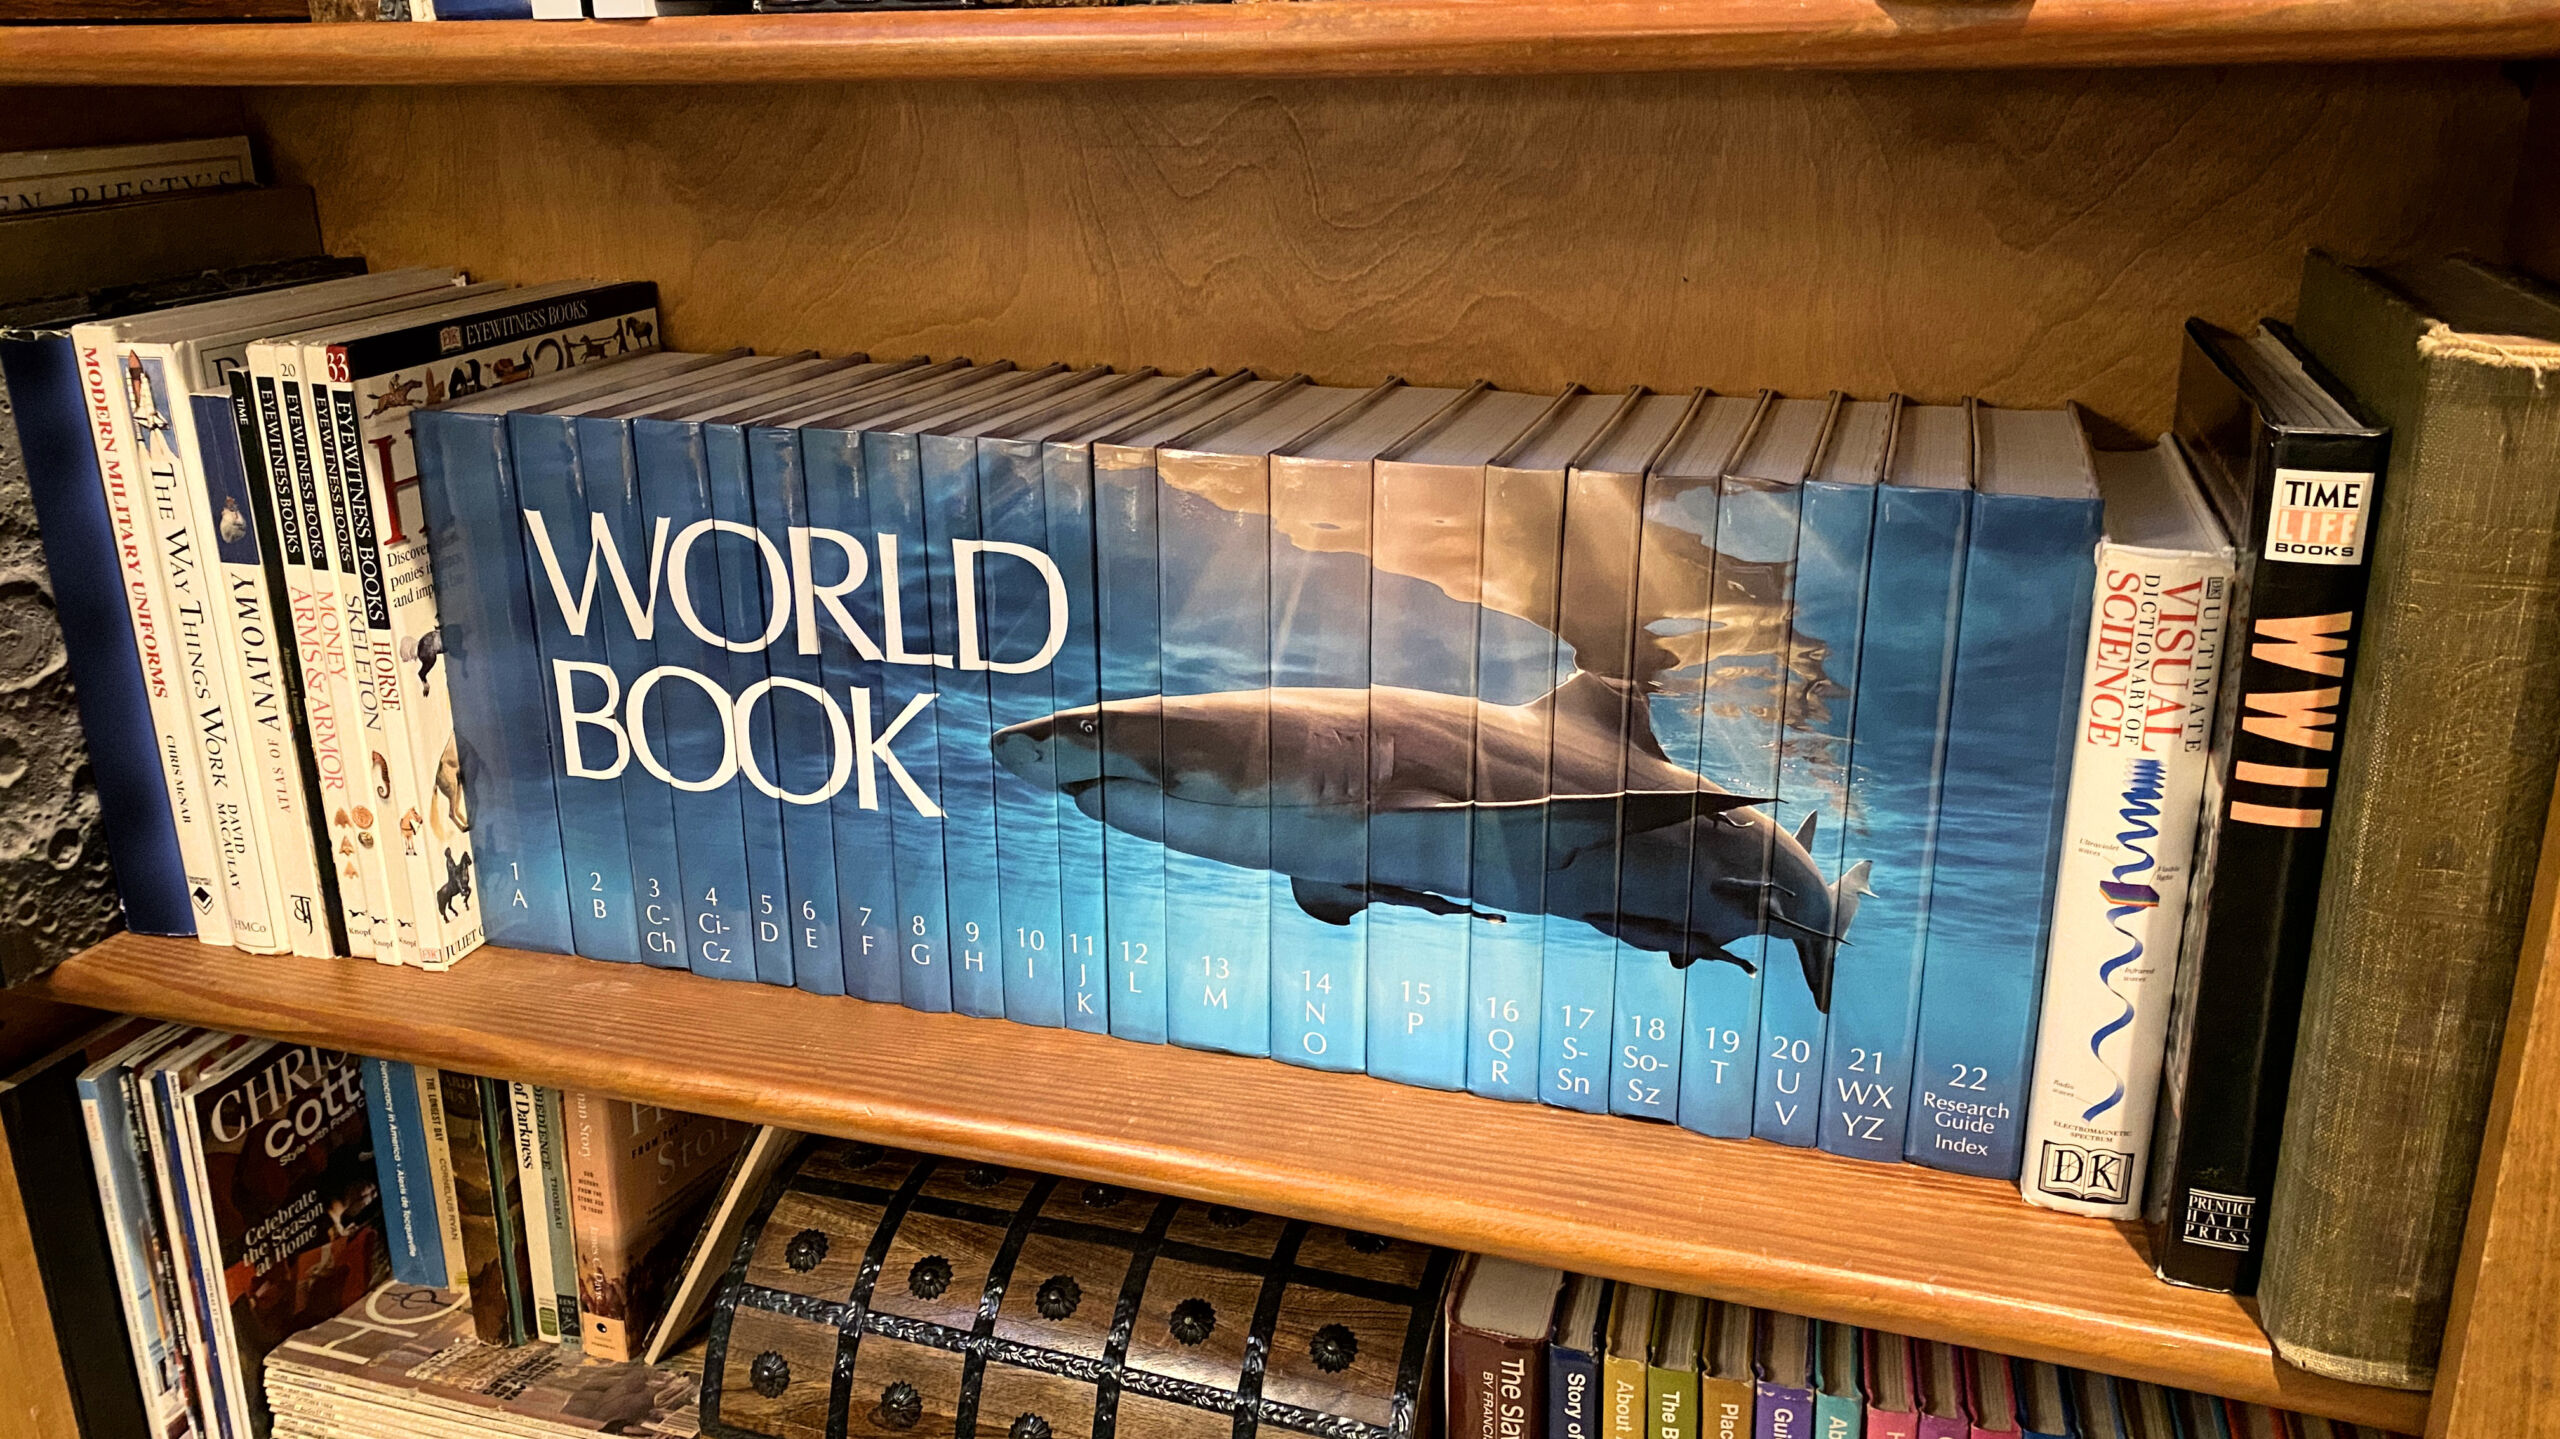
A photo of the 2023 edition of the World Book Encyclopedia on the author's family room shelf.
Enlarge / A photo of the 2023 edition of the World Book Encyclopedia on the author’s family room shelf.
Benj Edwards

These days, many of us live online, where machine-generated content has begun to pollute the Internet with misinformation and noise. At a time when it’s hard to know what information to trust, I felt delight when I recently learned that World Book still prints an up-to-date book encyclopedia in 2023. Although the term “encyclopedia” is now almost synonymous with Wikipedia, it’s refreshing to see such a sizable reference printed on paper. So I bought one, and I’ll tell you why.

Based in Chicago, World Book, Inc. first published an encyclopedia in 1917, and it has released a new edition almost every year since 1925. The company, a subsidiary of Warren Buffett’s Berkshire Hathaway, claims that its encyclopedia is “the only general reference encyclopedia still published today.” My research seems to back up this claim; it’s true even for other languages. Its fiercest competitor of yore, The Encyclopedia Britannica, ended its print run in 2012 after 244 years in print.

In a nod to our present digital age, World Book also offers its encyclopedia as a subscription service through the web. Yet it’s the print version that mystifies and attracts my fascination. Why does it still exist?

“Because there is still a demand!” Tom Evans, World Book’s editor-in-chief, told Ars over email.

Today, up-to-date information flows freely thanks to the Internet. It’s only a Google search away. Many people rely on Wikipedia, which is a nonprofit collaborative resource, for reference purposes. Despite that, some people and organizations apparently still buy paper encyclopedias. Evans said that sales of the print edition are “in the thousands” and that World Book always prints just enough copies to satisfy demand.

The Encyclopedia Britannica, a competitor of World Book, ended its print run in 2012.
Enlarge / The Encyclopedia Britannica, a competitor of World Book, ended its print run in 2012.
Encyclopedia Britannica

A World Book rep told Quartz in 2019 that the print encyclopedia sold mostly to schools, public libraries, and homeschooling families. Today, Evans says that public and school libraries are still the company’s primary customers. “World Book has a loyal following of librarians who understand the importance of a general reference encyclopedia in print form, accessible to all.”

As a kid, our family owned a 1968 edition of World Book that I relied on for school reports and projects all the way until my high school graduation in 1999, although I briefly used Microsoft Encarta on CD-ROM and a CompuServe encyclopedia in the 1990s. At the time, even with electronic references, instantaneous, up-to-date information didn’t seem as important. We were still largely operating at the speed of paper. While that concept seems foreign to us in our current world, there was a certain kind of comfort in that slowness.

Speaking of slow, a paper encyclopedia set certainly can’t run away from you. Back in the day, our family’s encyclopedia set took up a large dedicated shelf in our family room. Just like my old 1968 edition, the new print edition of World Book is a physically hefty reference. The 2023 version spans 17,000 articles spread over 14,000 pages in 22 volumes. The company says it features over 25,000 photographs, illustrations, diagrams, and maps.

All this paper-bound content can’t possibly come cheap, you might think. And, of course, you’re right. At a time when most information comes to us for free online (with strings attached, of course), it’s easy to have sticker shock at the $1,199 retail price for the 2023 edition of World Book, although shoppers might occasionally find it for as low as $799 on Amazon (to compare, the online subscription costs $250 per year). Earlier editions are available for much lower prices.

I know it may seem weird to prefer the print edition since you can get the same content in the online version in a space-saving and portable format. But with the paper version, the World Book will always be yours. It can’t be edited stealthily or taken down if the company needs the server space or goes out of business.

So I took the plunge.

https://arstechnica.com/?p=1938612


DeSantis ad uses fake AI images of Trump hugging and kissing Fauci, experts say

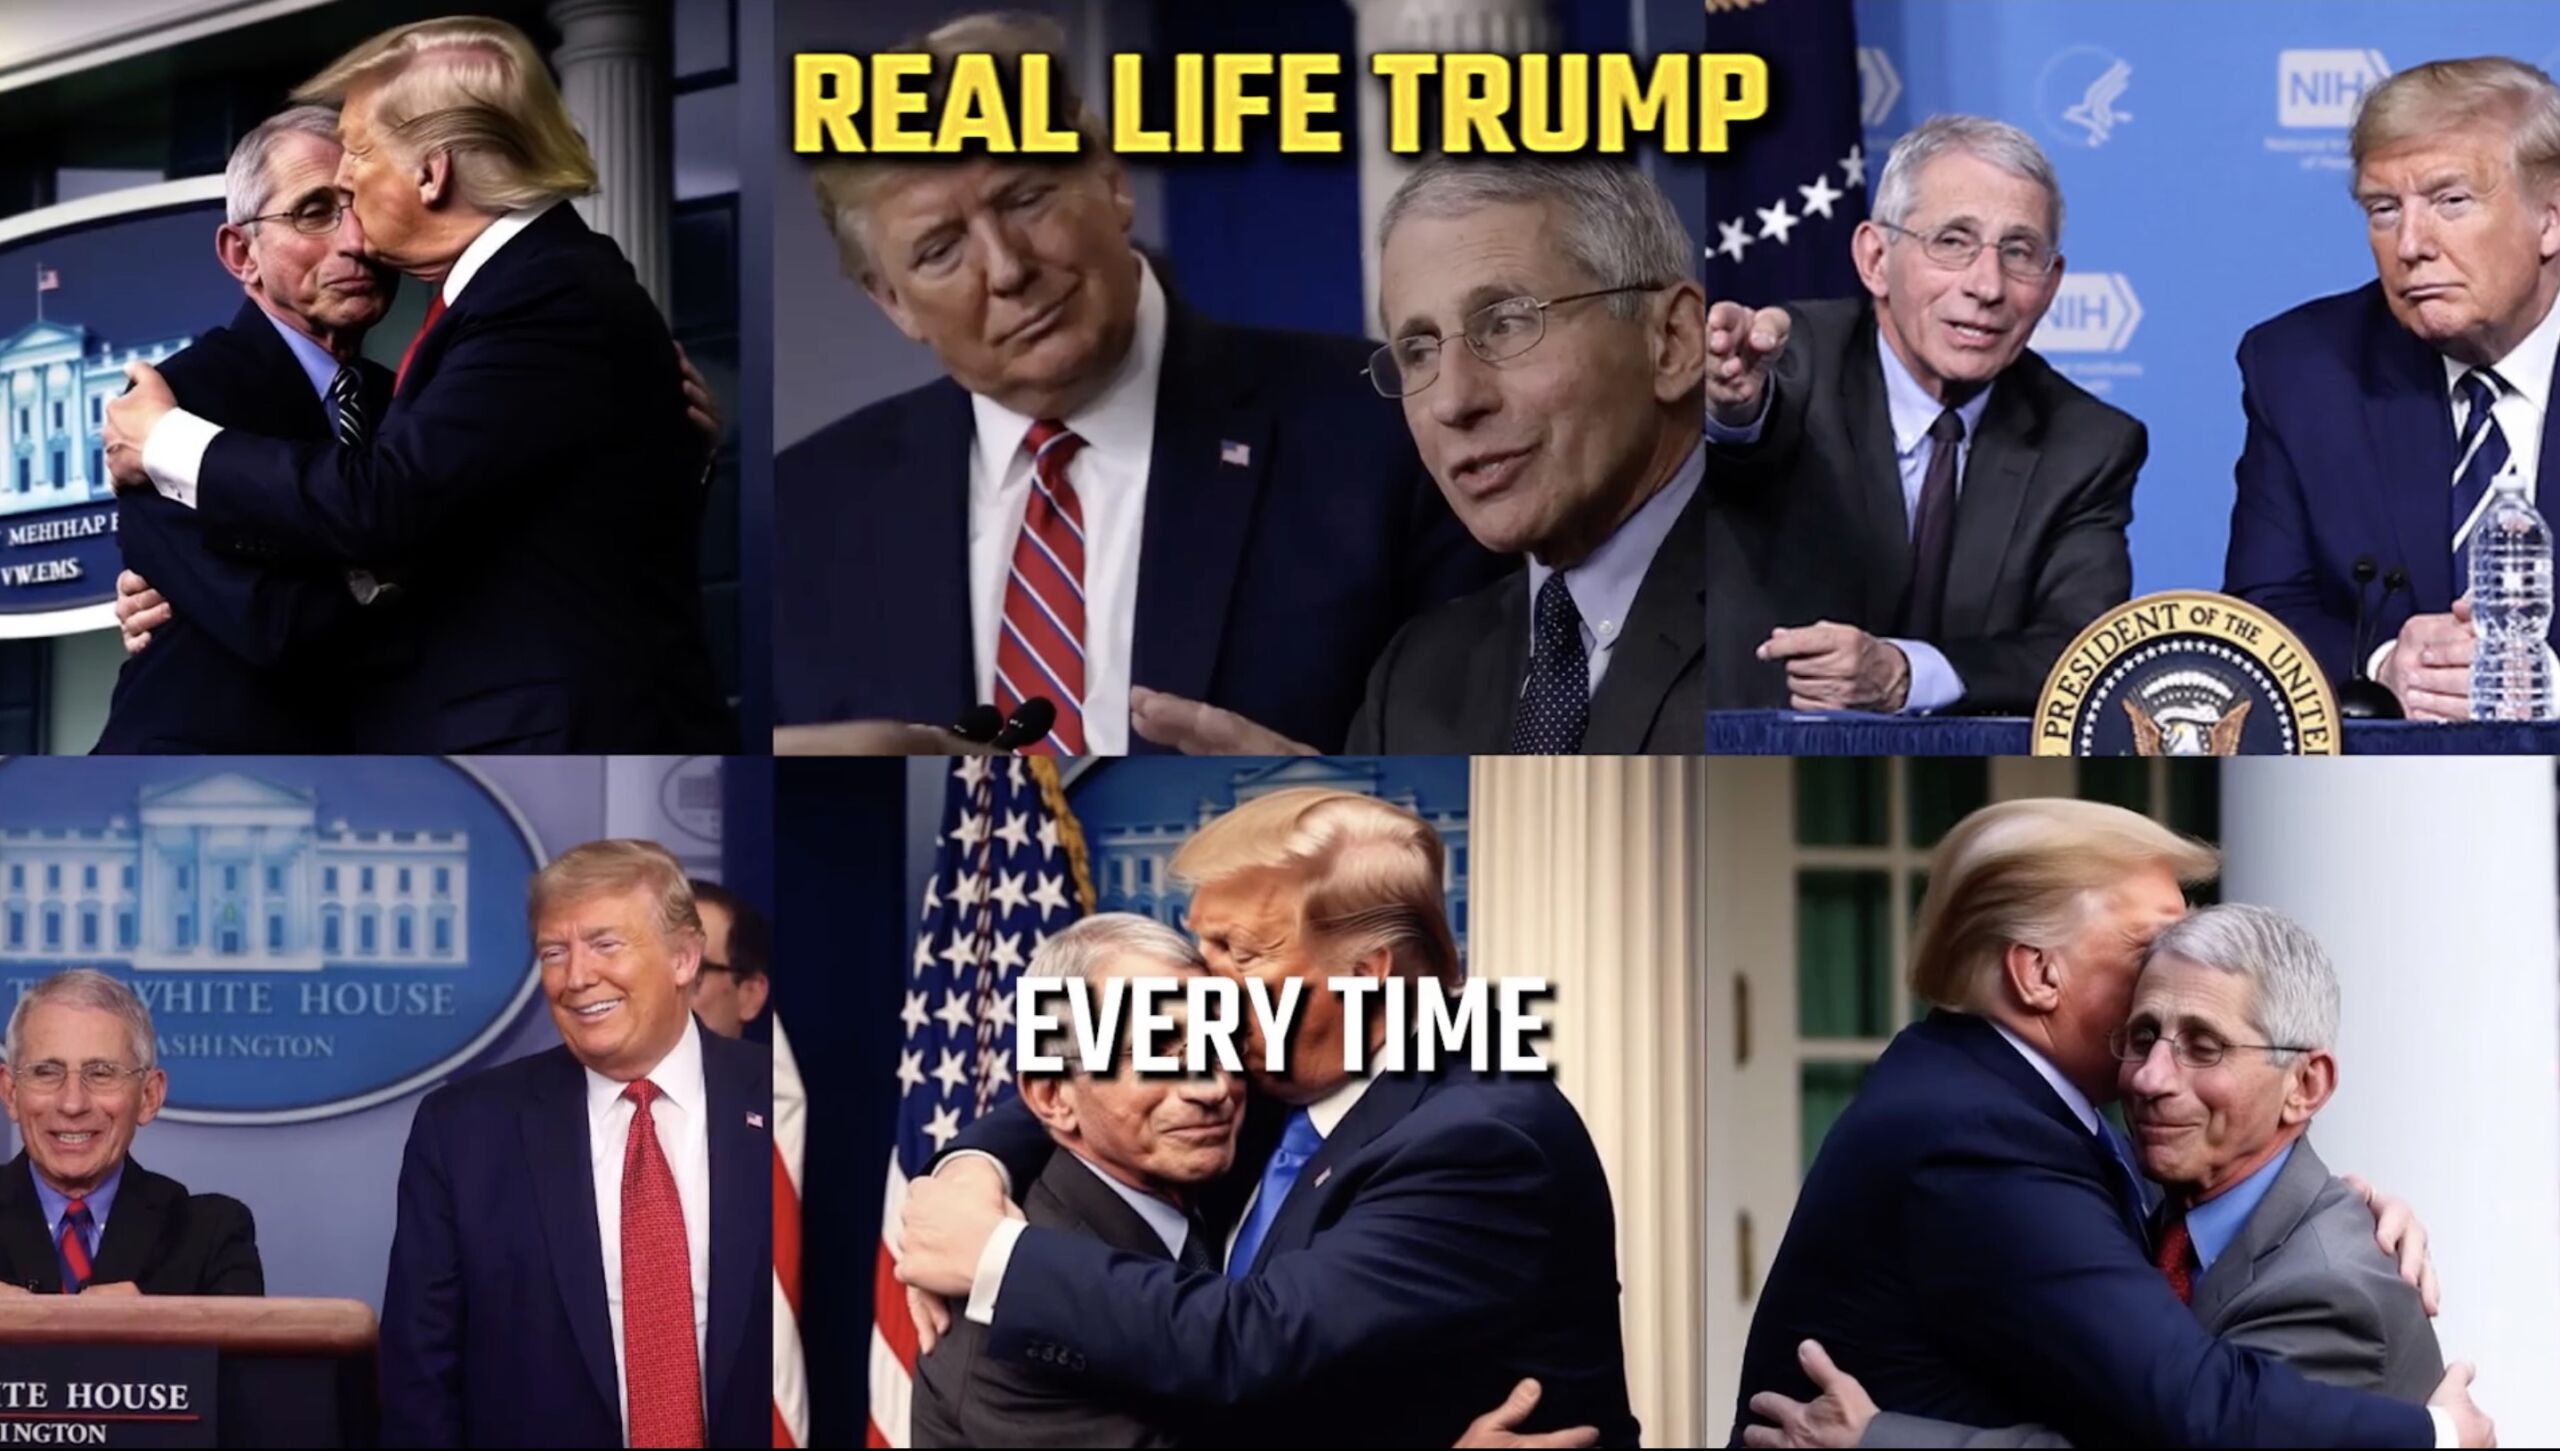
Collage shows three fake images of Trump hugging and kissing Anthony Fauci on the cheek, while three real images of the two men standing or sitting near each other are also shown.
Enlarge / Screenshot from Ron DeSantis ad shows a collage of real and fake images.

A Ron DeSantis presidential campaign video shows three pictures of Donald Trump hugging and kissing Anthony Fauci, all of which seem to be fake images generated by artificial intelligence. One professor told Ars today that there is “no doubt” the ad uses fake AI images.

As reported by AFP yesterday, media forensics experts say the images, which the DeSantis ad passed off as photographs taken during Trump’s presidency, have telltale signs of AI. Even non-experts may notice oddities, such as incomprehensible text on a sign that should say “White House” and “Washington.”

Of course, another giveaway is that then-President Trump and Fauci weren’t really on hugging and kissing terms. Trump repeatedly attacked Fauci and resisted measures to slow the spread of the COVID-19 pandemic. Fauci, who is now retired, was the longtime director of the National Institute of Allergy and Infectious Diseases.

The DeSantis video advertisement released Monday slams Trump for not firing Fauci. About halfway through, there is a collage of six images (seen at the top of this article) of Trump and Fauci.

“No doubt in my mind” that they’re fake

“There is no doubt in my mind that the top-left and bottom-middle pictures are fakes,” V.S. Subrahmanian, an AI researcher and professor of computer science at Northwestern University, told Ars today. “As pointed out in the AFP piece, the top-left image shows incorrect lettering on the picture of the White House. The bottom-middle image shows a number of weird white streaks between the stars in the US flag.”

As some people pointed out, Trump’s hair looks unnatural in the images. Ars Technica AI and Machine Learning Reporter Benj Edwards told me today that he noticed, among other problems, a “lack of detail in the hair. AI synthesis models are still bad at rendering accurate details and better at getting general things approximately correct.”

We contacted the DeSantis campaign today and will update this article if we get a response.

The three real photos in the collage show Trump and Fauci sitting or standing near each other. One of the real pictures can be found on Getty Images, another is on the National Institutes of Health website, and the third is from Reuters.

Though DeSantis is slamming Trump for not firing Fauci, DeSantis himself reportedly praised Fauci on March 25, 2020, as “really doing a good job” in a “tough, tough situation.”

Sneaky intermixing of real and fake images

“It was sneaky to intermix what appears to be authentic photos with fake photos, but these three images are almost certainly AI-generated,” University of California, Berkeley Professor Hany Farid told AFP. Farid’s research focuses on areas including digital forensics, misinformation, image analysis, and human perception. Problems in the bottom-right image include “differences in the shape of Trump’s ear as compared to stock photos,” Farid said.

The three suspicious images “contain many signs indicating that they were AI-generated,” AFP was told by Matthew Stamm, a Drexel University professor and expert on detecting falsified images and videos.

“For example, if you look closely at Donald Trump’s hair in the top-left, bottom-middle, and bottom-right images, you can see that it contains inconsistent textures and is significantly blurrier than other nearby content such as his ears or other regions of his face,” Stamm told AFP.

University of Buffalo Professor Siwei Lyu, director of the school’s Media Forensic Lab, “told AFP the [top-left] image also portrays Trump’s right arm in an abnormal position, with it appearing to extend too far as it wraps fully around Fauci’s body,” the news organization reported. In the lower-middle picture, Trump’s right hand is “clearly generated with the thumb in an unnatural position,” Lyu told AFP.

“At the same time, Stamm noted that Trump’s left hand does not appear to have a thumb in the image, instead blending into his right hand,” AFP wrote.

The DeSantis campaign ad is not the first to use AI. In April, the GOP released an anti-Biden ad that used AI-generated images.

https://arstechnica.com/?p=1946386