How to check if your ste is eligible in Preferred Sources

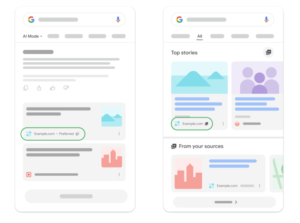
Google recently rolled out a preferred sources feature on the search results page. When a user selects a website as a preferred source, that site’s content is more likely to show up in Top Stories and gets highlighted as a preferred source within AI Overviews and AI Mode.

Here is a screenshot of how it looks.

This feature is available for all languages. Google noted that preferred sources apply to AI Overviews and AI Mode, and that only domain-level and subdomain-level sites are eligible not subdirectories. So a site like:

  • https://www.example.com/
  • https://code.example.com/

would be eligible, but something like https://www.example.com/blog would not.

How To Check If Your Site Is Eligible

Before doing anything else, check whether your site actually shows up in the source preferences tool. If it does, you can guide users to select it as a preferred source.

How To Send Users Directly To The Source Preferences Tool

You can use this URL format to take users straight to the tool:

  • https://google.com/preferences/source?q=Your_Website’s_URL

For example, if your site is example.com, the link would be:

  • https://google.com/preferences/source?q=example.com

Sharing this link with your audience in a newsletter, on social, or on your site gives them a direct path to mark your domain as a preferred source, which could help increase your visibility in Top Stories and AI-generated results going forward.

Here is Google’s official documentation.

Have you checked whether your site is eligible for preferred sources yet?

https://searchenginewatch.com/how-to-help-users-find-your-site-through-preferred-sources-in-search-results/


New Attack Methods Enable Malware to Hijack Passkey-Protected Accounts

Palo Alto Networks researchers have disclosed the details of new attack methods targeting passwordless authentication, showing how malware can hijack a passkey-protected account.

Passkeys are increasingly adopted by tech giants and are widely recommended because they are more secure against phishing.

The new attack methods, named ‘Pass-ta-key’ by Palo Alto Networks, focus on Google-synced passkeys. The security firm’s researchers showed how a threat actor could use the techniques to take over accounts without needing privilege escalation or user interaction.

In a Pass-ta-key attack, malware already present on a Windows machine running Chrome can examine the browser’s local synchronization database to identify which online accounts the user has protected with passkeys, along with associated usernames and encrypted credential material.

The malware recovers a device identity key that Chrome stores on disk or in memory. It then uses Windows cryptographic APIs to generate a signature over a challenge received from Google’s cloud authenticator service, without any biometric prompt, device unlock, or elevated privileges. 

The cloud service treats the signed request as coming from a legitimate trusted device. It returns a valid authentication assertion, which the attacker forwards to the target website to complete the login.

Advertisement. Scroll to continue reading.

In a more advanced variant, dubbed ‘Silver Pass-ta-key’, the malware forces Chrome into a device re-registration process. During a short window in that process, it registers its own user-verification key with the cloud authenticator. Once registered, the attacker can later authenticate from a completely different machine.

The most severe technique, ‘Golden Pass-ta-key’, extracts a master secret that briefly appears in Chrome’s process memory during re-enrollment. Possession of this secret allows the malware to decrypt every synchronized passkey private key belonging to the account, enabling the attacker to decrypt future passkeys as well.

Google has been notified and Palo Alto Networks’ blog post indicates that it has rolled out some mitigations. 

Related: Passkey Login Bypassed via WebAuthn Process Manipulation

Related: TP-Link Omada ZTP Vulnerabilities Chain Into Full Network Takeover

Related: Gemini Agent-to-Agent Attack Method Exposed Secrets, Enabled Pull Request Tampering

https://www.securityweek.com/new-attack-methods-enable-malware-to-hijack-passkey-protected-accounts/


As Reddit stock falls, CEO questions value of Google’s AI Overviews

Like any company, Reddit reports quarterly earnings, and its CEO, Steve Huffman, addresses investors during those reports. It’s not always about just sharing numbers, though: This quarter, Huffman took the opportunity to voice concerns and criticisms about Google’s AI Overviews feature, which automatically summarizes search results on most user queries.

First, there was a letter to investors, wherein Huffman spun his narrative about Reddit’s value proposition and general strategic direction amid the proliferation of AI tools.

He wrote:

As the internet becomes flooded with synthetic content, people are craving real human perspective. We are the antidote to an automated web. AI compresses the internet into summaries. Reddit delivers the opposite: deep discussions, passionate debates, and lived experiences. People don’t want a summary of Reddit; they want Reddit.

The letter also said:

As AI makes information more abundant, the challenge is no longer finding content—it’s finding context, personal opinion, and first-hand accounts. Everything online feels flat, polished, generated, or sponsored, so consumers are overwhelmed and increasingly skeptical. We’ve never had more information, but we’ve never trusted it less.

And then, in comments around the earnings report, he added:

What we see is, 10 blue links has driven tremendous value and growth to the broader ecosystem… from where we sit, AI Overviews has yet to make a similar level of positive impact, and I think that’s consistent across the broader landscape, right? As businesses, publishers, retailers, we’re still looking for that win-win.

To add context to these statements, Reddit has long had a relatively lucrative ($60 million) licensing deal with Google, but Reddit is considering ending that deal, according to a Wall Street Journal report from earlier this month. The report also said that several prominent publishers are considering similarly cutting ties with Google, including The Economist, Reuters, Politico, and USA Today. (Reddit also has a deal with OpenAI.)

Last year, a study by Pew Research that looked at data from 900 US adults concluded that Google’s AI Overviews cut referrals to sites like those by almost half, compared to the “10 blue links” approach that Huffman referred to. It’s important to note, though, that Google has long diverged from just “10 blue links” in other ways even before AI Overviews entered the scene.

https://arstechnica.com/ai/2026/08/reddit-ceo-on-ai-overviews-were-still-looking-for-that-win-win/


Google AI Uncovers 13-Year-Old Chrome Flaw Amid Record Patching Pace

Google this week confirmed that this year’s surge in Chrome vulnerabilities has been driven by the use of AI.

The increase in Chrome bugs started in April and has continued throughout July, with the latest browser release containing 370 security fixes and bringing the total number of bugs patched this year to over 1,800.

Google patched 1,072 security defects with the Chrome 149 and 150 releases, “surpassing the total number of security bugs fixed across the prior 23 milestones combined.”

This was the result of using an agent harness that leverages Gemini to identify security flaws across Chrome’s codebase with increased efficiency, the internet giant says.

What validated the AI-powered vulnerability detection, Google says, was the discovery of a sandbox escape that lurked in the browser for 13 years.

Tracked as CVE-2026-3545 (CVSS score of 9.8) and patched in early May in Chrome 145, the issue could have allowed “a compromised renderer to trick the browser into reading local files,” it says.

Advertisement. Scroll to continue reading.

Described as an insufficient data validation in Navigation, the vulnerability could have been exploited via crafted HTML pages to perform a sandbox escape.

The Chrome Security team started using LLMs in 2023, but it was the agent harness built in early 2026 that has been essential to finding and patching more flaws in the browser.

It has support for model interoperability, was trained on a knowledge base of previously identified CVEs and of Chrome’s entire Git history, leverages developer-supplied SECURITY.md files that are consumed by a “critic” agent, and can run vulnerability-finding models over the codebase multiple times.

“We’ve built all of this with safety in mind, and have put in place guardrails to mitigate the risk of AI behaving unexpectedly. Our AI analyzes source code strictly at rest, operating on locked-down machines that lack general internet access,” Google explains.

While also relying on AI for bug validation, triaging, and patch generation, the internet giant continues to use other security testing infrastructure for bug detection, and welcomes researchers submitting vulnerability reports through its VRP.

“At this point, we have LLMs generating candidate fixes for most vulnerabilities, dramatically increasing the rate of security fixes in recent Chrome releases,” Google says.

Additionally, the company is relying on AI to prevent new security bugs by identifying and eliminating them “as close to code submit-time as possible” and by neutralizing issues in the tree that could impact code deemed safe in isolation.

Reducing the patch gap and eliminating memory safety bugs

To reduce the patch gap, Google is also piloting a twice-a-week Chrome security release cadence, which will complement the two-week schedule for major Chrome releases that was announced in March.

“We are working on automating the generation of release notes and CVE descriptions from security bug fixes to eliminate manual bottlenecks and shorten the window between vulnerability discovery and public disclosure,” the company says.

Google is also working on ensuring that Chrome is always up to date on users’ machines, through dynamic patching, which eliminates the need to restart the browser when applying updates, seamless session restoration, and restarts while in a windowless state (the application runs in the background while all windows are closed).

Additionally, Google is working on eliminating entire classes of security issues from Chrome, such as memory safety flaws. For that, it is hardening the runtime environment to squash C++ bugs, and is transitioning to memory-safe languages.

In this regard, it is expanding MiraclePtr to more libraries and deploying MiracleObject to the GPU main thread to neutralize use-after-free defects. In addition, it’s taking a ‘spanification’ effort to eliminate out-of-bounds weaknesses, and is integrating memory allocation protections to block integer overflows.

In the long term, Google is transitioning Chrome’s codebase to memory-safe languages like Rust, through building a centralized Rust SDK, deploying Rust to replace most flawed code segments, and writing new modular components in Rust.

“In addition to Rust, we are also exploring options like implementing the browser’s top-level user interface using HTML, CSS, and TypeScript to further reduce dependencies on traditional C++ frameworks,” Google notes.

According to the company, keeping the open source software ecosystem secure is another critical aspect of improving Chrome users’ protections. It has been using automated vulnerability scanning pipelines to keep dependencies patched and will move all Chrome third-party dependencies onto automated update pipelines.

“Every bug found and fixed is one less foothold for an attacker. But discovering and fixing a bug is only half the battle — we must also ship the fix and apply the update for users faster than adversaries can exploit the bug, and invest in projects that mitigate or eliminate classes of bugs through accelerated release cadences, dynamic patching, and opportune restarts, we are driving toward a browser that is continuously protected without disrupting the user,” Google notes.

Related: Critical Flaw Led to Azure Cosmos DB Pwnage

Related: Timeless Compliance: Why Better Questions Beat Bigger Frameworks

Related: Microsoft Unveils MAI-Cyber-1-Flash, Its First Cybersecurity AI Model

Related: Anthropic’s Opus 5 Nears Mythos 5 on Finding Bugs, but Falls Short on Exploits

https://www.securityweek.com/googles-ai-agent-uncovers-13-year-old-chrome-flaw-amid-record-patching-pace/

Google’s “privacy-preserving” age verification system is coming to the Play Store

Governments around the world are suddenly very keen on online age verification requirements. In some places, this takes the form of ID requirements to access adult content, but several US states have also focused on app stores. With these laws now going into effect, Google has announced an expansion of its beta Play Age Signals API, which it claims will allow developers to confirm user ages without impinging on privacy.

Google’s system doesn’t require an ID or selfie verification—it’s connected to the company’s existing Family Link app. The idea is that parents will set age ranges for their kids’ managed accounts. For example, you might set a range like 16–17, allowing apps to tailor experiences and content for teenagers.

Google notes that the ranges are dynamic and may change as young users get older. So a kid who’s 13 may be in the same app content bracket for a few years before hitting the next level. Parents have the option to set and share these ranges if they want that additional level of control over what their children can access in Google Play. However, it’s not mandatory for child accounts—it’s fully opt-in and can be turned off at any time.

Google began testing the Play Age Signals API late last year as it became apparent that multiple states were going to put the onus of age verification on app stores. The Computer & Communications Industry Association (CCIA), which lobbies on behalf of tech firms, has opposed these laws. However, the US Supreme Court recently paused a lower court injunction, allowing the Texas law to take effect. Louisiana and Utah also have similar laws going into effect.

https://arstechnica.com/gadgets/2026/07/google-begins-global-rollout-of-age-verification-api-in-google-play/


Editori contro Google: Reddit riconsidera l’accordo da 60 milioni. Politico e Reuters valutano il blocco

Per anni Google ha rappresentato una fonte fondamentale di traffico per gli editori online. Ora l’espansione delle risposte generate dall’AI sta incrinando quel rapporto: il motore di ricerca utilizza i contenuti per rispondere direttamente agli utenti, ma invia sempre meno visitatori ai siti che li hanno prodotti.

Secondo quanto ricostruito dal Wall Street Journal, Reddit, USA Today, Politico, The Economist, People Inc. e Reuters stanno valutando come proseguire la collaborazione con Google e, in alcuni casi, se bloccare del tutto l’accesso ai propri contenuti.

Reddit riconsidera l’accordo da 60 milioni

Nel 2024 Reddit ha firmato con Google un accordo da 60 milioni di dollari l’anno, consentendo al gruppo di utilizzare il materiale pubblicato sulla piattaforma per addestrare i propri modelli AI.

Con l’intesa vicina alla scadenza, riferisce il Wall Street Journal, i dirigenti di Reddit stanno però valutando quale vantaggio rimanga nel continuare ad alimentare i sistemi di Google, mentre le risposte generate dall’AI riducono i clic verso i siti esterni. Le due aziende stanno discutendo un possibile rinnovo.

“Per alcune categorie di editori è una questione esistenziale”, ha dichiarato al quotidiano David Buttle, amministratore delegato della società di consulenza DJB Strategies. “Stanno valutando soluzioni più radicali”.

USA Today: “È il momento di dire basta”

USA Today Co., proprietaria dell’omonima testata nazionale e di centinaia di giornali locali, sta considerando di bloccare il crawler di Google. Una scelta che escluderebbe i suoi contenuti sia dalle sintesi AI sia dai tradizionali risultati con i link blu.

I dati di Semrush citati dal Wall Street Journal mostrano che, tra giugno 2025 e giugno 2026, il traffico organico proveniente dagli utenti statunitensi di Google verso il sito nazionale di USA Today è diminuito del 18%.

“È il momento di prendere posizione e dire che ne abbiamo abbastanza”, ha affermato l’amministratore delegato Mike Reed. Il gruppo sarebbe disposto a chiudere l’accesso a Google qualora il calo del traffico proseguisse e starebbe già preparando il proprio modello economico a un futuro senza i ricavi generati dal motore di ricerca.

USA Today ha inoltre avviato una causa contro Google, accusandolo di detenere un monopolio nelle tecnologie pubblicitarie che danneggerebbe i ricavi degli editori.

Traffico in calo per Politico, CNN e Reuters

La flessione riguarda anche altre grandi testate. Secondo Semrush, il traffico statunitense proveniente da Google è diminuito del 20% per Politico e del 31% sia per CNN sia per Business Insider tra giugno 2025 e giugno 2026.

Il Wall Street Journal riferisce che alcuni dipendenti di Politico hanno discusso la possibilità di limitare l’accesso di Google e degli altri bot agli articoli gratuiti, introducendo una registrazione obbligatoria per gli utenti umani.

Anche Reuters sta valutando se bloccare il crawler di Google per il proprio sito destinato al pubblico.

“Stiamo certamente esaminando il compromesso economico tra la ricerca e le sintesi AI”, ha dichiarato al Wall Street Journal il presidente di Reuters, Paul Bascobert.

Il nodo dei crawler

Secondo Cloudflare, citata dal quotidiano americano, i bot rappresentano ormai oltre la metà del traffico web. Alcuni raccolgono contenuti per addestrare modelli AI, altri analizzano i siti per rispondere alle domande degli utenti o vendono il materiale raccolto ad altre aziende.

Gli editori possono impedire a Google di utilizzare i propri contenuti per l’addestramento dei modelli, ma in genere devono consentire al crawler di accedervi sia per le funzioni AI sia per la ricerca tradizionale, qualora vogliano comparire in entrambe. Bloccare Google può quindi significare rinunciare non soltanto alle sintesi AI, ma anche alla visibilità nei risultati classici.

Google difende le sue funzioni AI

Google respinge l’idea che le nuove funzionalità stiano semplicemente sottraendo traffico agli editori. Un portavoce ha dichiarato al Wall Street Journal che gli strumenti AI inviano ogni settimana miliardi di clic verso il web, evidenziano i collegamenti alle fonti e aiutano creatori ed editori ad ampliare il pubblico.

Il gruppo ha inoltre avviato un programma che remunera più di 200 editori per l’accesso ai contenuti destinati all’AI.

A giugno Google ha annunciato che, in seguito a una decisione dell’autorità britannica, permetterà agli editori di scegliere se partecipare alle funzionalità AI senza perdere la presenza nei risultati di ricerca tradizionali. La sperimentazione partirà nel Regno Unito, senza una tempistica definita per l’estensione globale.

People Inc. non esclude il blocco

People Inc., proprietaria di testate come People, Better Homes & Gardens e Travel + Leisure, ha già ridotto la propria dipendenza dal motore di ricerca.

Nel primo trimestre dell’anno Google ha generato il 25% del traffico del gruppo, contro oltre la metà di due anni prima. La società continua a consentire al crawler di accedere ai propri contenuti, ma sta rivalutando il rapporto.

“Bloccarli completamente è assolutamente un’opzione”, ha dichiarato al Wall Street Journal l’amministratore delegato Neil Vogel.

Per anni lo scambio è stato semplice: gli editori consentivano a Google di indicizzare i propri contenuti e ricevevano in cambio traffico, pubblicità e nuovi abbonati. Con le risposte generate dall’AI, questo equilibrio sta venendo meno. Google continua ad avere bisogno di contenuti autorevoli per alimentare i propri servizi, ma gli editori ricevono sempre meno visite.

Novità su Google, per aggiungere Key4Biz tra le tue fonti preferite, clicca qui

Aggiungi Key4Biz tra le tue fonti preferite

Leggi le altre notizie sull’home page di Key4biz

https://www.key4biz.it/editori-contro-google-reddit-riconsidera-laccordo-da-60-milioni-politico-e-reuters-valutano-il-blocco/582502/


It’s official: EU will force Google to share search data and open up AI on Android

The EU’s mandates for Google Search could have more wide-ranging implications. Google will be forced to share search data with competing search providers, giving them a better chance of gaining market share and loosening Google’s iron grip on web search. The Commission alleges this action was necessary because Google’s past sharing offers have not gone far enough.

Under the new rules, Google will have to provide data to other search firms transparently and for a reasonable fee. Google will also have to treat AI chatbots as search services for the purposes of data sharing. The goal is for other companies to get access to search metrics similar to what Google itself sees, which EU regulators claim is essential for a smaller player to challenge Google’s dominance.

Google calls for “balance”

Google was vocally opposed to the EU’s new rules before they were finalized, and the company is not mincing words now that they’re final. Kent Walker, Google’s president of global affairs, claims Google offered more measured solutions that it believed could satisfy the DMA’s goals, but the path chosen by the European Commission goes too far and will harm users.

“Today’s decisions risk undermining vital privacy and security guardrails for millions of Europeans,” said Walker.

Walker objects to the Commission’s position that AI assistants need greater access to Android. He claims that AI tools are widely supported, with phone makers playing a key role in vetting them. Granting non-Gemini AI platforms deeper integration with Android could circumvent safeguards, he said.

Similarly, Google contends that sharing search data as the EU now demands will risk user privacy. The DMA action calls on Google to anonymize data using a multilayered approach, and the Commission is open to amending its decision to ensure identifiable data is appropriately handled. Google acknowledges that regulators are open to adjusting the rules, but Walker still characterizes this ruling as a threat to privacy, business trade secrets, and even national security.

Google will have some time to hash out the specifics with EU regulators. The company must be ready to start sharing search data with other companies in January 2027. The Android platform must be updated for deeper integration with AI apps by July 2027.

https://arstechnica.com/gadgets/2026/07/its-official-eu-will-force-google-to-share-search-data-and-open-up-ai-on-android/


Google revamps image search for its 25th anniversary with more images and more AI

Believe it or not, there was a time when searching the web for images was not possible. Twenty-five years ago, Google launched image search, and it’s celebrating by looking back at its biggest visual milestones and refreshing the experience for today’s searchers. The celebration also includes expanded AI because that’s just how Google rolls in 2026.

Google claims the impetus for image search a quarter-century ago was the green Versace dress Jennifer Lopez wore to the 2000 Grammy Awards. If you were alive at the time, you probably remember the one. Google engineers understood that people searching for the dress didn’t want to read about it—they just wanted to see it. The company got to work building image search, launching the first version in July 2001. Twenty-five years later, it’s easy to take for granted that you can search for Lopez’s green dress or whatever else strikes your fancy.

Currently, going to the Google image search site shows a plain search bar for finding images. It’s a refreshingly minimalist interface for the modern web. Even Google’s search homepage has a smattering of AI buttons and drop-down menus. That will change when the new Google Images rolls out.

Soon, Google Image search will feature a gallery of images from across the web before you’ve even searched for anything. Google says this gallery will be updated continuously based on your interests. Your “interests” in this context means your web and search history on Google. So the things you look up and interact with online will inform what content Google suggests in this new interface.

https://arstechnica.com/google/2026/07/google-revamps-image-search-for-its-25th-anniversary-with-more-images-and-more-ai/


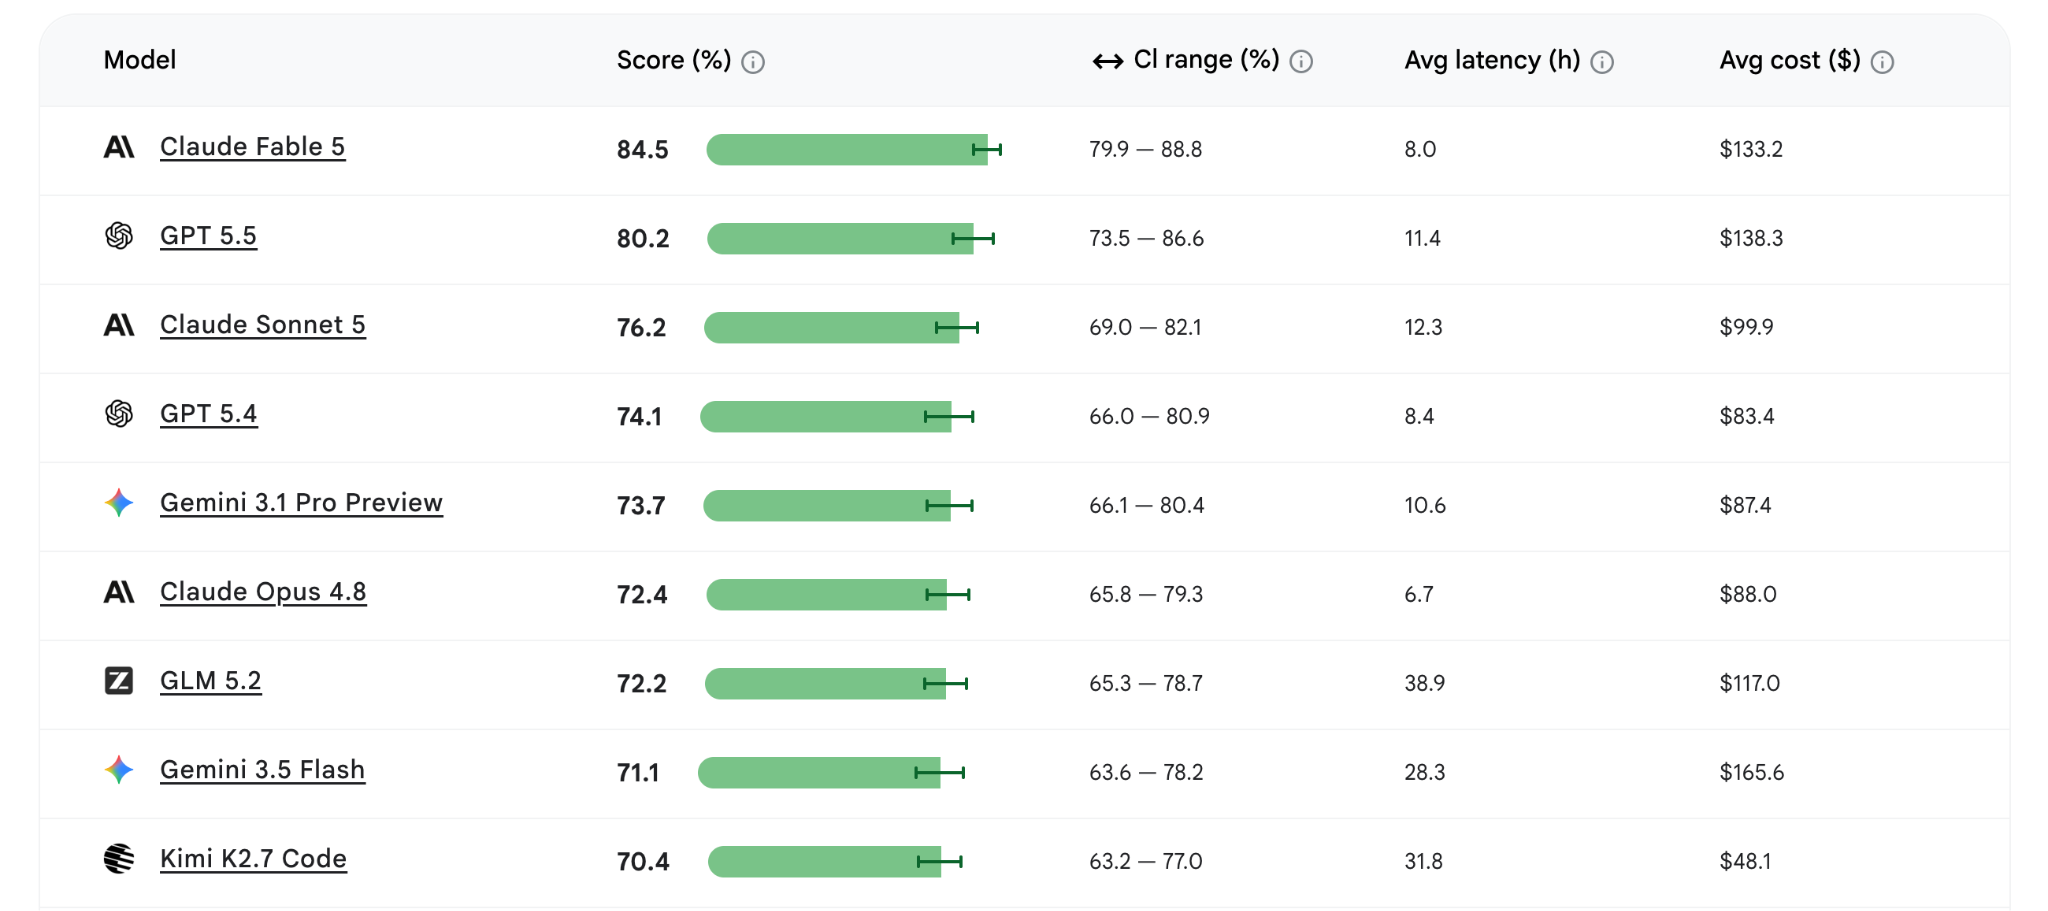
Google updates Android Bench with new LLMs, but Gemini still lags behind

Google’s updated leaderboard shows Gemini slipping to fifth place.

Credit: Google

Google’s updated leaderboard shows Gemini slipping to fifth place. Credit: Google

However, Fable 5 and GPT 5.5 also have extremely high operating costs, chewing through more than $130 in tokens for the 100-problem, 10-run benchmark. Gemini 3.1 Pro didn’t score as high, but it only costs $87 to run the test. Gemini 3.5 Flash, which is supposed to be cheaper to run than other models, has the highest cost on the leaderboard because it took so much longer to complete the benchmark: $165 per run and a 28-hour runtime.

The Android coding performance gap for Google’s models is a problem as the company shifts many of its projects toward agentic development. Obviously, Google would prefer that Android developers use Google’s tools in their workflows, which may be why Google has reportedly been offering to buy application source code from developers for AI training.

Community collaboration

Android Bench is supposed to evolve over time, adopting new workflows to test models. Google hopes that developers will want to contribute to Android Bench by sharing benchmarks and development tasks. To make that more feasible, Google is switching to the Harbor framework. According to the company, this testing sandbox makes it easy for developers to run, evaluate, and share results for Android Bench.

Google re-ran all its previous tests with Harbor to get a new baseline for LLM performance. So there has been some shift in the previously reported scores even though the underlying tests haven’t changed (yet). The historical data will remain online in an archive.

With the new, easier framework, developers can run their own development tasks against Android Bench and submit those for possible inclusion in the official test. The Android Bench GitHub has been updated with the new dataset and instructions on how to get involved.

https://arstechnica.com/google/2026/07/google-revamps-android-ai-dev-benchmark-adds-fable-5-and-other-agents/


Google loses long-running appeal of record EU fine, will have to cough up $4.7 billion

Back in 2018, Google was handed a record-setting 4.34 billion-euro ($4.9 billion) fine in Europe for abusing its monopoly on Android. The company has spent the intervening years challenging that decision, but the continent’s highest court has put a stop to that. The Court of Justice of the European Union has affirmed the penalty, meaning Google is out of options.

Google’s fight may not have turned out the way the company wanted, but it wasn’t for nothing. The initial amount was trimmed slightly by a lower court in 2022, bringing the total to a still record-setting 4.1 billion euros ($4.7 billion). And that looks like the amount Google will have to pay since there are no further avenues for appeal.

The fine stems from the way Google bundles apps and services with Android phones. The EU took issue with Google search and Chrome being the default options on Android. Even devices made by other companies, such as Samsung and Xiaomi, include Google apps as the default per the Android licensing agreement, giving Google an unfair advantage, according to European antitrust regulators. This is not to be confused with a 2.95 billion euro ($3.45 billion) fine against Google’s advertising monopoly issued by the European Union last year.

“The appeal ​brought by Google and its parent company Alphabet against the judgment of the ‌General Court is dismissed, thereby confirming the ​penalty imposed for Google Search’s abuse of a dominant position in the context ⁠of the Android operating system,” the judge’s ruling (PDF) said.

The case mirrored Europe’s actions against Windows years earlier when Microsoft was forced to add browser ballot screens to crack Internet Explorer’s dominance. Of course, Microsoft’s browser dominance was crumbling by the time the EU managed to get that implemented. Google’s market position, however, remains firmly in place despite creating similar ballot screens on Android when the ruling was first handed down.

https://arstechnica.com/gadgets/2026/07/google-loses-long-running-appeal-of-record-eu-fine-will-have-to-cough-up-4-7-billion/