WordPress Releases AI Plugins For Anthropic Claude, Google Gemini, And OpenAI via @sejournal, @martinibuster

WordPress has created three new plugins that make it easy to add OpenAI, Google Gemini, or Anthropic Claude integration for the PHP AI Client SDK. The plugins enable text, image, function calling and web search support.

Requirements For Using WordPress AI Plugin

PHP 7.4 or higher is required to use these plugins and of course an API key for the AI model. Users on WordPress 6.9 will need to install the WordPress PHP AI client SDK. WordPress 7.0 which rolls out in early April will have the SDK integrated by default.

The official WordPress.org documentation for the PHP AI client explains:

“The PHP AI Client SDK …provides shared infrastructure that lets WordPress plugins and other PHP projects integrate AI capabilities rapidly and flexibly. …it offers a unified interface that works across all AI providers – from simple text generation to complex multimodal operations, streaming responses, and long-running tasks.

Developers specify what AI capabilities they need, and users manage their provider credentials in one place. Those credentials then work automatically across all compatible plugins on their site.”

WordPress AI Plugin Features

The features for the OpenAI plugin version are:

  • Automatic provider registration
  • Function calling support
  • Image generation with DALL-E models
  • Text generation with GPT models
  • Web search support

The description for the WordPress OpenAI plugin explains:

“Available models are dynamically discovered from the OpenAI API, including GPT models for text generation, DALL-E and GPT Image models for image generation, and TTS models for text-to-speech.”

Features for Anthropic Claude:

Automatic provider registration

Extended thinking support

Function calling support

Text generation with Claude models

Available features for Google Gemini integration:

  • Automatic provider registration
  • Function calling support
  • Image generation with Imagen models
  • Text generation with Gemini models

Download The WordPress AI Plugins

Find the WordPress AI Plugins here:

AI Provider for Anthropic

AI Provider for Google

AI Provider for OpenAI

https://www.searchenginejournal.com/wordpress-releases-ai-plugins-for-anthropic-claude-google-gemini-and-openai/568822/


Google Updates AI Mode Recipe Sites Results In Response To Backlash via @sejournal, @martinibuster

Robby Stein, VP of Product Google Search, posted that Google is updating AI Mode so that it surfaces more links to creators when users search for recipes. Google’s AI Mode has generated controversy by synthesizing multiple recipes into what many have taken to calling Frankenstein recipes. This new update aims to fix that by making it easier to tap and see a link to the recipe sites.

Change To How AI Mode Displays Recipes

What Google did was to create an attractive display of recipes that when clicked opens a side panel that displays recipe images and a summary of the recipe. The user can click from there to visit the recipe site and explore the dish in more depth.

Robby Stein said that this change is already rolled out. I tried variations of Stein’s example keyword phrase (easy recipes for two) and was able to spawn a recipe panel, what I think he’s referring to. On the left is a summary and in this specific AI Mode results, I had to scroll down to get to the images that can be clicked.

Screenshot Of AI Mode Without Images To Click

Scrolling down the page reveals a new topic with images that can be clicked.

Screenshot Of AI Mode Images That Can Be Clicked

The problem with this AI Mode result is that it’s not clear that those images can be clicked. They look like decorative images. It may be that a user will not going to intuitively understand that clicking those images will generate a side panel to the right with more information on that particular dish.

Screenshot Of AI Mode Panel With Recipe

Announcement By Robby Stein Of Google

Google’s Robby Stein made a direct mention of the “feedback” they had received about how AI Mode was handling meal ideas.

According to Robby Stein:

“We’ve heard feedback on recipe results in AI Mode, and we’re making updates to better connect people with recipe creators on the web. Starting today, when you search for meal ideas like “easy dinners for two,” you can tap on the dish to see links to relevant recipe sites, plus a short overview of the dish to help with inspiration.

We’re also planning to bring helpful information like cook time to more recipe results, which testers have found useful for deciding on a recipe. We know there’s more work to be done on this, so stay tuned for future updates.”

He also posted a video of the feature in action:

Featured Image by Shutterstock/Luis Molinero

https://www.searchenginejournal.com/google-updates-ai-mode-recipe-sites-results-in-response-to-backlash/568798/


Phishing OAuth: campagne contro enti pubblici sfruttano Microsoft


Nuove campagne di phishing stanno sfruttando in modo strumentale il protocollo OAuth per distribuire malware e compromettere endpoint aziendali, con un focus particolare su organizzazioni governative e del settore pubblico. A diffondere la notizia è stata Microsoft stessa che ha rilevato un abuso sistematico dei meccanismi di redirect legittimi previsti dallo standard di autorizzazione.

Secondo quanto comunicato dal team di sicurezza di Redmond, alcune applicazioni OAuth malevole sono già state disabilitate su Microsoft Entra ID, ma attività correlate risultano ancora in corso e richiedono monitoraggio continuo. Non sono stati resi noti dettagli su scala e impatto delle campagne.

OAuth come vettore: quando il redirect diventa arma

OAuth (Open Authorization) è lo standard utilizzato per consentire l’accesso a servizi online tramite credenziali di terze parti, come Google, Facebook o Apple, attraverso l’uso di access token. Una delle funzionalità previste dallo standard permette agli identity provider di reindirizzare l’utente verso una landing page in caso di errore durante il processo di autenticazione. E proprio questa caratteristica viene sfruttata dagli attaccanti.

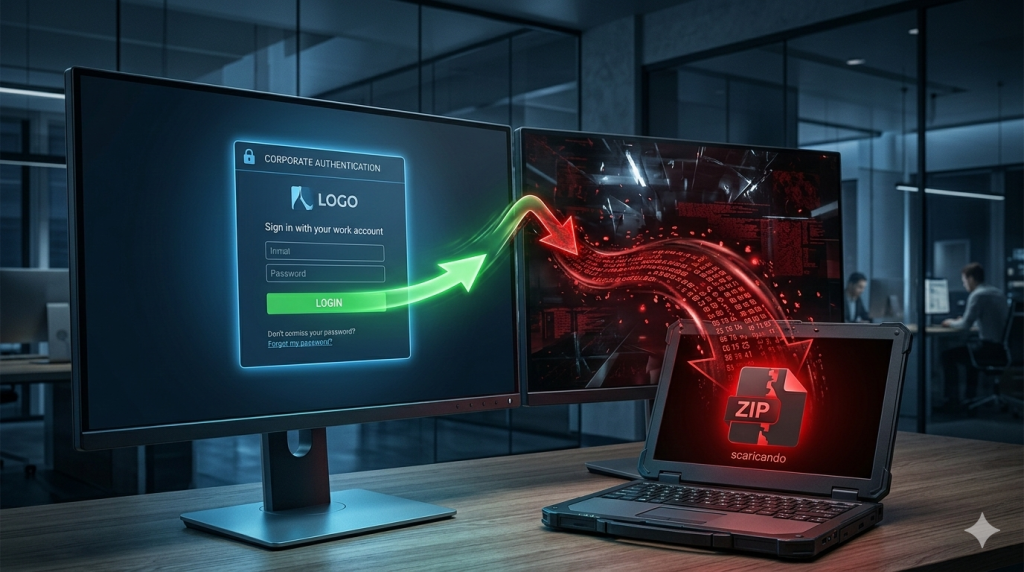
I criminali creano URL OAuth apparentemente legittimi, utilizzando provider come Microsoft Entra ID o Google Workspace, ma manipolano specifici parametri per generare volutamente un errore nel processo di login. L’errore innesca un redirect verso una pagina sotto il controllo degli attaccanti, dalla quale viene scaricato il payload malevolo.

Un esempio di URL osservato nelle campagne contro Entra ID include parametri come scope non validi e prompt=none, combinati in modo tale da produrre un comportamento anomalo pur mantenendo un’apparenza coerente con una richiesta OAuth standard.

Come evidenziato dai ricercatori Microsoft, l’obiettivo non è il furto degli access token, poiché l’utente non concede alcun permesso all’applicazione. Lo scopo è invece forzare un errore che attivi il meccanismo di redirect, trasformando un flusso legittimo in un veicolo di distribuzione malware.

Dalla mail al C2: la catena di infezione

Le campagne iniziano con email di phishing che simulano richieste di firma elettronica, notifiche di registrazioni di riunioni Teams, reset password Microsoft 365 o contenuti a tema politico. I link malevoli vengono inseriti nel corpo del messaggio o, in alcuni casi, nascosti in allegati PDF.

Gli indicatori suggeriscono l’uso di strumenti di mass mailing preconfigurati, oltre a soluzioni custom sviluppate in Python e Node.js. Sono stati impiegati anche servizi cloud di posta elettronica e macchine virtuali ospitate nel cloud per la distribuzione delle email.

Una volta attivato il redirect OAuth, la vittima viene condotta su piattaforme di phishing-as-a-service come EvilProxy, in grado di intercettare credenziali e cookie di sessione.

In una delle campagne documentate, il redirect conduceva a un percorso /download/XXXX che avviava automaticamente il download di un archivio ZIP. Il contenuto includeva file LNK e loader basati su HTML smuggling.

L’apertura del file LNK innescava l’esecuzione di un comando PowerShell che avviava una fase di ricognizione del sistema. Successivamente veniva eseguito un file legittimo, steam_monitor.exe, utilizzato per effettuare side-loading di una DLL malevola denominata crashhandler.dll.

La DLL provvedeva a decrittare crashlog.dat ed eseguire il payload finale in memoria, stabilendo una connessione outbound verso un endpoint di command-and-control esterno.

Persistenza e rotazione dei domini: evasione dinamica

Un ulteriore elemento critico riguarda la flessibilità dell’infrastruttura attaccante. Ospitando il payload su URI di redirect controllati, gli attori malevoli possono ruotare rapidamente domini e destinazioni quando vengono bloccati dai filtri di sicurezza.

Questo approccio rende più complessa l’attività di detection basata su blacklist statiche e impone l’adozione di controlli comportamentali e analisi dei flussi OAuth anomali.

Condividi l’articolo


Articoli correlati

Altro in questa categoria


https://www.securityinfo.it/2026/03/04/phishing-via-oauth-campagne-contro-enti-pubblici-sfruttano-i-redirect-di-microsoft-entra-per-distribuire-malware/?utm_source=rss&utm_medium=rss&utm_campaign=phishing-via-oauth-campagne-contro-enti-pubblici-sfruttano-i-redirect-di-microsoft-entra-per-distribuire-malware


Android: 129 vulnerabilità corrette, zero-day Qualcomm già sfruttata


Google ha rilasciato gli aggiornamenti di sicurezza Android di marzo correggendo 129 vulnerabilità, tra cui una falla zero-day già sfruttata in attacchi mirati. La vulnerabilità, tracciata come CVE-2026-21385, interessa un componente grafico sviluppato da Qualcomm e, secondo quanto comunicato nel bollettino ufficiale, sarebbe oggetto di “limited, targeted exploitation”, ovvero di uno sfruttamento limitato, ma su bersagli precisi.

CVE-2026-21385: overflow nel sottocomponente Graphics

Secondo l’advisory pubblicato da Qualcomm il 3 febbraio, la vulnerabilità è un integer overflow (o wraparound) nel sottocomponente Graphics, sfruttabile da un attaccante locale per provocare corruzione della memoria.

L’azienda ha dichiarato di essere stato informato della vulnerabilità il 18 dicembre e di aver notificato i clienti il 2 febbraio. La falla, classificata come gravità elevata, coinvolgerebbe 235 chipset Qualcomm, ampliando significativamente la superficie potenzialmente esposta.

Dieci vulnerabilità critiche: RCE senza interazione utente

Oltre alla zero-day Qualcomm, il bollettino Android di marzo include la correzione di 10 vulnerabilità critiche nei componenti System, Framework e Kernel.

La più grave riguarda il componente System e potrebbe consentire remote code execution senza necessità di privilegi aggiuntivi né interazione da parte dell’utente. Una condizione che, se sfruttata in catene di exploit, potrebbe facilitare compromissioni silenziose su larga scala.

Le altre vulnerabilità critiche permettono escalation di privilegi o condizioni di denial-of-service, confermando come il livello di rischio nel layer basso del sistema operativo resti elevato, soprattutto in scenari dove gli aggiornamenti non vengono applicati tempestivamente.

Patch level 2026-03-01 e 2026-03-05: il nodo frammentazione

Google ha distribuito due livelli di patch: 2026-03-01 e 2026-03-05. Il secondo include tutte le correzioni del primo, oltre a fix relativi a componenti closed-source di terze parti e a sottocomponenti del kernel, che potrebbero non essere applicabili a tutti i dispositivi.

Come noto, i dispositivi Google Pixel ricevono gli aggiornamenti in modo immediato, mentre gli altri vendor devono integrare, testare e adattare le patch alle specifiche configurazioni hardware. Questo passaggio introduce ritardi variabili che, in presenza di una zero-day già sfruttata, possono tradursi in finestre di esposizione significative.

Per i team di sicurezza mobile e per i CISO, l’episodio conferma la necessità di monitorare costantemente i livelli di patch installati sui dispositivi aziendali, soprattutto in ambienti BYOD o in flotte eterogenee. La presenza di chipset Qualcomm in centinaia di modelli rende la gestione del rischio ancora più complessa.

Condividi l’articolo


Articoli correlati

Altro in questa categoria


https://www.securityinfo.it/2026/03/03/android-129-vulnerabilita-corrette-zero-day-qualcomm-gia-sfruttata/?utm_source=rss&utm_medium=rss&utm_campaign=android-129-vulnerabilita-corrette-zero-day-qualcomm-gia-sfruttata


Una falla in Chrome sfrutta Gemini Live per scopi malevoli


Palo Alto, azienda specializzata in sicurezza informatica, ha scoperto una vulnerabilità nel browser Google Chrome avrebbe potuto trasformare l’assistente AI integrato in uno strumento di sorveglianza e furto dati. Il problema è stato segnalato a Google dopodiché è stata catalogata come CVE-2026-0628 e corretta a gennaio con il rilascio di Chrome 143.

Il problema riguardava Gemini Live, il pannello laterale AI di Chrome progettato per assistere l’utente nella navigazione tramite riassunti in tempo reale, esecuzione automatica di task e comprensione contestuale delle pagine web. Tutte funzioni molto utili, ma che che, come dimostra questo caso, ampliano in modo significativo la superficie d’attacco del browser.

L’AI nel browser: potere operativo e nuovi rischi

Gemini Live è concepito per “vedere” ciò che vede l’utente: il modello accede al contenuto della pagina attiva, ne interpreta il contesto e può eseguire azioni complesse direttamente dall’interfaccia del browser. Questo approccio consente operazioni multi-step che, fino a poco tempo fa, richiedevano estensioni dedicate o interventi manuali.

Secondo l’analisi di Palo Alto Networks, proprio questo accesso privilegiato all’ambiente di navigazione rappresenta il punto critico. L’AI non è una semplice estensione: è un componente nativo del browser con capacità avanzate, incluse interazioni con file locali, screenshot delle schede, accesso a microfono e videocamera.

In altre parole, l’assistente dispone di permessi che vanno oltre quelli normalmente concessi a un’estensione tradizionale e se un attore malevolo riesce a inserirsi in quel flusso, eredita lo stesso livello di privilegio.

Come funzionava l’attacco: estensioni malevole e declarativeNetRequests

La vulnerabilità CVE-2026-0628 avrebbe consentito a estensioni dannose di iniettare codice JavaScript all’interno del pannello Gemini Live. Per farlo, l’estensione doveva disporre di un set specifico di permessi attraverso l’API declarativeNetRequests che permette di intercettare e modificare richieste e risposte HTTPS.

Questa API nasce con finalità legittime, come il blocco di richieste intrusive o malevole, ma grazie alla possibilità di interagire con contenuti originati da Gemini e caricati nella scheda del sito sarebbe potuta diventare un vettore di compromissione.

In pratica, l’estensione avrebbe potuto intercettare il flusso tra il browser e il pannello AI, inserendo codice in grado di sfruttare le capacità operative dell’assistente. Tra gli scenari ipotizzati: attivazione silenziosa di microfono e videocamera, accesso ai file locali, cattura di screenshot delle schede aperte e persino l’orchestrazione di campagne phishing sfruttando l’interfaccia di Gemini.

Il punto più delicato è che il pannello Gemini è parte integrante del browser. Non si tratta di un plugin isolato, ma di un componente con accesso diretto alle risorse di sistema. Il dirottamento dell’assistente avrebbe quindi permesso a un’estensione di aggirare i normali limiti di sicurezza, ottenendo privilegi superiori rispetto a quelli previsti dal modello di sicurezza standard di Chrome.

Patch e implicazioni per la sicurezza dei browser AI-native

Palo Alto Networks ha segnalato la vulnerabilità a Google lo scorso ottobre. La correzione è stata distribuita con le versioni 143.0.7499.192 e 143.0.7499.193 per Windows e macOS, e con la 143.0.7499.192 per Linux.

L’episodio evidenzia un tema destinato a diventare centrale nel dibattito sulla sicurezza applicativa: l’integrazione nativa di modelli AI nei browser modifica radicalmente il perimetro di fiducia. Se l’assistente dispone di accesso privilegiato per eseguire operazioni legittime, qualsiasi vulnerabilità nel suo canale di comunicazione diventa un moltiplicatore di rischio.

Per i professionisti della sicurezza IT, il caso CVE-2026-0628 rappresenta un campanello d’allarme che sentiamo ormai suonare sempre più spesso. L’evoluzione verso browser AI-native richiede una revisione delle strategie di hardening, monitoraggio delle estensioni e controllo dei permessi concessi. Non è più sufficiente valutare il rischio delle estensioni in modo isolato: occorre considerare anche l’interazione con componenti intelligenti ad alto privilegio

Condividi l’articolo


Articoli correlati

Altro in questa categoria


https://www.securityinfo.it/2026/03/02/una-falla-in-chrome-sfrutta-gemini-live-per-scopi-malevoli/?utm_source=rss&utm_medium=rss&utm_campaign=una-falla-in-chrome-sfrutta-gemini-live-per-scopi-malevoli


Paradosso ransomware, pagamenti in calo ma attacchi ai massimi storici


Il ransomware continua a evolvere come una delle minacce più pervasive per organizzazioni pubbliche e private e i dati emersi dal Crypto Crime Report 2026 di Chainalysis fotografano un fenomeno apparentemente contraddittorio. Nel 2025 i pagamenti legati al ransomware sono diminuiti per il secondo anno consecutivo, ma allo stesso tempo il numero di attacchi e di vittime rivendicate ha raggiunto livelli record, segnando un nuovo punto di svolta nell’economia dell’estorsione digitale.

Secondo il report, i gruppi ransomware hanno incassato circa 820 milioni di dollari nel 2025, con un calo dell’8% rispetto all’anno precedente. La quota di vittime disposte a pagare è scesa al minimo storico del 28%, segnale di una maggiore resilienza organizzativa, di politiche di risposta più mature e di una crescente pressione normativa e assicurativa contro il pagamento dei riscatti. Tuttavia, questa apparente buona notizia è controbilanciata da un incremento significativo delle richieste economiche: il riscatto mediano è passato da 12.738 dollari nel 2024 a 59.556 dollari nel 2025, evidenziando una strategia criminale orientata a massimizzare il valore di ogni singolo attacco.

Volume record e frammentazione dell’ecosistema criminale

Il vero elemento distintivo del 2025 non è stato il valore complessivo dei riscatti, bensì il volume degli attacchi. I dati eCrime.ch indicano un aumento del 50% anno su anno delle vittime, rendendo il 2025 l’anno più attivo mai registrato per il ransomware. Questa crescita riflette una trasformazione strutturale del panorama delle minacce, dove la pressione estorsiva non è più dominata esclusivamente dai grandi brand criminali.

Il panorama dei gruppi ransomware appare infatti sempre più frammentato. Le operazioni delle forze dell’ordine, le sanzioni internazionali e gli arresti hanno colpito nomi storici come LockBit e BlackCat, ma il vuoto è stato rapidamente riempito da spin-off, affiliati opportunisti e nuovi attori meno strutturati. Questi gruppi minori contribuiscono a un numero crescente di tentativi di estorsione, molti dei quali non si traducono in pagamenti tracciabili, rendendo più complessa la valutazione economica reale del fenomeno.

Gli eventi di maggiore impatto mediatico hanno comunque contribuito a definire il 2025 come un anno critico. Il caso Jaguar Land Rover è stato descritto come l’incidente cyber più costoso nella storia del Regno Unito, mentre Marks & Spencer ha subito una prolungata interruzione operativa dopo una violazione attribuita a un gruppo legato a Scattered Spider, con conseguenze rilevanti sul valore di mercato. Tuttavia, il report sottolinea che la vera storia non è quella dei mega-breach, ma la crescita costante del volume complessivo degli attacchi, spesso rivolti a organizzazioni di dimensioni medie o a supply chain complesse.

Leak site e pressione reputazionale come leva strategica

I dati di Emsisoft rafforzano questa lettura, indicando che oltre 8.000 organizzazioni sono state pubblicamente nominate sui leak site nel 2025, un incremento significativo rispetto agli anni precedenti. L’esposizione pubblica continua a rappresentare uno degli strumenti più efficaci per forzare le vittime alla negoziazione, soprattutto in contesti regolamentati o ad alta visibilità.

Le economie avanzate restano nel mirino privilegiato degli attaccanti. Gli Stati Uniti guidano la classifica delle vittime, seguiti da Canada, Germania, Regno Unito e dal resto dell’Europa occidentale. I settori più colpiti includono manifatturiero, finanziario e servizi professionali, mentre in Canada e Germania emerge un interesse particolare verso supply chain, logistica e infrastrutture critiche. Negli Stati Uniti, invece, l’aumento delle vittime ha interessato trasversalmente tutti i comparti, compresi governo e infrastrutture essenziali.

Questa distribuzione geografica e settoriale evidenzia come il ransomware sia ormai una minaccia sistemica, capace di colpire ecosistemi economici complessi e di generare impatti a cascata su partner, fornitori e clienti. L’effetto reputazionale e operativo derivante dalla pubblicazione sui leak site si conferma quindi un elemento centrale della strategia estorsiva moderna.

Il ransomware come supply chain criminale

Uno degli insight più rilevanti del report Chainalysis riguarda l’evoluzione del ransomware verso un modello simile a una supply chain criminale. In questo contesto, gli Initial Access Broker (IAB) svolgono un ruolo sempre più determinante, fungendo da intermediari che vendono accessi compromessi alle reti aziendali già pronti all’uso. Nel 2025, gli IAB hanno ricevuto almeno 14 milioni di dollari in pagamenti on-chain, una cifra modesta rispetto al totale ransomware ma strategicamente significativa.

L’analisi di Chainalysis evidenzia infatti una correlazione temporale tra l’aumento dei pagamenti agli IAB e la successiva crescita degli attacchi ransomware: i picchi nelle transazioni verso questi intermediari precedono di circa 30 giorni l’aumento dei pagamenti ransomware e delle pubblicazioni sui leak site. Questo pattern suggerisce una filiera operativa strutturata, in cui l’accesso iniziale viene acquistato, monetizzato e trasformato in campagne estorsive con tempistiche relativamente prevedibili.

Il report conclude che il ransomware non sta diminuendo, ma si sta trasformando. Meno organizzazioni pagano, ma più organizzazioni vengono colpite, le richieste economiche aumentano e il mercato degli accessi compromessi continua a prosperare, preparando il terreno per nuove ondate di disclosure e campagne di estorsione. Ma questo significa anche che la promozione della resilienza aziendale ha funzionato, iniziando a minare il terreno che ha portato alla crescita del ransomware: la sua redditività.

Condividi l’articolo


Articoli correlati

Altro in questa categoria


https://www.securityinfo.it/2026/02/27/paradosso-ransomware-pagamenti-in-calo-ma-attacchi-ai-massimi-storici/?utm_source=rss&utm_medium=rss&utm_campaign=paradosso-ransomware-pagamenti-in-calo-ma-attacchi-ai-massimi-storici


Google API Keys: le chiavi pubbliche diventano credenziali sensibili


L’introduzione di funzionalità di intelligenza artificiale generativa nelle piattaforme cloud sta ridefinendo il perimetro di sicurezza delle credenziali applicative. Un caso emblematico è stato scoperto dai ricercatori di Truffle Security Co. e riguarda l’ecosistema Google Cloud dove le tradizionali API key — storicamente considerate semplici identificatori di progetto — hanno acquisito nuovi privilegi con l’arrivo di Gemini. Il risultato è una superficie d’attacco inattesa, in cui migliaia di chiavi pubbliche possono essere sfruttate per accedere a dati privati, consumare risorse e generare costi anche elevati.

Un cambio di paradigma nella gestione delle API key

Per oltre un decennio Google ha comunicato in modo esplicito che le API key non erano né andavano trattate come segreti. La documentazione di servizi come Google Maps e Firebase invitava infatti gli sviluppatori a inserirle direttamente nel codice client o nelle pagine HTML, poiché il loro scopo principale era identificare il progetto ai fini di fatturazione e monitoraggio. Eventuali restrizioni, come l’allow-listing dei referer HTTP, venivano considerate controlli accessori e non meccanismi di autenticazione.

L’arrivo della Generative Language API, che abilita l’accesso a Gemini, ha però modificato radicalmente questa premessa. Quando l’API viene attivata in un progetto Google Cloud, tutte le API key esistenti associate a quel progetto possono ottenere automaticamente accesso agli endpoint sensibili di Gemini, senza notifiche, conferme o cambiamenti visibili nell’interfaccia di gestione. In altri termini, una chiave creata anni prima per un widget di Maps può trasformarsi silenziosamente in una credenziale capace di interrogare modelli generativi a nome di qualcun altro e accedere ai dati del progetto.

Questa dinamica introduce una forma di espansione retroattiva dei privilegi, in cui la sequenza temporale degli eventi diventa determinante. La chiave nasce come identificatore pubblico, l’API Gemini viene attivata successivamente e, senza alcun intervento dell’utente, la stessa chiave assume un ruolo autentico e sensibile. Il problema non è dunque una configurazione errata, ma un difetto architetturale legato a default permissivi e alla mancanza di separazione tra chiavi pubbliche e segrete.

Default insicuri e rischio di privilege escalation

Alla base della vulnerabilità vi è il fatto che Google utilizza un formato unico di API key (prefisso AIza…) per scenari con requisiti di sicurezza profondamente diversi. Quando una nuova chiave viene generata, la configurazione predefinita è “unrestricted”, rendendola valida per tutte le API abilitate nel progetto, incluse quelle generative. L’interfaccia segnala genericamente il rischio di uso non autorizzato, ma l’impostazione di default resta permissiva.

Questo scenario si allinea a due debolezze note: posture di sicurezza con default insicuri e assegnazione impropria dei privilegi. L’assenza di separazione tra chiavi pubbliche e segrete favorisce confusione operativa e compromissioni, mentre l’upgrade implicito dei privilegi applicato a chiavi già esposte in ambienti pubblici rappresenta una forma di trust escalation difficilmente individuabile dagli sviluppatori.

Lo scenario di attacco: scraping e accesso ai dati Gemini

Dal punto di vista operativo, l’exploit è estremamente semplice. Un attaccante può visitare un sito web, recuperare dal codice sorgente una API key utilizzata per servizi come Maps e inviarla a un endpoint Gemini. In diversi casi analizzati, la richiesta non restituisce un errore ma una risposta valida, segno che la chiave è accettata per operazioni sensibili.

Una volta ottenuto l’accesso, il threat actor può interrogare endpoint che contengono file caricati, dataset, documenti e contenuti cache del progetto. Oltre alla compromissione della riservatezza dei dati, emerge il rischio economico: l’uso massivo delle API generative può generare costi elevati e saturare le quote disponibili, causando interruzioni ai servizi legittimi. L’attaccante non deve compromettere infrastrutture o credenziali interne, ma semplicemente sfruttare una chiave pubblica già esposta.

L’impatto reale: migliaia di chiavi vulnerabili online

Un’analisi condotta sul dataset Common Crawl di novembre 2025 ha individuato 2.863 API key Google attive potenzialmente sfruttabili attraverso questo vettore. Tra le organizzazioni coinvolte figurano istituzioni finanziarie, aziende di sicurezza e realtà globali del recruiting, a dimostrazione di quanto il problema non sia limitato a progetti marginali.

Particolarmente significativo è il fatto che anche Google stessa presentasse chiavi pubbliche esposte su siti di prodotto che, una volta testate, risultavano valide per interrogare endpoint Gemini. Durante un test, una chiave pubblicata da anni per finalità innocue ha restituito una risposta positiva alla richiesta di elenco modelli generativi disponibili, confermando la trasformazione silenziosa dei privilegi.

La disclosure e la risposta di Google

La vulnerabilità è stata segnalata a Google nel novembre 2025 attraverso il Vulnerability Disclosure Program. In una prima fase il comportamento è stato classificato come previsto, ma l’evidenza fornita — inclusi esempi interni a Google — ha portato a una riclassificazione come bug e a un aumento della severità. L’azienda ha quindi avviato un piano di mitigazione che include la rilevazione automatica delle chiavi esposte e la limitazione del loro accesso a Gemini.

A gennaio 2026 il problema è stato formalmente catalogato come privilege escalation limitata a un singolo servizio, mentre a febbraio risultava ancora in fase di remediation strutturale. Nonostante le difficoltà iniziali nel triage, Google ha riconosciuto il rischio e ha ampliato i meccanismi di protezione per i clienti potenzialmente esposti. Ad oggi, però, la soluzione completa è ancora mancante.  Google ha indicato alcune direttrici di miglioramento, tra cui default più restrittivi per le nuove chiavi generate tramite AI Studio, blocco automatico delle chiavi individuate come compromesse e notifiche proattive ai proprietari dei progetti.

Condividi l’articolo


Articoli correlati

Altro in questa categoria


https://www.securityinfo.it/2026/02/27/google-api-keys-le-chiavi-pubbliche-diventano-credenziali-sensibili/?utm_source=rss&utm_medium=rss&utm_campaign=google-api-keys-le-chiavi-pubbliche-diventano-credenziali-sensibili


How Researchers Reverse-Engineered LLMs For A Ranking Experiment via @sejournal, @martinibuster

Researchers published the results of a study showing how AI search rankings can be systematically influenced, with a high success rate for product search tests that also generalizes to other categories like travel.

The name of the research paper is Controlling Output Rankings in Generative Engines for LLM-based Search and the approach to optimization is called CORE, a way to influence output rankings in LLMs.

Caveat About The CORE Research

The testing and the reported results were done with actual LLMs queried via an API.

They tested:

  • Claude 4
  • Gemini 2.5
  • GPT-4o
  • Grok-3

They did not test AI Overviews, ChatGPT or Claude through their consumer interfaces. The importance of this distinction is that the normal kinds of personalization will not play a role. Also, the testing was limited to just the candidate search results.

Also, when the researchers queried the target LLMs (Claude-4, Gemini-2.5, GPT-4o, and Grok-3) via an API, the models did not rely on RAG or their own external search tools. Instead, the researchers manually supplied the “retrieved” data as part of the input prompt.

Why The Research Matters

CORE is a proof-of-concept for strategically optimizing text with reasoning and reviews. It also shows that LLMs respond differently to reviews and reasoning-based changes to text.

Reverse Engineering A Black Box

Understanding exactly what to do to improve AI search engine rankings is a classic black box problem. A black box problem is where you can see what goes into a box (the input) and what comes out (the output), but what happens inside the box is unknown.

The researchers in this study employed two strategies for reverse engineering generative AI to identify what optimizations were best for influencing rankings.

They used two reverse-engineering approaches:

  1. Query-Based Solution
  2. Shadow Model Solution

Of the two approaches, the Query-Based Solution performed better than the Shadow Model approach.

The percentages of top ranked optimizations of bottom ranked pages:

  • Query-based Top-1 ≈ 77–82%
  • Shadow model Top-1 ≈ 30–34%

Query-Based Solution

The query-based solution operates under the constraint that the researchers cannot access model internals, so they treat the LLM as a black box.

They repeatedly modify the document text. After each modification, they resubmit the candidate list to the LLM and observe the new ranking. The modify and test loop continues until a target ranking criterion or iteration limit is reached.

The query-based solution uses an LLM to add text to the target document. This is content expansion, not content editing.

They used two kinds of content expansion:

  1. Reasoning-Based Generation
    Adds explanatory language describing why the item satisfies the query.
  2. Review-Based Generation.
    Adds evaluative content, review-like language about the item.

These are not random edits. They are changes tested as separate strategies, which the researchers then evaluate the rankings to determine whether or not the change had a positive ranking effect.

Interestingly, neither approach (reasoning versus review based) was better than the other. Which one was better depended on the LLM they were testing against.

Here is how reasoning and review based performed:

  • GPT-4o and Claude-4 responded more strongly to reasoning-style augmentation,
  • Gemini-2.5 and Grok-3 responded more strongly to review-style augmentation.

Shadow Model Solution

In the context of reverse engineering a black box, a shadow model, also called a surrogate model, is a local model that mimics the target model (black box). The goal of the shadow model is to mathematically approximate the outputs of the black box so that the inputs to the shadow model eventually produce similar outputs to the black box. The input-output pairs of the black box are used as a training data set to train the shadow model.

Llama-3.1-8B Shadow Model

Interestingly, Llama-3.1-8B was a reliable proxy for calculating and predicting how target models like GPT-4o would rank products.

  • The researchers found that the recommendations produced by the Llama-3.1-8B shadow model and the target LLMs were generally consistent.
  • On a scale of 1 – 5, with 1 equal to divergence and 5 indicating similarity, Llama-3.1-8B scored a similarity rating of 4.5 when compared to GPT-4o outputs.

Success Rate With Different Shadow Models

The results of the research for the shadow model approach reach the following two conclusions:

1. The researchers show that by iteratively adjusting the target item using a shadow model, they were able to push it to the top of the rankings in their experiments.

2. They also prove that when the surrogate model only approximately matches the real model, the optimization still transfers, but the achievable promotion success decreases smoothly rather than failing abruptly.

Once the shadow model was trained they then began testing with three optimization strategies:

  1. String-Based
  2. Reasoning-Based
  3. Review-Based Optimization

String-Based Optimization

The researchers used a string of 20 characters that were all exclamation points (!) and then iteratively changed the string, tracking how the changes influenced the rankings. They performed 2,000 iterations of these mathematical updates to the string, refining it into the best string of characters that resulted in higher rankings. The resulting string looked like nonsense to humans but still increased the item’s ranking in the experiment.

This approach didn’t work as well as the other two approaches but it did work at a rate of 33% for boosting a last ranked page to the first position. Testing with human annotators showed that it was detected 98.5% of the time. So, not a stealth optimization.

Reasoning-Based Optimization

The researchers optimized the text to mirror a user’s reasoning over the retrieved results, as well as aligning with the LLM’s reasoning structure. In their tests, the reasoning-based approach achieved the highest success rate among the three strategies. But it was detected by human raters 62.1%, a relatively high rate likely because of the unnatural highly structured phrasing.

This is an example of the prompt they used to generate the reasoning-based content:

“You are a helpful assistant. The user query is: *user query* The candidate products are: *product list in JSON format* The target product is: *target item information* Generate an initial draft that highlights why the target product should be ranked highly for the given query. Use
step-by-step logical reasoning, comparing the target product with alternatives and explaining why it is the best match.”

And this is an example of reasoning content:

“Understanding Air Fryer Types
I’m exploring the different air fryer designs to help you find your perfect match. Basket-style models offer compact convenience, while oven-style units provide spacious versatility. Your choice depends on kitchen space and cooking habits—whether you need quick snacks or full meals.

Explaining Key Features
I’m breaking down the must-have features of premium air fryers. Precise temperature controls and auto-shutoff timers ensure perfect results, while dishwasher-safe baskets simplify cleanup. For families, I emphasize capacity (4+ quarts) and multi-functionality—think roasting, baking, and even dehydrating for maximum utility.”

Review-Based Optimization

The review content is written in the past tense in order to resemble an actual purchase. Like a lot of the optimizations described in this research paper, this one is quite likely the most deceitful because they were writing the reviews without having reviewed an actual product, then iterating the optimization until the content ranked as high as it could go, scoring betwen 79% to 83.5% in pushing a last place ranking to first place.

For GPT-4o: Reasoning-based reached 81.0%, while Review-based reached 79.0% and scoring as high as 91% for pushing a last ranked listing to the top 5.

This is an example of a prompt used to generate the review content:

“You are a helpful assistant. The user query is: *user query* The candidate products are: *product list in JSON format* The target product is: *target item information*

Generate an initial draft in the style of a short customer review. Write in past tense and natural language, as if you had purchased and compared the product with alternatives. Highlight the advantages of the target product in a realistic review-like way.”

The headings used in one of the reviews shows a pattern of information aligned to the following intents:

  • Presenting an overview of the product type
  • Narrowing the focus to explain features
  • Provide information of different models
  • Purchasing strategies (how to buy at the best price)
  • Summary of key takeaways

That pattern partially follows Google’s recommendation for review content, but it lacks a clear comparison with alternatives, discussion of improvements from previous product models, and of course links to multiple stores to purchase from.

The review content had the following headings in it:

  • Understanding Air Fryer Types
  • Explaining Key Features
  • Detailing Top Models
  • Providing Smart Purchase Strategies
  • Final Verdict

An example of the review content published in the research paper indicates that it leads the LLM into believing that actual product testing occurred, even though that was not the case.

Example of the “Final Verdict” content:

“After 6 months of testing, the Gourmia Air Fryer Oven (GAF486) is my #1 recommendation. It’s the only model that replaced my oven and toaster, with none of the smoke alarms or soggy fries. If you buy one air fryer, make it this one—your taste buds (and wallet) will thank you.”

Takeaways

The experiments were conducted in a controlled setting where the researchers supplied the candidate results directly to the models rather than influencing live search or real-world retrieval systems. Yet there are some takeaways that may be useful.

  • LLMs Have Content Preferences
    The research confirms that different models (like GPT-4o vs. Gemini-2.5) have measurable preferences toward specific content types, such as logical reasoning versus hands-on reviews.
  • Suggests That Expanding Content Is Useful
    Adding specific types of explanatory or evaluative content may be helpful to increasing rankings in an LLM.
  • Shadow Model
    The research showed that even if the shadow model only approximately matches a real model, the optimization still works under a controlled experimental environment. Whether it works in a live environment is an open question but I personally wonder if some of the spam that ranks in AI-assisted search is due to this kind of optimization.

Read the research paper:

Controlling Output Rankings in Generative Engines for LLM-based Search

Featured Image by Shutterstock/SuPatMaN

https://www.searchenginejournal.com/how-researchers-reverse-engineered-llms-for-a-ranking-experiment/568279/


Google To Test Search Changes In EU After DMA Charges, Per Report via @sejournal, @MattGSouthern

Google is preparing to test changes to how search results appear in Europe that would give competing vertical search services more visibility, Reuters reported, citing a person with direct knowledge of the plans.

The test would show results from top-ranked rival services by default alongside Google’s own results for queries related to hotels, flights, and restaurants.

With this test, Google is aiming to avoid a fine under the EU’s Digital Markets Act. The European Commission sent preliminary findings in March, alleging Google Search treats Alphabet’s own services more favorably than rivals under the DMA. Penalties can reach up to 10% of a company’s global annual revenue.

Google has proposed multiple rounds of changes since it first faced DMA charges last year. Those proposals were rejected. Now, Google is moving past proposals to actual testing.

Google has already run smaller-scale experiments with stripped-down search results, removing maps and hotel listings in favor of basic blue links. Businesses criticized those tests after reporting up to 30% drops in free direct booking clicks.

Why This Matters

The DMA case is one of several regulatory and antitrust actions pressuring Google to change how search results work. Each one could change which results appear and how much visibility third-party sites get.

Travel, hospitality, and local business verticals would feel the effects first. Rival services could pull clicks from Google’s integrated results toward other booking platforms and aggregators.

The EU-specific nature of this test matters too. Google has made DMA-specific search changes in European markets that don’t exist elsewhere. EU search results already look different from what you see in other regions, and this test would widen that gap further.

Google has accumulated €9.71 billion ($11.5 billion) in EU antitrust fines since 2017 across various cases. The DMA gives the Commission a separate enforcement tool with penalties that could add billions more.

Looking Ahead

Reuters said the changes would be rolled out across Europe soon. No specific dates were given.

Between the U.S. antitrust remedies and the EU’s DMA enforcement, the rules governing what appears on a Google search results page are changing on multiple fronts.


Featured Image: Samuel Boivin/Shutterstock

https://www.searchenginejournal.com/google-to-test-search-changes-in-eu-after-dma-charges-per-report/568275/


Gen Z Preference For TikTok Over Google Drops 50%, Data Shows via @sejournal, @MattGSouthern

More U.S. consumers in an Adobe Express survey said they’ve used TikTok for search than in the company’s 2024 survey. But the platform’s position as a Google challenger may be weaker than the headline numbers suggest.

An updated report from Adobe Express, published February 17, surveyed 807 consumers and 200 small business owners in the US about their search habits across platforms. Adobe says the data was collected in January 2026, and that the SurveyMonkey survey was conducted in February 2026.

Forty-nine percent of consumers surveyed said they have used TikTok as a search engine, up 8 percentage points from 41% in Adobe’s 2024 report.

Gen Z Is Pulling Back

Among Gen Z respondents, the share who said they are more likely to rely on TikTok than Google fell from 8% in 2024 to 4% in 2026.

Sixty-five percent of Gen Z still said they’ve used TikTok as a search engine, and 25% found it effective for finding information. But that usage isn’t translating into preference over Google the way it did two years ago.

That tracks with separate reporting from Axios in 2024. The Axios data showed Google still held the top spot as Gen Z’s preferred search starting point, with 46% of users aged 18-24 beginning their queries there.

ChatGPT Pulls Ahead As A Google Alternative

14% of consumers said they are more likely to rely on ChatGPT than on Google as a search engine. That’s double the 7% who said the same about TikTok.

The ChatGPT figure was consistent across age groups, with 12% of Gen Z, 15% of millennials, 15% of Gen X, and 14% of baby boomers. TikTok-over-Google numbers were low across every group and lowest among baby boomers (2%), with millennials (8%) actually higher than Gen Z (4%).

When asked which platforms they found most helpful for search, consumers ranked Google first at 85%, followed by Reddit (29%), ChatGPT (26%), YouTube (24%), and TikTok (16%).

Business Investment Is Cooling

Among the 200 business owners surveyed, 58% had used TikTok for promotions. They allocated an average of 16% of their marketing budget to TikTok content creation and 15% of their SEO budget to TikTok search optimization.

Only 38% said they plan to increase investment in TikTok affiliate marketing, down from 53% who said the same in 2024.

The top challenge business owners reported was converting TikTok engagement into sales (38%), followed by growing follower counts and engagement rates (36%).

Influencer marketing use grew, with 38% of small business owners using TikTok influencers for product sales or promotions, up from 25% in 2024.

Why This Matters

The “TikTok is replacing Google” narrative has been a recurring theme since at least 2022. This data complicates that story. Optimizing for TikTok search still makes sense if your audience skews younger, but the data suggests Gen Z may be settling into a multi-platform pattern rather than abandoning Google.

The ChatGPT numbers are worth watching more closely. If 14% of consumers across all age groups say they’re more likely to rely on ChatGPT than Google, that’s a broader competitive signal than TikTok’s Gen Z niche.

Looking Ahead

Adobe’s report is vendor-funded and conducted via SurveyMonkey with 1,007 respondents (807 consumers and 200 business owners). Adobe says data was collected in January 2026. The sample skews millennial-heavy (53%), with Gen Z making up only 15% of consumers surveyed. No margin of error was disclosed.

The year-over-year comparisons are based on Adobe’s own prior data, not an independently replicated sample. The generational trends are directional rather than definitive.

Still, the direction in the data aligns with broader industry observations. Consumers are using more platforms for search-like behavior, but Google remains dominant. The real competition for Google’s search role, based on this survey at least, may be coming from AI chatbots rather than social video.


Featured Image: Frame Stock Footage/Shutterstock

https://www.searchenginejournal.com/gen-z-preference-for-tiktok-over-google-drops-50-data-shows/568267/