Google May Treat Search Box Pages As A Site Quality Issue via @sejournal, @martinibuster

Google’s John Mueller and Martin Splitt discussed what happens when spammers abuse website search functions to create thousands of spammy search pages. They said that Google begins to treat those pages as hacked.

Website Search Spam And Quality Issues

Virtually every website has a search function, and something that’s not clearly understood is that using the search bar generates a search results page that contains the search query. What’s surprising is that it’s normal behavior for these web pages to generate a URL that can be used to access that search, creating a situation where a spammer can use the search bar to generate thousands of web pages containing mentions of a spammy brand, the URL, and spam-related keywords.

Google’s Mueller said that website search spam can become a quality issue if the spam pages can be indexed or are indexable. Mueller used the example of entering text into a search box to generate a web page that contains that spammy text, which is something that can happen.


Mueller says search spam can become a quality issue:

“There is one place where you could run into quality issues though with search results pages. Namely, if you let people search for things that are totally irrelevant to your website and your search results page includes those terms on those search results page and is indexable.

…And it’s not so much that someone has hacked your website to do this because your website is doing that freely and basically saying like, oh, you search for photos, here’s a photo. But because it’s accessible for any search term that comes up, it’s suddenly a liability. It’s more like a vector for other people to spam.”

That last bit about a search box becoming a vector for spamming is correct, if the web page allows those auto-generated pages to be indexed.

Google May Flag Internal Search Pages As Hacked

The other useful information that Mueller and Splitt shared is that they flag these kinds of spammed pages as if they are hacked, explaining that these kinds of pages can show up in Google’s search results.

Mueller explained:

“And we’ve seen that happen that people do that at scale. They will try to recognize common CMSs that don’t have their search results pages blocked and go off and link to thousands of sites with millions of pages, all with maybe some adult terms and a phone number or pharmaceuticals and a phone number or something else and a telegram address or some other kind of contact mechanism where the goal is not so much that people go to your site and kind of see your photos, but rather that in the search results they’ll see for these pharmaceuticals call this number.

And sometimes that does show up for these kind of queries. And when we see that happen, we might flag that as hacked. So in Search Console, you might see that as something that is flagged as hacked.”

Google Can Catch Spammed Search Result Pages Algorithmically

Mueller also explained that Google can algorithmically catch these kinds of pages and block them from showing up in search results. From the site owner’s side, this can feel like a win because Google handled it. Mueller cautions against assuming that the problem is taken care of.

How To Prevent Search Box Spam

Google’s Mueller and Splitt recommended two approaches for preventing search spam from becoming an issue:

  1. Prevent crawling
  2. Prevent indexing

Prevent Crawling

The first recommendation is to use a robots.txt to prevent Google and other search engines from crawling the auto-generated search box web pages.

Mueller and Splitt list four reasons to block indexing with robots.txt:

  1. Google doesn’t need to crawl search pages.
  2. It prevents infinite crawling.
  3. It reduces server load.
  4. It prevents crawl budget waste.

Regarding infinite crawling, Martin Splitt said that some implementations of search boxes can turn into an infinite “crawl space” where the search box keeps autogenerating web pages through a “did you mean” feature that’s triggered in response to Google’s crawling those search pages.

Splitt explains:

“So we learned a bunch of stuff about search results on websites. So they can be infinite crawl spaces because we can basically generate pages upon pages of these and maybe we even link to like, did you mean, and then we create even more that the crawler sinks into. And it sounds like they’re relatively easy to get rid of with robots.txt and or no index.”

The infinite crawl space issue is also linked to increased server load and putting stress on the website crawl budget.

John Mueller explained how infinite crawling, server load, and crawl budget waste are linked:

“And all of that basically means we find, or we could potentially find an infinite number of pages on your site. And I know some people are like, wow, if I had an infinite number of pages in Google, then I would be king.

But having an infinite number of pages known to Google is not a good thing because Google will try to crawl all of those pages. And you can imagine what happens when we see, I don’t know, 100 million pages that are new from Martin Split will go off and try to crawl those. So that’s something where then suddenly crawl budget becomes a question and your server load and your server’s like, oh my gosh.”

Those are all the reasons why Mueller and Splitt recommend using robots.txt to prevent crawling of search box pages. More precisely, they say to use as broad and general a robots.txt rule as possible that can catch all variations of auto-generated search box pages.

Noindex Directive

Mueller and Splitt mention using the robots noindex directive but say that robots.txt is both easier and the cleanest way to handle search box web pages.

Watch Episode 113 of Search Off The Record

[embedded content]

Featured Image by Shutterstock/Tirachard Kumtanom

https://www.searchenginejournal.com/google-may-treat-search-box-pages-as-a-site-quality-issue/584419/


WP Engine Partners With BigCommerce To Scale WordPress Stores via @sejournal, @martinibuster

WP Engine announced Commerce Connect, a partnership with BigCommerce that enables ecommerce stores to scale to the next level without any downtime or changes to SEO. Most importantly, Commerce Connect is not about replacing platforms but enabling a safe way to modernize and grow to the next level while preserving everything about the brand.

What WP Engine announced is about helping ecommerce stores migrate their business without downtime while also preserving SEO. Scaling and modernizing an ecommerce store can negatively impact search visibility, but WP Engine’s Commerce Connect solves that problem by preserving all of the WordPress SEO, design, and user experience, making the choice to scale a business an easy one.

Heather Brunner, Chairwoman and CEO at WP Engine, explained:

“Growing ecommerce brands shouldn’t have to choose between the WordPress experience they’ve invested in and the commerce capabilities they need to scale, our partnership with BigCommerce gives brands the flexibility to scale confidently, adapt as their business evolves, and build for what’s next.”

That part about “what’s next” is important because of the profound changes introduced by AI shopping, which Commerce Connect can address.

The official announcement shares how Commerce Connect works:

“By connecting BigCommerce’s enterprise commerce platform with WP Engine’s platform, high-growth midmarket brands can scale their ecommerce capabilities while leveraging the power of WordPress.

Keeping content and commerce connected also helps brands maintain consistent product information across their digital experiences, creating richer shopping journeys while strengthening product visibility as AI-powered search and discovery continue to evolve.”

Interview With VP of Product At WP Engine

Search Engine Journal had the opportunity ask more questions about Commerce Connect, Keith Fafel, VP of Product at WP Engine provided answers that should help ecommerce stores understand how the new product can help them.

Not About Replacing Platforms

What are the signs that a WordPress-based ecommerce store may need to modernize and step up to a more capable ecommerce solution? What advantages does Commerce Connect provide merchants who find themselves outgrowing WooCommerce and are ready to grow their business to the next level?

Fafel explained that this is not about replacing WordPress:

“We see WP Engine Commerce Connect for BigCommerce as solving a broader growth and platform challenge, while helping growing brands scale with confidence. It’s not about replacing one platform with another. Each ecommerce solution takes a different approach to helping brands create a successful online store. We want to keep growing the WordPress ecosystem, and this solution provides optionality for scaling ecommerce sites.

WP Engine Commerce Connect for BigCommerce provides several advantages to merchants. The biggest advantage is that it enables them to preserve the WordPress experiences they’ve already built while adding the enterprise commerce capabilities needed to support larger catalogs, higher traffic, and continued growth.”

How Commerce Connect Preserves SEO

Many businesses invest heavily in content, SEO, and custom WordPress experiences before they outgrow their ecommerce platform. How does this partnership help them preserve those investments while continuing to grow?

WP Engine’s Keith Fafel responded:

“WP Engine Commerce Connect for BigCommerce preserves build investments by allowing brands to keep their existing WordPress content, themes, custom designs, URL structures, and SEO foundation. Instead of rebuilding the consumer-facing experience, brands can modernize the commerce platform underneath it, reducing disruption while gaining the scalability and capabilities needed for continued growth.”

A Safe Path To Scale Ecommerce And Keep What Works

How does this partnership change what’s possible for WordPress merchants that wasn’t practical before?

Fafel answered:

“This partnership gives growing WordPress brands a new path to scale. Instead of choosing between preserving the digital experiences they’ve built or adopting more advanced commerce capabilities, they can now do both. This means merchants can continue to scale while preserving the content, design, SEO, and customer experiences that drive their business. This solution provides WP Engine customers with a choice for how they operate and scale their ecommerce business, while keeping them in the WordPress ecosystem.”

That is an interesting answer because it underlines that Commerce Connect is not a replacement for WordPress, it’s a way to preserve all the things that work with the WordPress platform while also modernizing and scaling.

What Kinds Of Business Benefit From Commerce Connect?

I asked WP Engine’s Keith Fafel to tell us what kinds of businesses stand to benefit the most from WP Engine Commerce Connect for BigCommerce, and what are the characteristics of a brand that needs to modernize with Commerce Connect.

Fafel explained that high-growth brands that feel they’re reaching the limits of their current platform stand to benefit:

“WP Engine Commerce Connect for BigCommerce is designed for high-growth, mid-market brands generating <$1M in GMV that are reaching the next stage of their ecommerce journey. They typically have established WordPress websites with significant investments in content, design, and SEO, and are experiencing growing product catalogs, higher traffic, and more complex commerce needs.

Rather than rebuilding what already works, these businesses want a way to modernize their commerce capabilities while preserving the digital experiences that have helped drive their growth.”

What capabilities do businesses typically discover they need as they scale and how does BigCommerce provide that?

Fafel answered:

“As merchants grow, they typically need to support larger product catalogs, higher traffic volumes, more complex operations, and need greater flexibility to adapt as their business evolves. Through our partnership with BigCommerce, the platform gives brands an enterprise-ready commerce foundation that scales with those needs, while allowing them to preserve the WordPress experiences that already drive their business.”

Learn more about Commerce Connect here.

Featured Image by Shutterstock/Dilok Klaisataporn

https://www.searchenginejournal.com/wp-engine-bigcommerce-wordpress-stores/584343/


Google Opens Search Console Social Reporting To Everyone via @sejournal, @MattGSouthern

  • Platform properties are now open to everyone, three weeks after the rollout began.
  • Google published a guide on reading the Search data behind social and video posts.
  • Search Console now reports on content you publish off your own site.

Search Console platform properties are now open to everyone worldwide, and Google has published a guide to reading your social and video search data.

https://www.searchenginejournal.com/google-opens-search-console-social-reporting-to-everyone/584144/


Google May Be Penalizing AI-Generated Content As Thin Content via @sejournal, @martinibuster

A forum website published a post on Reddit expressing disbelief that Google issued a manual action for thin content, finding it hard to reconcile how Google could send so much traffic for nearly twenty years only to find fault with it now. Google is calling it a manual action for thin content, but SEOs believe it may be for AI-generated content.

Manual Action For Thin Content

According to the Reddit post, a forum received a manual action for thin content. The notification specifically pointed to over half a million posts in one specific category of the site, /threads/. They explained that it’s a partial manual action and that the penalization does not affect the rest of the site, just this one part of the website.

They explained:

“The message (WNC‑651700, ~17 July 2026) is: “Thin content with little or no added value.”
It’s a partial manual action, meaning a human reviewer looked at part of the site, judged it unworthy of ranking, and suppressed it pending a reconsideration request.

The Affects field names exactly one thing: the URL pattern windowsforum.com/threads/.
That’s 168,290 visible threads and over half a million posts, twenty years deep, suppressed together.

No example URLs were provided. Not one.”

Thin Content

Google has multiple definitions of thin content. One of them, thin affiliate content, is content published on affiliate sites that are word for word duplicates of what is found on the merchant websites.

Former Googler Matt Cutts has said that thin affiliate content lacks “original insight or research or analysis” or any other kind of content like original videos that “add value.”

Other forms of thin content:

  • Syndicated content
  • Article marketing content

Cutts has also explained that the opposite of thin content is content that site owners have written themselves, contains additional value, is unique, and leans in on the author’s actual expertise.

That last part may be critical for understanding why the Redditor’s forum received a thin content warning, but not in the context that the site owners were thinking of.

Why Is Actual Thin Content Not Penalized?

The part that confused the site owner is that there were two other sections of the website that were more clearly thin content, yet those web pages were not subject to a manual action. One section was a feed of syndicated headlines. The other section was an archived knowledge base. They said both sections have been inactive for three years, yet neither of them was called out for a manual action. It was the forum section of the site that received a manual action.

They wrote:

“The part that doesn’t reconcile

Two sections of the site are the obvious candidates for a thin‑content finding:

an old syndicated headline feed

an archived knowledge base

Together, that’s 11,927 threads with a mean age of about 12.5 years.

…This material has been crawled, indexed, and ranked continuously through Panda, Penguin, the September 2023 helpful content update, and through the community’s migration from its original domain… Fifteen years, two domains, every major ranking change Google has shipped and it never drew a manual action.”

Redditors expressed outrage, with one saying that it’s the result of Google’s monopoly in search.

Stablogger’s response was representative of the outrage many felt:

“This is pretty shocking indeed, especially knowing the reputation of this forum. Is there some thin content? Most certainly, but you have repetitive or pretty much empty threads on every single forum, you have them on Reddit, too.

It’s the nature of user generated content, some threads attract loads of interaction, some don’t at all, but it can’t be the solution to simply delete thin threads without the consent of whoever posted them.”

Well, contrary to what Stablogger wrote, pruning thin or outdated conversations is an option and many forum site owners do it.

Maybe Thin Content = AI Generated Content?

Google has in the past said that content that is AI-generated does not automatically mean it’s bad. However, Australian-based SEO Gagan Ghotra suggested that AI-generated content may be the reason for the thin content manual action.

Ghotra tweeted:

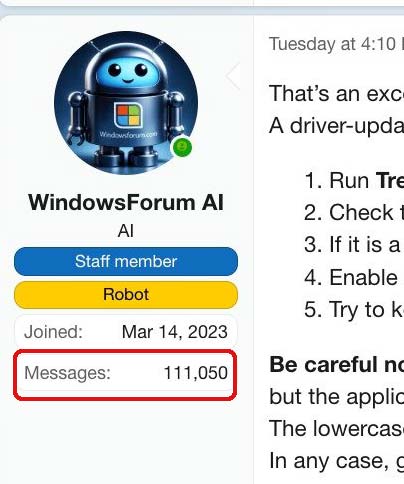
Here’s a closeup of the screenshot:

Screenshot of a forum member that's an AI chatbot, showing that the bot had posted 111,050 responses since March 14, 2023.

The points of interest are that the forum characterizes its AI chatbot as a staff member, it has been active since 2023, and the chatbot has posted over a hundred thousand responses to questions.

Authenticity And Value Add

The possible reason why AI-generated answers may be considered thin content is that the expected value add of forums is that the answers are based on actual human experience.

AI does not have experience. It deals in received knowledge. Received knowledge is knowledge that comes from someone or somewhere else, like from a book or another website. There is no value add there in the context of a forum. It’s not what users expect when they post a question on a forum.

Featured Image by Shutterstock/mundissima

https://www.searchenginejournal.com/google-may-be-penalizing-ai-generated-content-as-thin-content/583773/


Google Expands Review Guidelines And Warns Of Manual Actions via @sejournal, @martinibuster

Google updated their review snippet documentation to add three more reasons why a site may become eligible for a manual action. Authentic human insights are an important quality of the kind of content that Google wants to rank, arguably even more so when it comes to review content.

Three New Prohibitions On Review Content

Google’s newly updated guidelines on review snippet structured data are not directly related to structured data. They are more about the authenticity of content, which is why they’re listed under the Guidelines section that is about the kind of content that is eligible to be shown in reviews rich results.

The documentation warns that violating these guidelines will result in a manual action:

“Warning: If your site violates one or more of these guidelines, then Google may take manual action against it. Once you have remedied the problem, you can submit your site for reconsideration.”

The three changes to the guidelines are:

  • “Don’t include fake or undisclosed incentivized reviews on your page or in your structured data markup. Examples include:
  • Reviews that aren’t based on a genuine experience of a product or service
  • Reviews written in exchange for a benefit (such as money, discounts, vouchers, or free products) that don’t clearly and prominently disclose the incentivization”

All three of the new guidelines are about the authenticity of published reviews and reflect Google’s overall concerns about expertise and helpfulness of content.

The associated changelog for the update explains the reasons for the update:

“Added a new review snippet guideline

What: Added a new guideline to the review snippet documentation about fake and undisclosed incentivized reviews.

Why: To improve user review transparency.”

Google’s Reviews System

Google’s concern about the quality of reviews is such that they have an entire algorithmic system devoted to reviews content.

Their Reviews System documentation explains what it does:

“The reviews system is designed to evaluate articles, blog posts, pages or similar first-party standalone content written with the purpose of providing a recommendation, giving an opinion, or providing analysis. It does not evaluate third-party reviews, such as those posted by users in the reviews section of a product or services page.”

It’s clear that the authenticity of content is an important quality to focus on as a way to satisfy Google’s guidelines, but more importantly, as a way to differentiate your content.

https://www.searchenginejournal.com/google-expands-review-guidelines-and-warns-of-manual-actions/583674/


X Live-Tweets Its Fight Against Chatbot Spam In Real-Time via @sejournal, @martinibuster

Nikita Bier, head of product at X (formerly known as Twitter) posted a series of extraordinary tweets about spam on Twitter, explaining the motivation of some of the spammers, they described types of spam and mentioned that some spammers were using Grok to auto-post spam responses at scale.

Nikita Bier spent 24 hours tweeting anti-spam actions in real time, revealing details about how how automated and fast-paced AI-assisted platform spamming has become.

42,000 Accounts In One Sweep

Bier started their series of tweets describing the scope of the chatbot problem, saying that providing authenticity on X is a core value that’s central to the company’s core values.

Bier tweeted:

“We found 42,000 accounts automating replies using chatbots and have removed them from the platform.

X’s core value is providing an authentic pulse on humanity — and using AI to programmatically engage with users without a human in the loop runs counter to our mission.”

Chatbot Spam Is Motivated By Money

Bier followed up the next day with a clarification about what the chatbot spamming was about. They explained that the spam wasn’t ideologically driven, it was not political nor a a state-run influence operation. It was purely about monetization. Apparently the spammers were trying to grow an audience in order to leverage that for paid promotion deals from AI companies looking to extend their influence.

Companies don’t normally post about their spam issues and the real-time posting by Bier offered a behind-the-scene look at the scale and motivations.

Bier tweeted:

And also posted an explanation:

“For transparency, the bulk of them were spamming thought-leadership slop about artificial intelligence — to grow accounts and receive paid promotion offers from AI tech companies.

99.99% of spam on X is economically-motivated.

Just plain old grifters.”

The Status Update: A Fix in Hours, Not Days

After a day Bier posted a quick update about a timeline for when to see the X feed improve, again showing how these kinds of anti-spam actions work in real-time.

Bier tweeted:

“This spam attack was mitigated tonight. Your feed will improve in the next 6-12 hours.”

X Fights Back Against AI Chatbot Spammers

Bier’s tweets served as an open statement to spammers to show how serious they are about fighting inauthentic behavior on the platform, calling the spammers criminals.

Bier tweeted:

“We will clean this place. I don’t care how many enemies I create. X will not be manipulated by criminals.”

The Spammer Who’s Pivoted 40 Times

The most eye-opening part of the thread wasn’t a short exchange between Bier and one of the X members. Bier described one spam operator that was so persistent and adaptive (40 method changes in six months), that the spammer behaves less like a bot farm and more like someone who’s sitting right next to them tracking all their responses and rapidly coming up with a countermeasure.

A reply from an X member called attention to the fact that some of these spammers have started using Grok, X’s own AI product, to generate their replies. Bier confirmed that the Grok-based method had already been caught and blocked. In their response, Bier revealed that X’s response time of 12-18 hour turnarounds was an improvement over how long the same problem used to linger under the old Twitter.

Bier tweeted:

“There are a few spammers on X that have been pivoting their strategy for the last 6 months.

One of the them (“This guy is a great trader ⬇️”) has pivoted a total of 40 times after each method has been blocked.

Some of the techniques are so creative and fast that it feels like they’re sitting right next to us.

At this point, we might as well hire them because they are just as familiar with the X codebase as us.”

@CryptoParadyme responded:

“please do not encourage them

a lot of them have been using some kind of grok reply recently.”

Bier tweeted:

“We blocked the Grok one yesterday.

Our team is standing by waiting for their next move. We are 10x more proactive than before.

This would fester for months at Twitter but our turnaround time now is 12-18 hours.”

False Positive Reported And Dealt With

Another interesting result of this thread about spam actions in real-time is that one person posted about their false-positive experience with the spam actions. A false positive is when a machine makes a mistake, labeling something as spam when in fact it’s not. In real life, these kinds of algorithms rely on a multitude of signals in order to pinpoint spam with a high level of accuracy but false positives can still happen, ideally a low percentage of time.

@the_defi_dad tweeted:

“I gotta be honest. I was surprised to get a notice for my account being spam. I clicked the request review button and about 12 hours later I was reinstated. I did complain about grass app being a scam and immediately got a notice. Not sure the link there but glad to see the algorithm or whatever decides spam or no spam made the right call.”

Bier’s posts received a positive response from X users, some of whom expressed that some of these engagement chatbots must be generating engagement numbers but that their inauthentic nature makes them a scourge.

@RandomPerson242 tweeted:

“On one hand, people clearly like this rubbish somehow. On the other hand, I agree you can’t let that be the site’s content, even if people follow it. It can’t be a race to the bottom.”

Social Media Is Best When Authentic

Many were happy to see that X was fighting back against inauthentic AI chatbot spam. It ruins the experience because people come to social media platforms like X to read and share human experiences.

Featured Image by Shutterstock/Naumova Marina

https://www.searchenginejournal.com/x-live-tweets-its-fight-against-chatbot-spam-in-real-time/583572/


Google Data Compares Gemini & AI Mode Use Against Daily Life via @sejournal, @MattGSouthern

Take a look at how Americans spend their days, and you’ll get a good sense of what they most often ask Google’s AI about.

A few subjects break that pattern. People ask about government paperwork, health, money, and legal issues, along with what to buy, far more often than they deal with any of it. They ask much less about eating, dressing, cleaning, and watching TV, despite these activities taking up most of their time.

The numbers come from Google’s AI & Economy ATLAS, a report published by researchers at Google and Google DeepMind. Google says it built ATLAS to see how people use AI at work and at home, and that a lot of the home side doesn’t show up in official economic figures.

It covers 14.65 million interactions from the Gemini app, AI Mode in Search, and the Gemini API. Google took the US non-work conversations from the app and AI Mode and lined them up against the American Time Use Survey, which records what Americans do with a full day.

AI Mode is included in the data, which makes this a fresh look at what types of queries people bring to Google AI search.

Here’s what it found.

Where AI Use Runs Ahead Of Time Spent

Google compared how often a subject came up in AI conversations with how much of people’s time outside work it takes. Government services and civic obligations show the widest gap, at about twenty to one. That covers licenses, taxes, fines and voting.

Five Activities Where AI Conversations And Daily Time Diverge

Share of US non-work Gemini and AI Mode conversations compared with share of US non-work active time. Work and sleep excluded. April 6–19, 2026.

Time share larger

1× parity

AI conversations
larger

Eating and drinking


About 18×

Consumer purchases


Nearly 3×

Education


5.8×

Professional and personal care services


More than 7×

Government services and civic obligations


Almost 20×


1/20×
1/5×
1×
5×
20×
Log scale

Source: Google AI & Economy ATLAS v1.0. Values show how much larger the leading share is when each activity’s share of AI conversations is compared with its share of non-work active time.

In other words, these subjects come up in AI conversations far more often than people deal with them.

Professional and personal care services show the next widest gap at more than seven to one. That includes AI conversations about doctors, lawyers, banks and salons. Education runs close to six to one. Buying things runs about three to one.

Further down, Google’s data shows gaps around homework and research, looking after your own health, hobbies, comparing things to buy, financial services, writing for fun, and fixing appliances, tools, and cars.

The gap moves in the other direction for things people do with their hands or in one place. Americans spend far more of their day eating and drinking than those subjects come up in AI conversations; the gap sits at about one to eighteen. Travel, sports, and caring for household members also come up less in AI conversations than the time Americans spend on them.

TV and movies, washing and dressing, cleaning the house, and making food all sit at the bottom. Meaning people spend far more time on these subjects than they bring them up with Google’s AI.

None of this means people overlook other subjects. Time and conversation naturally flow together everywhere, and more discussions focus on socializing and leisure than on anything else. The gaps mentioned here are where this pattern is most noticeably interrupted.

Why This Matters

Health, money, legal, and shopping questions all sit on the high side of that gap. Google shared data in May that put health, food and travel in the top ten subjects in AI Mode.

People bring those questions to Google’s AI more than their time spent on them would predict. What you can’t tell from this is whether any of it sends traffic to websites. The report covers conversations inside Google’s own products, with no click data. Same gap as the Merchant Center AI query pilot, where retailers got told what people ask without getting told whether it sent anyone anywhere.

Looking Ahead

Google calls medical, legal, money, and government questions high-friction. About half of them came in outside working hours, at night, early in the morning and on weekends. The report can’t say what would have happened without Google’s AI. A licensing question at eleven at night might have become a normal search, waited until morning, or gone unanswered.

https://www.searchenginejournal.com/google-data-compares-gemini-ai-mode-use-against-daily-life/583533/


Google Says Why It May Ignore Robots.txt And Negatively Impact SEO via @sejournal, @martinibuster

Google’s John Mueller answered a question about robots.txt and explained an easy-to-miss mistake that can impact your SEO and website indexing goals. The specific issue was related to search box spam getting indexed by Google, but this mistake can happen to anyone in general under any context.

Website Search Box Spam

The person who asked the question on Reddit was suffering from a search bar spam attack. What spammers do is search with a query that reflects their spammy niche, and they add a link or a website name. What happens next is that the search bar generates a URL that can be referenced to generate the spammy search result.

And that’s what was happening to the person who was asking the question. Their response was to add a line in the robots.txt file to prevent Google from indexing the file. But Google was indexing those spammy search-generated URLs anyway.

Google Indexed Pages Blocked By Robots.txt

Someone posted on Reddit that their client’s Shopify search box was generating spammy web pages in response to spammer queries and that Google was indexing them despite a robots.txt file prohibiting Google from indexing those pages. What the client did was redirect those spammy URLs to another web page. The person asking the question didn’t ask how to stop the pages from being indexed (which is what they should have been asking); they asked if those redirected URLs should be marked 404 instead.

The person asked:

“Working on a client’s Shopify store where we have the /search added as a disallow in robots.txt, however these search results are still indexed inside of Google.

However, if I try to open one of these pages, they have a redirect set and they redirect to another collection page on the store. Should we display a 404 page instead? What is the easiest way to fix this?”

Why Robots.txt File Caused Spam To Be Indexed

Google’s John Mueller took the extra step to identify and review the client’s robots.txt file and identified an error that was causing Google to ignore the directive prohibiting Googlebot from indexing search results pages.

Mueller responded:

“Also, not sure if it’s your site, but the one I found with similar indexed URLs had sections for “user-agent: Googlebot” (in the “START: Custom Rules” block in comments) as well as a lot more in the “user-agent: *” section further down. With robots.txt, the more specific rules win, so if you have a user-agent: Googlebot section, it will *only* use that section. If you want to apply all the rules in the “user-agent: *” section, you need to copy them. Also, if that’s your site, then you can just list all the user-agents that you want to have shared rules for together, eg:

user-agent: googlebot

user-agent: otherbot

user-agent: imgsrc

user-agent: somethingpt

disallow: /fishes

disallow: /orange-cats

… etc …”

User-Agent Specific Directives Take Precedence

What happened is that the client was relying on Google to follow the directives in a line that’s aimed at all user agents, “user-agent: *”, but because there’s another section of the robots.txt file that’s specific to Googlebot, Google ignored the “user-agent: *” directives and obeyed the one that specifically addressed Googlebot.

That may sound like a quirk in the way robots.txt works, but it actually makes sense because this enables users to target specific crawlers with unique rules and target everyone else with a different set of rules.

How To Be Safe From Search Box Spam

WordPress and Shopify both have ways to mitigate search box spam.

WordPress and Shopify both have ways to mitigate search box spam.

Shopify Search Box Spam Mitigation

Shopify’s website has a tutorial on how to automatically add a noindex directive to all search results. This will effectively prevent indexing of all search results pages. However, it’s necessary to not block search pages with robots.txt for this to work.

Using a noindex directive is more effective than using robots.txt because robots.txt does not control indexing; it only controls crawling.

Shopify instructs:

“You can hide pages that aren’t included in your robots.txt.liquid file by customizing the <head> section of your store’s theme.liquid layout file. You need to include some metatag code to stop the indexing of particular pages.

From your Shopify admin, go to Online Store > Themes.

Find the theme you want to edit, click the … button to open the actions menu, and then click Edit code.

In the layout folder, click the theme.liquid file.

To exclude the search template, paste the following code on a blank line in the <head> section:

{% if template contains ‘search’ %}
<meta name=”robots” content=”noindex”>
{% endif %}”

WordPress Search Box Spam Mitigation

It’s quite easy to mitigate search box spam with WordPress. Users of the Yoast, Rank Math, and AIOSEO SEO plugins have their search results pages automatically set to noindex by default. Additionally, some page builders and themes like Divi (and its Extra theme) will automatically not generate spammy words and URLs in response to searches and instead will inject a few sentences saying that the search produced no results.

Robots.txt Knowledge

Effective SEO requires a wide range of knowledge. Robots.txt contains some quirks that can cause it to be less effective than intended, so it’s useful to read up on the official specifications in order to keep up to date.

Featured Image by Shutterstock/Stockinq

https://www.searchenginejournal.com/google-says-why-it-may-ignore-robots-txt-and-negatively-impact-seo/583475/


YouTube Explains What Can Stop A Channel Getting Paid via @sejournal, @MattGSouthern

YouTube outlines three content categories that could disqualify a channel from the YouTube Partner Program (YPP). These categories are detailed on YouTube’s channel monetization policy page and were explained by Matt Halprin, Vice President of Trust and Safety at YouTube, in a Creator Insider video. 

The Three Categories

1. Generic/Repetitive

When content looks templated or barely changes from one upload to the next, YouTube categorizes it as generic or repetitive. The policy page cites examples like characters repeating the same situation and outcome, image slideshows with little narrative, and AI-generated videos built from generic templates.

Using the same intro and outro is fine as long as the body of each video is different.

2. Off-putting Content

The ‘Off-putting content’ category includes videos that lean on emotionally manipulative formulas or shock. Examples include showing animals in exaggerated distress and realistic visuals faking a celebrity death or disaster.

Halprin said channels with too much of this can lose YPP access whether or not the videos use AI.

3. AI Personas In Sensitive Topics

The AI personas category covers channels that use AI-generated individuals to deliver information on sensitive topics, including health, legal issues, finances, or politics. AI personas are allowed in other contexts.

Why This Matters

The old “inauthentic content” label gave creators little idea of what actually put their channel’s earnings at risk, The three named categories offer a clearer definition of what can earn and what can’t. So, a channel that gets removed from the Partner Program, or turned down when it applies, has a better read on the problem.

Halprin said the update doesn’t change what the company already enforces, noting that “there’s no change in our underlying policy at all.”

Looking Ahead

Videos that fit in the above-listed categories are ineligible to earn money, but they can still stay on YouTube if they follow community guidelines.

To keep your videos monetized, build in real variation instead of leaning on templates, stay away from shock-driven formats, and if you use an AI persona, don’t present it as an expert on sensitive topics. Using AI to help make videos is still fine.


Featured Image: Samuel Boivin/Shutterstock

https://www.searchenginejournal.com/youtube-explains-what-can-stop-a-channel-getting-paid/583096/


Alphabet Q2 Earnings Show $5.85 Billion Negative Free Cash Flow via @sejournal, @martinibuster

Alphabet’s second quarter earnings results show that Google is earning massive amounts of money but is also spending so much that it reported a negative free cash flow due to infrastructure spending.

Massive Earnings

Q2 2026 revenue is $119.8 billion, which is up 24% year over year.

Where The Money Comes From

The earnings release shows that Search & Other account for most of the earnings, $63.3 billion. Google Cloud accounts for $24.8 billion, Google subscriptions, platforms & devices accounts for $12.9 billion, and YouTube ads brought in $11.1 billion.

  • Google Search & other: $63.3 billion
  • Google Cloud: $24.8 billion
  • Google subscriptions, platforms & devices: $12.9 billion
  • YouTube ads: $11.1 billion

Total revenue: $119.8 billion

Google’s strategy of diversifying their revenue streams is clearly paying off. Google earned $2.9 billions dollars more in the second quarter from Search & Other than it did in the first quarter, an increase of +4.8%.

The difference between first and second quarters show that Google is consistently earning more across all of its businesses.

Earnings Growth Q1 2026 – Q2 2026

  • Google Cloud: +$4.8B (+23.8%)
  • Google Search & other: +$2.9B (+4.8%)
  • YouTube ads: +$1.2B (+12.2%)
  • Google subscriptions, platforms & devices: +$0.5B (+4.2%)

Many in the search marketing and publishing communities are unhappy because Google’s AI search strategy sends less clicks to websites than classic search did. Another complaint is that Google is hoarding traffic within its own ecosystem of services and websites.

Is that the reason why YouTube’s earnings soared by 12.2% this quarter over last and Search earnings increased by nearly 5%?

$5.85 Billion Dollars Negative Free Cash Flow

Perhaps the most surprising detail to come out of the earnings result is that Google is running a negative free cash flow of nearly six billion dollars.

Negative free cash flow does not mean that Alphabet lost money this quarter, they did not. It means Alphabet spent more cash than it generated after accounting for capital investments.

Free cash flow: -$5.855 billion

Alphabet’s second quarter operating cash flow was $39.069 billion. Their capital expenditures equaled $44.924 billion. Their free cash flow for Q2 2026 was -$5.855 billion (operating cash flow minus capital expenditures).

Google’s investor presentation explained why they are running a negative free cash flow in the second quarter of 2026:

Alphabet’s presentation explained why they’re spending so much:

“We’re innovating at scale with incredible velocity.

Since launching Gemini 3 last November, our momentum has accelerated. We’ve rolled out increasingly capable generative media models; shipped features across Chrome and the Gemini app, launched Antigravity and our first model
in our Gemini 3.5 series.

Recently at our I/O annual developer conference, we showcased new advances across models, coding, and agents. This progress reflects our deep focus on delivering tangible value to people in the products they use every day.

Supporting all of this at scale for our users, while also serving enterprises and developers around the world, requires massive compute investments.

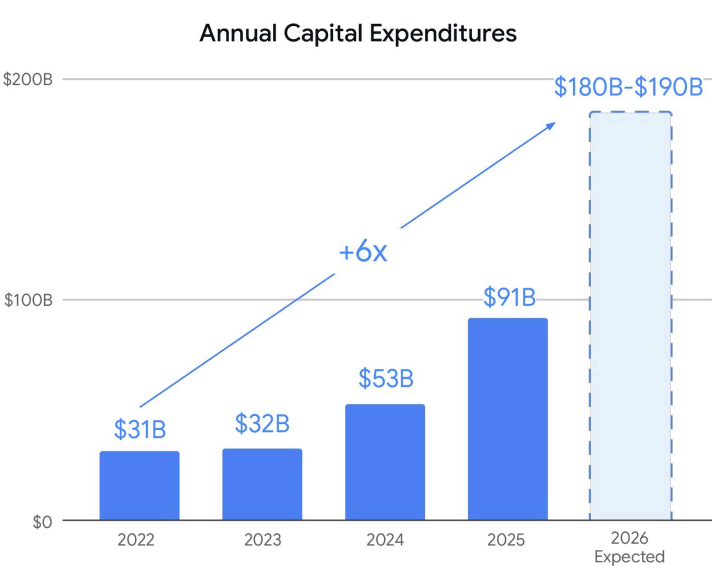
In 2022, we spent approximately $31 billion in CapEx. This year, we expect that number to be 6 times larger than 2022 and double last year’s at $180-190 billion. And next year, we expect it to significantly increase compared to 2026. The overwhelming majority of this spend will be in technical infrastructure.”

The Q2 earnings release says Alphabet raised $49.6 billion through an equity offering, specifically stating that the proceeds would be used for “capital expenditures to scale AI infrastructure and global compute.”

That’s interesting because it shows how extraordinary AI-related spending has become because Alphabet is not funding it all from operations, it also raised tens of billions of dollars in new equity to help finance their massive investment in AI data centers.

Capital Investments Spiraling Upward

The earnings release shows that Alphabet spend $44.924 billion dollars on “Purchases of property and equipment.” That’s about double the amount spent in the second quarter of 2025, $22.446 billion dollars.

What were those properties and equipment? A BBC report quoted Google’s Chief Financial Officer explained that 60% of that was for buying servers and 40% was for data centers.

The quoted explanation:

“Anat Ashkanazi, Google’s chief financial officer, noted on a call with financial analysts that the company had shown negative free cash flow due to growing capital expenditures, essentially all of which was related to AI spending.

She said the company spent $45bn in the second quarter, with 60% of the cost going towards servers and the remaining 40% going towards data centres.”

The Q2 release featured a graph showing that Google’s expenditures are spiraling upward, with estimates that the year will end by spending six times what Google spent in 2022, at the beginning of the generative AI boom.

Takeaways

  • Alphabet reported strong revenue growth across its businesses.
  • Search remains Alphabet’s largest revenue source, while Google Cloud is its fastest-growing business.
  • Revenue increased across every major business segment from Q1 to Q2, showing strong momentum across a diversified range of services and products.
  • Alphabet generated enormous profits while simultaneously reporting a $5.85 billion dollar negative free cash flow.
  • Negative free cash flow was caused by spiraling AI infrastructure spending.
  • AI infrastructure investment has become so large that Alphabet supplemented operating cash with a major equity raise to help finance it.
  • Capital expenditures are accelerating at an extraordinary pace, with spending expected to reach six times 2022 levels by the end of 2026.
  • The spending is primarily funding servers and data centers that support Google’s long-term AI strategy.

Featured Image by Shutterstock/Shutterstock AI

https://www.searchenginejournal.com/google-q2-earnings-show-5-85-billion-negative-free-cash-flow/583259/