Google Discover Update: Early Data Shows Fewer Domains In US via @sejournal, @MattGSouthern

NewzDash published an analysis comparing Discover visibility before and after Google’s February 2026 Discover core update, using panel data from millions of US users tracked through its DiscoverPulse tool.

It compared pre-update (Jan 25-31) and post-update (Feb 8-14) windows across the top 1,000 domains and top 1,000 articles in the US, California, and New York.

For transparency, NewzDash is a news SEO tracking platform that sells Discover monitoring tools.

What The Data Shows

Google said the update targeted more locally relevant content, less sensational and clickbait content, and more in-depth, timely content from sites with topic expertise. The NewzDash data has early readings on all three.

NewzDash compared Discover feeds in California, New York, and the US as a whole. The three feeds mostly overlapped, but each state got local stories the others didn’t. New York-local domains appeared roughly five times more often in the New York feed than in the California feed, and vice versa.

In California, local articles in the top 100 placements rose from 10 to 16 in the post-update window. The local layer included content from publishers like SFGate and LA Times that didn’t appear in the national top 100 during the same period.

Clickbait reduction was harder to confirm. NewzDash acknowledged that headline markers alone can’t prove clickbait decreased. It did find that what it called ‘templated curiosity-gap patterns’ appeared to lose visibility. Yahoo’s presence in the US top 1,000 dropped from 11 to 6 articles, with zero items in the top 100 post-update.

Unique content categories grew across all three geographic views, but unique publishers shrank in the US (172 to 158 domains) and California (187 to 177). That combination suggests Discover is covering more topics but sending that distribution to a narrower set of publishers.

This pattern aligns with what early December core update analysis showed about specialized sites gaining ground over generalists.

X.com’s Growing Discover Presence

X.com posts from institutional accounts climbed from 3 to 13 items in the US top 100 Discover placements and from 2 to 14 in New York’s top 100.

NewzDash noted it had tracked X.com’s Discover growth since November and said the update appeared to accelerate the trend. Most top-performing X items came from established media brands.

The analysis noted it couldn’t prove or disprove whether X posts are cannibalizing publisher traffic in Discover, calling the data a “directional sanity check.” The open question is whether routing through X adds friction that could reduce click-through to owned pages.

Why This Matters

As we continue to monitor the Discover core update, we now have early data on what it seems to favor. Regional publishers with locally relevant content showed up more often in NewzDash’s post-update top lists.

Discover covered more topics in the post-update window, but fewer sites were getting that traffic in the US and California. Publishers without a clear topic focus could be on the wrong side of that trend.

Looking Ahead

This analysis covers an early window while the rollout is still being completed. The post-update measurement period overlaps with the Super Bowl, Winter Olympics, and ICC Men’s T20 World Cup, any of which could independently inflate News and Sports category visibility.

Google said it plans to expand the Discover core update beyond English-language US users in the months ahead.


Featured Image: joingate/Shutterstock

https://www.searchenginejournal.com/google-discover-update-early-data-shows-fewer-domains-in-us/568091/


90 Days. 1 Plan. Improved Local Search Visibility [Webinar] via @sejournal, @hethr_campbell

A 90 Day Plan to Prepare Every Location for AI Search

AI is changing how consumers discover and choose local brands. For multi-location businesses, visibility is no longer decided only by search rankings. 

AI agents now evaluate location data, reviews, content, engagement, and brand trust before a customer ever clicks. This shift means each individual location is judged on its own signals, not just the strength of the parent brand.

Without a clear plan, enterprise teams risk silent exclusion across entire location networks, leading to lost visibility and declining demand. The challenge is not understanding that GEO matters, but knowing how to operationalize it at scale.

In this session, Ana Martinez, Chief Technology Officer of Uberall, shares a practical 90-day framework for making every location AI-ready. She will explain how AI agents surface and exclude local brands, which location-level signals matter most, and how teams can execute GEO across hundreds or thousands of locations.

What You’ll Learn

  • A phased GEO roadmap to prepare, optimize, and scale AI readiness
  • The key location level signals AI agents trust and what to fix first
  • How to operationalize GEO across large location networks

Why Attend?

This webinar gives enterprise teams a clear, actionable plan to compete in AI-driven local discovery. You will leave with a framework that protects visibility, supports demand, and prepares every location for how discovery works today.

Register now to learn how to make every location AI-ready in the next 90 days.

🛑 Can’t attend live? Register anyway, and we’ll send you the on-demand recording after the webinar.

https://www.searchenginejournal.com/90-days-improved-local-search-visibility/566687/


Google Revises Discover Guidelines Alongside Core Update via @sejournal, @MattGSouthern

Google revised its “Get on Discover” documentation following the lauch of the February Discover core update.

On its documentation updates page, Google said it added more information on how sites can increase the likelihood of content appearing in Discover. Here’s what was added.

What Changed

Comparing the archived version with the current page shows Google rewrote its list of recommendations for Discover visibility.

The previous version combined title and clickbait guidance into a single bullet, saying to “Use page titles that capture the essence of the content, but in a non-clickbait fashion.”

Google split that into two items. The first now says “Use page titles and headlines that capture the essence of the content.” The second says “Avoid clickbait and similar tactics to artificially inflate engagement.”

That word “clickbait” is new. The previous version said “Avoid tactics to artificially inflate engagement” without naming the tactic.

The sensationalism guidance changed too. The old version said “Avoid tactics that manipulate appeal by catering to morbid curiosity, titillation, or outrage.” The revision names the tactic, saying “Avoid sensationalism tactics that manipulate appeal.”

The new addition is a recommendation to “Provide an overall great page experience,” with a link to Google’s page experience documentation. That recommendation isn’t in the archived version.

Image requirements, traffic fluctuation guidance, and performance monitoring sections remain unchanged.

Why This Matters

These documentation changes map to what Google said the core update targets. The blog post announcing the update said the update would show more locally relevant content, reduce sensational content and clickbait, and surface more original content from sites with expertise.

Discover documentation has changed before alongside algorithm updates. Previously, Google added Discover to its Helpful Content System documentation and later expanded its explanation of why Discover traffic fluctuates. Both of those updates aligned with broader changes to how Discover evaluated content.

Page experience has been part of Google’s Search guidance since 2020 but wasn’t in the Discover-specific recommendations before this revision.

Looking Ahead

The February Discover core update is rolling out to English-language users in the United States over the next two weeks. Google said it plans to expand to all countries and languages in the months ahead.

Publishers monitoring Discover traffic in Search Console should check the Get on Discover page for the current recommendations. Google’s standard core update guidance applies as well.


Featured Image: ZikG/Shutterstock

https://www.searchenginejournal.com/google-revises-discover-guidelines-alongside-core-update/566748/


Discover Core Update, AI Mode Ads & Crawl Policy – SEO Pulse via @sejournal, @MattGSouthern

Welcome to the week’s Pulse for SEO: updates affect how Google ranks content in Discover, how it plans to monetize AI search, and what content you serve to bots.

Here’s what matters for you and your work.

Google Releases Discover-Only Core Update

Google launched the February 2026 Discover core update, a broad ranking change targeting the Discover feed rather than Search. The rollout may take up to two weeks.

Key Facts: The update is initially limited to English-language users in the United States. Google plans to expand it to more countries and languages, but hasn’t provided a timeline. Google described it as designed to “improve the quality of Discover overall.” Existing core update and Discover guidance apply.

Why This Matters For SEOs

Google has historically rolled Discover ranking changes into broader core updates that affected Search as well. Announcing a Discover-specific core update means rankings in the feed can now move without any corresponding change in Search results.

That distinction creates a monitoring problem. When you track performance in Search Console, you should check Discover traffic independently over the next two weeks. Traffic drops that look like a core update penalty may be Discover-only. Treating them as Search problems leads to the wrong diagnosis.

Discover traffic concentration has grown for publishers. NewzDash CEO John Shehata reported that Discover accounts for roughly 68% of Google-sourced traffic to news sites. A core update targeting that surface independently raises the stakes for any publisher relying on the feed.

Read our full coverage: Google Releases Discover-Focused Core Update

Alphabet Q4 Earnings Reveal AI Mode Monetization Plans

Alphabet reported Q4 2025 earnings, showing Search revenue grew 17% to $63 billion. The call included the first detailed look at how Google plans to monetize AI Mode.

Key Facts: CEO Sundar Pichai said AI Mode queries are three times longer than traditional searches. Chief Business Officer Philipp Schindler described the resulting ad inventory as reaching queries that were “previously challenging to monetize.” Google is testing ads below AI Mode responses.

Why This Matters For SEOs

The monetization details matter more than the revenue headline. Google is treating AI Mode as additive inventory, not a replacement for traditional search ads. Longer queries create new ad surfaces that didn’t exist when users typed three-word searches. For paid search practitioners, that means new campaign territory in conversational queries.

The metrics Google celebrated on this call describe users staying on Google longer. Google framed longer AI Mode sessions as a growth driver, and the monetization infrastructure follows that logic. The tradeoff to watch is referral traffic.

AI Mode creates a seamless path from AI Overviews, as detailed in our coverage last week. The earnings data suggest Google sees that containment as part of the growth story.

Read our full coverage: Alphabet Q4 2025: AI Mode Monetization Tests And Search Revenue Growth

Mueller Pushes Back On Serving Markdown To LLM Bots

Google Search Advocate John Mueller pushed back on the idea of serving Markdown files to LLM crawlers instead of standard HTML, calling the concept “a stupid idea” on Bluesky and raising technical concerns on Reddit.

Key Facts: A developer described plans to serve raw Markdown to AI bots to reduce token usage. Mueller questioned whether LLM bots can recognize Markdown on a website as anything other than a text file, or follow its links. He asked what would happen to internal linking, headers, and navigation. On Bluesky, he was more direct, calling the conversion “a stupid idea.”

Why This Matters For SEOs

The practice exists because developers assume LLMs process Markdown more efficiently than HTML. Mueller’s response treats this as a technical problem, not an optimization. Stripping pages to Markdown can remove the structure that bots need to understand relationships between pages.

Mueller’s technical guidance is consistent, including his advice on multi-domain crawling and his crawl slump guidance. This fits a pattern where Mueller draws clear lines around bot-specific content formats. He previously compared llms.txt to the keywords meta tag, and SE Ranking’s analysis of 300,000 domains found no connection between having an llms.txt file and LLM citation rates.

Read our full coverage: Google’s Mueller Calls Markdown-For-Bots Idea ‘A Stupid Idea’

Google Files Bugs Against WooCommerce Plugins For Crawl Issues

Google’s Search Relations team said on the Search Off the Record podcast that they filed bugs against WordPress plugins. The plugins generate unnecessary crawlable URLs through action parameters like add-to-cart links.

Key Facts: Certain plugins create URLs that Googlebot discovers and attempts to crawl. The result is wasted crawl budget on pages with no search value. Google filed a bug with WooCommerce and flagged other plugin issues that remain unfixed. The team’s response targeted plugin developers rather than expecting individual sites to fix the problem.

Why This Matters For SEOs

Google intervening at the plugin level is unusual. Normally, crawl efficiency falls on individual sites. Filing bugs upstream suggests the problem is widespread enough that one-off fixes won’t solve it.

Ecommerce sites running WooCommerce should audit their plugins for URL patterns that generate crawlable action parameters. Check your crawl stats in Search Console for URLs containing cart or checkout parameters that shouldn’t be indexed.

Read our full coverage: Google’s Crawl Team Filed Bugs Against WordPress Plugins

LinkedIn Shares What Worked For AI Search Visibility

LinkedIn published findings from internal testing on what drives visibility in AI-generated search results. The company reported that non-brand awareness-driven traffic declined by up to 60% across the industry for a subset of B2B topics.

Key Facts: LinkedIn’s testing found that structured content performed better in AI citations, particularly pages with named authors, visible credentials, and clear publication dates. The company is developing new analytics to identify a traffic source for LLM-driven visits and to monitor LLM bot behavior in CMS logs.

Why This Matters For SEOs

What caught my attention is how much this overlaps with what AI platforms themselves are saying. Search Engine Journal’s Roger Montti recently interviewed Jesse Dwyer, head of communications at Perplexity. The AI platform’s own guidance on what drives citations lines up closely with what LinkedIn found. When both the cited source and the citing platform arrive at the same conclusions independently, that gives you something beyond speculation.

Read our full coverage: LinkedIn Shares What Works For AI Search Visibility

Theme Of The Week: Google Is Splitting The Dashboard

Every story this week points to the same realization. “Google” is no longer one thing to monitor.

Google is now announcing Discover core updates separately from Search core updates. AI Mode carries ad formats and checkout features that don’t exist in traditional results. Mueller drew a policy line around how bots consume content. Google filed crawl bugs upstream at the plugin level, and LinkedIn is building a separate measurement for AI-driven traffic.

A year ago, you could check one traffic graph in Search Console and get a reasonable picture. The picture now fragments across Discover, Search, AI Mode, and LLM-driven traffic. Ranking signals and update cycles differ, and the gaps between them haven’t been closed.

Top Stories Of The Week:

This week’s coverage spanned five developments across Discover updates, search monetization, crawl policy, and AI visibility.

More Resources:


Featured Image: Accogliente Design/Shutterstock

https://www.searchenginejournal.com/discover-core-update-ai-mode-ads-crawl-policy-seo-pulse/566659/


Google Shows How To Check Passage Indexing via @sejournal, @martinibuster

Google’s John Mueller was asked how many megabytes of HTML Googlebot crawls per page. The question was whether Googlebot indexes two megabytes (MB) or fifteen megabytes of data. Mueller’s answer minimized the technical aspect of the question and went straight to the heart of the issue, which is really about how much content is indexed.

GoogleBot And Other Bots

In the middle of an ongoing discussion in Bluesky someone revived the question about whether Googlebot crawls and indexes 2 or 15 megabytes of data.

They posted:

“Hope you got whatever made you run 🙂

It would be super useful to have more precisions, and real-life examples like “My page is X Mb long, it gets cut after X Mb, it also loads resource A: 15Kb, resource B: 3Mb, resource B is not fully loaded, but resource A is because 15Kb < 2Mb”.”

Panic About 2 Megabyte Limit Is Overblown

Mueller said that it’s not necessary to weigh bytes and implied that what’s ultimately important isn’t about constraining how many bytes are on a page but rather whether or not important passages are indexed.

Furthermore, Mueller said that it is rare that a site exceeds two megabytes of HTML, dismissing the idea that it’s possible that a website’s content might not get indexed because it’s too big.

He also said that Googlebot isn’t the only bot that crawls a web page, apparently to explain why 2 megabytes and 15 megabytes aren’t limiting factors. Google publishes a list of all the crawlers they use for various purposes.

How To Check If Content Passages Are Indexed

Lastly, Mueller’s response confirmed a simple way to check whether or not important passages are indexed.

Mueller answered:

“Google has a lot of crawlers, which is why we split it. It’s extremely rare that sites run into issues in this regard, 2MB of HTML (for those focusing on Googlebot) is quite a bit. The way I usually check is to search for an important quote further down on a page – usually no need to weigh bytes.”

Passages For Ranking

People have short attention spans except when they’re reading about a topic that they are passionate about. That’s when a comprehensive article may come in handy for those readers who really want to take a deep dive to learn more.

From an SEO perspective, I can understand why some may feel that a comprehensive article might not be ideal for ranking if a document provides deep coverage of multiple topics, any one of which could be a standalone article.

A publisher or an SEO needs to step back and assess whether a user is satisfied with deep coverage of a topic or whether a deeper treatment of it is needed by users. There are also different levels of comprehensiveness, one with granular details and another with an overview-level of coverage of details, with links to deeper coverage.

In other words, sometimes users require a view of the forest and sometimes they require a view of the trees.

Google has long been able to rank document passages with their passage ranking algorithms. Ultimately, in my opinion, it really comes down to what is useful to users and is likely to result in a higher level of user satisfaction.

If comprehensive topic coverage excites people and makes them passionate enough about to share it with other people then that is a win.

If comprehensive coverage isn’t useful for that specific topic then it may be better to split the content into shorter coverage that better aligns with the reasons why people are coming to that page to read about that topic.

Takeaways

While most of these takeaways aren’t represented in Mueller’s response, they do in my opinion represent good practices for SEO.

  • HTML size limits belie a concern for deeper questions about content length and indexing visibility
  • Megabyte thresholds are rarely a practical constraint for real-world pages
  • Counting bytes is less useful than verifying whether content actually appears in search
  • Searching for distinctive passages is a practical way to confirm indexing
  • Comprehensiveness should be driven by user intent, not crawl assumptions
  • Content usefulness and clarity matter more than document size
  • User satisfaction remains the deciding factor in content performance

Concern over how many megabytes are a hard crawl limit for Googlebot reflect uncertainty about whether important content in a long document is being indexed and is available to rank in search. Focusing on megabytes shifts attention away from the real issues SEOs should be focusing on, which is whether the topic coverage depth best serves a user’s needs.

Mueller’s response reinforces the point that web pages that are too big to be indexed are uncommon, and fixed byte limits are not a constraint that SEOs should be concerned about.

In my opinion, SEOs and publishers will probably have better search coverage by shifting their focus away from optimizing for assumed crawl limits and instead focus on user content consumption limits.

But if a publisher or SEO is concerned about whether a passage near the end of a document is indexed, there is an easy way to check the status by simply doing a search for an exact match for that passage.

Comprehensive topic coverage is not automatically a ranking problem, and it not always the best (or worst) approach. HTML size is not really a concern unless it starts impacting page speed. What matters is whether content is clear, relevant, and useful to the intended audience at the precise levels of granularity that serves the user’s purposes.

Featured Image by Shutterstock/Krakenimages.com

https://www.searchenginejournal.com/how-check-if-entire-document-is-indexed/566661/


The Shift From Search Sessions To Decision Sessions via @sejournal, @DuaneForrester

This one started with a question from Adorján-Csaba Demeter, a subscriber in Romania, who asked how big the behavior change could be after Google’s AI Mode Personal Search launch, and it pushed me to think past the product announcement and into the habit shift underneath it.

AI changing search is a foregone conclusion. The real story is what happens to people when search stops acting like a library and starts acting like a helper that knows what you meant, what you like, and what you have coming up next.

When effort drops, behavior changes first. Then business models change. Then the web scrambles to catch up.

Image Credit: Duane Forrester

What Google Actually Changed

Google did not just add another AI layer to results. It moved AI Mode from “answer from the web” toward “answer from the web plus your life,” starting with opt-in connections to Gmail and Google Photos for AI Pro and AI Ultra subscribers in the U.S., delivered as a Labs experiment.

That detail matters because it tells you what Google thinks the next battleground is.

Not faster answers, but stickier habits.

When the system can read your hotel confirmation in Gmail, it can plan. When it can see the kinds of trips you take in Photos, it can recommend. You stop doing the work of explaining context. You start delegating outcomes.

That is a bet on human behavior.

The three behavior shifts that will most likely follow, in order, are:

1. People ask more questions, and they ask harder questions.

Google already sees this pattern with AI Overviews. In major markets like the U.S. and India, Google says AI Overviews drive over a 10% increase in usage for the types of queries that show them. That is a habit signal, not a satisfaction claim.

When people believe the system will do more for them, they return more often, and they push further. Queries get longer. They get more specific. They get more outcome-oriented. People stop asking “what is” and start asking “what should I do.”

Personal context amplifies that shift. If the system already knows your reservations, your preferences, and your recent activity, the user has less friction and more confidence. That increases question volume.

2. Sessions end sooner, and fewer decisions happen on websites.

Here’s the part businesses need to internalize. AI does not just reduce clicks. It compresses the journey and ends sessions earlier.

Pew’s browsing-panel study found that when an AI summary appeared, users clicked a traditional search result in 8% of visits versus 15% when there was no AI summary. Pew also found users were more likely to end their browsing session after a page with an AI summary, 26% versus 16% without.

3. People shift from browsing to delegating.

This is where behavior becomes durable. Traditional search trained people to open tabs, compare sources, build their own plan, then act. AI Mode personalizes the plan inside search itself. It turns “find me information” into “help me decide.” If the system can use your life context, it can do the assembly work you used to do manually.

That is the transition from search sessions to decision sessions. A search session ends when you find information. A decision session ends when you have a recommended next step and you are ready to act.

Adoption Will Be Real, And Uneven, For A Simple Reason

People like convenience, but they do not always like the feeling of being summarized.

Pew found that among Americans who have seen AI summaries in search results, only one in five say they find them extremely or very useful. Most say somewhat useful, and 28% say not too or not at all useful.

Low-stakes categories will move fastest because the cost of being wrong is low. High-stakes categories will move slower because trust and liability show up quickly, even when the convenience is obvious.

Even with mixed sentiment, usage is already going mainstream. Deloitte’s 2025 Connected Consumer survey found 53% of surveyed consumers are either experimenting with gen AI or using it regularly, up from 38% in 2024.

The behavior change is already underway, and I think Google is trying to capture it inside its existing habit loop.

What This Does To Businesses, Even If Your SEO Is Perfect

This is where most teams get stuck. They see AI Mode and AI summaries and assume it is “just another ranking change.” It is not. It is a consumer behavior change that reshapes the economics of discovery. The shift is subtle at first, then it hits you all at once, because it changes what people consider a completed search experience.

When sessions complete in the answer layer, classic top-of-funnel traffic becomes less reliable, even if your rankings hold. The competitive line shifts to inclusion: being referenced, cited, recommended, or selected as the next step inside the plan the system generates.

To win there, build for next-step intent. Most marketing content assumes the user will land on your site and then decide. AI compresses that journey, so your content has to carry options, tradeoffs, and a clear “what to do next,” in a form that survives summarization.

Vertical Impacts, Where Behavior Shifts First

Healthcare

People already use search as a first stop for health. The Annenberg Public Policy Center found that most (79%) U.S. adults say they’re likely to look online for the answer to a question about a health symptom or condition.

And the way they search is predictable. A 2025 JMIR survey study found participants most often sought information on health conditions, 90.2%, and medication info came next, 60.3%.

As the answer layer feels more confident, people will use it for triage and next steps. It will influence which clinic they choose and how quickly they escalate a concern.

Healthcare businesses should expect:

  1. Less website traffic for broad informational topics, and more pressure on “what do I do next” moments.
  2. Increased competition to be the cited and trusted source inside AI answers.
  3. Higher stakes for accuracy and clarity, because summarization can remove nuance.

There is also a revealing warning signal here. A study of health-related AI Overviews citations, found YouTube was the single most cited source, accounting for 4.43% of citations in that dataset.

That is not an argument against AI. It is a reminder that citation sources do not automatically align with medical rigor. Businesses in healthcare need to make their evidence, authorship, and care pathways machine-readable and unambiguous.

Financial Services

Finance is already living in an “assistant” world, and that matters because it shows how quickly consumers accept delegated help when it saves effort.

Bank of America reports that Erica (their consumer AI assistant) has surpassed 3.2 billion client interactions since its 2018 launch, and clients now interact with Erica more than 2 million times per day.

That is behavior change at scale.

Meanwhile, consumers are increasingly willing to use AI for financial advice and information. ABA Banking Journal reported in September 2025 that 51% of respondents said they turn to AI to get financial advice or information, and another 27% said they are considering it.

Now when we connect the dots…

If AI Mode personalizes search around a user’s life context, financial decision-making gets pulled earlier into the assistant layer. Budgeting questions, product comparisons, “should I refinance,” “how much house can I afford,” and “what happens if I miss a payment” all become conversational.

Financial services businesses should expect:

  1. Increased competition for being the recommended next step, not just being discoverable.
  2. More pressure to publish clear, plain-language product explanations that survive summarization.
  3. A sharper separation between low-stakes guidance and regulated advice, with trust and compliance becoming part of how content gets used.

Retail And Ecommerce

Retail gets hit hard because the classic behavior pattern is tab sprawl, and AI collapses it into a shortlist.

Retail businesses should expect:

  1. Fewer browsing sessions that start with generic research and end on a product page.
  2. More “shortlist behavior,” where the system presents a handful of options and the user picks.
  3. Higher importance for product data that can be summarized cleanly, including dimensions, compatibility, return policies, and warranty terms.

If your differentiation lives in fluffy copy, it dies in the summary. If it lives in measurable attributes, verified reviews, and clear tradeoffs, it survives.

Local Services

Local services are where this gets practical fast. People search when something broke, they need help now, and they do not want homework.

AI Mode personal context will steer choices based on urgency, location, constraints, and preferences. That means “best next step” routing becomes default behavior.

Local businesses should expect:

  1. Less opportunity to win by content volume alone.
  2. More emphasis on entity clarity, service area accuracy, availability, pricing ranges, and proof of credibility.
  3. A rise in “invisible funnel” decisions, where the customer shows up ready to book because the plan already happened elsewhere.

What You Can Do Today, Without Waiting For The Dust To Settle

For Consumers

1. Decide where you want personalization, and where you do not. Personal AI is a trade. You get convenience, but you give context. Make that choice deliberately.

2. Use AI for options, then verify what has consequences. Health, money, legal, and safety decisions deserve a second look. If an answer influences a purchase, a medical step, or a contract, capture the source and key details so convenience does not erase accountability.

For Businesses

1. Stop treating clicks as the only signal that matters. Clicks will drop in many query classes, and sessions will end sooner. Measure presence in answers, citations, recommendations, and downstream conversions that happen after exposure.

2. Rebuild your content around next-step intent. Take your highest value pages and rewrite them for decision completion. Clear options. Clear tradeoffs. Clear “what to do next.”

3. Make your entity impossible to misunderstand. Clean organization signals, consistent naming, authoritative profiles, accurate locations, and structured data where relevant. When the machine layer tries to explain who you are, make it easy.

4. Publish proof, not fluff. In high-stakes verticals, show your sources, your credentials, your policies, and your constraints. AI can compress text, but it still needs real signals to anchor trust.

The Competitive Forecast, Google Versus The Rest

If AI Mode personal search takes off, the winners will not be determined by model quality alone. Distribution and habit will do most of the work.

Scenario one, Google accelerates

Google’s biggest advantage is not that it can build an assistant. It is that it can place the assistant inside a habit billions of people already have. (Android + Siri) It already sees increased usage when AI Overviews appear, over 10% in major markets for those query types.

If Google can move Personal Intelligence from paid opt-in into broader availability, and expand the connected sources beyond Gmail and Photos, it can turn search into a daily operating layer for planning and decisions. That is a habit engine.

Scenario two, the market stays plural

ChatGPT and other assistants will continue to grow because they do not live only in “search.” They live in work, writing, learning, and deep tasks. Many users will keep separate habits, one for web discovery, another for assistant workflows, at least for a while.

In a plural market, businesses must optimize for multiple answer layers, not just Google.

What To Watch In 2026

  1. Whether Google keeps Personal Intelligence as a paid feature or uses it as a default habit builder.
  2. Whether connected context expands, and which sources get added next.
  3. Whether user sentiment shifts from lukewarm to reliant or stays mixed as Pew found.
  4. How quickly session compression shows up by vertical, since that will reveal where business disruption hits first.

The Takeaway

The change to watch is not that AI can answer questions. That part is already here, and it will keep improving. The real change is that people will stop doing the assembly work they have always done in search. They will ask more, browse less, and increasingly accept plans that arrive pre-built, because it feels faster and it feels complete. Habits will change.

When that happens, power moves upward into the answer layer. Competition shifts from who ranks to who gets included, because inclusion is what influences the decision before a user ever lands on your site. The web does not disappear, but its role changes. It becomes the dependency that feeds answers, not the destination where discovery naturally occurs.

If you run a business, you cannot pause this shift. You can adapt. Build for decision completion. Make your proof easy to carry forward so it survives summarization and still earns trust. Measure what matters when the click often disappears.

More Resources:


This post was originally published on Duane Forrester Decodes.


Featured Image: Collagery/Shutterstock

https://www.searchenginejournal.com/the-shift-from-search-sessions-to-decision-sessions/566291/


Is Google Finally Cracking Down On Self-Promotional Listicles? via @sejournal, @lilyraynyc

Jump straight to examples of affected websites.

Over the past year, one of the most common tactics for gaining visibility in AI search has been for companies to publish “listicle” content on their own blogs – ranking the best companies or products in their niche and placing themselves in the No. 1 spot.

There are variations of this approach – the listicle might contain a list of the best companies, or it could also list the best products in a specific industry. The common thread is that the company publishing the blog post ranks itself, and/or its own products, in the top position.

It has also become increasingly common for companies using this tactic to collaborate with others in the same industry, mutually promoting one another in their respective listicles – a modern twist on reciprocal linking: you mention me, and I’ll mention you.

Over the past year or two, these self-serving listicles have proven to be effective at influencing traditional search rankings – and, by extension, visibility within LLMs that rely on retrieval-augmented generation (RAG) – when users search for the top companies, products, or services in a given niche.

For example, if you type “best content marketing agencies” into Google’s AI Overviews, you might see a result like this:

Image Credit: Lily Ray

When you dig into the listed sources, you’ll notice that the recommended companies are using listicle-style blogs to rank themselves as the No. 1 top content marketing agency (example articles from Omniscient, Ten Speed, and Optimist are shown as sources above).

Search queries containing “best” tend to return recent results both in the search results and within LLM responses. For example, when a user is looking for the “best accounting software for small business,” Google often prominently ranks articles that were published or updated within the last year, and ChatGPT also generates fan-out queries containing “2026” to ensure the user’s query pulls up recent information:

Image Credit: Lily Ray

Therefore, part of this approach is to ensure that the article is either recently published, and/or recently updated with the current year in the title, to benefit from the search results and LLMs prioritizing recent results for these queries.

The Gray Area Of SEO

I consider this tactic to fall into the “gray area” of SEO. SEO strategies are often labeled as “white hat” or “black hat”—shorthand for approaches that either comply with search engine policies or clearly violate them and are treated as spam. Some tactics, however, sit in between: they aren’t illegal or overtly malicious, and not necessarily unethical, but they can be misleading to users. In many cases, they are implemented primarily for SEO benefit rather than to deliver a genuinely valuable or authentic user experience.

The concept of the “gray area” is one that SEO expert Glenn Gabe frequently references in his analysis of Google updates. His definition closely aligns with mine: a space where sites may not be explicitly violating Google’s policies, but still lack strong quality signals or rely on risky tactics – leaving them especially vulnerable to volatility as Google’s core systems evolve.

When evaluating where a given tactic might land, I often refer to Google’s recommendations about avoiding creating content that is written primarily for search engines, not humans. With this approach, a few of Google’s questions come into play:

  • Does the content provide original information, reporting, research, or analysis?

Although these pages often claim extensive research, that credibility is undermined by consistently ranking their own company first and by the implausibility that they have truly hired and evaluated the other competitors they rank in the listicle. Google has long recommended that review content contains real evidence of having tested the reviewed products or services. These pages almost always lack this evidence.

  • Does the title avoid exaggerating or being misleading?

Using “best” in the title implies an objective, independent evaluation. When a company ranks itself No. 1 without clear disclosure or transparent methodology, that framing can be misleading – even if the claims aren’t technically false.

  • Does the content present information in a way that makes you want to trust it?

Articles that rank the publisher’s own company as the best company introduce an inherent bias that undermines trust. Without third-party validation, reviewer credentials, or evidence of independent, objective testing, the information lacks the signals users (and Google) expect from credible reviews.

For these reasons, I haven’t been recommending these types of listicles as a sustainable strategy for building long-term visibility in organic search or AI-generated answers. They rarely provide an honest or authentic user experience, and tactics that sit in the gray area of Google’s content and spam policies have a long track record of eventually creating problems for site owners over time.

It Works, Until It Doesn’t

The challenge with SEO tactics that fall into the gray area is that they can definitely drive strong results – at least for a while. Furthermore, with the rise of AI search, we’re seeing that LLMs like ChatGPT are certainly susceptible to spammy tactics and currently lack Google’s level of sophistication in detecting and countering manipulative SEO approaches.

That said, there’s a familiar line anyone who’s followed my work has heard me say on repeat: It works, until it doesn’t.

When a tactic proves effective at driving SEO visibility and becomes widely adopted, Google (and other search engines) almost always develop ways to detect and suppress it. This pattern is what I call “the cycle of SEO” – a concept I explored in depth during my 2025 BrightonSEO keynote, shown below:

[embedded content]

I shared a few times throughout 2025 that I believe the excessive use of self-promotional listicles will be a common pattern among websites negatively impacted by upcoming Google core updates. I have also been theorizing that Google may develop new manual actions for this particular tactic (since it may be hard to identify algorithmically). Here’s a clip of me at the Profound Zero Click Search event in NYC back in October, explaining how abandoning SEO for GEO tactics can be dangerous.

Furthermore, I wasn’t the only one to caution against self-promotional listicles. Over the past year, Wil Reynolds, founder and CEO of Seer Interactive, has warned in conference talks and other resources that this approach lacks authenticity and risks undermining audience trust.

Similarly, Glenn Gabe, who also specializes in Google core update recovery, recently shared an example of a site potentially losing traffic due to excessive use of listicles. Glenn also cautioned against this approach in his 2025 December Core Update article.

However, many sites doubled down on self-promotional listicles because, despite the risks, they have proven highly effective at driving visibility in both organic search results and AI answers. Brands featured in these self-serving listicles have clearly benefited in recent months. But early signs from a recent Google update suggest the window for this tactic may be closing.

SearchingFor Clues After Google Ranking Volatility

Barry Schwartz of Search Engine Roundtable reported significant Google ranking volatility in January 2026, a couple weeks after the conclusion of the December 2025 Core Update. When volatility like this surfaces, I review affected sites to identify emerging patterns – and this time, I was surprised to see sharp visibility declines across several large brands, all beginning around the same period.

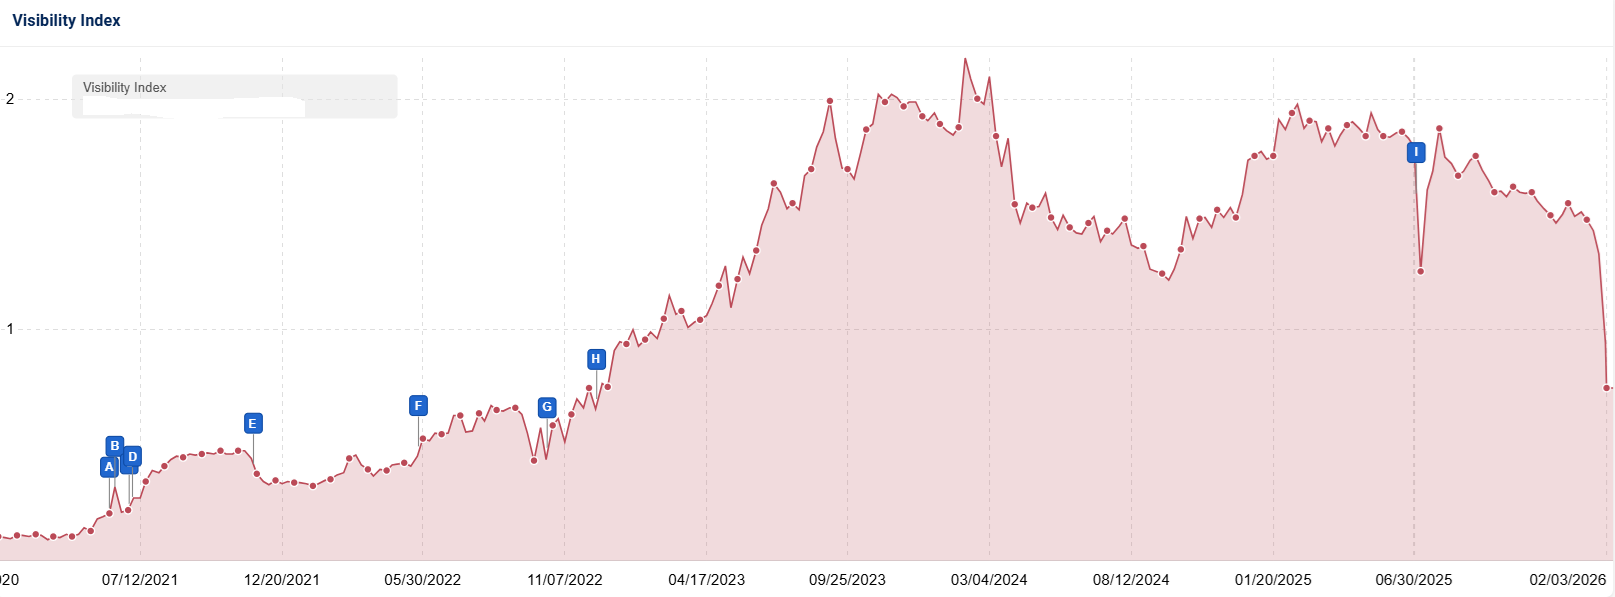
While performance drops during confirmed and unconfirmed updates can stem from many factors, a few patterns across recently impacted sites were unusually consistent this time. The first trend I noticed is that several well-known brands saw substantial organic visibility declines beginning around mid-to-late January. (I use the Sistrix U.S. Visibility Index to measure this.)

Based on the type of content I saw most heavily impacted, it seems possible this volatility reflects ongoing refinements to Google’s reviews system, which has increasingly focused on detecting self-serving, biased, or low-evidence review content.

In most cases, I also observed that the blog was the primary driver of the visibility decline, accounting for the largest share of the losses, or a similar content hub containing articles or resources.

The visibility chart below shows an example of a well-known $8B B2B brand that saw its organic visibility drop by a whopping -49% between January 21 and February 2, 2026.

Note: I have redacted company names and branded product names from all the screenshots below for the purpose of protecting the sites’ anonymity.

Image Credit: Lily Ray

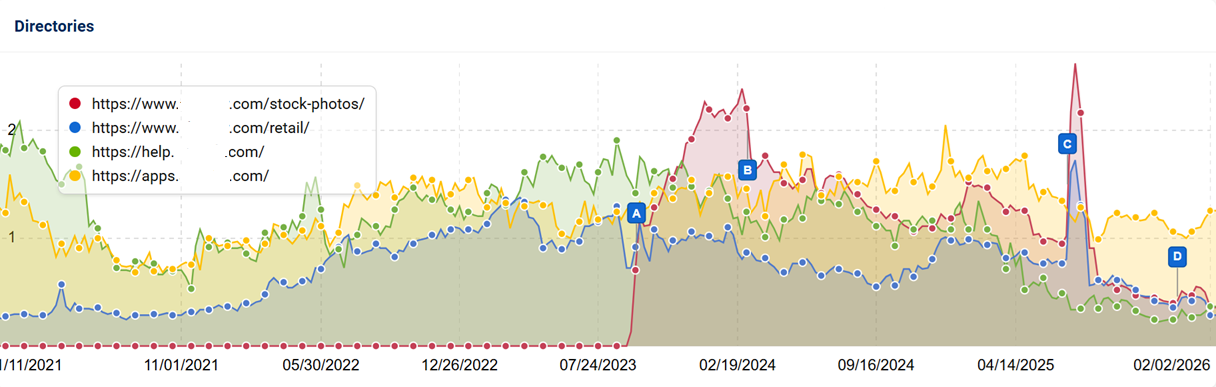
The company blog makes up 77% of this site’s visibility, and it shows a massive visibility decline since mid-January 2026:

Image Credit: Lily Ray

Other subfolders and subdomains on the site showed much smaller declines, or even visibility gains, during the same time period:

Image Credit: Lily Ray

I dug through the blog articles to look for common patterns employed by sites negatively impacted by algorithm updates, and did see some of the common culprits: highly-similar programmatic content templates, excessive informational content targeting various “who, what, when” search terms, and over-use of ‘2026’ across titles, despite the year being only four weeks underway.

But something else stood out: the blog contained dozens of self-promotional listicles. 191 of them, to be precise. By self-promoting listicles, I mean an article containing “best” where the company lists itself as the No. 1 best. You can easily detect this with the following search on Google (replace with your site’s details):

site:company.com/blog/ intitle:best “1. company”

or

site:company.com/blog/ “best” “1. company”

Image Credit: Lily Ray

Now, I must point out that this company’s blog has ~30,000 articles indexed on Google, so 191 is a drop in the bucket. That said, producing 191 self-promotional listicle articles feels more like an intentional strategy than an accident.

Here is another example of a SaaS company that was hit hard beginning around January 19. The site dropped in overall Google organic search visibility by -43% since the recent ranking volatility began.

Image Credit: Lily Ray

Approximately ~85% of the site’s organic visibility stems from its /guide/ folder, which saw the most significant visibility drop:

Image Credit: Lily Ray

Looking through the /guide/ folder shows dozens of educational articles related to the site’s offerings – about 2,780 indexed articles on Google. But looking again at whether the /guide/ folder uses self-promotional “best” listicles where the company ranks itself No. 1, lo and behold – there are 228 such articles:

Image Credit: Lily Ray

The next example is a B2B/B2C SaaS company that dropped by -42% visibility since mid-January 2026.

Image Credit: Lily Ray

The vast majority of the site’s visibility comes from its /tutorials/ folder, which saw the most significant visibility decline, dropping to a visibility level the folder hadn’t seen since 2021:

Image Credit: Lily Ray

Among the 1,980 tutorials indexed in Google’s results, 76 of them are self-serving listicles, 38 of which have been updated to include “2026” in the title:

Image Credit: Lily Ray

Now, here’s another example of a B2B SaaS company that lost -38% of its organic visibility since the ranking volatility started:

Image Credit: Lily Ray

About ~80% of this site’s visibility stems from its blog, which, as with other examples, saw by far the greatest drop in visibility:

Image Credit: Lily Ray

Among the 2,790 indexed pages on the blog, 267 of them are self-promotional “best” listicles where the company ranks itself or its own products as No. 1. 76 of them use “2026” in the title tag, which could also raise some flags, given the current date.

Image Credit: Lily Ray

Next up is a popular SaaS product that dropped by -34% total visibility since the volatility started. In this case, the site had actually seen substantial SEO growth throughout 2025 and into early 2026, but the site is quickly reversing course over the last two weeks:

Image Credit: Lily Ray

This company’s blog also represents about ~90% of its total visibility, containing 7,700 indexed articles on Google. The blog also greatly contributed to the site’s rapid growth in visibility over the last year:

Image Credit: Lily Ray

Digging into the use of self-promotional articles on this site’s blog, it turns out the site has 340 such articles on its blog that list its own company or its products as the No. 1 best in the space:

Image Credit: Lily Ray

The next site is a software company that appears to have launched its company blog around July of 2025. The blog represents about 93% of the site’s overall SEO visibility. Below is a view of the full site’s visibility trajectory:

Image Credit: Lily Ray

And below is a view of just the blog subfolder’s visibility. For this site, the drop appears to have started during the December Core Update, and was exacerbated by movement in recent weeks:

Image Credit: Lily Ray

Looking at the 1,420 articles on this company’s blog, 61 of them (4%) are self-promotional listicles:

Image Credit: Lily Ray

Lastly, here is an example of another SaaS company and digital marketing provider that lost -29% of its organic visibility since mid-January, 2026:

Image Credit: Lily Ray

The /blog/ folder on this site represents over 90% of the site’s organic visibility in Google search, containing 1,700 indexed results on Google:

Image Credit: Lily Ray

This site had only 10 self-promotional listicles, an extremely small number overall. Even so, if pages like these are truly contributing to the visibility decline, it underscores how heavily Google may be weighting them in its evaluations.

Image Credit: Lily Ray

Common Trends Among Affected Sites

It’s important to note that self-promotional listicles are only one tactic among many used by these sites in their content strategies, alongside other approaches that may be perceived by Google as prioritizing SEO over “helpful, reliable information that’s created to benefit people.”

That said, there are some other commonalities among these sites that are worth pointing out:

  • All of these sites are in the SaaS space, which could suggest that they are likely to be paying close attention to recent SEO/GEO trends.
    • Many of the blogs and resource centers actually contained specific guidance around GEO and AI search.
  • Many of these sites had recently scaled content quickly, which could be an indication that they are using (or over-utilizing) AI to quickly scale content, perhaps with insufficient human oversight.
  • I dropped several of these articles into originality.ai’s AI detection tool, and all returned a 100% confidence score that the text is AI-generated.
Image Credit: Lily Ray
  • The blogs were using other tactics I have seen get sites in trouble with during Google’s algorithm updates: artificial refreshining (including recent dates when the article was not substantially updated); Schema.org violations, such as misusing AggregateRating Schema across ineligible pages; excessive informational/definition-based content, content that is overly salesy and/or strays from the main purpose of the site, and heavy automation/programmatic templates scaled across hundreds or thousands of pages

It’s also important to note that I found examples of a few sites that saw heavy performance declines in their blogs, but were not over-utilizing self-promotional listicles in their content. That said, they were using other tactics that could affect performance, often tied to review articles and other articles leveraging highly-similar. programmatic page templates:

Image Credit: Lily Ray

Self-promotional listicles may only tell one part of the story. That said, given that this approach was common among all the companies with the largest drops (and other companies not included in this article), it looks to me like a major likely culprit worth considering when evaluating the overall quality of these blogs and resource centers.

The Impact Of Declining SEO Visibility On AI Search

SEO and AI search performance are closely tied together, especially Google’s AI search results and other LLMs that scrape Google. I spoke to Glenn Gabe, who has also been monitoring the same sites, seeing declines, and he just shared this article today showing how these four sites are rapidly losing visibility in AI Overviews. Note that all four of these sites were included in the examples shown throughout this article:

Presumably, these drops in Google organic results will also impact visibility across other LLMs that leverage Google’s search results, which extends beyond Google’s ecosystem of AI search products like Gemini and AI Mode, but is also likely to include ChatGPT.

I will dig into these outcomes as much as possible in the coming days and share what I find.

Wrapping Up

Self-promotional “best” listicles have proven to be an effective shortcut to visibility in both traditional search and AI-generated answers (GEO) – but new data suggests that shortcut may be contributing to performance declines in SEO.

Note: Yes, it’s still possible to find examples of this approach working. Like all SEO hacks, it can take a while for Google to demote the tactic across the board, and the results are not always perfect. Some listicles will surely continue to perform.

But as Google continues to refine how it evaluates quality, intent, and trust – especially in review-style content – tactics that prioritize self-promotion over genuine evaluation appear increasingly risky.

While these pages may still drive short-term gains and have shown success in AI search, the recent volatility signals that long-term visibility in both organic search and AI systems is more likely to favor content grounded in real-world experience, transparent methodology, and demonstrable value to users. As with many SEO trends before it, what works today may quietly become a liability tomorrow.

More Resources: 


This post was originally published on Lily Ray Substack.


Featured Image: Tetiana Yurchenko/Shutterstock

https://www.searchenginejournal.com/is-google-finally-cracking-down-on-self-promotional-listicles/566529/


Google Search Hits $63B, Details AI Mode Ad Tests via @sejournal, @MattGSouthern

Alphabet reported Q4 2025 revenue of $113.8 billion, beating Wall Street estimates and marking the company’s first year above $400 billion in annual revenue. Google Search grew 17% to $63.07 billion.

On the earnings call, the company revealed how it plans to monetize AI Mode and shared new data on how AI is changing search behavior.

What’s Happening

Google Search and other advertising revenue hit $63.07 billion, up 17% from $54.03 billion in Q4 2024. Search growth accelerated through 2025, rising from 10% in Q1 to 12% in Q2 to 15% in Q3 and 17% in Q4.

CEO Sundar Pichai said Search had more usage in Q4 than ever before. He attributed the growth to AI features changing how people search.

Pichai said on the call:

“Once people start using these new experiences, they use them more. In the US, we saw daily AI Mode queries per user double since launch.”

Queries in AI Mode are three times longer than traditional searches, and a “significant portion” lead to follow-up questions.

AI Mode Monetization Tests

Chief Business Officer Philipp Schindler said Google is “in the early stages of experimenting with AI Mode monetization, like testing ads below the AI response, with more underway.”

On Direct Offers, a new pilot program, Schindler said:

“We announced Direct Offers, a new Google Ads pilot, which will allow advertisers to show exclusive offers for shoppers who are ready to buy, directly in AI Mode.”

Google also plans to launch checkout directly within AI Mode from select merchants.

Schindler said the longer AI Mode queries are creating new ad inventory. Gemini’s understanding of intent “has increased our ability to deliver ads on longer, more complex searches that were previously challenging to monetize.”

YouTube Miss Explained

YouTube ad revenue reached $11.38 billion, up 9% but below the $11.84 billion analysts expected.

Schindler attributed the miss to election ad lapping from Q4 2024:

“On the brand side, as an ad share, the largest factor negatively impacting the year-over-year growth rate was lapping the strong spend on U.S. elections.”

He also noted that subscription growth can reduce ad revenue. When users switch to YouTube Premium, it hurts ad revenue but helps the overall business.

What Else Happened

Google Cloud revenue jumped 48% to $17.66 billion. Alphabet plans to spend $175 billion to $185 billion on capital expenditures in 2026, nearly double its 2025 spending. That suggests more AI features coming to Search and other products.

Why This Matters

Looking back a year ago at Q4 2024 results, Search grew 12%. By Q1 2025, AI Overviews reached 1.5 billion monthly users, and Search was growing 10%. Now Search growth has accelerated to 17%.

The metrics Google celebrated on this call describe users staying on Google longer. Schindler described the new ad inventory as additive, reaching queries that were “previously challenging to monetize.”

That’s a monetization win for Google. The tradeoff to watch is referral traffic.

When asked about cannibalization, Pichai said Google hasn’t seen evidence of it:

“The combination of all of that I think creates an expansionary moment. I think it’s expanding the type of queries people do with Google overall.”

That may be true for queries. Whether it holds for referral traffic is something you’ll need to track in your own analytics.

Looking Ahead

Google maintains the position that AI features expand search activity rather than cannibalize it. The Q4 revenue numbers back it up.

The open question is what expanding AI Mode features means for referral traffic, and your own analytics will tell that story.


Featured Image: Rokas Tenys/Shutterstock

https://www.searchenginejournal.com/google-search-hits-63b-details-ai-mode-ad-tests/566613/


The Real SEO Skill No One Teaches: Problem Deduction via @sejournal, @billhunt

Most SEO failures are not optimization failures. They are reasoning failures that occur before optimization even begins.

In enterprise SEO escalations, the pattern is remarkably consistent. Teams jump straight to causes, debate theories, and assign blame before anyone clearly articulates the actual problem they are trying to understand.

Once blame enters the conversation, problem definition disappears. Teams shift into CYA mode, and without a shared understanding of the problem, every proposed fix becomes guesswork.

The Failure Pattern Everyone Recognizes

If you’ve worked in enterprise SEO long enough, you’ve seen this meeting.

A stakeholder raises an issue. Google is showing the wrong title or site name. Search visibility dropped. A location isn’t represented correctly. The room doesn’t go quiet. It fills with explanations.

Someone points to a lack of internal links. Another suggests Google rewrote the titles. Yet another CMS defect is mentioned. A recent Google update is blamed. Someone inevitably asks whether hreflang is broken.

Each explanation sounds plausible in isolation. Each reflects real experience. But none of them is grounded in a clearly stated problem.

Everyone is trying to be helpful. No one has actually said what outcome the system produced.

SEO discussions often collapse not because teams lack expertise, but because they skip the most important step: precisely describing the system outcome they are trying to explain.

Meeting Two: Activity Without Clarity

What usually follows is a second meeting. On the surface, it feels productive.

Teams arrive having done work. The CMS has been reviewed. A detailed technical SEO audit is complete. Google update trackers and industry forums have been checked for similar impacts, along with LinkedIn commentary. Multiple diagnostic tools have been run.

There is evidence of many man-hours of activity presented. There are screenshots of issues and non-issues, and it all looks like progress toward a resolution. In reality, it is often a misdirected effort.

If the original problem was vague or incorrectly framed, all of that analysis is aimed at the wrong target. Only later does the realization set in. While the audits detected issues, they are not related to this problem.

Time and attention were spent validating assumptions instead of diagnosing system behavior.

That’s not an execution failure. It’s a problem definition failure.

Why SEO Conversations Go Off The Rails

That failure isn’t accidental. It’s structural, and SEO is uniquely exposed to it.

I have often been critical, stating that the search industry lacks root cause analysis. That’s true, but it’s not because teams aren’t trying. There is no shortage of audits, checklists, or prescriptive processes when a traffic drop or SERP anomaly appears. The problem is that those tools narrow thinking rather than clarify it. They push teams toward doing something before anyone has agreed on what actually happened.

In many SEO conversations, signals are treated as probabilistic guesses rather than observed outcomes. Rankings fluctuate, a listing looks different, traffic dips, and the discussion quickly drifts toward familiar explanations. Google must have changed something. A ranking factor shifted. An update rolled out.

What gets missed is far more mundane and far more common. Control is spread across teams. Changes are made inside one department and are never communicated to another. Content, templates, navigation, schema, analytics, and infrastructure evolve independently. Cause and effect don’t move in straight lines, and no single team sees the whole system.

When no one clearly states the outcome the system produced, the group defaults to what feels responsible: activity.

Root cause analysis turns into a checklist exercise. Teams start debating causes before agreeing on the outcome itself. Meetings fill with effort, artifacts, and action items, but clarity never quite arrives.

Systems, however, don’t respond to effort. They respond to inputs.

The Missing Skill: Problem Deduction

The most important SEO skill isn’t keyword research, schema, technical audits, GEO, or any other optimization acronym that happens to be in fashion. Those are all processes and tools. Useful ones. But they only matter after the real work has been done. That work is problem deduction.

Problem deduction is the discipline of slowing the conversation down long enough to understand what the system actually produced, not what the team expected it to produce. It requires stepping outside of assumptions, resisting familiar explanations, and describing the outcome in neutral terms before trying to fix anything.

Only then does real analysis begin. Teams can reason backward through the signals that contributed to the outcome, distinguish between inputs they can change and constraints they inherited, and act without blame or superstition driving the discussion.

In practice, problem deduction means the ability to:

  • Observe a system outcome without bias, focusing on what the system produced rather than what was intended.
  • Describe that outcome precisely and neutrally, without embedding assumptions about cause.
  • Reason backward through contributing signals, identifying which inputs could plausibly influence the result.
  • Separate fixable inputs from historical constraints, so effort is spent where it can actually matter.
  • Act without blame or superstition, keeping decisions grounded in evidence rather than instinct.

This doesn’t replace technical SEO or root cause analysis. It makes them possible.

Problem deduction is systems thinking applied to search. And almost no one teaches it.

A Real-World Enterprise Example

Recently, I reviewed an enterprise case where a client was frustrated that Google consistently displayed a specific location as the site name, regardless of the user’s location or query intent. The conversation followed a familiar arc. At first, explanations came quickly. Someone pointed to internal linking, noting that this location had accumulated more authority over time. Others suggested Google’s automatic title rewrites were to blame. The CMS came up, along with the possibility of injected or inconsistent code. SEO implementation gaps were also mentioned. Each explanation sounded reasonable. All of them were based on real experience. But none of them described the outcome. So we stopped the discussion and reset the conversation by stating the problem plainly:

Google selected a location, not the brand name, as the site name representing the brand in search results.

That single sentence changed the tone of the room. Once the outcome was clearly defined, the reasoning became straightforward. The discussion shifted from speculation to diagnosis, and the signals that led to that result became much easier to trace.

How Google Actually Made That Decision

Google wasn’t confused. It was responding to a consistent set of reinforcing signals.

Once the outcome was clearly defined, the explanation stopped being mysterious. Several independent signals all pointed to the same conclusion, and Google simply followed the strongest, most consistent path.

1. Misapplied WebSite Schema

One issue started at the structural level. Location pages had been marked up as if each were a separate website entity, rather than reinforcing the primary brand domain. Multiple pages effectively claimed to be “the website,” diluting canonical authority and causing the schema signal to cancel itself out through duplication. Google didn’t misunderstand the markup. It received conflicting declarations and discounted them logically.

2. Title Tag Dilution

At the same time, title tags failed to reinforce a clear hierarchy. The homepage HTML title tag attempted to carry too much information at once, referencing the marketing tagline first, then the brand and first location, and finally the other locations, separated by commas, into a single tag. Instead of clarifying the relationship between the brand and locations, the structure blurred it. Google responded by favoring the location that was most consistently reinforced across signals. Google favored the most consistently reinforced location, not arbitrarily, but logically.

3. External Corroboration Bias

External signals reinforced the same outcome. Inbound links, citations, and references disproportionately pointed to a single location. From Google’s perspective, the broader web corroborated what on-site signals already suggested. One location appeared to represent the brand more clearly than the others. This wasn’t favoritism. It was corroboration.

What Could Be Easily Fixed And What Couldn’t

Once the actual problem was clearly identified, the conversation changed. The issue wasn’t that Google was behaving unpredictably. It was that something in the system was consistently telling Google to treat a single location as the site name rather than the brand itself.

With the problem framed that way, analysis became practical. Instead of debating theories, we could examine the systems that contributed to that outcome and begin correcting them. Just as importantly, it allowed us to distinguish between changes that could be made immediately and those that would require sustained effort.

Some corrections were straightforward. Because the schema was generated programmatically, the WebSite markup could be adjusted immediately to reinforce the primary brand entity. The brand team also agreed to simplify the homepage title, focusing it on the brand and tagline, while allowing individual location pages to carry the weight of location-specific signals.

Other signals were less malleable. External corroboration, built up through years of links and citations pointing to a single location, couldn’t be reversed quickly. That work would take time and consistent reinforcement.

Problem deduction didn’t just tell us what to fix. It told us where to start, what to expect, and how much effort each correction would realistically require.

SEO teams waste enormous effort trying to “fix” things that can only change gradually. Problem deduction helps teams focus on directional correction rather than instant reversal.

Why Root Cause Analysis Often Fails In SEO

Root cause analysis breaks down when teams try to answer “why” before agreeing on “what.”

In enterprise SEO, that failure is amplified by how work is organized. Control is decentralized across content, engineering, analytics, brand, legal, localization, and platform teams. No single group owns the full system, yet everyone is accountable to their own KPIs. When an anomaly appears, the instinct isn’t to describe the outcome carefully. It’s to protect territory.

Conversations shift quickly. Causes are proposed before outcomes are defined. Responsibility is implied, then deflected. Each team points to the part of the system it doesn’t control. The discussion becomes less about understanding behavior and more about avoiding fault.

At the same time, the process itself narrows thinking. Root cause analysis turns into a checklist exercise. Teams reach for audits, tools, and familiar diagnostic steps, not because they are wrong, but because they are safe. Checklists create motion without requiring agreement, and activity becomes a substitute for clarity.

When internal explanations feel uncomfortable or politically risky, attention often shifts outward. Someone cites a recent Google update. Another references a post from a well-known SEO or a chart showing sector-wide volatility. External signals offer a kind of relief. If “everyone” is seeing impact, then no one internally has to explain their system.

But those signals are rarely diagnostic. Used too early, they short-circuit reasoning rather than support it.

The result is a familiar pattern. Meetings generate effort, artifacts, and action items, but the outcome itself remains vaguely defined. Teams stay busy. Nothing really changes.

Problem deduction interrupts that cycle. It forces agreement on what the system actually produced before explanations, defenses, or fixes enter the conversation. Once the outcome is clearly defined, decentralization becomes navigable, blame loses its power, and root cause analysis shifts from performance to purpose.

That’s when it starts working.

The Skill Enterprises Should Be Hiring For First

Not long ago, an advisory client asked me a deceptively simple question while defining a new enterprise search role.

“What is the single most important skill we should hire for?”

They were expecting a familiar answer. Something about technical SEO depth, AI search experience, schema expertise, or platform fluency. That’s usually how these conversations go.

I didn’t give them any of those. Instead, I said critical reasoning.

There was a pause.

Despite what many people in the search industry believe, technical skills are the easy part. Tools can be learned. Platforms change. Gaps get closed. Teams adapt. What’s far harder to teach is the ability to think clearly when the system doesn’t behave the way you expected it to.

Enterprise SEO is full of that kind of ambiguity. Signals conflict. Outcomes are indirect. Ownership is fragmented. And when things go wrong, pressure builds quickly.

In those moments, the people who struggle most aren’t the ones who lack tactical knowledge. They’re the ones who can’t slow the conversation down long enough to reason.

The skill that matters is the ability to observe what the system actually produced without bias, describe it precisely, separate symptoms from causes, reason backward through contributing signals, and resist the urge to jump to conclusions or assign blame.

In other words, problem deduction.

Specifically (as highlighted above), the ability to:

  • Observe a system outcome without bias.
  • Describe it precisely.
  • Separate symptoms from causes.
  • Reason backward through contributing signals.
  • Resist jumping to conclusions or assigning blame.

I told them plainly: We can teach the mechanics of search. What’s nearly impossible to teach is how to reason critically if that muscle isn’t already there. People either have it or they don’t. Enterprise SEO punishes the absence of that skill more than almost any other digital discipline.

This Is Bigger Than SEO

Once you recognize the pattern, it becomes hard to unsee.

The same failure mode that derails root cause analysis also explains why SEO so often turns political. When outcomes aren’t clearly defined, teams fill the gap with narratives. Best practices harden into superstition. Google updates become a convenient external explanation for internal incoherence. Infrastructure issues quietly masquerade as ranking problems because they’re harder to confront directly.

None of this happens because teams are careless. It happens because modern digital systems are fragmented by design.

As described earlier, control is decentralized across content, engineering, analytics, brand, legal, localization, and platform teams. No one owns the entire system, yet everyone is accountable to their own KPIs. When something goes wrong, describing the outcome precisely feels risky. It invites scrutiny. It raises uncomfortable questions about ownership and handoffs.

So conversations drift. Causes are debated before outcomes are agreed upon. Responsibility is implied, then deflected. Checklists replace reasoning because they allow motion without alignment. And when internal explanations feel politically unsafe, attention shifts outward – to Google updates, industry chatter, or gurus diagnosing sector-wide volatility.

Those external signals provide relief, but not resolution. They describe correlation, not causation. They offer context, not clarity and allow organizations to stay busy without ever confronting how their own systems produced the result.

This is where SEO begins to overlap with something broader: findability.

Whether someone encounters a brand through Google, an AI assistant, a marketplace, or a vertical search engine, the underlying questions are the same. Are we present? Are we represented clearly and consistently? Does that representation invite deeper engagement, or does it confuse and fragment trust?

Those outcomes don’t depend on isolated optimizations. They depend on coherent systems that behave predictably across surfaces.

Problem deduction is what makes that coherence possible. By forcing agreement on what the system actually produced before explanations or fixes enter the room, it cuts through decentralization, neutralizes blame, and restores reasoning. Root cause analysis stops being performative and starts serving its purpose.

That’s when the conversation changes. And that’s when progress actually begins.

The Real Takeaway

Google didn’t choose the wrong site name. It chose the only version of the brand the system clearly defined.

The real SEO skill isn’t knowing what to change. It’s knowing what actually happened before you touch anything at all.

Until enterprises teach, hire for, and reward problem deduction, SEO conversations will continue to spin in circles, fixing symptoms while the system quietly reinforces the same outcomes.

And no amount of optimization can fix a problem that was never clearly defined in the first place.

More Resources:


Featured Image: KitohodkA/Shutterstock

https://www.searchenginejournal.com/the-real-seo-skill-no-one-teaches-problem-deduction/566071/


Why SEO Roadmaps Break In January (And How To Build Ones That Survive The Year) via @sejournal, @cshel

SEO roadmaps have a lot in common with New Year’s resolutions: They’re created with optimism, backed by sincere intent, and abandoned far sooner than anyone wants to admit.

The difference is that most people at least make it to Valentine’s Day before quietly deciding that daily workouts or dry January were an ambitious, yet misguided, experiment. SEO roadmaps often start unraveling while Punxsutawney Phil is still deep in REM sleep.

By the third or fourth week of the year, teams are already making “temporary” adjustments. A content cadence slips here. A technical initiative gets deprioritized there. A dependency turns out to be more complicated than anticipated, etc. None of this is framed as failure, naturally, but the original plan is already being renegotiated.

This doesn’t happen because SEO teams are bad at planning. It happens because annual SEO roadmaps are still built as if search were a stable environment with predictable inputs and outcomes.

(Narrator: Search is not, and has never been, a stable environment with predictable inputs or outcomes.)

In January, just like that diet plan, the SEO roadmap looks entirely doable. By February, you’re hiding in a dark pantry with a sleeve of Thin Mints, and the roadmap is already in tatters.

Here’s why those plans break so quickly and how to replace them with a planning model that holds up once the year actually starts moving.

The January Planning Trap

Annual SEO roadmaps are appealing because they feel responsible.

  • They give leadership something concrete to approve.
  • They make resourcing look predictable.
  • They suggest that search performance can be engineered in advance.

Except SEO doesn’t operate in a static system, and most roadmaps quietly assume that it does.

By the time Q1 is halfway over, teams are already reacting instead of executing. The plan didn’t fail because it was poorly constructed. It failed because it was built on outdated assumptions about how search works now.

Three Assumptions That Break By February

1. Algorithms Behave Predictably Over A 12-Month Period

Most annual roadmaps assume that major algorithm shifts are rare, isolated events.

That’s no longer true.

Search systems are now updated continuously. Ranking behavior, SERP layouts, AI integrations, and retrieval logic evolve incrementally –  often without a single, named “update” to react to.

A roadmap that assumes stability for even one full quarter is already fragile.

If your plan depends on a fixed set of ranking conditions remaining intact until December, it’s already obsolete.

2. Technical Debt Stays Static Unless Something “Breaks”

January plans usually account for new technical work like migrations, performance improvements, structured data, internal linking projects.

What they don’t account for is technical debt accumulation.

Every CMS update, plugin change, template tweak, tracking script, and marketing experiment adds friction. Even well-maintained sites slowly degrade over time.

Most SEO roadmaps treat technical SEO as a project with an end date. In reality, it’s a system that requires continuous maintenance.

By February, that invisible debt starts to surface – crawl inefficiencies, index bloat, rendering issues, or performance regressions – none of which were in the original plan.

3. Content Velocity Produces Linear Returns

Many annual SEO plans assume that content output scales predictably:

More content = more rankings = more traffic

That relationship hasn’t been linear for a long time.

Content saturation, intent overlap, internal competition, and AI-driven summaries all flatten returns. Publishing at the same pace doesn’t guarantee the same impact quarter over quarter.

By February, teams are already seeing diminishing returns from “planned” content and scrambling to justify why performance isn’t tracking to projections.

What Modern SEO Roadmap Planning Actually Looks Like

Roadmaps don’t need to disappear, but they do need to change shape.

Instead of a rigid annual plan, resilient SEO teams operate on a quarterly diagnostic model, one that assumes volatility and builds flexibility into execution.

The goal isn’t to abandon strategy. It’s to stop pretending that January can predict December.

A resilient model includes:

  • Quarterly diagnostic checkpoints, not just quarterly goals.
  • Rolling prioritization, based on what’s actually happening in search.
  • Protected capacity for unplanned technical or algorithmic responses.
  • Outcome-based planning, not task-based planning.

This shifts SEO from “deliverables by date” to “decisions based on signals.”

The Quarterly Diagnostic Framework

Instead of locking a yearlong roadmap, break planning into repeatable quarterly cycles:

Step 1: Assess (What Changed?)

At the start of each quarter, and ideally again mid-quarter, evaluate:

  • Crawl and indexation patterns.
  • Ranking volatility across key templates.
  • Performance deltas by intent, not just keywords.
  • Content cannibalization and decay.
  • Technical regressions or new constraints.

This is not a full audit. It’s a focused diagnostic designed to surface friction early.

Step 2: Diagnose (Why Did It Change?)

This is where most roadmaps fall apart: They track metrics but skip interpretation.

Diagnosis means asking:

  • Is this decline structural, algorithmic, or competitive?
  • Did we introduce friction, or did the ecosystem change around us?
  • Are we seeing demand shifts or retrieval shifts?

Without this layer, teams chase symptoms instead of causes.

Step 3: Fix (What Actually Matters Now?)

Only after diagnosis should priorities shift. That shift may involve pausing content production, redirecting engineering resources, or deliberately doing nothing while volatility settles. Resilient planning accepts that the “right” work in February may bear little resemblance to what was approved in January.

How To Audit Mid-Quarter Without Panicking

Mid-quarter reviews don’t mean throwing out the plan. They mean stress-testing it.

A healthy mid-quarter SEO check should answer three questions:

  1. What assumptions no longer hold?
  2. What work is no longer high-leverage?
  3. What risk is emerging that wasn’t visible before?

If the answer to any of those changes execution, that’s not failure. It’s adaptive planning.

The teams that struggle are the ones afraid to admit the plan needs to change.

The Bottom Line

The acceleration introduced by AI-driven retrieval has shortened the gap between planning and obsolescence.

January SEO roadmaps don’t fail because teams lack strategy. They fail because they assume a level of stability that search has not offered in years. If your SEO plan can’t absorb algorithmic shifts, technical debt, and nonlinear content returns, it won’t survive the year. The difference between teams that struggle and teams that adapt is simple: One plans for certainty, the other plans for reality.

The teams that win in search aren’t the ones with the most detailed January roadmap. They’re the ones that can still make good decisions in February.

More Resources:


Featured Image: Anton Vierietin/Shutterstock

https://www.searchenginejournal.com/why-seo-roadmaps-break-and-how-to-build-ones-that-survive-the-year/565586/