Why Proposal To Label Sections Of AI Generated Content Is Controvesial via @sejournal, @martinibuster
A new proposal was published for creating an HTML attribute that can be helpful for notifying crawlers what part of a web page is generated by AI. The proposal is quickly becoming relevant because of new rules coming into effect in Europe this summer, but some are questioning whether this is the right solution to that problem.

What The AI Disclosure Proposal Is

An explainer for the new proposal says that the problem this solves is to there is currently no way to indicate that a section of a web page is generated with AI. What they’re proposing is a page-level meta tag that communicates a uniform degree of AI generated content on the page and also a section-level disclosure for when just a section of a page is AI-generated.

Page-Level Disclosure

The page-level disclosure uses a meta tag with a choice of attributes that communicate how much of the content is or is not AI-generated.

<meta name="ai-disclosure" content="...">

The choice of attributes are:

  • “ai-generated” (AI-generated with human prompting and/or review)
  • “ai-assisted” (Human-authored, AI edited or refined)
  • “autonomous” (AI-generated without human oversight)
  • “mixed” (Means that sections of the page have different levels of AI involvement)
  • “none” (No AI involvement)

Element-Level Disclosure

The Element-Level disclosure relies on an attribute that can be used on any HTML element. The proposal uses two examples that rely on Semantic HTML, which can be considered to kind of exceed the parameters for which the elements were created (more on that later).

The proposal uses an example of the <section> semantic HTML element:

<section ai-disclosure=”none”>
<h2>Six-Month Investigation: City Budget Shortfall</h2>
<p>Our reporters spent six months reviewing financial records…</p>
</section>

The proposal also uses an example of the <aside> semantic HTML element:

<aside ai-disclosure=”ai-generated” ai-model=”gpt-4o” ai-provider=”OpenAI”>
<h3>AI Summary</h3>
<p>The investigation found a $4.2M discrepancy in the city’s
infrastructure fund, attributed to misclassified expenditures…</p>
</aside>

AI Disclosure

The proposal was created by David E. Weekly (LinkedIn profile), who noted that there are currently proposals that provide a more general signal that an entire web page is AI generated but nothing that labels only a section of a web page in a page that is otherwise authored by a human.

Weekly’s proposal acknowledges the reality that many web pages are partially AI generated. One example is the AI generated summaries of news content. The proposal specifically mentions news sites that contain a sidebar with AI generated summaries.

The proposal suggests creating an HTML attribute that can be applied at the section level using the <aside> HTML element, which is one of the core elements of Semantic HTML. It’s a an interesting way to leverage an existing semantic HTML element.

Weekly explains how it solves a problem:

“A news article page might contain a human-written investigation alongside an AI-generated summary sidebar. Existing approaches only support page-level disclosure (the <meta> tag proposed in whatwg/html#9479) or HTTP response-level signals (IETF draft-abaris-aicdh-00). Neither allows marking individual sections of a page, which is what 42+ commenters on the WHATWG issue identified as the key missing capability.

The EU AI Act Article 50 (effective August 2026) requires machine-readable marking of AI-generated text content, creating regulatory demand for exactly this kind of standard.”

The Aside Element Controversy

The <aside> HTML element is designed for marking off sections of content that are not a part of the main content. The <aside> element can be used for a “related articles” section and it could also be used around a block of content that is advertising (because it’s not a part of the main content). The way that is accomplished is by the use of an HTML attribute which semantically describes what that block of content is.

The definition of the <aside> element is:

“The <aside> HTML element represents a portion of a document whose content is only indirectly related to the document’s main content. Asides are frequently presented as sidebars or call-out boxes.”

So the use of the <aside> element kind of makes sense for the context of AI generated content although an argument can be made that in the context of content summaries generated by AI fits into the flow of the content and thus it can’t be <aside>, because <aside> is only semantically correct when the content is indirectly related to the document’s main content.

So, is this an imperfect solution in the context of an AI generated summary that is directly related to the document’s main content? I think it may be. Nobody in the GitHub discussion brings up this obvious disconnect in the use of the <aside> element in the context of an AI authored summary.

The core rule of the <aside> element is that it should contain tangential or supplementary information. A summary, by definition, is a condensed version of the main content. Whether the summary is AI-generated or human-written doesn’t change the semantic role on the page.

The Section Element Controversy

Using the <section> semantic HTML element is problematic because the role of this element is to group thematically related content together, with the key word being “thematic,” which refers to the subject matter, the theme, or topic of the content. It tells the browser or an assistive devices like a screen reader that everything within the section belongs to a specific topic.

The HTML spec for the <section> element is:

“A thematic grouping of content, typically with a heading.”

What a screen reader navigating a page that uses the <section> element sees:

  • Introduction
  • Methodology
  • Results
  • Conclusions
  • Future Research

Using the the <section> element to declare the authorship or origin of the content breaks the intended purpose of the <section> element and could be problematic for people visiting a site with assistive devices.

Can Be Used On Any Element

The proposal said that the attributes can be used on any HTML element but the proposal seems to lean hard on the two semantic HTML elements discussed above.  Although none of the commenters in the proposal mentioned how the proposed use of the semantic HTML elements break the Accessibility Tree, this is an aspect worth discussing. Maybe it would have been better if the author had chosen different elements as examples but the proposal as it is right now leans  heavily on those two elements to do the heavy lifting.

Not A Settled Proposal

There is a lively conversation going on in the GitHub repository for the proposal. One of the purposes of the <aside> elements relates to accessibility. The last comment on the proposal calls attention to the fact that the proposal is meant to satisfy a legal requirement but not solve an issue related to the web.

They wrote:

“I’ve reviewed the proposal and the surrounding discussion, including the arguments in favor and against. However, the more I read, the more uncertainty I have about the practical necessity of introducing additional markup at the platform level. At the moment, this approach seems primarily aimed at satisfying formal or regulatory requirements, without a clearly demonstrated benefit for the web ecosystem as a whole.”

The takeaway is that the commenter sees the proposal as compliance-driven markup that platforms would be expected to add even when it does not clearly improve the web itself, and that concern becomes sharper if the implementation pushes disclosure into existing semantic HTML elements like <aside> in cases where the disclosed content is a part of the main flow.

https://www.searchenginejournal.com/controversial-proposal-to-label-sections-of-ai-generated-content/566351/


Google Shows How To Get More Traffic From Top Stories Feature via @sejournal, @martinibuster

Google added new documentation to Search Central covering their Preferred Sources program that helps news websites get into the Top Stories feature. The documentation explains what publishers can do to make it more likely to be ranked in Top Stories and get more traffic.

Top Stories

Given that Top Stories is about breaking news, freshness may be a factor for ranking.Top Stories surfaces local news as well as breaking news. Schema structured data is not necessary to rank in Top Stories but adding Schema.org Article structured data helps Google better understand what the page is about. While the Top Stories display resembles Google’s carousel feature, the ItemList structured data for Carousel displays has no effect.

Source Preferences Tool

The preferred sources program is available only to English language web pages globally. Google also states that sites that are already in the Preferred Sources tool are eligible to deep link to encourage users to add your site as a preferred source. https://www.google.com/preferences/source

According to Google:

If your site appears in the source preferences tool, you can use the following methods to guide your readers to select your site as a preferred source:

Add the deeplink to your social posts or promotions. Use the following URL format, which takes users directly to your site in the source preferences tool:

https://google.com/preferences/source?q=Your_Website's_URL

For example, if your site is https://example.com, use the following URL:

https://google.com/preferences/source?q=example.com

Do What You Can For More Traffic From Top Stories

Getting traffic out of Google appears to be getting increasingly difficult. So it’s useful to take advantage of every available opportunity.

Featured Image by Shutterstock/RealPeopleStudio


https://www.searchenginejournal.com/google-shows-how-to-get-more-traffic-from-top-stories-feature/566329/


Google’s SAGE Agentic AI Research: What It Means For SEO via @sejournal, @martinibuster

Google published a research paper about creating a challenging dataset for training AI agents for deep research. The paper offers insights into how agentic AI deep research works, which implies insights for optimizing content.

The acronym SAGE stands for Steerable Agentic Data Generation for Deep Search with Execution Feedback.

Synthetic Question And Answer Pairs

The researchers noted that the previous state of the art AI training datasets (like Musique and HotpotQA) required no more than four reasoning steps in order to answer the questions. On the number of searches needed to answer a question, Musique averages 2.7 searches per question and HotpotQA averaged 2.1 searches. Another commonly used dataset named Natural Questions (NQ) only required an average of 1.3 searches per question.

These datasets that are used to train AI agents created a training gap for deep search tasks that required more reasoning steps and a greater number of searches. How can you train an AI agent for complex real-world deep search tasks if the AI agents haven’t been trained to tackle genuinely difficult questions.

The researchers created a system called SAGE that automatically generates high-quality, complex question-answer pairs for training AI search agents. SAGE is a “dual-agent” system where one AI writes a question and a second “search agent” AI tries to solve it, providing feedback on the complexity of the question.

  • The goal of the first AI is to write a question that’s challenging to answer and requires many reasoning steps and multiple searches to solve.
  • The goal of the second AI is try to measure if the question is answerable and calculate how difficult it is (minimum number of search steps required).

The key to SAGE is that if the second AI solves the question too easily or gets it wrong, the specific steps and documents it found (the execution trace) is fed back to the first AI. This feedback enables the first AI to identify one of four shortcuts that enable the second AI to solve the question in fewer steps.

It’s these shortcuts that provide insights into how to rank better for deep research tasks.

Four Ways That Deep Research Was Avoided

The goal of the paper was to create a set of question and answer pairs that were so difficult that it took the AI agent multiple steps to solve. The feedback showed four ways that made it less necessary for the AI agent to do additional searches to find an answer.

Four Reasons Deep Research Was Unnecessary

  1. Information Co-Location
    This is the most common shortcut, accounting for 35% of the times when deep research was not necessary. This happens when two or more pieces of information needed to answer a question are located in the same document. Instead of searching twice, the AI finds both answers in one “hop”.
  2. Multi-query Collapse
    This happened in 21% of cases. The cause is when a single, clever search query retrieves enough information from different documents to solve multiple parts of the problem at once. This “collapses” what should have been a multi-step process into a single step.
  3. Superficial Complexity
    This accounts for 13% of times when deep research was not necessary. The question looks long and complicated to a human, but a search engine (that an AI agent is using) can jump straight to the answer without needing to reason through the intermediate steps.
  4. Overly Specific Questions
    31% of the failures are questions that contain so much detail that the answer becomes obvious in the very first search, removing the need for any “deep” investigation.

The researchers found that some questions look hard but are actually relatively easy because the information is “co-located” in one document. If an agent can answer a 4-hop question in 1 hop because one website was comprehensive enough to have all the answers, that data point is considered a failure for training the agent for reasoning but it’s still something that can happen in real-life and the agent will take advantage of finding all the information on one page.

SEO Takeaways

It’s possible to gain some insights into what kinds of content satisfies the deep research. While these aren’t necessarily tactics for ranking better in agentic AI deep search, these insights do show what kinds of scenarios caused the AI agents to find all or most of the answers in one web page.

“Information Co-location” Could Be An SEO Win
The researchers found that when multiple pieces of information required to answer a question occur in the same document, it reduces the number of search steps needed. For a publisher, this means consolidating “scattered” facts into one page prevents an AI agent from having to “hop” to a competitor’s site to find the rest of the answer.

Triggering “Multi-query Collapse”
The authors identified a phenomenon where information from different documents can be retrieved using a single query. By structuring content to answer several sub-questions at once, you enable the agent to find the full solution on your page faster, effectively “short-circuiting” the long reasoning chain the agent was prepared to undertake.

Eliminating “Shortcuts” (The Reasoning Gap)
The research paper notes that the data generator fails when it accidentally creates a “shortcut” to the answer. As an SEO, your goal is to be that shortcut—providing the specific data points like calculations, dates, or names that allow the agent to reach the final answer without further exploration.

The Goal Is Still To Rank In Classic Search

For an SEO and a publisher, these shortcuts underline the value of creating a comprehensive document because it will remove the need for an AI agent from getting triggered to hop somewhere else. This doesn’t mean it will be helpful to add all the information in one page. If it makes sense for a user it may be useful to link out from one page to another page for related information.

The reason I say that is because the AI agent is conducting classic search looking for answers, so the goal remains to optimize a web page for classic search. Furthermore, in this research, the AI agent is pulling from the top three ranked web pages for each query that it’s executing. I don’t know if this is how agentic AI search works in a live environment, but this is something to consider.

In fact, one of the tests that the researchers did was conducted using the Serper API to extract search results from Google.

So when it comes to ranking in agentic AI search, consider these takeaways:

  • It may be useful to consider the importance of ranking in the top three.
  • Do optimize web pages for classic search.
  • Do not optimize web pages for AI search
  • If it’s possible to be comprehensive, remain on-topic, and rank in the top three, then do that.
  • Interlink to relevant pages to help those rank in classic search, preferably in the top three (to be safe).

It could be that agentic AI search will consider pulling from more than the top three in classic search. But it may be helpful to set the goal of ranking for the top 3 in classic search and to focus on ranking other pages that may be a part of the multi-hop deep research.

The research paper was published by Google on January 26, 2026. It’s available in PDF form:  SAGE: Steerable Agentic Data Generation for Deep Search with Execution Feedback.

Featured Image by Shutterstock/Shutterstock AI Generator

https://www.searchenginejournal.com/googles-sage-agentic-ai-research-what-it-means-for-seo/566215/


Analysis Reveals Surprises About How CMS Platforms Are Influencing Tech SEO via @sejournal, @theshelleywalsh

The Web Almanac is an annual report that translates the HTTP Archive dataset into practical insight, combining large-scale measurement with expert interpretation from industry experts.

To get insights into what the 2025 report can tell us about what is actually happening in SEO, I spoke with one of the authors of the SEO chapter update, Chris Green, a well-known industry expert with over 15 years of experience.

Chris shared with me some surprises about the adoption of llms.txt files and how CMS systems are shaping SEO far more than we realize. Little-known facts that the data surfaced in the research, and surprising insights that usually would go unnoticed.

You can watch the full interview with Chris on the IMHO recording at the end, or continue reading the article summary.

“I think the data [in the Web Almanac] helped to show me that there’s still a lot broken. The web is really messy. Really messy.”

Bot Management Is No Longer ‘Google, Or Not Google?’

Although bot management has been binary for some time – allow/disallow Google – it’s becoming a new challenge. Something that Eoghan Henn had picked up previously, and Chris found in his research.

We began our conversation by talking about how robots files are now being used to express intent about AI crawler access.

Chris responded to say that, firstly, there is a need to be conscious of the different crawlers, what their intention is, and fundamentally what blocking them might do, i.e., blocking some bots has bigger implications than others.

Second to that, requires the platform providers to actually listen to those rules and treat those files as appropriate. That isn’t always happening, and the ethics around robots and AI crawlers is an area that SEOs need to know about and understand more.

Chris explained that although the Almanac report showed the symptom of robots.txt usage, SEOs need to get ahead and understand how to control the bots.

“It’s not only understanding what the impact of each [bot/crawler] is, but also how to communicate that with the business. If you’ve got a team who want to cut as much bot crawling as possible because they want to save money, that might desperately impact your AI visibility.”

Equally, you might have an editorial team that doesn’t want to get all of their work scraped and regurgitated. So, we, as SEOs, need to understand that dynamic, how to control it technically, but how to put that argument forward in the business as well.” Chris explained.

As more platforms and crawlers are introduced, SEO teams will have to consider all implications, and collaborate with other teams to ensure the right balance of access is applied to the site.

Llms.txt Is Being Applied Despite No Official Platform Adoption 

The first surprising finding of the report was that adoption for the proposed llms.txt standard is around 2% of sites in the dataset.

Llms.txt has been a heated topic in the industry, with many SEOs dismissing the value of the file. Some tools, such as Yoast, have included the standard, but as yet, there has been no demonstration of actual uptake by AI providers.

Chris admitted that 2% was a higher adoption than he expected. But much of that growth appears to be driven by SEO tools that have added llms.txt as a default or optional feature.

Chris is skeptical of its long-term impact. As he explained, Google has repeatedly stated it does not plan to use llms.txt, and without clear commitment from the major AI providers, especially OpenAI, it risks remaining a niche, symbolic gesture rather than a functional standard.

That said, Chris has experienced log-file data suggesting some AI crawlers are already fetching these files, and in limited cases, they may even be referenced as sources. Green views this less as a competitive advantage and more as a potential parity mechanism, something that may help certain sites be understood, but not dramatically elevate them.

“Google has time and again said they don’t plan to use llms.txt which they reiterated in Zurich at Search Central last year. I think, fundamentally, Google doesn’t need it as they do have crawling and rendering nailed. So, I think it hinges on whether OpenAI say they will or won’t use it and I think they have other problems than trying to set up a new standard.”

Different, But Reassuringly The Same Where It Matters

I went on to ask Chris about how SEOs can balance the difference between search engine visibility and machine visibility.

He thinks there is “a significant overlap between what SEO was before we started worrying about this and where we are at the start of 2026.”

Despite this overlap, Chris was clear that if anyone thinks optimizing for search and machines is the same, then they are not aware of the two different systems, the different weightings, the fact that interpretation, retrieval, and generation are completely different.

Although there are different systems and different capabilities in play, he doesn’t think SEO has fundamentally changed. His belief is that SEO and AI optimization are “kind of the same, reassuringly the same in the places that matter, but you will need to approach it differently” because it diverges in how outputs are delivered and consumed.

Chris did say that SEOs will move more towards feeds, feed management, feed optimization.

“Google’s universal commerce protocol where you could potentially transact directly from search results or from a Gemini window obviously changes a lot. It’s just another move to push the website out of the loop. But the information, what we’re actually optimizing still needs to be optimized. It’s just in a different place.”

CMS Platforms Shape The Web More Than SEOs Realize

Perhaps the biggest surprise from Web Almanac 2025 was the scale of influence exerted by CMS platforms and tooling providers.

Chris said that he hadn’t realized just how big that impact is. “Platforms like Shopify, Wix, etc. are shaping the actual state of tech SEO probably more profoundly than I think a lot of people truly give it credit for.”

Chris went on to explain that “as well-intentioned as individual SEOs are, I think our overall impact on the web is minimal outside of CMS platforms providers. I would say if you are really determined to have an impact outside of your specific clients, you need to be nudging WordPress or Wix or Shopify or some of the big software providers within those ecosystems.”

This creates opportunity: Websites that do implement technical standards correctly could achieve significant differentiation when most sites lag behind best practices.

One of the more interesting insights from this conversation was that so much on the web is broken and how little impact we [SEOs] really have.

Chris explained that “a lot of SEOs believe that Google owes us because we maintain the internet for them. We do the dirty work, but I also don’t think we have as much impact perhaps at an industry level as maybe some like to believe. I think the data in the Web Almanac kind of helped show me that there’s still a lot broken. The web is really messy. Really messy.”

AI Agents Won’t Replace SEOs, But They Will Replace Bad Processes

Our conversation concluded with AI agents and automation. Chris started by saying, “Agents are easily misunderstood because we use the term differently.”

He emphasized that agents are not replacements for expertise, but accelerators of process. Most SEO workflows involve repetitive data gathering and pattern recognition, areas well-suited to automation. The value of human expertise lies in designing processes, applying judgment, and contextualizing outputs.

Early-stage agents could automate 60-80% of the work, similar to a highly capable intern. “It’s going to take your knowledge and your expertise to make that applicable to your given context. And I don’t just mean the context of web marketing or the context of ecommerce. I mean the context of the business that you’re specifically working for,” he said.

Chris would argue that a lot of SEOs don’t spend enough time customizing what they do to the client specifically. He thinks there’s an opportunity to build an 80% automated process and then add your real value when your human intervention optimizes the last 20% business logic.

SEOs who engage with agents, refine workflows, and evolve alongside automation are far more likely to remain indispensable than those who resist change altogether.

However, when experimenting with automation, Chris warned we should avoid automating broken processes.

“You need to understand the process that you’re trying to optimize. If the process isn’t very good, you’ve just created a machine to produce mediocrity at scale, which frankly doesn’t help anyone.”

Chris thinks that this will give SEOs an edge as AI is more widely adopted. “I suggest the people that engage with it and make those processes better and show how they can be continually evolved, they’ll be the ones that have greater longevity.”

SEOs Can Succeed By Engaging With The Complexity

The Web Almanac 2025 doesn’t suggest that SEO is being replaced, but it does show that its role is expanding in ways many teams haven’t fully adapted to yet. Core principles like crawlability and technical hygiene still matter, but they now exist within a more complex ecosystem shaped by AI crawlers, feeds, closed systems, and platform-level decisions.

Where technical standards are poorly implemented at scale, those who understand the systems that shape them can still gain a meaningful advantage.

Automation works best when it accelerates well-designed processes and fails when it simply scales inefficiency. SEOs who focus on process design, judgment, and business context will remain essential as automation becomes more common.

In an increasingly messy and machine-driven web, the SEOs who succeed will be those willing to engage with that complexity rather than ignore it.

SEO in 2026 isn’t about choosing between search and AI; it’s about understanding how multiple systems consume content and where optimization now happens.

Watch the full video interview with Chris Green here:

[embedded content]

Thank you to Chris Green for offering his insights and being my guest on IMHO.

More Resources: 


Featured Image: Shelley Walsh/Search Engine Journal

https://www.searchenginejournal.com/what-the-latest-web-almanac-report-reveals-about-bots-cms-influence-llms-txt/565958/


Why Global Search Misalignment Is An Engineering Feature And A Business Bug via @sejournal, @billhunt

Google’s AI Overviews (AIO) represent a fundamental architectural shift in search. Retrieval has moved from a localized ranking-and-serving model, designed to return the most appropriate regional URL, to a semantic synthesis model, designed to assemble the most complete and defensible explanation of a topic.

This shift has introduced a new and increasingly visible failure mode: geographic leakage, where AI Overviews cite international or out-of-market sources for queries with clear local or commercial relevance.

This behavior is not the result of broken geo-targeting, misconfigured hreflang, or poor international SEO hygiene. It is the predictable outcome of systems designed to resolve ambiguity through semantic expansion, not contextual narrowing. When a query is ambiguous, AI Overviews prioritize explanatory completeness across all plausible interpretations. Sources that resolve any sub-facet with greater clarity, specificity, or freshness gain disproportionate influence – regardless of whether they are commercially usable or geographically appropriate for the user.

From an engineering perspective, this is a technical success. The system reduces hallucination risk, maximizes factual coverage, and surfaces diverse perspectives. From a business and user perspective, however, it exposes a structural gap: AI Overviews have no native concept of commercial harm. The system does not evaluate whether a cited source can be acted upon, purchased from, or legally used in the user’s market.

This article reframes geographic leakage as a feature-bug duality inherent to generative search. It explains why established mechanisms such as hreflang struggle in AI-driven experiences, identifies ambiguity and semantic normalization as force multipliers in misalignment, and outlines a Generative Engine Optimization (GEO) framework to help organizations adapt in the generative era.

The Engineering Perspective: A Feature Of Robust Retrieval

From an AI engineering standpoint, selecting an international source for an AI Overview is not an error. It is the intended outcome of a system optimized for factual grounding, semantic recall, and hallucination prevention.

1. Query Fan-Out And Technical Precision

AI Overviews employ a query fan-out mechanism that decomposes a single user prompt into multiple parallel sub-queries. Each sub-query explores a different facet of the topic – definitions, mechanics, constraints, legality, role-specific usage, or comparative attributes.

The unit of competition in this system is no longer the page or the domain. It is the fact-chunk. If a particular source contains a paragraph or explanation that is more explicit, more extractable, or more clearly structured for a specific sub-query, it may be selected as a high-confidence informational anchor – even if it is not the best overall page for the user.

2. Cross-Language Information Retrieval (CLIR)

The appearance of English summaries sourced from foreign-language pages is a direct result of Cross-Language Information Retrieval.

Modern LLMs are natively multilingual. They do not “translate” pages as a discrete step. Instead, they normalize content from different languages into a shared semantic space and synthesize responses based on learned facts rather than visible snippets. As a result, language differences no longer serve as a natural boundary in retrieval decisions.

Semantic Retrieval Vs. Ranking Logic: A Structural Disconnect

The technical disconnect observed in AI Overviews, where an out-of-market page is cited despite the presence of a fully localized equivalent, stems from a fundamental conflict between search ranking logic and LLM retrieval logic.

Traditional Google Search is designed around serving. Signals such as IP location, language, and hreflang act as strong directives once relevance has been established, determining which regional URL should be shown to the user.

Generative systems are designed around retrieval and grounding. In Retrieval-Augmented Generation pipelines, these same signals are frequently treated as secondary hints, or ignored entirely, when they conflict with higher-confidence semantic matches discovered during fan-out retrieval.

Once a specific URL has been selected as the source of truth for a given fact, downstream geographic logic has limited ability to override that choice.

The Vector Identity Problem: When Markets Collapse Into Meaning

At the core of this behavior is a vector identity problem.

In modern LLM architectures, content is represented as numerical vectors encoding semantic meaning. When two pages contain substantively identical content, even if they serve different markets, they are often normalized into the same or near-identical semantic vector.

From the model’s perspective, these pages are interchangeable expressions of the same underlying entity or concept. Market-specific constraints such as shipping eligibility, currency, or checkout availability are not semantic properties of the text itself; they are metadata properties of the URL.

During the grounding phase, the AI selects sources from a pool of high-confidence semantic matches. If one regional version was crawled more recently, rendered more cleanly, or expressed the concept more explicitly, it can be selected without evaluating whether it is commercially usable for the searcher.

Freshness As A Semantic Multiplier

Freshness amplifies this effect. Retrieval-Augmented Generation systems often treat recency as a proxy for accuracy. When semantic representations are already normalized across languages and markets, even a minor update to one regional page can unintentionally elevate it above otherwise equivalent localized versions.

Importantly, this does not require a substantive difference in content. A change in phrasing, the addition of a clarifying sentence, or a more explicit explanation can tip the balance. Freshness, therefore, acts as a multiplier on semantic dominance, not as a neutral ranking signal.

Ambiguity As A Force Multiplier In Generative Retrieval

One of the most significant, and least understood, drivers of geographic leakage is query ambiguity.

In traditional search, ambiguity was often resolved late in the process, at the ranking or serving layer, using contextual signals such as user location, language, device, and historical behavior. Users were trained to trust that Google would infer intent and localize results accordingly.

Generative retrieval systems respond to ambiguity very differently. Rather than forcing early intent resolution, ambiguity triggers semantic expansion. The system explores all plausible interpretations in parallel, with the explicit goal of maximizing explanatory completeness.

This is an intentional design choice. It reduces the risk of omission and improves answer defensibility. However, it introduces a new failure mode: as the system optimizes for completeness, it becomes increasingly willing to violate commercial and geographic constraints that were previously enforced downstream.

In ambiguous queries, the system is no longer asking, “Which result is most appropriate for this user?”

It is asking, “Which sources most completely resolve the space of possible meanings?”

Why Correct Hreflang Is Overridden

The presence of a correctly implemented hreflang cluster does not guarantee regional preference in AI Overviews because hreflang operates at a different layer of the system.

Hreflang was designed for a post-retrieval substitution model. Once a relevant page is identified, the appropriate regional variant is served. In AI Overviews, relevance is resolved upstream during fan-out and semantic retrieval.

When fan-out sub-queries focus on definitions, mechanics, legality, or role-specific usage, the system prioritizes informational density over transactional alignment. If an international or home-market page provides the “first best answer” for a specific sub-query, that page is retrieved immediately as a grounding source.

Unless a localized version provides a technically superior answer for the same semantic branch, it is simply not considered.

In short, hreflang can influence which URL is served. It cannot influence which URL is retrieved, and in AI Overviews, retrieval is where the decision is effectively made.

The Diversity Mandate: The Programmatic Driver Of Leakage

AI Overviews are explicitly designed to surface a broader and more diverse set of sources than traditional top 10 search results.

To satisfy this requirement, the system evaluates URLs, not business entities, as distinct sources. International subfolders or country-specific paths are therefore treated as independent candidates, even when they represent the same brand and product.

Once a primary brand URL has been selected, the diversity filter may actively seek an alternative URL to populate additional source cards. This creates a form of ghost diversity, where the system appears to surface multiple perspectives while effectively referencing the same entity through different market endpoints.

The Business Perspective: A Commercial Bug

The failures described below are not due to misconfigured geo-targeting or incomplete localization. They are the predictable downstream consequence of a system optimized to resolve ambiguity through semantic completeness rather than commercial utility.

1. The Commercial Blind Spot

From a business standpoint, the goal of search is to facilitate action. AI Overviews, however, do not evaluate whether a cited source can be acted upon. They have no native concept of commercial harm.

When users are directed to out-of-market destinations, conversion probability collapses. These dead-end outcomes are invisible to the system’s evaluation loop and therefore incur no corrective penalty.

2. Geographic Signal Invalidation

Signals that once governed regional relevance – IP location, language, currency, and hreflang – were designed for ranking and serving. In generative synthesis, they function as weak hints that are frequently overridden by higher-confidence semantic matches selected upstream.

3. Zero-Click Amplification

AI Overviews occupy the most prominent position on the SERP. As organic real estate shrinks and zero-click behavior increases, the few cited sources receive disproportionate attention. When those citations are geographically misaligned, opportunity loss is amplified.

The Generative Search Technical Audit Process

To adapt, organizations must move beyond traditional visibility optimization towards what we would now call Generative Engine Optimization (GEO).

  1. Semantic Parity: Ensure absolute parity at the fact-chunk level across markets. Minor asymmetries can create unintended retrieval advantages.
  2. Retrieval-Aware Structuring: Structure content into atomic, extractable blocks aligned to likely fan-out branches.
  3. Utility Signal Reinforcement: Provide explicit machine-readable indicators of market validity and availability to reinforce constraints the AI does not infer reliably on its own.

Conclusion: Where The Feature Becomes The Bug

Geographic leakage is not a regression in search quality. It is the natural outcome of search transitioning from transactional routing to informational synthesis.

From an engineering perspective, AI Overviews are functioning exactly as designed. Ambiguity triggers expansion. Completeness is prioritized. Semantic confidence wins.

From a business and user perspective, the same behavior exposes a structural blind spot. The system cannot distinguish between factually correct and consumer-engagable information.

This is the defining tension of generative search: A feature designed to ensure completeness becomes a bug when completeness overrides utility.

Until generative systems incorporate stronger notions of market validity and actionability, organizations must adapt defensively. In the AI era, visibility is no longer won by ranking alone. It is earned by ensuring that the most complete version of the truth is also the most usable one.

More Resources:


Featured Image: Roman Samborskyi/Shutterstock

https://www.searchenginejournal.com/why-global-search-misalignment-is-an-engineering-feature-and-a-business-bug/563927/


How Search Engines Tailor Results To Individual Users & How Brands Should Manage It

How many times have you seen different SERP layouts and results across markets?

No two people see the same search results, as per Google’s own documentation. No two users receive identical outputs from AI platforms either, even when using the same prompt. In a time of information overload, this raises an important question for global marketers: How do we manage and leverage personalized search experiences across multiple markets?

Today, clarity and transparency matter more than ever. Users have countless choices and distractions, so they expect experiences that feel relevant, trustworthy, and aligned with their needs in the moment. Personalization is now central to how potential customers discover, evaluate, and engage with brands.

Search engines have been personalizing results for years based on language, search behavior, device type, and technical elements such as hreflang. With the quick evolution of generative artificial intelligence (AI), personalization has expanded into summarized answers on AI platforms and hyper-personalized experiences that depend on internal data flows and processes.

This shift forces marketers to rethink how they measure visibility and business impact. According to McKinsey, 76% of users feel frustrated when experiences are not personalized, which shows how closely relevance and user satisfaction are linked.

At the same time, long-tail discovery increasingly happens outside of search engines, particularly on platforms like TikTok. Statista reports that 78% of global internet users now research brands and products on social media.

All of this is happening while most users know little about how search engines or AI systems operate.

Regardless of where people search, the implications extend far beyond algorithms. Personalization affects how teams collaborate, how data moves across departments, and how global organizations define success.

This article explores what personalization means today and how global brands can turn it into a competitive advantage.

From SERPs To AI Summaries

Search engines no longer return lists of blue links alone or People Also Ask (PAA). They now provide summarized information in AI Overviews and AI Mode, currently for informational queries.

Google often surfaces AI summaries first and URLs second, while continuously testing different layouts for mobile and desktop, as shown below.

Screenshot from search for [what is a nepo baby], Google, December 2025

Google’s Search Labs experiments, including features such as Preferred Sources, show how layouts and summaries change based on context, trust signals, and behavioral patterns.

Large language models (LLMs) add another layer. They adjust responses based on user context, intent, and sometimes whether the user has a free or paid account. Because users rarely get exactly what they need on the first attempt, they re-prompt the AI, creating iterative conversations where each instruction or prompt influences the next.

What prompts users to click through to a source or research it on search engines, whether it is curiosity, uncertainty, boredom, a call-to-action, or the model stating it does not know, is still unclear. Understanding this behavior will soon be as important as traditional click-through rate (CTR) analysis.

For global brands, the challenge is not simply keeping up with technology. It’s maintaining a consistent brand voice and value exchange across channels and markets when every user sees a different interpretation of the brand. Trust is now as important as visibility.

This landscape increases the importance of market research, segmentation, cultural insights, and competitive analysis. It also raises concerns about echo chambers, search inequality, and the barriers brands face when entering new markets or reaching new audiences.

Meanwhile, the long tail continues to shift to platforms like TikTok, where discovery works very differently from traditional search. And as enthusiasm for AI cools, many professionals believe we have entered the “trough of disillusionment” stage described by Jackie Fenn’s technology adoption lifecycle.

What Personalization Means Today

In marketing, personalization refers to tailoring content, offers, and experiences based on available data.

In search, it describes how search engines customize results and SERP features for individual users using signals such as:

  • Data patterns.
  • Inferred interests.
  • Location.
  • Search behavior.
  • Device type.
  • Language.
  • AI-driven memory (which is discussed below).

The goal of search engines is to provide relevant results and keep users engaged, especially as people now search across multiple channels and AI platforms. As a result of this, two people searching the same query rarely see identical results. For example:

  • A cuisine enthusiast searching for [apples] may see food-related content.
  • A tech-oriented user may see Apple product news.

SERP features can also vary across markets and profiles. People Also Ask (PAA) questions and filters may differ by region, language, or click behavior, and may not appear at all. For example, the query “vote of no confidence” displays different filters and different top results in Spain and the UK, and PAA does not appear in the UK version.

AI platforms push this further with session-based memory. Platforms like AI Mode, Gemini, ChatGPT, and Copilot handle context in a way that makes users feel there are real conversations, with each prompt influencing the next. In some cases, results from earlier responses may also be surfaced.

A human-in-the-loop (HITL) approach is essential to evaluate, monitor, and correct outputs before using them.

How Personalization Technically Works

Personalization operates across several layers. Understanding these helps marketers see where influence is possible.

1. SERP Features And Layout

Google and Bing adapt their layouts based on history, device type, user engagement, and market signals. Featured Snippets, PAA modules, videos, forums, or Top Stories may appear or disappear depending on behavior and intent.

2. AI Overviews, AI Mode, And Bing Copilot

AI platforms can:

  • Summarize content from multiple URLs.
  • Adapt tone and depth based on user behavior.
  • Personalize follow-up suggestions.
  • Integrate patterns learnt within the session or even previous sessions.

Visibility now includes being referenced in AI summaries. Current patterns show this depends on:

  • Clear site and URL structure.
  • Factual accuracy.
  • Strong entity signals.
  • Online credibility.
  • Fresh, easily interpreted content.

3. Structured Data And Entity Consistency

When algorithms understand a brand, they can personalize results more accurately. Schema markup helps avoid entity drift, where regional websites are mistaken for separate brands.

Bing uses Microsoft Graph to connect brand data with the Microsoft ecosystem, extending the influence of structured data.

4. Context Windows And AI Memory

LLMs simulate “memory” using context windows, which is the amount of information they can consider at once. This is measured in tokens, which represent words or parts of words. It is what makes conversations feel continuous.

This has some important implications:

  • Semantic consistency matters.
  • Tone should be unified across markets.
  • Messaging needs to be coherent across content formats.

Once an AI system associates a brand with a specific theme, that context can persist for a while, although it is unclear how long for. This is probably why LLMs favor fresh content as a way to reinforce authority.

5. Recommenders

In ecommerce and content-heavy sites, recommenders show personalized suggestions based on behavior. This reduces friction and increases time on site.

Benefits Of Personalization

When personalization works, users and brands can benefit from:

  • Reduced user friction.
  • Increased user satisfaction.
  • Improved conversion rates.
  • Stronger engagement.
  • Higher CTR.

This can positively influence the customer lifetime value. However, these benefits rely on consistent and trustworthy experiences across channels.

Potential Drawbacks

Alongside the benefits, personalization brings some challenges that marketers need to be aware of. These are not reasons to avoid personalization, but important considerations when planning global strategies. Consider:

  • Filter bubbles reduce exposure to diverse viewpoints and competing brands.
  • Privacy concerns increase as platforms rely on more behavioral and demographic data.
  • Reduced result diversity makes it harder for new or smaller brands to appear.
  • Global templates lose effectiveness when markets expect local nuance.

This means that brands using the same template or unified content across markets for globalization lose even more effectiveness in markets, as cultural nuance, context, or different user motivations are expected. Furthermore, purchase journeys vary across markets. Hence, the effectiveness of hyper-personalization.

It is probably more important than ever that brands spend time researching and planning to gain or maintain visibility in global markets, as well as strengthening their brand perception.

Managing Personalization Across Teams And Channels

At the moment, LLMs tend to favor strong, clearly structured brands and websites. If a brand is not well understood online, it is less likely to be referenced in AI summaries.

Successful digital and SEO projects rely on strong internal processes. When teams work in isolation, inconsistencies appear in data, content, and technical implementation, which then surface as inconsistencies in personalized search.

Common issues include:

  • Weak global alignment.
  • Translations that miss local relevance.
  • Conflicting schema markup.
  • Local pages ranking for the wrong intent.
  • Important local keywords being ignored.

Below is a framework to help organizations manage personalization across markets and channels.

1. Shared Objectives And Understanding Across Teams

Many search or marketing challenges can be prevented by building a shared understanding across teams of:

  • Business and project goals.
  • Issues across markets.
  • Search developments across markets.
  • Audience segmentation.
  • Integrated insights across all channels.
  • Data flows that connect global and local teams.
  • AI developments.

2. Strengthen The Technical Elements Of Your Website

Reinforce the technical elements of your website so that it is easy for search engines and LLMs to understand your brand across markets to avoid entity drift:

  • Website structure.
  • Schema markup on the appropriate sections.
  • Strong on-page structure.
  • Strong internal linking.
  • Appropriate hreflang.

3. Optimize For Content Clusters And User Intent, Not Keywords

Structure is everything. Organizing content into clusters helps users and search engines understand the website clearly, which supports personalization.

4. Use First-Party Data To Personalize On-Site Experiences

Internal search and logged-in user experiences are important to understand your users and build user journeys based on behavior. This helps with content relevance and stronger intent signals.

First-party data can support:

  • Personalized product recommendations.
  • Dynamic filters.
  • Auto-suggestions based on browsing behavior.

5. Maintain Cross-Channel Consistency

A coherent experience supports stronger personalization and prevents fragmented journeys, and search is only one personalized environment. Tone, structure, messaging, and data should remain consistent across:

  • Social platforms.
  • Email.
  • Mobile apps.
  • Websites and on-site search.

Clear and consistent USPs should be visible everywhere.

6. Strengthen Your Brand Perception

With so much online competition, brands whose work is being referenced positively across the internet. It is the old PR: Focus on your strengths and publish well-researched work, with stats that are useful to your target users.

Conclusion: Turning Personalization Into An Advantage

Conway’s Law matters more than ever. The idea that organizations design systems that mirror their own communication structures is highly visible in search today. If teams operate in silos, those silos often show up in fragmented content, inconsistent signals, and mixed user experiences. Personalization then amplifies these gaps even further by not being cited on AI platforms or the wrong information being spread.

Understanding how personalization works and how it shapes visibility, trust, and user behavior helps brands deliver experiences that feel coherent rather than confusing.

Success is no longer just about optimizing for Google. It is about understanding how people search, how AI interprets and summarizes content, how brands are referenced across the web, and how teams collaborate across channels to present a unified message.

Where every search result is unique, the brands that succeed will be the ones that coordinate, connect, and communicate clearly, both internally and across global markets, to help strengthen the perception of their brand.

More Resources:


Featured Image: Master1305/Shutterstock

https://www.searchenginejournal.com/how-search-engines-tailor-results-to-individual-users-and-how-brands-can-and-should-manage-it/562582/


The State of AEO & GEO in 2026 [Webinar] via @sejournal, @hethr_campbell

How AI Search Is Reshaping Visibility & Strategy

AI search is rapidly changing how brands are discovered and how visibility is earned. 

As AI Overviews, ChatGPT, Perplexity, and other answer engines take center stage, traditional SERP rankings are no longer the only measure of success. 

For enterprise SEO leaders, the focus has shifted to understanding where to invest, which strategies actually move the needle, and how to prepare for 2026.

Join Pat Reinhart, VP of Services and Thought Leadership at Conductor, and Lindsay Boyajian Hagan, VP of Marketing at Conductor, as they unpack key insights from The State of AEO and GEO in 2026 Report. This session provides a clear look at how enterprise teams are adapting to AI-driven discovery and where AEO and GEO strategies are headed next.

What You’ll Learn

Why Attend?

This webinar offers data-backed clarity on what is working in AI search today and what to prioritize moving forward. You will gain actionable insights to refine your strategy, focus resources effectively, and stay competitive as AI continues to reshape search in 2026.

Register now to access the latest guidance on growing AI visibility in 2026.

🛑 Can’t make it live? Register anyway, and we’ll send you the recording.

https://www.searchenginejournal.com/aeo-and-geo-in-2026/563856/


Google Reveals The Top Searches Of 2025 via @sejournal, @MattGSouthern

In 2025, Google’s AI tool Gemini topped global searches. People tracked cricket matches between India and England, looked up details on the new Pope, and searched for information about Iran and the TikTok ban. They followed LA fires and government shutdowns.

But between the headlines, they also looked up Pedro Pascal and Mikey Madison. They wanted to make hot honey and marry me chicken. They planned trips to Prague and Edinburgh. They searched for bookstores from Livraria Lello in Porto to Powell’s in Portland.

Google’s Year in Search tracks what spiked. These lists show queries that grew the fastest relative to 2024, ranging from breaking news to entertainment, sports, and lifestyle. Together, they present a picture of what captured attention throughout the year.

Top Searches Of 2025

Google’s AI assistant Gemini became the top trending search globally, showing how widely AI tools were embraced throughout the year. The rest of the top 10 was filled with sports, with cricket matches between India and England, the Club World Cup, and the Asia Cup capturing a lot of public interest.

The global top 10 trending searches were:

Global top 10:

  1. Gemini
  2. India vs England
  3. Charlie Kirk
  4. Club World Cup
  5. India vs Australia
  6. Deepseek
  7. Asia Cup
  8. Iran
  9. iPhone17
  10. Pakistan and India

The US list reflected different priorities and diverged from global trends, with Charlie Kirk at the top and entertainment properties ranking highly. KPop Demon Hunters secured the second position.

The US top 10 trending searches were:

US top 10:

  1. Charlie Kirk
  2. KPop Demon Hunters
  3. Labubu
  4. iPhone 17
  5. One Big Beautiful Bill Act
  6. Zohran Mamdani
  7. DeepSeek
  8. Government shutdown
  9. FIFA Club World Cup
  10. Tariffs

News & Current Events

Natural disasters and political events shaped what news topics people were searching for. The LA Fires, Hurricane Melissa, and the TikTok ban drew worldwide interest, while in the US, folks were most often searching about topics like the One Big Beautiful Bill Act and the government shutdown.

Global top 10:

  1. Charlie Kirk assassination
  2. Iran
  3. US Government Shutdown
  4. New Pope chosen
  5. LA Fires
  6. Hurricane Melissa
  7. TikTok ban
  8. Zohran Mamdani elected
  9. USAID
  10. Kamchatka Earthquake and Tsunami

US top 10:

  1. One Big Beautiful Bill Act
  2. Government shutdown
  3. Charlie Kirk assasination
  4. Tariffs
  5. No Kings protest
  6. Los Angles fires
  7. New Pope chosen
  8. Epstein files
  9. U.S. Presidential Inauguration
  10. Hurricane Melissa

AI-Generated Content Leads US Trends

AI-generated content captured everyone’s attention in the US, with AI-created images and characters popping up all over different categories. The viral AI Barbie, AI action figures, and Ghibli-style AI art topped this year’s trends.

The top US trends included:

  1. AI action figure
  2. AI Barbie
  3. Holy airball
  4. AI Ghostface
  5. AI Polaroid
  6. Chicken jockey
  7. Bacon avocado
  8. Anxiety dance
  9. Unfortunately, I do love
  10. Ghibli

People

Music artists and political figures were among the most searched people worldwide. d4vd, Kendrick Lamar, and the newly elected Pope Leo XIV attracted the most international attention. In the US, searches mainly centered on political appointees such as Zohran Mamdani and Karoline Leavitt.

Global top 10:

  1. d4vd
  2. Kendrick Lamar
  3. Jimmy Kimmel
  4. Tyler Robinson
  5. Pope Leo XIV
  6. Vaibhav Sooryavanshi
  7. Shedeur Sanders
  8. Bianca Censori
  9. Zohran Mamdani
  10. Greta Thunberg

US top 10:

  1. Zohran Mamdani
  2. Tyler Robinson
  3. d4vd
  4. Erika Kirk
  5. Pope Leo XIV
  6. Shedeur Sanders
  7. Bonnie Blue
  8. Karoline Leavitt
  9. Andy Byron
  10. Jimmy Kimmel

    Entertainment

    Actors

    Breakthrough performances drove increased actor searches. Mikey Madison saw a spike in global searches after her acclaimed role in Anora, while Pedro Pascal led searches in the US.

    Global top 5:

    1. Mikey Madison
    2. Lewis Pullman
    3. Isabela Merced
    4. Song Ji Woo
    5. Kaitlyn Dever

    US top 5:

    1. Pedro Pascal
    2. Malachi Barton
    3. Walton Goggins
    4. Pamela Anderson
    5. Charlie Sheen

    Movies

    Expected franchise entries and original films topped movie searches. Anora was the top globally, while KPop Demon Hunters gained US popularity, alongside major releases such as The Minecraft Movie and Thunderbolts.

    Global top 5:

    1. Anora
    2. Superman
    3. Minecraft Movie
    4. Thunderbolts*
    5. Sinners

    US top 5:

    1. KPop Demon Hunters
    2. Sinners
    3. The Minecraft Movie
    4. Happy Gilmore 2
    5. Thunderbolts*

        Books

        Contemporary romance and classic literature were the most searched genres. Colleen Hoover’s “Regretting You” and Rebecca Yarros’s “Onyx Storm” topped both global and US charts, while George Orwell’s “Animal Farm” and “1984” saw a resurgence in popularity.

        Global top 10:

        1. Regretting You – Colleen Hoover
        2. Onyx Storm – Rebecca Yarros
        3. Lights Out – Navessa Allen
        4. The Summer I Turned Pretty – Jenny Han
        5. The Housemaid – Freida McFadden
        6. Frankenstein – Mary Shelley
        7. It – Stephen King
        8. Animal Farm – George Orwell
        9. The Witcher – Andrzej Sapkowski
        10. Diary Of A Wimpy Kid – Jeff Kinney

        US top 10:

        1. Regretting You – Colleen Hoover
        2. Onyx Storm – Rebecca Yarros
        3. Lights Out – Navessa Allen
        4. The Summer I Turned Pretty – Jenny Han
        5. The Housemaid – Freida McFadden
        6. It – Stephen King
        7. Animal Farm – George Orwell
        8. The Great Gatsby – F. Scott Fitzgerald
        9. To Kill a Mockingbird – Harper Lee
        10. 1984 – George Orwell

        Podcasts

        Podcast searches were driven by political commentary and celebrity-hosted shows. The Charlie Kirk Show ranked first both worldwide and in the US, while sports podcast New Heights and Michelle Obama’s “IMO” gained attention in the US.

        Global top 10:

        1. The Charlie Kirk Show
        2. New Heights
        3. This Is Gavin Newsom
        4. Khloé In Wonder Land
        5. Good Hang With Amy Poehler
        6. Candace
        7. The Meidastouch Podcast
        8. The Ruthless Podcast
        9. The Venus Podcast
        10. The Mel Robbins Podcast

        US top 10:

        1. New Heights
        2. The Charlie Kirk Show
        3. IMO with Michelle Obama and Craig Davidson
        4. This Is Gavin Newsom
        5. Good Hang With Amy Poehler
        6. Khloé In Wonder Land
        7. The Severance Podcast
        8. The Rosary in a Year
        9. Unbothered
        10. The Bryce Crawford Podcast

        Sports Events

        International soccer tournaments attracted the most global sports searches. The FIFA Club World Cup, Asia Cup, and ICC Champions Trophy were the top interests worldwide, while in the US, searches centered on domestic events like the Ryder Cup and UFC championships.

        Global top 10:

        1. FIFA Club World Cup
        2. Asia Cup
        3. ICC Champions Trophy
        4. ICC Women’s World Cup
        5. Ryder Cup
        6. EuroBasket
        7. Concacaf Gold Cup
        8. 4 Nations Face-Off
        9. UFC 313
        10. UFC 311

        US top 10:

        1. Ryder Cup
        2. 4 Nations Face-Off
        3. UFC 313
        4. UFC 311
        5. College Football Playoff
        6. Super Bowl LX
        7. NBA Finals
        8. World Series
        9. Stanley Cup Finals
        10. March Madness

        Lifestyle And Gaming

        Anticipated game releases led search trends. Arc Raiders was the most-searched title globally, while Clair Obscur: Expedition 33 was the top search in the US, alongside popular titles such as Battlefield 6 and Hollow Knight: Silksong.

        Global top 5 games:

        1. Arc Raiders
        2. Battlefield 6
        3. Strands
        4. Split Fiction
        5. Clair Obscur: Expedition 33

        US top 5 games:

        1. Clair Obscur: Expedition 33
        2. Battlefield 6
        3. Hollow Knight: Silksong
        4. ARC Raiders
        5. The Elder Scrolls IV: Oblivion Remastered

          Music (US Only)

          Emerging artists and well-known musicians drove music searches. d4vd led in musician searches, whereas Taylor Swift led song rankings with various tracks, including “Wood” and “The Fate of Ophelia.”

          Top 5 musicians:

          1. d4vd
          2. KATSEYE
          3. Bad Bunny
          4. Sombr
          5. Doechii

          Top 5 songs:

          1. Wood – Taylor Swift
          2. DtMF – Bad Bunny
          3. Golden – HUNTR/X
          4. The Fate of Ophelia – Taylor Swift
          5. Father Figure – Taylor Swift

          Travel (US Only)

          Major cities and popular European destinations drove travel itinerary searches. Boston, Seattle, and Tokyo led domestic travel plans, while Prague and Edinburgh were notably popular for European trips.

          Top 10 travel itinerary searches:

          1. Boston
          2. Seattle
          3. Tokyo
          4. New York
          5. Prague
          6. London
          7. San Diego
          8. Acadia National Park
          9. Edinburgh
          10. Miami

            Google Maps

            Google Maps data represents the most-searched locations on Maps in 2025.

            Bookstores

            Historic and iconic bookstores drew worldwide attention on Google Maps. Portugal’s Livraria Lello and Tokyo’s Animate Ikebukuro were the most searched internationally, while Powell’s City of Books in Portland ranked highest in US bookstore interest.

            Global top 5:

            1. Livraria Lello, Porto District, Portugal
            2. animate Ikebukuro main store, Tokyo, Japan
            3. El Ateneo Grand Splendid, Buenos Aires, Argentina
            4. Shakespeare and Company, Île-de-France, France
            5. Libreria Acqua Alta, Veneto, Italy

            US top 5:

            1. Powell’s City of Books, Portland, Oregon
            2. Strand Book Store, New York, New York
            3. The Last Bookstore, Los Angeles, California
            4. Kinokuniya New York, New York, New York
            5. Stanford University Bookstore, Stanford, California

                Looking Back

                That’s what caught attention in 2025. People searched for breaking news about natural disasters and political changes. They tracked sports tournaments and looked up new AI tools. They followed major world events.

                And between those searches, they looked up actors after breakthrough performances, found recipes they saw on social feeds, and planned trips to places they’d been thinking about for years.

                The trends don’t tell you what mattered most. They tell you what people were curious about when they had a spare moment, whether that was understanding a major news event or finding the perfect travel itinerary.

                You can watch the full Google Year In Search video below:

                [embedded content]

                The full Year in Search data is at trends.withgoogle.com/year-in-search/2025.

                More resources:

                https://www.searchenginejournal.com/google-reveals-the-top-searches-of-2025/563738/


                Google Updates Search Live With Gemini Model Upgrade via @sejournal, @martinibuster

                Google has updated Search Live with Gemini 2.5 Flash Native Audio, upgrading how voice functions inside Search while also extending the model’s use across translation and live voice agents. The update introduces more natural spoken responses in Search Live and reflects Google’s effort to improve natural voice queries, treating voice as a core interface as a way for users to get everything they can get from regular search plus enabling them to ask questions about the physical world around them and receive immediate voice translations between two people speaking different languages.

                The new updated voice capabilities, rolling out this week in the  United States, will enable Google’s voice responses to sound more natural and can even be slowed down for instructional content.

                According to Google:

                “When you go Live with Search, you can have a back-and-forth voice conversation in AI Mode to get real-time help and quickly find relevant sites across the web. And now, thanks to our latest Gemini model for native audio, the responses on Search Live will be more fluid and expressive than ever before.”

                Broader Gemini Native Audio Rollout

                This Search upgrade is part of a broader update to Gemini 2.5 Flash Native Audio rolling out across Google’s ecosystem, including Gemini Live (in the Gemini App), Google AI Studio, and Vertex AI. The model processes spoken audio in real time and produces fluid spoken responses, reducing barriers to natural conversation, reducing friction in live interactions. Although Google’s announcement didn’t say that the model was a speech-to-speech model (as opposed to speech-to-text then text-to-speech), this update follows Google’s October announcement of “Speech-to-Retrieval (S2R). It’s a neural network-based machine-learning model trained on large datasets of paired audio queries.”

                These changes show Google treating native audio as a core capability across consumer-facing products, making it easier for users to ask and receive information about the physical world around them in a natural manner that wasn’t previously possible.

                Improvements For Voice-Based Systems

                For developers and enterprises building voice-based systems, Google says the updated model improves reliability in several areas. Gemini 2.5 Flash Native Audio more consistently triggers external functions during conversations, follows complex instructions, and maintains context across multiple turns. These improvements make live voice agents more dependable in real-world workflows, where misinterpreted instructions or broken conversational flow reduce usability.

                Smooth Conversational Translation

                Beyond Search and voice agents, the update introduces native support for “live speech-to-speech translation.” Gemini translates spoken language in real time, either by continuously translating ambient speech into a target language or by handling conversations between speakers of different languages in both directions. The system preserves vocal characteristics such as speech rhythm and emphasis, supporting translation that sounds smoother and conversational.

                Google highlights several capabilities supporting this translation feature, including broad language coverage, automatic language detection, multilingual input handling, and noise filtering for everyday environments. These features reduce setup friction and allow translation to occur passively during conversation rather than through manual controls. The result is a translation experience that behaves much like an actual person in the middle translating between two people.

                Voice Search Realizing Google’s Aspirations

                The update reflects Google’s continued iteration of voice search toward an ideal that was originally inspired by the science fiction voice interactions between humans and computers in the popular Star Trek television and movie series.

                Read More:

                Google Announces A New Era For Voice Search

                You can now have more fluid and expressive conversations when you go Live with Search.

                Improved Gemini audio models for powerful voice interactions

                Gemini Live

                5 ways to get real-time help by going Live with Search

                Featured Image by Shutterstock/Jackbin

                https://www.searchenginejournal.com/google-updates-search-live-with-gemini-model-upgrade/563189/


                So You Want To Paywall?

                There are three inevitabilities in life. Death, taxes, and big tech companies dumping on the little guy. As zero-click searches reach an all-time high and content is stolen and repurposed for the gain of the almighty tech loser, there’s only one viable solution.

                To paywall.

                To create a value exchange that reduces reliance on third-party platforms. To become as self-sufficient as possible. Like an off-grid cabin or your mum’s basement, a paywall gives you a sense of security you just cannot put a price on.

                As we’re all finding, any kind of reliance on these guys doesn’t put us in a good position. They do not want to send us traffic.

                TL;DR

                1. Subscriber revenue is intrinsically more valuable to a business because it is predictable. Subscription and advertiser revenue are not created equal.
                2. Don’t paywall everything. Use dynamic/metered paywalls and leave high-reach, generally lower-quality platforms like Google Discover free for email signups.
                3. Subscription success relies on your USP – whether that’s exclusive data, deep, niche insights, or a certain vibe – you have to stand out.
                4. The customer experience and understanding of your audience matter. Create habit-forming connections and products. Become an essential part of their life.

                But What About Our Traffic?

                Your traffic will decline. But guess what? You’re already hemorrhaging clicks and have been for some time. And traffic doesn’t pay the bills.

                Two comparable pages, one with a paywall, one without (Image Credit: Harry Clarkson-Bennett)

                The only way to sustain rankings over time is with high-quality engagement data. Navboost stores and uses 13 months of data to identify good vs bad clicks, click quality, the last longest click, and on-page interactions to establish the most relevant content. All at a query level.

                Paywalls are not your friend when it comes to user engagement. Not for the masses. But for a small cohort of people who like you enough to pay, your engagement data will be excellent.

                In an ultra-personalized world, you will still do well to the people who really matter.

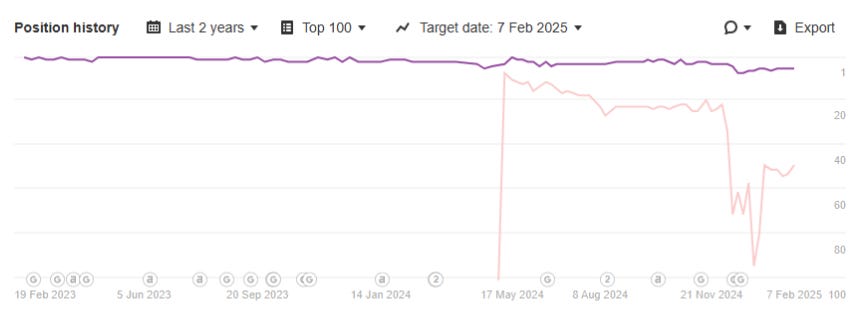
                We have data that pretty perfectly highlights the impact of a paywall on rankings. Over the course of three to four months in traditional search, your rankings start to steadily drop before settling in severe mediocrity. You’ve got to fight for every click. With great content, marketing, savviness. Everything.

                We have used an image manager to try and generate a free-to-air badge. It rarely shows up unless there’s no featured image, but the idea is excellent (Image Credit: Harry Clarkson-Bennett)

                In Google Discover – a highly personalized, click and engagement driven platform – this is even more pronounced. While Discover’s clickless traffic is lower quality, there will be a small cohort of highly engaged users that develop over time, you can target with a paywall.

                Unpaywall for the masses, build your owned channels, and paywall for the highly engaged. The platform will take care of the personalization for you.

                So, maximize your value exchange with ads and email signups for most users, but don’t neglect those with a high return rate.

                There’s some psychology involved in all of this. When a brand becomes widely known for paywalling, I suspect the likelihood of a click goes down as users know what to expect. Or maybe what not to expect.

                This likely perpetuates over time, so you should clarify what articles are free to air.

                Is Our Content Good Enough?

                To nail SEO bingo, it depends. It depends on what your value is in the market. There is a lot of free stuff out there already. But broadly rubbish. So as long as the bar keeps dropping, we’ll all be fine.

                I am old-ish. I like words. Writing great content isn’t easy and is usurped in many cases by richer, more visually striking content. Content that satisfies all types of users. Scanners, deep readers, listeners and get the answer and go-ers.

                In some ways, you can satisfy all types of users more effectively than ever. I think you have to hit three of the four Es of content creation. Make it resonate, be consistent, and understand your audience. Whatever you create stands a chance.

                But that doesn’t mean creating great stuff is any easier. If you work for a traditional publisher, the chances are you’ve brought a spoon to a gun fight. The war for attention is being fought on all fronts, and straight words are losing.

                Fortunately, not every subscription model relies on the quality of the prose. It might be that you have unique data, granular insights into a specific market, or are just a bloody good laugh.

                Subscriptions come in all shapes and sizes.

                Ultimately, it comes down to your market, marketing, positioning and your USP. You have to know and speak to your audience and you have to stand out. As Barry would say, if you’re forgettable, you’re doomed.

                How Do We Know If People Will Pay?

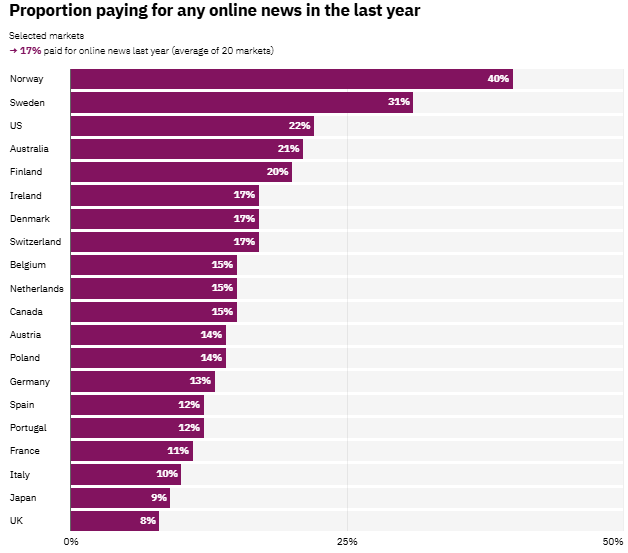
                When it comes to paying for news, some markets are far more “advance” than others. The Scandinavian market is light-years ahead of almost everyone else when it comes to paying for news. You have to do your research to understand:

                • How many people currently pay for news?
                • What demographic of person pays?
                • How saturated is the market already?
                • What is your niche?
                Where your audience are matters a lot (Image Credit: Harry Clarkson-Bennett)

                While it doesn’t align perfectly, it’s not surprising that those most likely to pay for news have higher income levels. Higher disposable income tends to create an environment where people buy more stuff.

                Shocking, I know.

                But that doesn’t tell the whole story. Norwegian news outlets have (apparently) a long history of trust with their audience and have never had access to free multi-day newspapers. Ditto other Scandinavian countries. In an age of rubbish and spin, trust and E-E-A-T are more important than ever.

                And while the UK sits in a pretty shocking-looking position, almost 24 million of us pay for a BBC license fee. That is, in essence, paying for news. Insert joke about BBC bias and woke cultural agendas here.

                Cultural and societal factors really matter. As does your understanding of the market.

                Important to note that according to Richard Reeves (AOP Director), Subscriptions have overtaken display advertising as the core source of digital revenue.

                “Most heartening is what this represents as the wider information ecosystem fractures: audiences recognise the value of professional journalism and are willing to pay for it.”

                In an era of slop, paying for something good is not a bad thing.

                Macro And Micro Factors Are Influential

                You can only control what you can control. But you shouldn’t dismiss the wider climate.

                In the UK and arguably globally, there is a cost-of-living crisis. Globally, there have been a number of very significant geopolitical issues that affect the wider economy. Money doesn’t go as far as it once did, and most subscriptions are a luxury purchase.

                Is a £20 or £30 monthly subscription more valuable than a £10 Netflix one? Or Spotify? These are questions you need to ask. Why would someone subscribe and stick around?

                How far your money goes has been declining for some time… (Image Credit: Harry Clarkson-Bennett)

                And we aren’t just competing with other publishers. While screen time and content consumption are at an all-time high, video consumption and the creator economy are booming.

                It is quite literally a near half a trillion dollar market.

                Not strengths for traditional publishers. While there have been some very good success stories in recent times (see Wired turning their journalists into individual subscription machines), legacy publishers need to adapt.

                So your pricing strategy, customer service, and overall experience are hugely important. You are almost certainly going to be a nice-to-have. So make sure your customer journey and path to conversion are premium, and your audience feel listened to.

                The standard customer experience (Image Credit: Harry Clarkson-Bennett)

                You need to speak to your audience. You don’t have to go into this blind. Forging real connections with people is not impossible and making them feel listened to will go a long way.

                You can try to figure out what they really value, how much they’re willing to spend and what’s stopping them.

                Should I Paywall Everything?

                No. Content is designed to do different things, and not everything is a premium product. Whatever journalists will tell you. If you shut down your site entirely, you become too closed off an ecosystem in my opinion.

                • Commercial Content: If you have affiliate-led content, paywalling is a questionable decision. It may not be wrong per se, but think about whether the pros outweigh the cons. Typically, it’s a good gateway drug for the rest of your content. And makes some money.
                • Content You Can Get Elsewhere: Evergreen content of a comparable quality to what already exists in the wider corpus is not a profitable opportunity. I’d argue that leaving this free-to-air has more pros than cons. You can always unpaywall the 100 best albums of all time, but gate the richer, individual album reviews.
                • Lower-Quality Platforms: A user that comes from a platform like Discover is far less likely to convert than someone who comes from organic search. So think about the role each platform plays in your content access ecosystem.
                • Paywall Vs. Newsletter signup: It is far easier to convert people to a paying subscriber from a newsletter database than from an on-page paywall. And the user journey is far less interrupted. Building an owned channel is never a bad thing, so think about how engaged users are and whether an email would be a more effective starting point.

                The Type Of Paywall Matters (Now More Than Ever)

                LLMs do not respect paywalls. As it turns out, neither does Google.

                I, for one, am stunned.

                As of just a few months ago, the search giant asked that publishers with paywalls change the way they block content to help Google out. The lighter touch paywall solution (a JavaScript-based one) includes the full content in the server response.

                “…Some JavaScript paywall solutions include the full content in the server response, then use JavaScript to hide it until subscription status is confirmed.

                This isn’t a reliable way to limit access to the content. Make sure your paywall only provides the full content once the subscription status is confirmed.”

                According to Google, they are struggling to determine the difference. So the problem is on us, not them. They (and I strongly suspect other LLMs) are ingesting this content and training their models on us whether we like it or not.

                For those of you who haven’t heard of Common Crawl, it stores a corpus of open web data accessible to “researchers.” By researchers, we now mean tech bros who don’t want to pay for, surprisingly, anything.

                According to their CEO;

                “If you didn’t want your content on the internet, you shouldn’t have put your content on the internet.”

                It doesn’t stop there either. Even if you block all non-whitelisted bots from accessing your site at a CDN level, you may have syndication partnerships in place. If so, it’s likely your content is making it out into the wider world.

                The internet is not exactly a leakproof vessel. If you’re setting one up now, try to implement a server-side option.

                What Is The Right Paywall For Me?

                I have written about the types of paywall available to you and the pros and cons of each. Generally, I think a metered or dynamic paywall is the best option for most publishers. At the very least, a freemium model. Something that gives people enough to draw them in.

                And you can’t exactly draw them in if you just hard paywall everything.

                You have to think of this as a full-blown marketing strategy. You need to know where people come from. How much of your content they have consumed. Whether it’s better to show them a newsletter signup as opposed to a paywall.

                It is absolutely worth knowing that over time, a strong email database will convert far more effectively than a hard paywall.

                So encouraging free signups and taking a longer-term view to conversions (you’ll need a good customer journey here) may be far more effective.

                How Can I Set One Up?

                There are a number of paywall management options out there for publishers. Leaky Paywall, Zephr, Piano. There are plenty.

                The best ones integrate with your existing tech stacks, have excellent personalization and customization options, deploy ad-blocking strategies, and run flexible gating strategies.

                Larger publishers tend to go with enterprise-level options with deep analytics and CRM integrations. Smaller publishers can work with lighter touch, cheaper operators. You really just need to scope out what will work best for you.

                Particularly when it comes to monthly costs and revenue share options.

                How Can I Map The Impact?

                You’ll need to establish a few key things:

                • The average drop in traffic you expect to see.
                • The subsequent loss of existing revenue (probably ad-related, but there may be some knock-on wider commercial impact).
                • The average value of a subscription (and the expected conversion rate).
                • Your customer LTV.

                Focusing on Customer LTV shifts marketing from chasing traffic to profitable, loyal audience relationships. It makes businesses understand that not all audiences or subscriptions are created equal.

                You generate more subs through paid media because the net is larger. But lots slip through the net. So you need a quality product (in both a product and marketing sense) alongside UX and customer service that reduces friction.

                Search and owned channels are smaller, but far more likely to pay because they have taken an action to find you. In some cases, they actually want you in their inbox. The quality is higher, but the overall returns are lower.

                So you just can’t treat everybody the same.

                Closing Thoughts

                Subscriber revenue is so valuable because it’s predictable. Subscription business models have boomed for that very reason. A pound of subscriber revenue is far more valuable than almost anything else, and it should be the focus of your business.

                But that doesn’t mean you put all your eggs in one basket. You can have multiple subscription types on your website, and that can help you become habitual with all types of users. But you need to add value to their lives every day.

                Puzzles, recipes, short and long-form videos, et al.

                Businesses make money in many ways. A diverse business is resilient. Resilient to macro and micro factors that will decimate some publishers over the next few years. So talk to your audience, trial new ways of adding value, and commit when one works. Become habitual.

                And, shock horror, people want to belong to something. So while the digital experience is crucial, making an effort to connect with people IRL matters.

                More Resources:


                This post was originally published on Leadership in SEO.


                Featured Image: beast01/Shutterstock

                https://www.searchenginejournal.com/so-you-want-to-paywall/562878/