Google May Be Penalizing AI-Generated Content As Thin Content via @sejournal, @martinibuster

A forum website published a post on Reddit expressing disbelief that Google issued a manual action for thin content, finding it hard to reconcile how Google could send so much traffic for nearly twenty years only to find fault with it now. Google is calling it a manual action for thin content, but SEOs believe it may be for AI-generated content.

Manual Action For Thin Content

According to the Reddit post, a forum received a manual action for thin content. The notification specifically pointed to over half a million posts in one specific category of the site, /threads/. They explained that it’s a partial manual action and that the penalization does not affect the rest of the site, just this one part of the website.

They explained:

“The message (WNC‑651700, ~17 July 2026) is: “Thin content with little or no added value.”
It’s a partial manual action, meaning a human reviewer looked at part of the site, judged it unworthy of ranking, and suppressed it pending a reconsideration request.

The Affects field names exactly one thing: the URL pattern windowsforum.com/threads/.
That’s 168,290 visible threads and over half a million posts, twenty years deep, suppressed together.

No example URLs were provided. Not one.”

Thin Content

Google has multiple definitions of thin content. One of them, thin affiliate content, is content published on affiliate sites that are word for word duplicates of what is found on the merchant websites.

Former Googler Matt Cutts has said that thin affiliate content lacks “original insight or research or analysis” or any other kind of content like original videos that “add value.”

Other forms of thin content:

  • Syndicated content
  • Article marketing content

Cutts has also explained that the opposite of thin content is content that site owners have written themselves, contains additional value, is unique, and leans in on the author’s actual expertise.

That last part may be critical for understanding why the Redditor’s forum received a thin content warning, but not in the context that the site owners were thinking of.

Why Is Actual Thin Content Not Penalized?

The part that confused the site owner is that there were two other sections of the website that were more clearly thin content, yet those web pages were not subject to a manual action. One section was a feed of syndicated headlines. The other section was an archived knowledge base. They said both sections have been inactive for three years, yet neither of them was called out for a manual action. It was the forum section of the site that received a manual action.

They wrote:

“The part that doesn’t reconcile

Two sections of the site are the obvious candidates for a thin‑content finding:

an old syndicated headline feed

an archived knowledge base

Together, that’s 11,927 threads with a mean age of about 12.5 years.

…This material has been crawled, indexed, and ranked continuously through Panda, Penguin, the September 2023 helpful content update, and through the community’s migration from its original domain… Fifteen years, two domains, every major ranking change Google has shipped and it never drew a manual action.”

Redditors expressed outrage, with one saying that it’s the result of Google’s monopoly in search.

Stablogger’s response was representative of the outrage many felt:

“This is pretty shocking indeed, especially knowing the reputation of this forum. Is there some thin content? Most certainly, but you have repetitive or pretty much empty threads on every single forum, you have them on Reddit, too.

It’s the nature of user generated content, some threads attract loads of interaction, some don’t at all, but it can’t be the solution to simply delete thin threads without the consent of whoever posted them.”

Well, contrary to what Stablogger wrote, pruning thin or outdated conversations is an option and many forum site owners do it.

Maybe Thin Content = AI Generated Content?

Google has in the past said that content that is AI-generated does not automatically mean it’s bad. However, Australian-based SEO Gagan Ghotra suggested that AI-generated content may be the reason for the thin content manual action.

Ghotra tweeted:

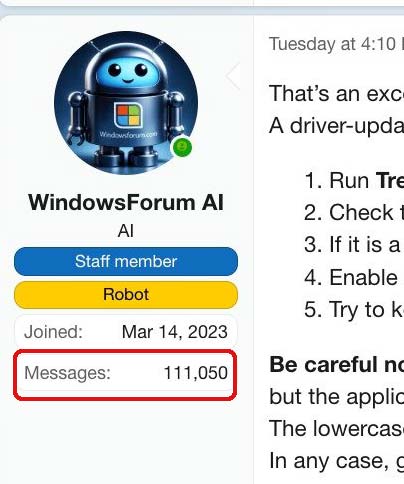
Here’s a closeup of the screenshot:

Screenshot of a forum member that's an AI chatbot, showing that the bot had posted 111,050 responses since March 14, 2023.

The points of interest are that the forum characterizes its AI chatbot as a staff member, it has been active since 2023, and the chatbot has posted over a hundred thousand responses to questions.

Authenticity And Value Add

The possible reason why AI-generated answers may be considered thin content is that the expected value add of forums is that the answers are based on actual human experience.

AI does not have experience. It deals in received knowledge. Received knowledge is knowledge that comes from someone or somewhere else, like from a book or another website. There is no value add there in the context of a forum. It’s not what users expect when they post a question on a forum.

Featured Image by Shutterstock/mundissima

https://www.searchenginejournal.com/google-may-be-penalizing-ai-generated-content-as-thin-content/583773/
Google Expands Review Guidelines And Warns Of Manual Actions via @sejournal, @martinibuster

Google updated their review snippet documentation to add three more reasons why a site may become eligible for a manual action. Authentic human insights are an important quality of the kind of content that Google wants to rank, arguably even more so when it comes to review content.

Three New Prohibitions On Review Content

Google’s newly updated guidelines on review snippet structured data are not directly related to structured data. They are more about the authenticity of content, which is why they’re listed under the Guidelines section that is about the kind of content that is eligible to be shown in reviews rich results.

The documentation warns that violating these guidelines will result in a manual action:

“Warning: If your site violates one or more of these guidelines, then Google may take manual action against it. Once you have remedied the problem, you can submit your site for reconsideration.”

The three changes to the guidelines are:

  • “Don’t include fake or undisclosed incentivized reviews on your page or in your structured data markup. Examples include:
  • Reviews that aren’t based on a genuine experience of a product or service
  • Reviews written in exchange for a benefit (such as money, discounts, vouchers, or free products) that don’t clearly and prominently disclose the incentivization”

All three of the new guidelines are about the authenticity of published reviews and reflect Google’s overall concerns about expertise and helpfulness of content.

The associated changelog for the update explains the reasons for the update:

“Added a new review snippet guideline

What: Added a new guideline to the review snippet documentation about fake and undisclosed incentivized reviews.

Why: To improve user review transparency.”

Google’s Reviews System

Google’s concern about the quality of reviews is such that they have an entire algorithmic system devoted to reviews content.

Their Reviews System documentation explains what it does:

“The reviews system is designed to evaluate articles, blog posts, pages or similar first-party standalone content written with the purpose of providing a recommendation, giving an opinion, or providing analysis. It does not evaluate third-party reviews, such as those posted by users in the reviews section of a product or services page.”

It’s clear that the authenticity of content is an important quality to focus on as a way to satisfy Google’s guidelines, but more importantly, as a way to differentiate your content.

https://www.searchenginejournal.com/google-expands-review-guidelines-and-warns-of-manual-actions/583674/


Charging AI Bots Decides Which Agents Can Still Cite You via @sejournal, @slobodanmanic

Charging an AI bot to crawl your website is a visibility decision, not a revenue decision. Every crawler you put behind a paywall is a choice about which agents still get to read, cite, and recommend you, and most website owners are about to make that choice without noticing it has become theirs to make. The mechanism is HTTP 402, a status code written into the web in 1997 and left dormant for almost thirty years. In July 2025, Cloudflare dusted it off to charge AI crawlers. On June 15, 2026, AWS added the same capability to its firewall. Two of the largest companies in web infrastructure now sell the same thing: a toll booth for machines. The question they hand you is about who you can afford to turn away.

The Toll Booth Everyone Is Reading As A Revenue Line

The launch posts frame pay-per-crawl as new money, but it’s really about consent. For years, AI companies have crawled the open web to train models and ground answers, and website owners had two blunt options: leave the door open, or block crawlers wholesale and hope the rules held. Pay-per-crawl is the first mechanism that lets a website say something more precise than yes or no. It lets you set terms. That is a genuine shift where consent and control, not the pennies, are the real prize.

The reason any of this exists in the first place is a broken bargain. For 30 years, the deal was simple: Let the crawler in, it indexes you, it sends people back. AI crawlers kept the first half and dropped the second. Cloudflare’s breakdown of why those bots crawl puts training at nearly 80% of AI bot activity, with the search-purpose fetches that can actually return a citation, a small slice of what is left. The rest is extraction that takes content and sends nobody back. So, this toll booth is the web trying to renegotiate a bargain the AI crawlers already stopped honoring.

Here is where the celebration from the announcement posts and my read on it part ways. The moment you can set terms, the terms become a visibility tradeoff, and that is the part the launch posts leave out.

Who Is Charging AI Crawlers, And How The Mechanism Works

Cloudflare launched the first major version on July 1, 2025. A publisher sets a flat, per-request price for its domain. When an AI crawler asks for a page, it either presents payment intent in its request headers and gets the content with a 200 response, or it gets a 402 Payment Required response carrying the price. Cloudflare describes itself as the Merchant of Record and runs the settlement, which matters: because Cloudflare sits between the crawlers and the publishers, it can act as the clearing house for both sides. At launch, the feature was a private beta, and Cloudflare framed it as a first experiment, not a finished market.

AWS added the same idea to its Web Application Firewall on June 15, 2026. When an AI crawler requests a protected article, data feed, or licensed archive, AWS WAF can return HTTP 402, and the price and payment details ride along through the x402 protocol as a machine-readable manifest. Payment settles in stablecoin through a Coinbase facilitator, the controls live in WAF Bot Control, and pricing can be set per content path and per bot type without touching the website’s code. Two of the largest infrastructure providers on the web now sell a tollbooth for machines within a year of each other.

They are not alone, though the rest of the field is shaped differently. TollBit runs a bot-and-agent paywall and marketplace, charging AI access on usage-based terms rather than a flat per-request price. Akamai brings that monetization to its own edge by integrating TollBit and Skyfire, announced in September 2025, so its customers can enforce the toll at the network layer without building it. Underneath the newer tolls sits x402, Coinbase’s open standard for the same HTTP 402 status code. It settles in stablecoin and needs no account from the paying agent, which would stretch the toll from known, identified bots to anonymous ones. For the full picture of which crawlers are even reaching you, the AI user-agent landscape is the reference, because you cannot price a bot you cannot name.

Across all of them, the toll lives at the edge, in the CDN and the firewall, the same layer that already decides who gets in. Payment and permission are merging into one control point.

The Open-Web Bargain Is Being Unbundled

The open web’s founding bargain is being taken apart and sold back line by line. The free-crawl-for-traffic deal that powered search, and the entire practice built on top of it, assumed the crawl was a cost a website paid to earn distribution. Pay-per-crawl is the first invoice for a crawl that no longer reliably returns the favor.

That unbundling has a specific shape. Access control and billing used to be separate concerns, handled by separate systems. Now they sit at the same edge, in the same WAF rule, in the same Cloudflare dashboard. The firewall that decides whether a request is allowed is becoming the meter that decides what the request costs. When permission and payment collapse into one layer, the decision to admit a visitor stops being a default and becomes a deliberate, priced choice. This is the agent-as-visitor question, the one underneath the Amazon v. Perplexity case over whether an agent is even an authorized visitor, turned from a legal abstraction into a setting you configure.

And the favor the crawl used to return has not vanished; it has moved. AI surfaces do send people back: Adobe’s 2026 data put AI-referred traffic to US retailers up 393% year over year. That number is why the toll is a visibility decision first and a billing one second. The crawler you would charge and the answer that refers a customer to you are often the same pipeline.

Whether You Should Charge Depends On Who You Are

A publisher with a deep, licensable archive, a news outlet, a reference database, or a proprietary data set, has two things that make charging rational: Content genuinely worth paying for, and crawlers it can afford to refuse because its distribution does not depend on them. For that owner, the toll is leverage, and using it is sound.

A content or commerce website chasing AI visibility sits on the opposite side. For that owner, the crawler is the distribution. Wall it out, and you might collect a few cents, or you might delete yourself from the place where your customers now ask their questions. The toll only works when two things are true at once: What is behind it is worth paying for, and the bot you are blocking is one you do not need to be seen by. The website whose strategy is to be the answer an agent gives is describing a crawler it cannot afford to charge. That is the same reason a website is now a source rather than a megaphone: The value is in being read, not in being walled.

So the move is to watch the door first. Find out which AI bots actually reach you and what they take, separate the ones that feed answers and send referrals from the ones that extract and return nothing, and only then decide where, and whether, a toll belongs. That is the test worth running before anyone charges a cent: meter one bot on one path, watch what it does to both your crawl volume and your presence in the answers, and let the result, not the launch post hype, inform your policy. You should not put a toll on traffic you have never looked at.

The Unsettled Question Is Whether Anonymous Bots Will Pay

No public study has yet shown how much citation share a website actually loses by tolling a specific bot. The logic of the cost is sound: A crawler that both reads you and feeds an AI answer can remove you from that answer when you refuse it. How large the effect runs in practice is unknown, and that is why this stays a decision you make on your own data, not on a rule of thumb.

The signal I will be watching is whether the anonymous-bot payment becomes real. Today, the workable models lean on identified crawlers that present payment intent. The x402 ambition is payment without prior registration, settled in stablecoin, which would extend the toll to the anonymous majority of automated traffic. If that works at scale, the priced web reaches much further than a handful of named bots. If it stays enterprise plumbing, pay-per-crawl remains a tool for large publishers and a curiosity for everyone else. Which of those comes true decides whether the toll booth is a niche or the new shape of the road.

Either way, the booth is built, and it is ours to operate. The bill you can see is the one the crawler pays. The bill you cannot see is the answer you vanish from. Decide which one you are watching.

More Resources:


This post was originally published on No Hacks.


Featured Image: Roman Samborskyi/Shutterstock

https://www.searchenginejournal.com/charging-ai-bots-decides-which-agents-can-still-cite-you/580050/


Google’s Q2: Precise Revenue Figures, Click Claims You Can’t Check via @sejournal, @MattGSouthern

Alphabet shared its Q2 earnings this week, showing that Google Search & Other revenue increased by 17% year over year to reach $63.27 billion. For all the details, check out our earnings brief, including how the growth rate has slowed from 19% in Q1, marking the first slowdown after four quarters of accelerating growth.

The numbers also leave out part of the story. Alphabet provides a detailed breakdown of Search business earnings in its securities filing, while Google describes what the web gets back in broad assurances. Both perspectives are now part of every quarter, and the distance between them is the story.

What The Quarter Established

The revenue aspect of Search offers everything you’d hope for from a data source. Alphabet provided clear numbers, comparisons year-over-year, and consistent definitions across quarters, making it straightforward to follow the progress.

The trajectory is checkable: Search & Other growth went from 10% in Q1 2025 to 12%, then 15%, 17%, and reaching 19% in Q1 2026, before easing back to 17% this quarter.

In its earnings release, CEO Sundar Pichai connected these results to AI, saying the company’s “popular AI features are driving Search query growth.” Chief Business Officer Philipp Schindler pointed out strengths across different industries, with retail leading the way, followed by finance, technology, media, and entertainment, and credited the Gemini integration within Google’s advertising systems. However, Google didn’t specify the exact contribution of each vertical.

The spending side got the same precise treatment. Roger Montti covered this, including the capital expenditures that led to negative free cash flow for the quarter.

That said, none of this detailed financial data addresses the most important question for businesses: the number of clicks to websites. Neither the Q4 2025 nor Q1 2026 reports we covered offered this information. Google’s broader claims about outbound traffic come from other sources like blog posts, interviews, and social media updates from its executives.

3 Kinds Of Claims About The Web

Google’s public statements about website traffic can be grouped into three categories. By organizing them this way, we see what kind of data each one would need to be testable.

The first group includes usage claims. In April, Pichai mentioned that “queries are at an all-time high” and repeated the query-growth link in this week’s release. In July, Nick Fox, senior vice president of Knowledge and Information, noted that Search reached its highest usage on record during a World Cup match. These claims highlight superlatives without providing specific counts. Having more queries does not mean more clicks leaving Google.

The second group involves volume claims. Fox shared in a July LinkedIn post that AI features in Search send billions of clicks to websites weekly. He also mentioned the previous daily figure: “Actually, as we’ve shared before, we continue to send billions of clicks to the web every day through Search.” However, both numbers only specify “billions,” without exact figures. Since one is daily and the other weekly, it’s unclear how the AI-related click count compares to overall clicks or what portion of Search traffic comes from AI surfaces.

The third group focuses on quality claims. Liz Reid, Google’s head of Search, stated that AI Overviews mainly remove “bounce clicks,” visits where users quickly find a fact and leave. In an August 2025 blog post, Reid mentioned that the total organic click volume has been “relatively stable” year-over-year, with an increase in average click quality. She also explained that Google is directing slightly more “quality clicks” to websites than a year earlier. Reid defines quality clicks as visits where users don’t swiftly return to the results page. The post also challenged third-party reports of sharp traffic drops, attributing them to flawed methods and isolated cases. These statements are directional comparisons without a published baseline or measurement.

Overall, all three categories lack precise counts, consistent definitions over time, splits between traditional results, AI Overviews, and AI Mode, and site-level click reporting for AI features. Our review of Google’s blog posts and executive statements before mid-July, as covered in our Fox analysis, shows no breakdown of click figures by AI features. As of publication, that hasn’t changed. Search Console’s generative AI reports, accessible to some websites, show impressions without clicks, including details by page, country, and device type, but no click-through rates.

Compare this to the revenue reports Alphabet filed this month. One side provides a detailed time series, while the other offers three types of assurance.

What Outside Measurement Can And Cannot Test

While independent data can help fill in some gaps, each source measures different things and doesn’t fully replace Google’s overall data. Since Google has challenged outside measurements, it’s helpful to understand the limitations of each dataset.

Click-through rate (CTR) on results pages with AI Overviews provides the clearest insight. Seer Interactive’s analysis found that organic CTR for queries with AI Overviews dropped from 1.76% in 2024 to just 0.61% in 2025. Similarly, Pew Research Center’s data shows users clicked results 8% of the time when AI Overviews appeared, compared to 15% without them. Both sets of data are specific to the queries and panels they examined. Seer notes AI Overview queries tend to be informational, which naturally have lower CTRs.

Looking at position-level CTR across all queries offers a different perspective. Advanced Web Ranking’s Q1 data indicates that CTRs improved for the top five desktop positions but declined for the top mobile position. However, since this data doesn’t specifically isolate AI Overview queries, it can’t definitively support or challenge the bounce-clicks explanation.

Another perspective is assistant referrals. SE Ranking’s data shows that referral traffic from Gemini increased after the Gemini 3 releases. Keep in mind, this measures a different product than clicks from AI Overviews or AI Mode within Search.

Finally, there’s downstream behavior. A Similarweb report found that brands recommended by ChatGPT answers were 2.5 times more likely to receive a site visit within a week. Of that traffic, 55.9% came from branded searches. This suggests AI recommendations can lead to visits through indirect routes, although it doesn’t directly test Google’s claims about clicks from AI features within Search.

What Each Analysis Can Measure

Each analysis captures a different part of the traffic picture. None reproduces Google’s aggregate outbound-click claims.

Together, these outside data points show that while there is some click pressure on specific surfaces that Google’s assurances don’t fully address, there are also indirect benefits elsewhere. This makes it challenging to draw a straightforward conclusion about a loss. Ultimately, no single dataset can capture the full picture. Google’s claims refer to overall clicks across Search and AI features, but every outside measurement focuses on a specific panel, keyword set, or referral path. The two can’t be reconciled with what’s publicly available.

Why This Matters For Search Professionals

The Q2 numbers don’t settle the click debate, and you shouldn’t expect any earnings report to. They show us something a bit narrower: Search revenue can go up without revealing whether organic visits increased or decreased. The quarter added another piece of evidence to one side of that question but doesn’t add clarity to the other.

That’s the practical challenge with the overall claims. Billions of weekly clicks provide important market context, but they don’t tell you if your pages gained or lost visitors because both your site’s performance and the overall market can be true at the same time. A single figure that describes everyone doesn’t really describe anyone.

Your own data is the closest thing to a checkable click number for your site. Tools like Search Console and analytics give you a clear picture of your traffic, even if they can’t always pinpoint which AI feature affected it. If you notice impressions are increasing while clicks are dropping on informational queries, that pattern is consistent with what Seer found with AI Overview queries. Broader CTR data remains mixed across devices and query types.

For publishers, the key indicators to watch are how referral shares from search change over time, and how branded versus non-branded traffic compares. The pattern from Similarweb suggests that AI recommendations might lead to branded search visits rather than direct referrals, so seeing a decline in referrals alongside growth in branded searches can tell a different story than a simple drop.

Be sure to keep paid search analysis separate from the organic side. Google’s expanding ad coverage in AI experiences is mainly about monetization, and it’s a separate track from organic traffic. An increase in AI ad inventory is not evidence that organic clicks went up or down.

When clients ask if Google’s reassurances should influence their strategies, a good answer is that the reassurances can’t be tested, but your own data can. Decisions should be based on the verifiable information you have.

Looking Ahead

This quarter’s gap isn’t between Google’s claims and independent data. It’s between two different disclosure standards within the same company, with only one set of numbers that everyone can verify.

To bridge this gap, we need some specific details: click and CTR data in Search Console’s generative AI reports, a published methodology behind the aggregate claims, and detailed breakdowns by surface. As of now, these haven’t been shared.

Still, Alphabet’s upcoming quarterly report will offer a snapshot of revenue, regardless of these missing details. The earnings reports from the past three quarters haven’t included AI-feature traffic data, and Google hasn’t suggested it will include this information in the future.

More Resources:


Featured Image: Blue Titan/Shutterstock

https://www.searchenginejournal.com/googles-q2-precise-revenue-figures-click-claims-you-cant-check/583280/


Google Says Why It May Ignore Robots.txt And Negatively Impact SEO via @sejournal, @martinibuster

Google’s John Mueller answered a question about robots.txt and explained an easy-to-miss mistake that can impact your SEO and website indexing goals. The specific issue was related to search box spam getting indexed by Google, but this mistake can happen to anyone in general under any context.

Website Search Box Spam

The person who asked the question on Reddit was suffering from a search bar spam attack. What spammers do is search with a query that reflects their spammy niche, and they add a link or a website name. What happens next is that the search bar generates a URL that can be referenced to generate the spammy search result.

And that’s what was happening to the person who was asking the question. Their response was to add a line in the robots.txt file to prevent Google from indexing the file. But Google was indexing those spammy search-generated URLs anyway.

Google Indexed Pages Blocked By Robots.txt

Someone posted on Reddit that their client’s Shopify search box was generating spammy web pages in response to spammer queries and that Google was indexing them despite a robots.txt file prohibiting Google from indexing those pages. What the client did was redirect those spammy URLs to another web page. The person asking the question didn’t ask how to stop the pages from being indexed (which is what they should have been asking); they asked if those redirected URLs should be marked 404 instead.

The person asked:

“Working on a client’s Shopify store where we have the /search added as a disallow in robots.txt, however these search results are still indexed inside of Google.

However, if I try to open one of these pages, they have a redirect set and they redirect to another collection page on the store. Should we display a 404 page instead? What is the easiest way to fix this?”

Why Robots.txt File Caused Spam To Be Indexed

Google’s John Mueller took the extra step to identify and review the client’s robots.txt file and identified an error that was causing Google to ignore the directive prohibiting Googlebot from indexing search results pages.

Mueller responded:

“Also, not sure if it’s your site, but the one I found with similar indexed URLs had sections for “user-agent: Googlebot” (in the “START: Custom Rules” block in comments) as well as a lot more in the “user-agent: *” section further down. With robots.txt, the more specific rules win, so if you have a user-agent: Googlebot section, it will *only* use that section. If you want to apply all the rules in the “user-agent: *” section, you need to copy them. Also, if that’s your site, then you can just list all the user-agents that you want to have shared rules for together, eg:

user-agent: googlebot

user-agent: otherbot

user-agent: imgsrc

user-agent: somethingpt

disallow: /fishes

disallow: /orange-cats

… etc …”

User-Agent Specific Directives Take Precedence

What happened is that the client was relying on Google to follow the directives in a line that’s aimed at all user agents, “user-agent: *”, but because there’s another section of the robots.txt file that’s specific to Googlebot, Google ignored the “user-agent: *” directives and obeyed the one that specifically addressed Googlebot.

That may sound like a quirk in the way robots.txt works, but it actually makes sense because this enables users to target specific crawlers with unique rules and target everyone else with a different set of rules.

How To Be Safe From Search Box Spam

WordPress and Shopify both have ways to mitigate search box spam.

WordPress and Shopify both have ways to mitigate search box spam.

Shopify Search Box Spam Mitigation

Shopify’s website has a tutorial on how to automatically add a noindex directive to all search results. This will effectively prevent indexing of all search results pages. However, it’s necessary to not block search pages with robots.txt for this to work.

Using a noindex directive is more effective than using robots.txt because robots.txt does not control indexing; it only controls crawling.

Shopify instructs:

“You can hide pages that aren’t included in your robots.txt.liquid file by customizing the <head> section of your store’s theme.liquid layout file. You need to include some metatag code to stop the indexing of particular pages.

From your Shopify admin, go to Online Store > Themes.

Find the theme you want to edit, click the … button to open the actions menu, and then click Edit code.

In the layout folder, click the theme.liquid file.

To exclude the search template, paste the following code on a blank line in the <head> section:

{% if template contains ‘search’ %}
<meta name=”robots” content=”noindex”>
{% endif %}”

WordPress Search Box Spam Mitigation

It’s quite easy to mitigate search box spam with WordPress. Users of the Yoast, Rank Math, and AIOSEO SEO plugins have their search results pages automatically set to noindex by default. Additionally, some page builders and themes like Divi (and its Extra theme) will automatically not generate spammy words and URLs in response to searches and instead will inject a few sentences saying that the search produced no results.

Robots.txt Knowledge

Effective SEO requires a wide range of knowledge. Robots.txt contains some quirks that can cause it to be less effective than intended, so it’s useful to read up on the official specifications in order to keep up to date.

Featured Image by Shutterstock/Stockinq

https://www.searchenginejournal.com/google-says-why-it-may-ignore-robots-txt-and-negatively-impact-seo/583475/


The AI Overviews YouTube Gap: The Platform Your Team Skipped For 20 Years via @sejournal, @gregjarboe

I uploaded my first YouTube video in August 2006. It was 42 seconds long, promoted an 11-part Christian Science Monitor series about a kidnapped journalist named Jill Carroll, and picked up a grand total of 1,908 views. My client at the time wasn’t impressed by that number, and honestly, neither was I.

Then, the story ran. More than 450,000 unique visitors flooded CSMonitor.com in the next 24 hours, seven times the site’s daily average that July. Page views broke past 1 million, up from a normal day of 121,247. A video almost nobody watched had just driven the biggest traffic day the site had ever seen.

That gap, between what a video earns on its own platform and what it triggers everywhere else, is the whole story of YouTube marketing. It was true in 2006. It’s true now, except the stakes have gone from one newsroom’s traffic spike to a $60 billion slice of the U.S. economy, and most SEO, content marketing, and social media departments still haven’t caught up.

The Proof Arrived On LinkedIn, Not In A Business Publication

YouTube CEO Neal Mohan posted the company’s 2025 U.S. Impact Report last week, built on research from Oxford Economics. YouTube’s creative ecosystem contributed more than $60 billion to U.S. GDP last year and supported over 540,000 full-time equivalent jobs. Every one of the 50 states now has at least 10 channels pulling more than 1 million monthly views. Creators who once needed to relocate to a media hub can now build a real business from anywhere, and the money they earn flows back into hiring local editors, renting studio space, and paying local suppliers.

YouTube’s own blog post by Alexandra Veitch, published the same week, filled in a number Mohan didn’t mention. Seventy-six percent of small- and medium-sized businesses with a YouTube channel say the platform helped them grow their customer base by reaching new audiences. That’s a distribution channel most marketing departments never built.

I’ve watched this ecosystem grow from the outside in and the inside out for two decades. The SEO and content marketing industry treated YouTube as a nice-to-have side channel for far too long, and that decision is now costing them exactly the audience Google’s AI systems are learning to trust most.

→ See also: YouTube CEO Reveals Your Video Marketing Strategy For 2026

Why The Gap Matters More In 2026 Than It Did In 2006

YouTube videos are surfacing inside AI Overviews with increasing frequency, often as the primary cited answer rather than a supplementary link. A platform your department may have deprioritized for years is becoming one of the more reliable ways to get cited inside the answer engines reshaping search.

Departments that spent two decades building text-based content and backlink profiles now find themselves without the relationships, the production workflow, or the institutional muscle memory to show up where a growing share of searchers, and AI systems, are actually looking.

The Fix Isn’t A YouTube Strategy, It’s A Partnership Strategy

Building an in-house YouTube presence from zero in 2026 is slow, expensive, and probably the wrong first move for most brands. The faster path runs through the 540,000 full-time creators the Oxford Economics research already counted. Somewhere in that number is a creator who already has the audience, the production skill, and the credibility inside your product category that your department spent 20 years not building.

That means marketers need to do three things, starting now.

  1. Identify creators who are relevant and influential in your specific category, not the biggest names in your budget range. A mid-sized channel with genuine authority in a niche will outperform a broad lifestyle creator every time a purchase decision is on the line.
  2. Fold influencer partnerships directly into SEO, content, and social workflows, rather than running them out of a separate influencer budget line with separate goals. The creator’s video needs to be treated as content that earns citations and drives search visibility, not just a one-off sponsorship.
  3. Measure the referral and citation effect, not just the view count. My 1,908-view video wasn’t designed to build an audience on YouTube. It was designed to persuade the editors at CNN.com, MSNBC.com, Yahoo News, AOL News, The Huffington Post, and Boing Boing to prepare stories about “Hostage: The Jill Carroll Story.” And their news coverage moved 450,000 people to The Christian Science Monitor’s website. The lesson has never changed. A creator partnership’s value shows up downstream, in traffic, in AI citations, and in conversions, far more than it shows up in the video’s own view counter.

My Take

Marketers who are still asking whether they need a YouTube strategy are asking the wrong question 20 years too late. The right question is which creators already own the audience and credibility your department was supposed to build, and how fast you can get a real partnership in place before a competitor gets there first. The agencies and in-house teams that treat influencer marketing as a separate line item from SEO and content strategy are going to keep losing ground in an AI search environment that doesn’t care which budget produced the video, only whether it earned the citation.

I didn’t plan to become a video marketer in 2006. A reporter’s kidnapping story and a 42-second clip did that for me. Twenty years later, the lesson is the same one Neal Mohan’s numbers just confirmed at scale. The audience was never the hard part. Showing up where it already lives is.

More Resources:


Featured Image: Roman Samborskyi/Shutterstock

https://www.searchenginejournal.com/the-ai-overviews-youtube-gap-the-platform-your-team-skipped-for-20-years/582702/


Search Growth Slows, Publishers Weigh Leaving Google – SEO Pulse via @sejournal, @MattGSouthern

Welcome to the week’s Pulse: updates affect the legal footing of the SERP tools you rely on, what it’s worth to keep your content in Google’s index, and where the revenue behind Search is heading.

Here’s what matters for you and your work.

Search Revenue Grows 17%; Pichai Points To Gemini 4

Alphabet reported Q2 2026 earnings, with Google Search & other revenue up 17% year over year to $63.27 billion. The growth rate eased from 19% in Q1, the first slowdown after four quarters of acceleration. On the earnings call, Pichai pointed to Gemini 4, now in pretraining, as the model Google needs to compete at the frontier.

Key facts: In the earnings release, CEO Sundar Pichai said the company’s “popular AI features are driving Search query growth,” and Chief Business Officer Philipp Schindler attributed the increase to strong vertical performance, led by retail. Alphabet also raised its 2026 capital spending forecast to $195 billion to $205 billion. In the call’s Q&A, Pichai named coding and agentic coding as areas where Google needs to improve.

Why This Matters

Search is still growing by billions a quarter, and Google credits its AI surfaces. The slowdown is one data point, not a trend, but it lands alongside another raise in spending meant to make AI the engine of a business that just grew slightly slower. How that bet plays out will shape which surfaces you optimize for and which ad formats reach your audience.

Read our full coverage:

Google Search Revenue Growth Eases After A Year Of Acceleration

Pichai Says Google Needs Gemini 4 To Compete At The Frontier

Court Dismisses Google’s DMCA Claims Against SerpApi

A federal judge dismissed Google’s DMCA claims against SerpApi, ruling that blocking automated access to public search results isn’t copyright circumvention when those results contain no copyrighted content.

Key facts: The judge granted SerpApi’s motion to dismiss both anti-circumvention claims under the Digital Millennium Copyright Act. Claims based on results without copyrighted content were dismissed without leave to amend, while claims involving licensed images in results were dismissed with permission for Google to amend within 21 days. The court rejected SerpApi’s argument that Google lacked the right to sue, and found Google plausibly alleged circumvention of its SearchGuard system.

Why This Matters

Many of the tools practitioners rely on, from rank trackers to SERP monitors, depend on scraped search results, and this round mostly went their way. The court held that getting past an access control isn’t a DMCA violation when the results behind it contain no copyrighted content. Google can still amend its narrower claims, and a district court order doesn’t bind other courts. For now, the decision gives scraping-based tools language to cite.

What People Are Saying

Rand Fishkin, co-founder and CEO of SparkToro, wrote on X:

“If you crawl the web, or rely on any product that does, you should be deeply grateful to @serp_api today.”

Independent SEO consultant Nick LeRoy posted on X:

“I’m not as anti-Google as most, but this is a fantastic victory for the industry (thanks @serp_api)”

Lily Ray, founder of Algorythmic, reacted on LinkedIn:

“Wow, the Google lawsuit against SerpAPI was dismissed 🤯 I wonder if we will see more Google scraping from the LLMs and tracking tools now… And a lot more noise in our GSC reporting 😕”

Read our full coverage: Court Dismisses Google’s DMCA Claims Against SerpApi

Publishers Put Conditions On Staying In Google Search

USA Today Co. CEO Mike Reed says the company is prepared to delist from Google in the next six to twelve months, according to Adweek. Several large publishers are weighing whether staying in the index is still worth the exchange.

Key facts: A Wall Street Journal report this week said Reddit is reevaluating its $60 million per year licensing deal with Google, Politico and Reuters are considering limits on Google’s crawler, and People Inc. described blocking Google entirely as an option. 

Why This Matters

Major publishers are now saying publicly what it would take to leave. If licensing becomes the answer, the value of content in Google’s index turns into a negotiated number instead of an assumed trade for traffic, and those negotiations could shape the terms smaller publishers get.

What People Are Saying

Cyrus Shepard, founder of Zyppy, wrote on LinkedIn after reading the Journal report:

“The reward to publishers is no longer there, and still declining.”

Former Ad Age editor Jack Neff, reacting on LinkedIn to Adweek’s earlier report on July 10, raised the cost side:

“If publishers blocking Google crawlers becomes widespread, I do truly fear how much worse the quality of AI Overviews can become as Gemini access to professional content gets further throttled.”

Read Adweek’s full report: Once Unimaginable, Publishers Are Preparing To Opt Out Of Google Search

EU Issues First DMA Fines Against Google, With Data-Sharing Terms Already Set

The European Commission fined Google €890 million on July 23, its first penalties against the company under the Digital Markets Act, one week after adopting binding decisions that require Google to share anonymized search data with rivals.

Key facts: The Commission issued a €460 million fine for favoring Google’s own shopping, hotel, transport, and sports results over comparable third-party services, and a €430 million fine for restricting developers from steering users outside Google Play. The separate July 16 decisions require Google to share anonymized query, click, view, and results-position data with eligible rivals, including AI chatbots that qualify as search engines, and to open Android to competing assistants. 

Why This Matters

The self-preferencing finding puts EU results-page layout under a compliance deadline, so how Google displays its services against third-party listings could change there within 60 days. The data-sharing decisions could eventually widen which search engines and chatbots can build competitive retrieval systems, and with that, who cites sources and sends referral traffic. Neither decision changes rankings on its own, and what becomes visible will depend on how Google complies.

Read our full coverage: Google Must Share Anonymized Search Data With Rivals

Theme Of The Week: Everyone Is Renegotiating With Google

Google Faces Pressure From Three Directions

A court ruling, publisher negotiations, and EU enforcement are putting pressure on Google from three directions.

Court

Dismissed Google’s DMCA claims involving search results without copyrighted content.

Legal pressure

↓

Publishers

USA Today Co. says it may leave Google Search within six to twelve months. Others are weighing crawler limits or licensing terms.

Commercial pressure

→

At the centerGoogle

$63.27BQ2 Search & other revenue+17% year over year

$195–205B2026 capex forecast

←

European Commission

Google received €890M in DMA fines. Separate decisions set search-data sharing and Android requirements.

Regulatory pressure

Every story this week is a party redrawing its deal with Google. A federal court narrowed which legal tools Google can use against companies that collect its results. Publishers are turning their presence in the index into a negotiation. The EU is fining how Google lays out its results page while compelling its search data outward. And the earnings show what sits on Google’s side of the table, a $63 billion quarter from Search with record spending riding on AI.

The exchange that defined the open web for two decades, content and access in return for traffic, is being repriced from every direction at once.

Top Stories Of The Week:

More Resources:

https://www.searchenginejournal.com/seo-pulse-search-growth-slows-publishers-weigh-leaving-google/583329/


AI Browsers Are Backward Because Agents Never Needed The Visual Layer via @sejournal, @slobodanmanic

An AI agent does not need the visual layer of your website, and it should never have needed it. That one idea is why the whole category of AI browsers is backward. We spent years building websites design-first and lost the web’s semantics, its accessibility, and the fundamentals underneath them along the way. So when a machine shows up to actually use the web, it cannot find the meaning we stopped encoding, and instead of putting that meaning back, the industry gave the machine a browser to work through and a screen for us to watch. On July 9, 2026, OpenAI retired ChatGPT Atlas, the standalone AI browser it launched only nine months earlier, and the death of the best-funded version of that idea is a good moment to say plainly why it was never the right one.

Atlas Lasted 9 Months

OpenAI launched Atlas in October 2025 as a standalone browser with an agent built in, positioned as a challenger to Chrome. On July 9, 2026, it announced the end. Atlas stops working on August 9, and its browsing folds into the ChatGPT desktop app and a Chrome extension. OpenAI’s own help-center article is titled “Evolving Atlas into ChatGPT for browser-based agentic work,” which is a generous way to describe discontinuing a browser about 30 days after the announcement.

It is not the first product OpenAI launched with a keynote and cut a few months later. Sora, its video app, was discontinued in April 2026, reportedly after earning only a couple of million dollars in total revenue against the cost of running it. Sora lasted six months. Both were cut in a “defend the core” push led by OpenAI’s applications chief, Fidji Simo.

The reason Atlas died matters more than the fact that it did, and OpenAI gives you a reason worth reading skeptically. The company’s line is that it is not walking away from agents on the web, only moving that capability out of a standalone browser and into the app people already use. That may well be true. It is also the kind of thing a company says when it kills a product and would rather call it an evolution than a retreat. OpenAI has not shared usage or cost figures for Atlas, so the tidy “wrong container” explanation sits right next to a plainer one: not enough people wanted a browser they had to be talked into. You do not need to settle which it is, because the deeper reason does not depend on OpenAI admitting anything.

The common read of these shutdowns is technical: the CAPTCHAs and the JavaScript walls that trip up anything trying to act on a modern website. That friction is real, but it was never the deep reason. Visual browsing was always a bad way to do this. At best, it is a necessary evil, the bridge you cross while the web still is not built for agents. I mapped the browsers carrying this wave earlier this year, and the arrival they represent is settled: Agents are coming to your website whether or not any single browser survives. What is not settled is the shape, and Atlas dying makes it plain. A machine built to squint at a page made for human eyes was always the wrong end state. One shutdown looks like engineering. Two, from the outfit with more money and distribution than anyone else building these, is the shape.

Vision Agents Are The Bet Everyone Else Is Doubling Down On

Atlas dying does not mean the AI browser is dead. Perplexity’s Comet, The Browser Company’s Dia, and Gemini inside Chrome are all still live, and underneath them a bigger bet is getting louder: vision-based agents, the “computer use” models that operate a website the way a person does, by looking at the rendered screen and clicking what they see.

The selling point is genuinely seductive. A vision agent works on any website with zero effort from the website’s owner. No integration, no standard to adopt, no cleanup. You point it at the same page a human sees and it figures out the rest. If that is the future, then arguing that agents need a machine-readable web sounds naive, because the entire appeal of a vision agent is that it does not need one. This is the tide, and it is worth taking seriously.

We Built A Web That Forgot How To Talk To Machines

Websites were built design-first, and somewhere in the process we lost the web’s semantics, its accessibility, and all the other fundamentals. The cause was not laziness, it was incentives. The focus went to developer experience and to frameworks that make it easy to build components that look a certain way, without anyone caring much whether those components are fundamentally correct underneath. A button became a styled <div> with a click handler. A form control became a bundle of nested elements that renders fine and mean nothing. To a person, all of it works, because a person brings eyes and a lifetime of pattern-matching to the page. To a machine, a <div> that behaves like a button is not a button. It is a box.

None of this is new, and the people who have been paying for the missing semantics are not AI agents. They are the people who use screen readers and other assistive technology. A screen reader cannot tell that the styled box is the checkout button, and neither can an agent, because both read the same thing: the accessibility tree the browser builds from your markup. A bare <div> never enters that tree as a button, so it is invisible to both, no matter how obvious it looks on screen. The accessibility community has described this exact failure for years, mostly to an industry that treated it as a compliance checkbox. The AI agent is the new screen reader. It is the same wall, hit by a much larger and much better-funded population, which is the only reason the industry suddenly cares.

The AI Browser Is A Workaround For A Broken Web

Once you see that agents read meaning and not pixels, the AI browser flips from a breakthrough to a workaround. Under the hood, an agent does not look at your page so much as read it, walking the same document structure and accessibility tree a screen reader walks. So what does a browser you can watch actually add? A window for a person to look through. Not for the agent, which reads the structure without rendering anything, and not for you, who needs to watch an agent read a page about as much as you need to watch a server answer a request. The watchable browser was theater from the start.

Pixels come in only as a fallback. When a page’s structure is broken enough, the accessibility tree is useless, and the agent, or the vendor behind it, falls back to looking at the rendered screen. Vision is the patch for a web that lost its semantics, not the way agents were built to work, and even the patch does not need a window you sit and watch. The cause under all of it is the same: a web that lost the ability to speak to machines.

There is a second reason these browsers exist, and it is less flattering. A visual agent clicking through a website in real time is a demo. It is something a company can put on a stage and impress people with, which is a large part of why they get built and hyped, especially at OpenAI. The receipt is the lifespan. A product built to be shown off more than used tends to have a short one. Atlas launched against Chrome with a keynote and was gone in nine months. When the spectacle is the point, the shutdown is only a matter of time.

Vision Agents Step Over The Mess Instead Of Cleaning It Up

The vision-agent bet, the one that says the machine should look at the page like a person, is the perpetual workaround. It is stepping over the mess on the floor every single day instead of cleaning it up once. Every visit, the agent re-derives from pixels what the page could have told it directly. That is slower, more expensive, and more fragile than reading the meaning, and it stays that way forever, because nothing underneath ever gets fixed. The labs can double down on it as much as they like. Working around something broken, instead of fixing it, is a bad long-term bet even when the short-term demo lands.

To be fair, vision agents do work on any website today with no effort from the owner, because the semantic web is broken enough that looking at the page is often the only reliable option right now. That is exactly why telling everyone to adopt a standard has never fixed this on its own. But “the workaround is the only thing that works today” is an argument for repairing the underlying web, not for pretending the workaround is the destination. The website that stays broken pays the vision-agent tax on every single visit. The website that fixes its fundamentals stops paying it.

The Fix Is The Fundamentals You Already Owed The Web

The move for anyone who runs a website is two things, and the first one is free: Learn to tell hype from real. Atlas’s birth and its death were both more hype than news. The launch was a browser war that was never going to happen, and the shutdown is a company cutting a side project to defend its core. Neither should move your strategy, because neither was ever about your website. Once you can see the visual browser for the demo it is, you stop chasing every new shell the labs put an agent inside.

The second thing is the work, and it is not glamorous. Put the fundamentals back. Are your messaging and story consistent across your website, so a machine reading it comes away with the same understanding a person would? Is your website easy to load and easy to read, without a wall of JavaScript standing between the agent and your content? Can a machine identify what your business is, read what is on the page, and actually use it? That is the whole of Machine-First Architecture, and none of it was invented for AI. It is the accessibility and the semantics the web always owed its users, finally worth doing because the cost of skipping them stopped being invisible.

Do that, and you are ready for any agent, in any shell, no matter what the labs hype next. A website that reads cleanly to a machine does not care whether that machine arrives in a standalone browser, a desktop app, a Chrome extension, or something nobody has announced yet.

The work in front of you was never a new burden invented by AI. It is the web done right, the way it should have been done for the people who needed it long before the machines showed up. Atlas is a footnote by August. The next agent, in whatever shape it takes, will still arrive at your website and try to understand it. Give it something to read, and you win no matter which browser dies next.

More Resources:


This post was originally published on No Hacks.


Featured Image: Igor Link/Shutterstock

https://www.searchenginejournal.com/ai-browsers-are-backward-because-agents-never-needed-the-visual-layer/583056/


Are We Repeating History & Risking Backlink Penalties Again? via @sejournal, @TaylorDanRW

The race to monetize AI visibility services, claiming new acronyms and extending existing fields of practice as whole new trenches of engineering, is something we’ve witnessed a lot over the past couple of years.

We’re seeing new entrants to the market because they see a gap, but no one is really stopping to ask the question: Why does a gap exist in the first place?

The truth is simple. The gap has, more often not been left open by accident, but rather created deliberately off the back of Google changing its tack and introducing penalties for the exact same manipulation practices that people try to repackage today as solutions for AI visibility.

In the early days of SEO, it was very different from how it is now, regardless of AI and Google’s overall search features. How Google indexed and how Google weighted weak factors that led to ranking order, have changed significantly over the years. The two main mechanisms of manipulation have always been content and links.

The rise and fall of AI-generated content, and how there is a misunderstanding between content production and Google’s crawl economics, I’ve already covered in another article. What we’re now starting to see is a very confident entry into the market of services playing on the link side of how visibility is generated, based on a market gap where people are trying to exploit without actually understanding where and why those bad habits were driven underground.

A Short History Of Backlink Manipulation

Google’s Penguin algorithm, which is now a part of the core algorithm, was a series of standalone updates that focused on penalizing link manipulation practices. Not only in the volume of backlinks, but also the over-optimization of anchor text, unnatural patterns of gaining links, random and sudden spikes with little justification as to why the spike existed, and also patterns of websites linking out to random websites and non-sequential content themes.

Google does this now algorithmically at scale. If we can quickly and easily see the link manipulation going on, just by using exports from third-party tools or even in the user interface of third-party tools, we can guarantee that Google and Bing are also able to see this manipulation at scale.

Backlink Manipulation Penalties Still Exist

A common misconception about Penguin becoming a part of the core algorithm is that Google simply ignores spammy links – that you could almost run free and buy backlinks and manipulate your profile to your heart’s content, and you won’t receive a penalty because Google would have to ignore the bad efforts. Anyone believing this is gravely misinformed.

Over the past year, I’ve seen more link-based penalties occurring than in the five years before it. That’s because people have bought into buying backlinks for AI purposes without understanding, and potentially ignoring, the underlying consequences of how they appear within Google and Bing’s indexes. Being present for various fan-out, grounding, and stacked queries also plays a role in AI visibility, let alone the fact that you need to be strong and visible when it comes to being included in training data.

Buying backlinks from a marketplace has been a risky practice ever since Penguin was introduced. Failing to acknowledge and understand that doing something for AI doesn’t make it an agnostic SEO practice, and you could very easily damage one while having a minimal impact on the other.

How Gurus Are Accidentally Saving The Industry

There is a certain irony to new entrants to the organic visibility market pushing these practices. What we’ve learned from them, they also are very likely aligned with the commentary that SEO is dead and a dead-end channel for investment, but what they’re actually doing is securing the future of SEO for the rest of us.

By repackaging tactics we regard as short-termist or spammy, what they’re actually doing is creating a large pile of clutter and signal noise that Google will inevitably sweep through and ignore or penalize, just as it has done during every previous cycle since Penguin was introduced. When the signal noise is gone and cleared, only those who have not been penalized and not engaged in these tactics will remain.

SEO has always been about understanding human search intent, providing accurate answers, and building genuine authority over periods of time.

Technology may be evolving from standard lists of links to conversational answer engines, but the fundamental economics of how Google crawls and understands websites, and the fundamental economics of how Bing does the same, are relatively the same, albeit with an added layer of AI in terms of processing layered on top.

Far from killing the industry, the current wave of spam will only make high-quality SEO work more valuable than ever before.

More Resources:


Featured Image: YoloStock/Shutterstock

https://www.searchenginejournal.com/are-we-repeating-history-risking-backlink-penalties-again/583070/


Alphabet Q2 Earnings Show $5.85 Billion Negative Free Cash Flow via @sejournal, @martinibuster

Alphabet’s second quarter earnings results show that Google is earning massive amounts of money but is also spending so much that it reported a negative free cash flow due to infrastructure spending.

Massive Earnings

Q2 2026 revenue is $119.8 billion, which is up 24% year over year.

Where The Money Comes From

The earnings release shows that Search & Other account for most of the earnings, $63.3 billion. Google Cloud accounts for $24.8 billion, Google subscriptions, platforms & devices accounts for $12.9 billion, and YouTube ads brought in $11.1 billion.

  • Google Search & other: $63.3 billion
  • Google Cloud: $24.8 billion
  • Google subscriptions, platforms & devices: $12.9 billion
  • YouTube ads: $11.1 billion

Total revenue: $119.8 billion

Google’s strategy of diversifying their revenue streams is clearly paying off. Google earned $2.9 billions dollars more in the second quarter from Search & Other than it did in the first quarter, an increase of +4.8%.

The difference between first and second quarters show that Google is consistently earning more across all of its businesses.

Earnings Growth Q1 2026 – Q2 2026

  • Google Cloud: +$4.8B (+23.8%)
  • Google Search & other: +$2.9B (+4.8%)
  • YouTube ads: +$1.2B (+12.2%)
  • Google subscriptions, platforms & devices: +$0.5B (+4.2%)

Many in the search marketing and publishing communities are unhappy because Google’s AI search strategy sends less clicks to websites than classic search did. Another complaint is that Google is hoarding traffic within its own ecosystem of services and websites.

Is that the reason why YouTube’s earnings soared by 12.2% this quarter over last and Search earnings increased by nearly 5%?

$5.85 Billion Dollars Negative Free Cash Flow

Perhaps the most surprising detail to come out of the earnings result is that Google is running a negative free cash flow of nearly six billion dollars.

Negative free cash flow does not mean that Alphabet lost money this quarter, they did not. It means Alphabet spent more cash than it generated after accounting for capital investments.

Free cash flow: -$5.855 billion

Alphabet’s second quarter operating cash flow was $39.069 billion. Their capital expenditures equaled $44.924 billion. Their free cash flow for Q2 2026 was -$5.855 billion (operating cash flow minus capital expenditures).

Google’s investor presentation explained why they are running a negative free cash flow in the second quarter of 2026:

Alphabet’s presentation explained why they’re spending so much:

“We’re innovating at scale with incredible velocity.

Since launching Gemini 3 last November, our momentum has accelerated. We’ve rolled out increasingly capable generative media models; shipped features across Chrome and the Gemini app, launched Antigravity and our first model
in our Gemini 3.5 series.

Recently at our I/O annual developer conference, we showcased new advances across models, coding, and agents. This progress reflects our deep focus on delivering tangible value to people in the products they use every day.

Supporting all of this at scale for our users, while also serving enterprises and developers around the world, requires massive compute investments.

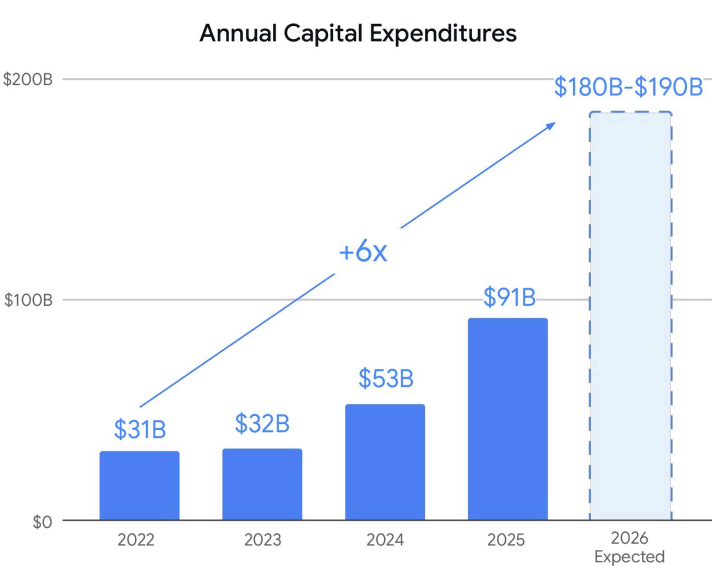
In 2022, we spent approximately $31 billion in CapEx. This year, we expect that number to be 6 times larger than 2022 and double last year’s at $180-190 billion. And next year, we expect it to significantly increase compared to 2026. The overwhelming majority of this spend will be in technical infrastructure.”

The Q2 earnings release says Alphabet raised $49.6 billion through an equity offering, specifically stating that the proceeds would be used for “capital expenditures to scale AI infrastructure and global compute.”

That’s interesting because it shows how extraordinary AI-related spending has become because Alphabet is not funding it all from operations, it also raised tens of billions of dollars in new equity to help finance their massive investment in AI data centers.

Capital Investments Spiraling Upward

The earnings release shows that Alphabet spend $44.924 billion dollars on “Purchases of property and equipment.” That’s about double the amount spent in the second quarter of 2025, $22.446 billion dollars.

What were those properties and equipment? A BBC report quoted Google’s Chief Financial Officer explained that 60% of that was for buying servers and 40% was for data centers.

The quoted explanation:

“Anat Ashkanazi, Google’s chief financial officer, noted on a call with financial analysts that the company had shown negative free cash flow due to growing capital expenditures, essentially all of which was related to AI spending.

She said the company spent $45bn in the second quarter, with 60% of the cost going towards servers and the remaining 40% going towards data centres.”

The Q2 release featured a graph showing that Google’s expenditures are spiraling upward, with estimates that the year will end by spending six times what Google spent in 2022, at the beginning of the generative AI boom.

Takeaways

  • Alphabet reported strong revenue growth across its businesses.
  • Search remains Alphabet’s largest revenue source, while Google Cloud is its fastest-growing business.
  • Revenue increased across every major business segment from Q1 to Q2, showing strong momentum across a diversified range of services and products.
  • Alphabet generated enormous profits while simultaneously reporting a $5.85 billion dollar negative free cash flow.
  • Negative free cash flow was caused by spiraling AI infrastructure spending.
  • AI infrastructure investment has become so large that Alphabet supplemented operating cash with a major equity raise to help finance it.
  • Capital expenditures are accelerating at an extraordinary pace, with spending expected to reach six times 2022 levels by the end of 2026.
  • The spending is primarily funding servers and data centers that support Google’s long-term AI strategy.

Featured Image by Shutterstock/Shutterstock AI

https://www.searchenginejournal.com/google-q2-earnings-show-5-85-billion-negative-free-cash-flow/583259/