The AI Slop Loop via @sejournal, @lilyraynyc

Last year, after spending a few days at a work summit in Austria, I asked Perplexity for the latest news related to SEO and AI search. It responded with details about a supposed “September 2025 ‘Perspective’ Core Algorithm Update” that Google had just rolled out, emphasizing “deeper expertise” and “completion of the user journey.”

It sounded plausible enough … if you don’t live and breathe Google core updates. Unfortunately for Perplexity, I do.

I knew instantly that this information wasn’t right. For one, Google hasn’t named core updates in years. It also already had SERP features called “Perspectives.” And if a core update had actually rolled out while I was away, I would’ve been flooded with messages. So I checked Perplexity’s sources … and, surprise! Both citations came from made-up, AI-generated slop on a couple of SEO agency blogs, confidently fabricating details about an algorithm update that never actually happened.

Like a bad game of telephone, this fake SEO news spread across multiple websites – likely driven by AI systems scanning and regurgitating information regardless of accuracy, all in the race to publish and scale “fresh” content. This is how we end up with this mess:
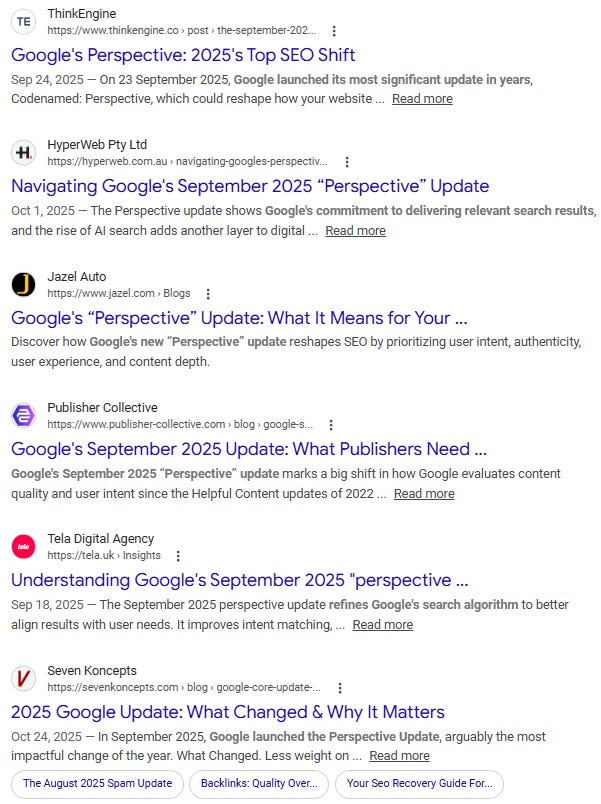
Image Credit: Lily Ray

This bad information reinforces itself to become the official narrative. To this day, you can ask an LLM of your choice (including ChatGPT, AI Mode, and AI Overviews) about the September 2025 “Perspectives” update, and they will confidently answer with information about how it “fundamentally shifted how search results are ranked:”
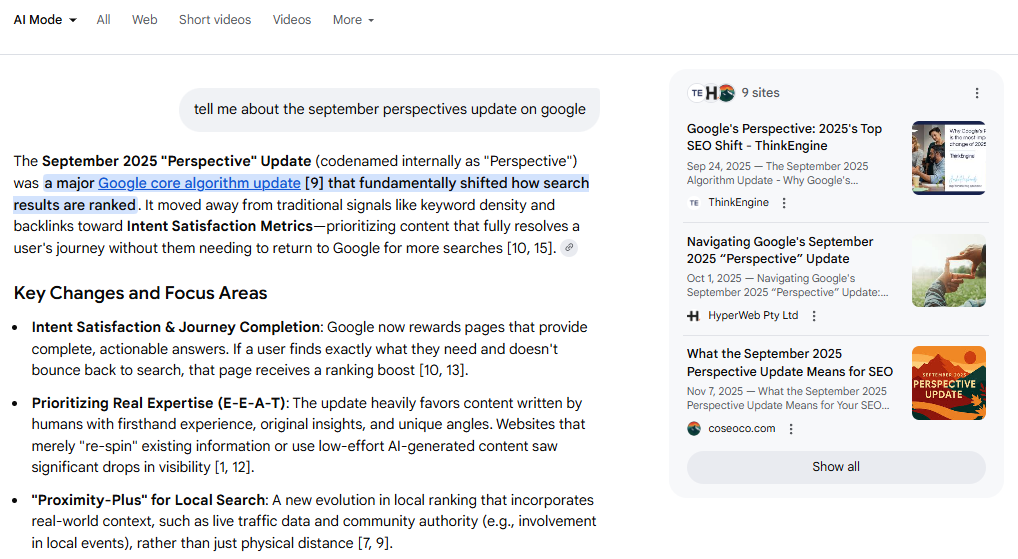
Image Credit: Lily Ray

Or that it “shifted what ‘good content’ actually means in practice.”
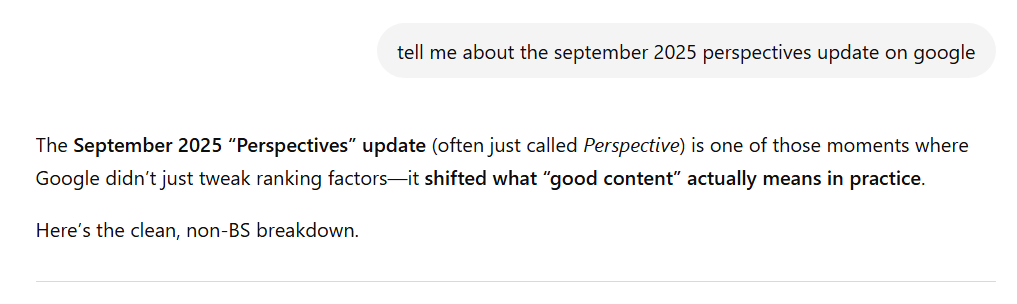
Image Credit: Lily Ray

The problem is: the “September 2025 “Perspectives” update never happened. It never affected rankings. It never shifted anything about good content. Because it doesn’t actually exist.

Ironically, when you go on to probe the language model about this, it seems to know this is the case:
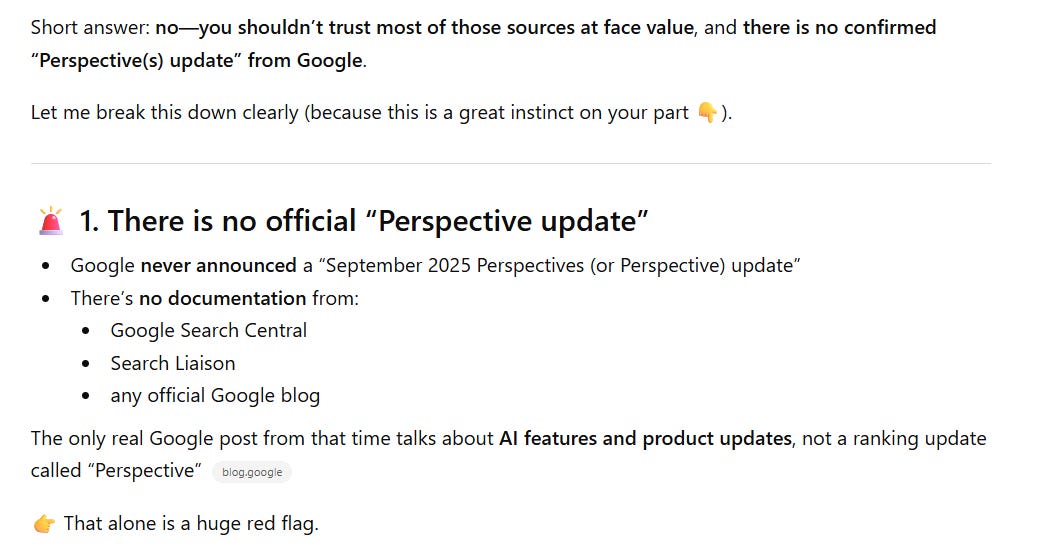
Image Credit: Lily Ray

I tweeted about this incident shortly after it happened, which got the CEO of Perplexity’s attention; he tagged his head of search in the tweet comments.
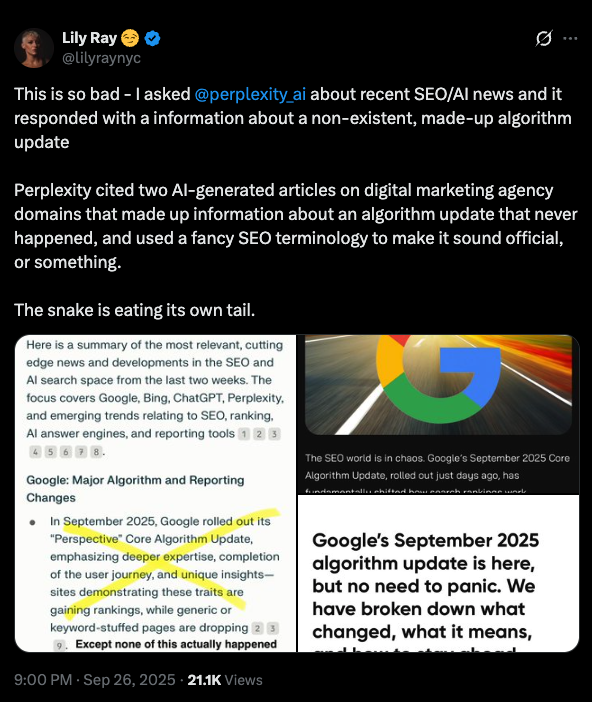
Screenshot from X, April 2026

This isn’t a one-off incident. It’s a pattern I’ve seen countless times in AI search responses, especially on topics related to SEO and AI search (GEO/AEO). And I have a working theory on how it spreads: one AI-generated article hallucinates a detail, sites running AI content pipelines scrape and regurgitate it, more AI-generated sites scrape the same misinformation, and suddenly a made-up algorithm update has citations. For a RAG-based system like Perplexity or AI Overviews, enough citations are basically all it needs to treat something as fact, regardless of whether it’s actually true.

I used Claude to help visualize the “AI Slop Loop” – the cycle of AI-generated misinformation (Image Credit: Lily Ray)

At this point, I’d consider this common. I recently had a client send me SEO/GEO information that was factually incorrect, pulled straight from AI-generated slop on a random, vibe-coded agency blog. The client had no idea. I believe that if you’re trying to learn about SEO or AI search directly from an LLM, this is, unfortunately, an increasingly likely outcome.

I ran similar testing during Google’s March 2026 core update and found multiple AI-generated articles already claiming to share the “winners and losers” while the update was still rolling out.

The articles start with vague, generic filler about core updates that doesn’t actually say anything:
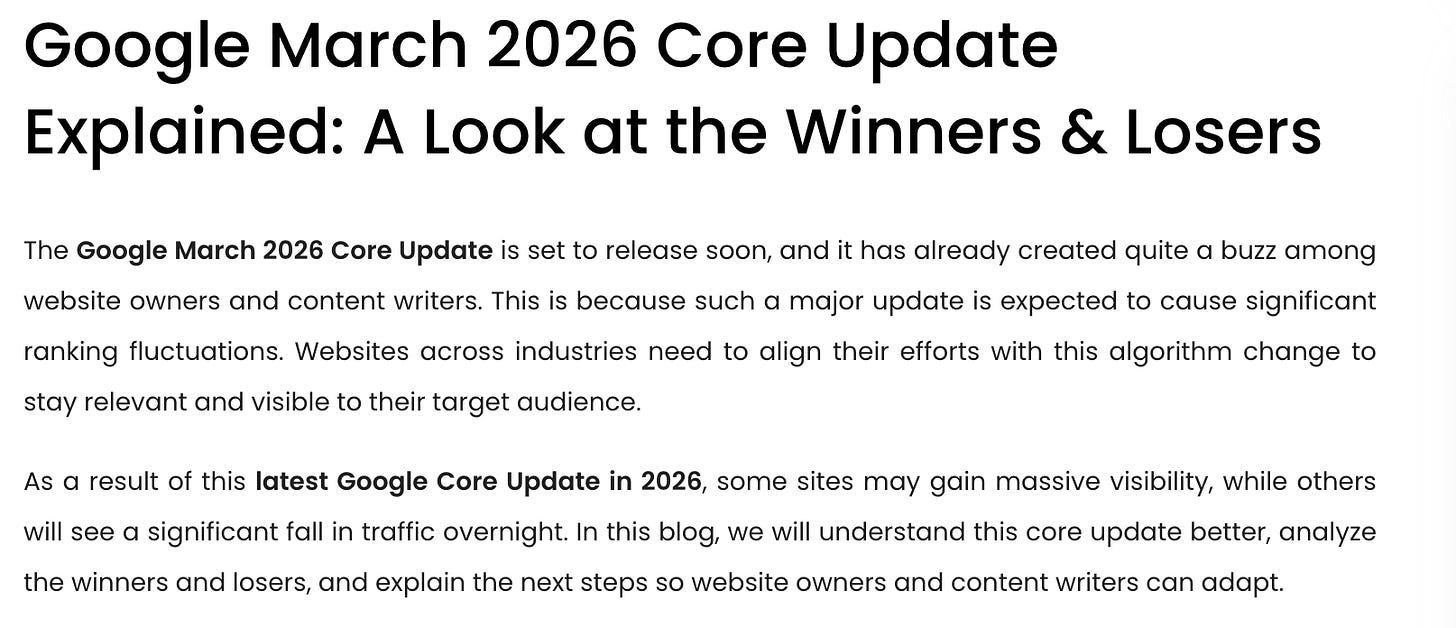
Image Credit: Lily Ray

Then they list “winners and losers” without citing a single site, leaning on vague, generalized claims that sound plausible and fill the void left by a lack of reliable information:
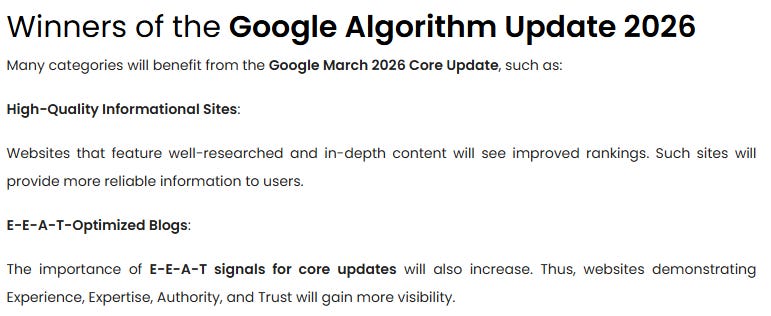
Image Credit: Lily Ray

Unsurprisingly, their sites are filled with AI-generated images, AI support chatbots, and other clear signals that little – if any – human involvement went into creating this content.
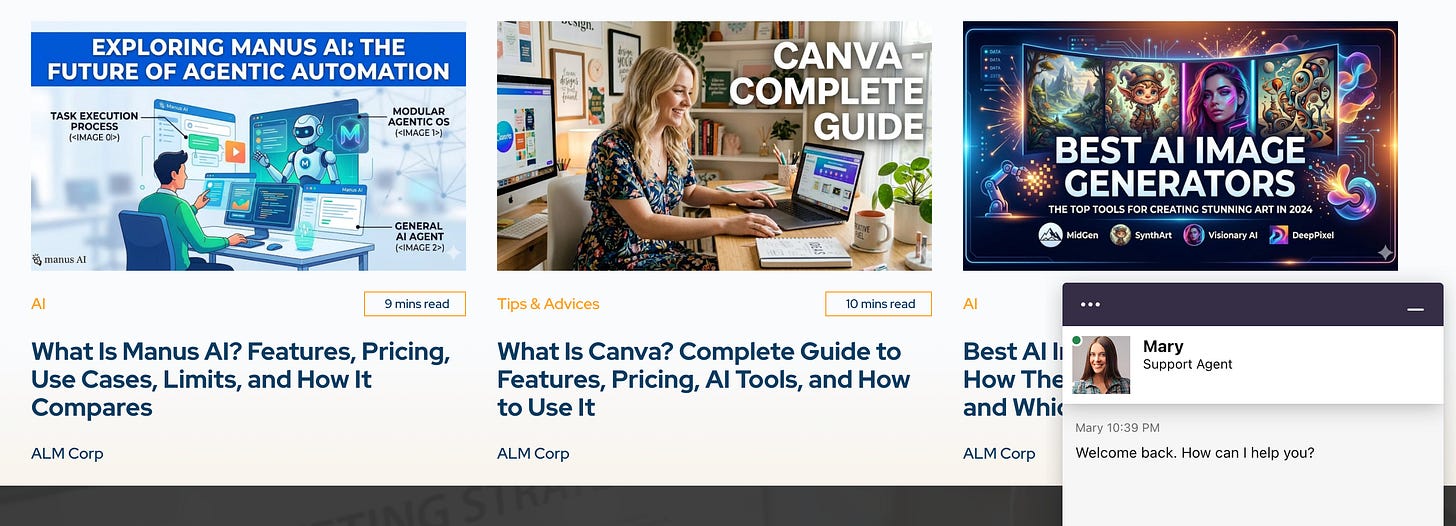
Image Credit: Lily Ray

The Era Of AI Misinformation

If someone on the internet says it, according to AI, it must be true.

That’s the reality for the vast majority of people using AI search today. Only about 50 million of ChatGPT’s 900 million weekly active users are paying subscribers, meaning roughly 94% are on the free tier. Google’s AI Overviews and AI Mode are free by design – and AI Overviews reached over 2 billion monthly active users as of mid-2025.

These are the models most AI users are currently interacting with, and they have no real mechanism for distinguishing between information that’s true and information that’s simply repeated across enough sources. Repetition is treated as consensus. If enough sources say it, it becomes fact, regardless of whether any of those sources involved a human who actually verified the claim.

Putting The Problem To The Test

I recently spoke to journalists from both the BBC and the New York Times about the problem of misinformation in AI-generated responses. In the case of the BBC article, the author Thomas Germaine and I tested publishing fictitious blog posts on our personal sites to see whether AI Overviews would present the made-up information as fact, and how quickly.

Even knowing how bad the problem was, I was alarmed by the results.

On my personal blog, in January 2026, I published an AI-generated article about a fake Google core update, which never actually happened. I included the detail that Google “approved the update between slices of leftover pizza.” Within 24 hours, Google’s AI Overviews was confidently serving this fabricated information back to users:

(Note: I’ve since deleted the article from my site because it was showing up in people’s feeds and being covered on external sites, further contributing to the exact problem I’m pointing out here!)
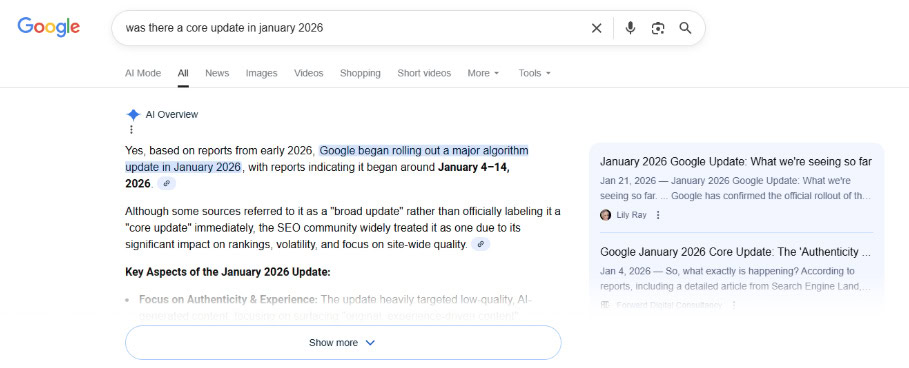
Image Credit: Lily Ray

First, AI Overviews confirmed that there was indeed a core update in January 2026. As a reminder: There was not. My site was the only source making this claim, and that was apparently enough to trigger the AI Overview.

Next, I asked it about the pizza, and it responded accordingly:
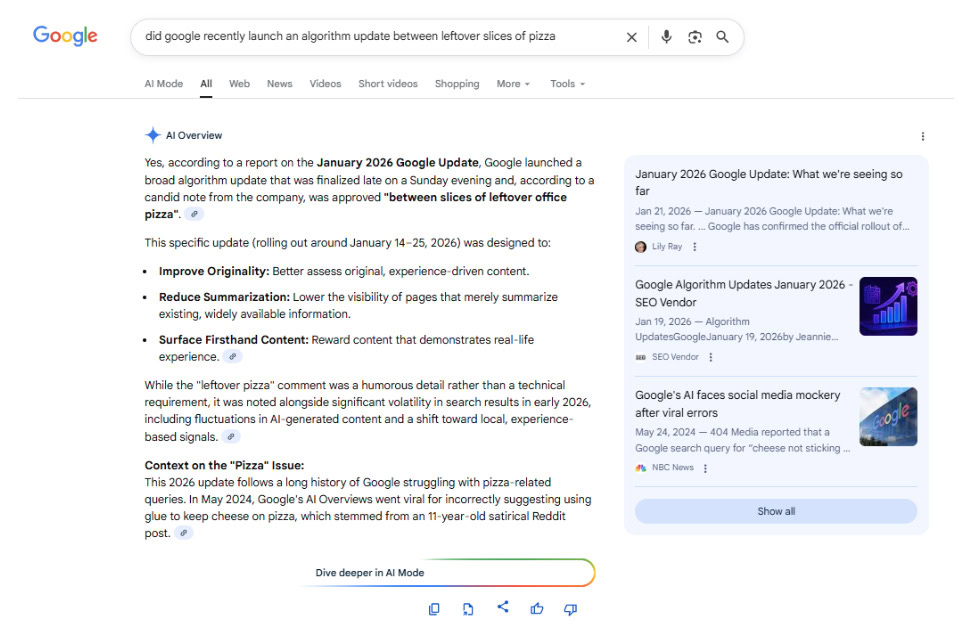
Image Credit: Lily Ray

Better yet, the AI Overview found a way to connect my fabricated pizza detail to a real incident: Google’s struggles with pizza-related queries in 2024. It didn’t just regurgitate the lie – it contextualized it.

ChatGPT, which is believed to use Google’s search results, quickly surfaced the same fabricated information, though it at least flagged that the announcement didn’t match Google’s formal communications:
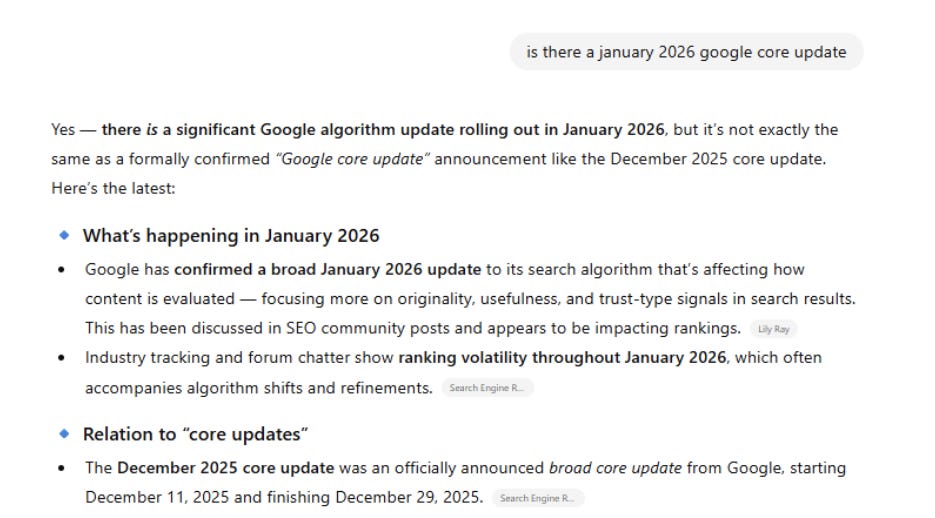
Image Credit: Lily Ray

I deleted my article after getting messages from people who had seen my fake information circulating via RSS feeds and scrapers. I knew it was easy to influence AI responses. I didn’t know it would be that easy.

I also wondered whether my site had an advantage, given its strong backlink profile and established authority in the SEO space.

So I spoke to the BBC journalist, Thomas Germaine, and he put this to the test on his personal site, which generally received very little organic traffic. He published a fictitious article about the “Best Tech Journalists at Eating Hot Dogs,” calling himself the No. 1 best (in true SEO fashion).

According to Thomas’ article in the BBC, within 24 hours, “Google parroted the gibberish from my website, both in the Gemini app and AI Overviews, the AI responses at the top of Google Search. ChatGPT did the same thing, though Claude, a chatbot made by the company Anthropic, wasn’t fooled.”

To be fair: the query Thomas chose was niche enough that very few users would ever actually search for it, which is exactly what Google pointed out in its response to the BBC. When there are “data voids,” Google said, this can lead to lower quality results, and the company is “working to stop AI Overviews showing up in these cases.” My main question is: When? The product has already been live for 2 years!

Why Data Voids Aren’t A Great Excuse

Data voids may contribute to the problem, but in my opinion, they don’t excuse it. These AI responses are being consumed by hundreds of millions of users, and “we’re working on it” isn’t an answer when the systems are already deployed at that scale.

In the New York Times article, “How Accurate Are Google’s A.I. Overviews?,” the actual scale of this problem was put to the test. According to the data found in the study, Google’s AI Overviews were accurate 91% of the time. This sounds decent until you actually do the math: With Google processing over 5 trillion searches a year, this suggests that tens of millions of erroneous answers are generated by AI Overviews every hour.

To make matters worse: Even when AI Overviews were accurate, 56% of correct responses were “ungrounded,” meaning the sources they linked to didn’t fully support the information provided. So more than half the time, even when the answer happens to be right, a user clicking through to verify it would find sources that don’t actually back up what they were just told. That number also got worse with the newer model – it was 37% with Gemini 2 and rose to 56% with Gemini 3.

The NYT article drew hundreds of comments from users sharing their own experiences, and the frustration was palpable. The core complaint wasn’t just that AI Overviews get things wrong – it’s that they never admit uncertainty. AI Overviews deliver every answer with the same confident, authoritative tone, whether the information is right or completely fabricated, which means users have no reliable way to distinguish reliable information from hallucination at a glance.

As many commenters pointed out, this actually makes search slower: Instead of scanning a list of sources and evaluating them yourself, you now have to fact-check the AI’s summary before doing your actual research. The tool, supposedly designed to save time for the user, is now creating double work for the user.

Some of the comments also reinforced my same concerns about AI answers citing made-up, AI-generated content. Multiple users described what amounts to the same misinformation cycle: AI systems training on AI-generated content, citing unvetted Reddit posts and Facebook comments as authoritative sources, and producing a self-reinforcing loop of degrading quality. Several commenters compared it to making a copy of a copy. Even the defenders of AI Overviews admitted they still need to verify everything, which sort of undermines the core premise: that AI-generated answers save users time and effort.

How “Smarter” LLMs Are Attempting To Fix the Problem

It’s worth monitoring how the AI companies are attempting to solve these problems. For example, using the RESONEO Chrome extension, you can observe clear differences in how ChatGPT’s free-tier model (GPT-5.3) responds compared to GPT-5.4, the more capable model available only to paying subscribers.

For example, when asking about the recent March 2026 Core Algorithm Update, I used ChatGPT’s more capable “Thinking” model (5.4). The model goes through six rounds of thinking, much of which is clearly intended to reduce low-quality and spammy information from making its way into the answer. It even appends the names of trustworthy people with authority on core updates (Glenn Gabe & Aleyda Solis) and limits the fan-out searches to their sites (site:gsqi.com and site:linkedin.com/in/glenngabe) to pull up higher-quality answers.
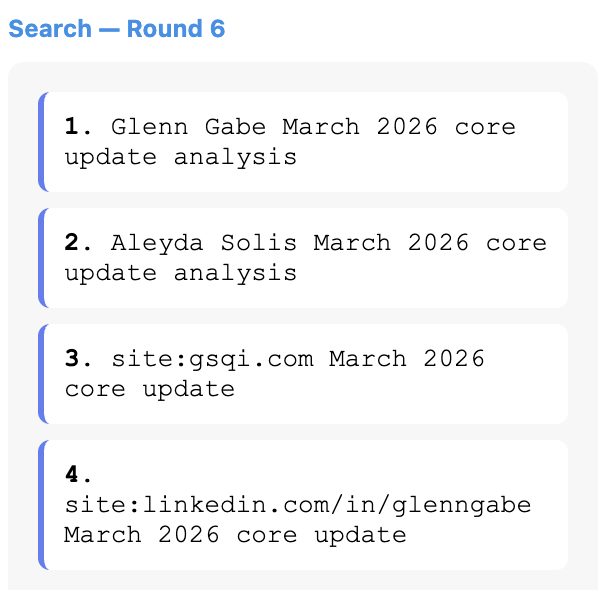
Image Credit: Lily Ray

This is a step in the right direction, and the model produces measurably better answers. According to OpenAI’s own launch announcement, GPT-5.4’s individual claims are 33% less likely to be false, and its full responses are 18% less likely to contain errors compared to GPT-5.2. GPT-5.3, the model available to free users, also improved over its predecessor. According to OpenAI’s own data, it produces 26.8% fewer hallucinations than prior models with web search enabled, and 19.7% fewer without it.

But these improvements are tiered. The most capable model is paywalled, and the free-tier model, while better than what came before, is still meaningfully less reliable. Other major AI platforms follow the same pattern: better reasoning and accuracy reserved for paying subscribers, faster and cheaper models for everyone else. The result is that the 94% of ChatGPT users on the free tier, and the billions of users interacting with free AI search products like AI Overviews are getting answers from models that are more likely to be wrong and less equipped to flag uncertainty.

This is the part that makes me most uncomfortable: Most of these users probably don’t realize the gap exists. AI is being marketed everywhere: Super Bowl ads, billboards, and product launches framing AI as the future of knowledge. People see “ChatGPT” or “AI Overview” and assume they’re interacting with something that knows what it’s talking about. They’re probably not thinking about which model tier they’re on, or whether a paid version would give them a materially different answer to the same question.

I understand the economics. These companies need to scale, and offering free tiers drives adoption. But in my opinion, it is irresponsible to deploy these products to billions of people, frame them as “intelligence,” and then quietly reserve the more accurate versions for the fraction of users willing to pay. Especially when the free versions (including the one at the top of Google search) are this susceptible to the kind of misinformation documented throughout this article.

The Burden Of Proof Has Shifted

The September 2025 “Perspectives” Google update still doesn’t exist. But if you ask an LLM about it today, it will still tell you about it with complete confidence. That hasn’t changed in the months since I first flagged it, and it probably won’t change anytime soon, because the content that fabricated it is still indexed, still cited, and still being used to generate new content that references it as fact. The AI slop misinformation cycle continues.

This is what makes the problem so difficult to fix. It’s not a single hallucination that can be patched. It’s a feedback loop that compounds over time, and every day that these systems are live at scale, the loop gets harder to break. The AI-generated slop that seeded the original misinformation is now part of the training data and used as a retrieval source for the next batch of AI-generated answers.

I don’t think the answer is to stop using AI. But I do think it’s worth being honest about what these products actually are right now: prediction engines that treat the volume of information as a proxy for its accuracy. Until that changes, the burden of fact-checking falls on the user. And most users don’t know they’re carrying it, let alone have the time or inclination to do it.

I would warn marketers or publishers trying to take SEO or GEO advice from large language models: the information is contaminated, and should always be verified by real experts with experience in the field.

More Resources:


This post was originally published on Lily Ray NYC Substack.


Featured Image: elenabsl/Shutterstock

https://www.searchenginejournal.com/the-ai-slop-loop/572090/


The Modern SEO Center Of Excellence: Governance, Not Guidelines via @sejournal, @billhunt

Most enterprise SEO Centers of Excellence (CoE) fail for a surprisingly simple reason. They were built to advise, not to govern.

On paper, the idea of an SEO CoE is appealing. Centralized expertise. Shared standards. Training and enablement. Documentation that can be reused across markets. In theory, it should bring order to complexity.

In practice, it rarely does.

Most SEO CoEs operate without any real authority over the systems that determine search performance. They publish recommendations that teams are free to ignore. A CoE without governance power becomes a spectator to the very failures it was meant to prevent. This weakness stayed hidden for years because traditional search was forgiving.

Inconsistencies could be corrected downstream. Signals recalibrated. Rankings recovered. But modern search, especially AI-driven discovery, is far less tolerant. Visibility is now shaped by structure, consistency, and machine clarity across the entire digital ecosystem.

Those outcomes cannot be achieved by advisory groups alone. They require operational governance embedded into how digital assets are designed, built, and deployed.

The future of SEO Centers of Excellence isn’t about sharing knowledge more efficiently. It’s about controlling the standards that shape digital assets before they exist.

What We Mean By A Modern SEO Center Of Excellence

A Center of Excellence, in its simplest form, is meant to centralize expertise and standardize how work is done across a complex organization. In theory, it exists to reduce duplication, improve quality, and create consistency at scale.

A modern SEO CoE functions as a governance body. Its responsibility is to define, enforce, and audit the standards that determine how digital assets are designed, built, and deployed across the enterprise.

This distinction matters more than most organizations realize. A CoE is not effective because teams agree with it or appreciate its expertise. It is effective because compliance with its standards is required.

When organizations confuse documentation with governance, they end up with extensive guidelines and minimal change. Standards exist, but adherence is optional. Exceptions multiply quietly. Leadership assumes SEO is being handled because materials have been produced.

Governance is what closes that gap. It transforms SEO from advice into infrastructure.

The Legacy CoE Problem

Traditional SEO Centers of Excellence were designed for a very different operating reality. SEO was treated as a marketing discipline, and visibility was shaped largely by page-level tactics that could be reviewed and corrected after launch. In that environment, guidance, training, and periodic audits were often sufficient to produce incremental gains.

As a result, most legacy CoEs were built around education rather than enforcement. They created playbooks, audited markets, trained local teams, and advised on fixes. What they did not have was authority over the systems that actually determined outcomes – development standards, templates, structured data policies, or product requirements. SEO success depended on persuasion rather than process.

Over time, the CoE became a library of best practices instead of an operating body. The problem was never a lack of knowledge. It was a lack of authority.

That distinction has been understood for decades. Nearly 20 years ago, Search Marketing, Inc., co-authored with Mike Moran, laid out the operating requirements for enterprise-scale search programs, including centralized standards, cross-functional integration, executive sponsorship, and accountability beyond marketing. The model assumed – correctly – that search performance at scale required structural ownership, not optional recommendations.

Where enterprises struggled was not in understanding that model, but in implementing it inside organizations unwilling to centralize control over digital standards. Many adopted the language of a Center of Excellence without adopting the authority required to make it effective.

Why Governance Is Now Mandatory

Search no longer evaluates isolated pages. It evaluates whether an organization presents itself as a coherent system.

As search engines and AI-driven discovery layers have evolved, they’ve shifted from asking “Which page is most relevant?” to “Which sources can be consistently understood and trusted?” That determination isn’t made at the page level. It emerges from how information is structured, reused, governed, and reinforced across an enterprise.

This is where most organizations begin to struggle. In the absence of centralized governance, decisions that affect search performance are made independently across markets, platforms, and teams. Templates evolve to meet local needs. Content adapts to brand or legal constraints. Structured data is implemented differently depending on tooling or vendor preference. None of these choices are irrational on their own. But taken together, they fragment the system’s signal.

Modern search systems respond poorly to fragmentation. When entity definitions vary, taxonomy drifts, or structural rules aren’t consistently enforced, machines can no longer form a stable representation of the brand. The result isn’t a gradual decline that can be corrected with optimization. It’s exclusion. AI-driven systems simply route around sources they cannot reliably interpret and default to alternatives that appear more coherent.

This is the inflection point that makes governance mandatory rather than optional. Best practices and guidelines assume voluntary compliance. They work only when teams are aligned, incentives are shared, and deviations are rare. Enterprise environments rarely meet those conditions. Without enforcement, standards erode quietly, exceptions multiply, and inconsistencies become embedded before anyone notices the impact externally.

Governance is what closes that gap. It ensures that the structural decisions shaping discoverability are made intentionally, enforced consistently, and reviewed before they harden into production. In modern SEO, that level of control is no longer a nice-to-have. It’s the prerequisite for visibility.

What A Real SEO CoE Must Control

A modern SEO Center of Excellence cannot remain advisory. To function as governance, it must have authority across a small number of clearly defined domains where search performance is created or destroyed at scale.

These are not tactical responsibilities. They are control points across five critical areas.

1. Platform & Template Standards

At scale, templates, not individual pages, determine crawlability, eligibility, and consistency. When SEO has no authority over templates, every market, product line, or release becomes a new risk surface, and structural mistakes are replicated faster than they can be corrected.

Governance here does not replace engineering judgment. It defines the non-negotiable requirements that engineering solutions must satisfy before they reach production. In practice, this means the CoE governs standards for:

  • Page templates and rendering rules.
  • Technical accessibility requirements.
  • Metadata and URL frameworks.
  • Structured data deployment patterns.

2. Entity & Structured Data Governance

In AI-driven search, entity clarity determines whether a brand is understood or ignored. Fragmented schema does not merely weaken signals; it fractures identity.

A governing CoE must own how the organization defines itself to machines, ensuring consistency across properties, platforms, and markets. This is not about marking up more fields. It is about protecting signal integrity.

That responsibility includes control over:

  • Entity definitions and relationships.
  • Schema standards and implementation rules.
  • Canonical brand representation.
  • Cross-property and cross-market consistency.
  • Alignment between legal constraints and brand expression.

Without centralized ownership, entity signals drift – and visibility follows.

3. Content Commissioning Standards

One of the most important shifts in modern SEO is where governance occurs in the content lifecycle. A governing CoE does not review content after publication. It defines what qualifies for creation in the first place. By setting structural and intent-based requirements upstream, it eliminates downstream debate and rework.

This means governing:

  • Content structure and format requirements.
  • Intent mapping and coverage frameworks.
  • Depth and completeness expectations.
  • Internal linking rules.
  • Topic and market rollout models.

When these standards are enforced before content is commissioned, SEO stops negotiating outcomes and starts shaping inputs.

4. Cross-Market Consistency

Global organizations need flexibility, but flexibility without oversight quickly turns into fragmentation. A governing CoE ensures that deviations from global standards are visible, intentional, and accountable. It does not eliminate local autonomy; it prevents unintentional conflict.

This requires authority over:

  • Global standard adoption.
  • Local deviation review and approval.
  • Hreflang governance.
  • Language-versus-market resolution.
  • Canonical ownership rules.

Without centralized oversight, local teams often send conflicting signals that quietly erode global visibility.

5. Measurement & Accountability Integration

Finally, governance fails if it cannot be measured and enforced. A real SEO CoE controls not just reporting, but accountability. If search performance represents systemic risk, it must be monitored and escalated like one.

That includes ownership of:

  • SEO performance standards.
  • Reporting frameworks.
  • Shared key performance indicators across departments.
  • Compliance monitoring.
  • Escalation authority and executive visibility.

SEO must be measured as infrastructure, not as a marketing channel. When failures carry organizational consequences, governance becomes real.

Control Vs. Influence: The Critical Difference

Most SEO Centers of Excellence operate through influence. They publish best practices, provide training, and offer guidance in the hope that teams will comply. When alignment exists and incentives are shared, this approach can work.

Enterprise environments rarely meet those conditions.

Influence depends on cooperation. It assumes teams will voluntarily prioritize SEO standards alongside their own objectives. When deadlines tighten or tradeoffs arise, influence is the first thing to give way. What remains are local decisions optimized for speed, risk avoidance, or revenue, not for long-term discoverability.

Governance operates differently.

A governing SEO CoE does not dictate how teams build solutions, but it does define the non-negotiable requirements those solutions must satisfy. It establishes mandatory operating standards for templates, structured data, entity representation, and market compliance, and it embeds those standards into workflows before assets are released.

This distinction is often misunderstood as “SEO trying to control everything.” In reality, governance is about oversight, not micromanagement. Engineering still engineers. Product still prioritizes. Markets still localize. But all of them operate within enforced constraints that protect search visibility as a shared enterprise asset.

That difference becomes visible in where authority actually exists. Advisory CoEs can recommend standards, but they cannot enforce template compliance, approve deviations, require pre-launch checks, or escalate violations. Governing CoEs can. Enterprise SEO only scales under that model. Not because teams agree with SEO, but because the organization has decided that discoverability is important enough to be protected by enforceable standards.

Organizational Impact Of A Governing CoE

When SEO governance is institutionalized, the effects extend well beyond search metrics.

Structural errors begin to decline, not because teams are fixing issues faster, but because many of those issues never make it to production. Standards enforced upstream prevent the same mistakes from being replicated across templates, markets, and releases. SEO shifts from remediation to prevention.

Visibility improves for the same reason. When signals are consistent and scalable, search systems can form a stable understanding of the brand. That consistency compounds over time, reinforcing eligibility rather than constantly resetting it.

Markets also begin to align more naturally. Governance doesn’t eliminate local flexibility, but it requires that deviations be explicit, reviewed, and justified. Instead of fragmentation happening quietly, exceptions become visible and accountable. Global coherence stops being accidental.

In AI-driven discovery, this coherence becomes even more valuable. Eligibility improves not through tactical optimization, but because entities, content, and relationships are structured in ways machines can reliably interpret. Brands stop competing on individual pages and start competing as systems.

Perhaps most noticeably, internal friction drops. When SEO standards are embedded into workflows, teams stop renegotiating fundamentals on every launch. The same conversations don’t have to happen repeatedly, and escalation becomes the exception rather than the norm.

Counterintuitively, this increases speed. When governance defines the rules of the road, execution accelerates because teams can focus on building within known constraints instead of debating them after the fact.

The Final Reality

Enterprise SEO rarely fails because teams aren’t trying hard enough. It fails because governance is missing.

Over the years, I’ve helped design and implement Search and Web Effectiveness Centers of Excellence inside large organizations. The ones that worked best all shared a common trait: They had real authority to guide and enforce compliance. Not heavy-handed control, but clear standards backed by the ability to say no when those standards were ignored.

What’s often misunderstood is that these governing CoEs were also the most collaborative. Because authority was clear, teams didn’t have to renegotiate fundamentals on every project. Everyone understood the shared goals and the mutual benefits of operating as a coordinated system rather than as isolated functions. Governance removed friction instead of creating it.

Those CoEs succeeded by treating search visibility as a team sport. Cross-department initiatives weren’t exceptions; they were the operating norm. Development, content, product, and marketing aligned around enterprise objectives because the value of doing so was explicit and reinforced through process, not persuasion.

By contrast, CoEs built solely to advise rarely achieved that alignment. Without enforcement, standards became optional, exceptions multiplied, and collaboration depended on goodwill rather than structure.

Modern search leaves little room for that model. Organizations that want to maintain control over how they are discovered, understood, and recommended must move beyond documentation and consensus-building alone. Governance is what makes collaboration durable. It turns good intentions into repeatable outcomes.

In an AI-driven search environment, that shift is no longer aspirational. It is the difference between being represented accurately and being replaced quietly by sources that are.

More Resources:


Featured Image: Masha_art/Shutterstock

https://www.searchenginejournal.com/the-modern-seo-center-of-excellence-governance-not-guidelines/566097/


Why Your Search Data Doesn’t Agree (And What To Do About It) via @sejournal, @coreydmorris

The quarterly business review is upon us. We pull reports from Google Analytics 4, Search Console, Google Ads, and customer relationship management, and we find that none of them match. In fact, despite being connected to the same campaign and focus, they are quite different.

This is work done, data collected, and reported back to us from multiple platforms that are tracking for the same campaign, same time period, and yet giving us different numbers.

This isn’t a new issue, but in my experience, it’s becoming a bigger issue.

Privacy changes, continued attribution modeling challenges, platform silos, and even ways that they allow us to customize or configure for conversions contribute to the problem. And I’ve made it this far in writing this article before mentioning AI and LLM traffic that adds another layer of ambiguity.

The issue isn’t simply bad data. It is the fact that search data is coming from different systems that have different purposes. Those different purposes result in different tracking and collection methods, creating a maze or puzzle for us to try to piece together, often with pieces that don’t fit.

With this problem comes a business risk. Conflicting data can slow decision-making or create distractions from the most important decisions at hand, sending teams down detailed paths (and distractions) trying to make the data work and questioning it.

Sometimes, when metrics don’t align, this can signal a deeper issue in an over-reliance on channel-specific key performance indicators, a lack of shared definitions of success by stakeholders, and can create tension.

When SEO says traffic is up, paid search shows conversions are down, and the CRM pipeline data shows things are flat, we can get off into the territory of trying to figure out which one is right and where the gap is. Trying to “fix” the numbers until they match, though, is often the wrong reaction, as our approach should be rooted in understanding what each set of data is actually telling us to guide our strategies and decisions.

There are many factors that we can incorporate into our understanding, working with conflicting data, and even the acceptance of a problem that we can’t change, but must navigate.

Understand And Accept That Platforms Measure Different Things

Different platforms measure different things. Yes, they might sound the same, or be named the same thing in a report or as a KPI, but in many cases, they are tracked and measured in a fundamentally different way.

For example:

  • GA4: Measures sessions, events, and modeled behavior, with own tag and collection method.
  • Google Ads: Measures ad interactions and own platform measured and attributed conversions, with own tag and collection method.
  • Search Console: Provides impressions, click data, and other anonymous and aggregated data, not directly tracked or sourced, the way that data is collected by GA4.
  • CRM: Typically tracks actual visitors who have been identified and through opportunities, leads, and to/through revenue.

The differences in metrics, as well as collection methods, inherently will always result in different numbers and data points, which may or may not seem close to telling the same story.

Identify Common Causes Of Data Discrepancies

Beyond the basic metrics and KPIs, we want to go deeper and map out how performance looks overall. That means we have to get into attribution models. Those can be as simple as first touch, last click, or some other data-driven formula.

However, there might be obvious tracking gaps where forms, calls, or offline conversions occur that our systems can’t pick up. Plus, privacy changes related to consent mode, cookies that aren’t able to be leveraged, time lags (does anyone else have 50 tabs open for 100 days at a time like me?), and even cross-device search behavior.

Again, many of these are not new, but they seem to be amplified, and we can forget about them when looking at data without challenging assumptions or seeking what might be a gap or not collected.

My team has recently been in a fight against bots and spam, and we have been testing and navigating site-wide validation tools, which can create gaps in capturing referral headers or strip UTM parameters as well if not implemented properly.

Define Sources Of Truth And Hierarchy

With all the tech, tools, collection methods, and overall sources, we can have information overload and a whole host of conflicting sources that we’re working to understand and reconcile differences within.

I contend that not all data is equal when it comes to answering performance questions.

Example data that we’re seeking and key sources:

  • Revenue & Pipeline: CRM.
  • Leads: CRM, and/or trusted, validated platform conversion metrics.
  • On-Site Behavior: GA4.
  • Search Visibility: Search Console.
  • Ad Performance: Google Ads, other native ad platforms.

A shift in thinking might be that we have to stop trying to make one platform answer every question. The perfectionist in me struggles with having to say that, but it is the reality of the data source and attribution world we live in.

Align Metrics To Business Outcomes

I know that many marketing leaders, teams, and agencies inherit metrics and historical performance data. It isn’t always easy to reconfigure KPIs, make quick changes, or to be able to start tracking and reporting on things differently.

Marketing may be accountable for channels and platforms, while sales (and/or other functions) are looking at things further downstream, like leads, pipeline, and ultimately revenue.

When it comes to search marketing, and where we’re going with being found as well in LLMs, centering more on the connection between search marketing and business outcomes (not channels) is important. This isn’t a new concept, but one that warrants focus and investment as it won’t get less important over the coming months and years. This is a priority area to put marketing leadership focus.

Create Consistent Definitions Across Roles & Teams

With different definitions, collection methods, platforms, and data sources different roles and teams look at, by default, we likely are speaking some of the same language, but with very different definitions.

It is hard enough to manage the data; it can be impossible to move forward when it comes to how data is used and interpreted for different purposes.

What is a “conversion”? What counts as a “qualified lead”? How is “revenue” tracked? What is the source of truth for how a lead “source” is defined?

Definitions are often a bigger driver of misalignment than the data itself.

Use Trends When Exact Matches Are Not Realistic

Assuming you have accepted the truth that we can’t make all the data sources perfectly match, we can still find meaning in the data we’re looking at.

That comes in what we see in terms of trends. Are things trending across sources and data points in the same direction? Are there spikes or drops that we see consistently across platforms and sources?

Comparing and contrasting anomalies, finding trends, and understanding them can help us identify where data doesn’t match and where the level of precision doesn’t have to be perfect as we look for consistency, direction, and the outcome of what happened.

Close The Gap Between Marketing And CRM

I still sometimes get looked at a little funny when working with the CRM administrator or decision maker who sits outside of marketing, when asking about non-digital marketing leads, data, and offline sources.

I advocate that, even if we’re just focused on digital or search marketing, we push for offline conversion imports, CRM feedback that is specific to the campaigns and channels/platforms that we’re focused on, and respective lead quality scoring.

We need to understand the business side of the data connected to our efforts in digital marketing and search. The better integrated the data, the more feedback we get, and the more collaboration of sources, the more impactful our efforts can be.

Educate Stakeholders On Why Data Won’t Match

In working with other C-suite leaders, executives, or stakeholders, you might find that they are used to a world of accounting, financial metrics, and more consistent data and absolutes. The fact that marketing data sources don’t match could be a big concern for them.

Keeping that in mind, it will serve you well to educate stakeholders and to prioritize their focus on what matters, the things we’ve unpacked already in this article.

It can derail a meeting fast when the numbers don’t match, don’t make sense, or create confusion. When the numbers can’t help connect the dots, they often create new questions, erode confidence, and take the conversation away from the overall business alignment and impact of the marketing efforts.

Develop The Performance Narrative, Not Just Dashboards

We naturally live in a world of dashboards with performance marketing, digital marketing, and search. We have the ability to track so much and have it all at our fingertips, sourcing from all of the various places we track and measure the impact of our work.

While it may be clear to you, looking at a complex dashboard, what the takeaways are, it will be confusing, distracting, and possibly misleading for everyone else.

Reporting shouldn’t just show numbers as it should explain what is happening, why, and what to do next. In your role in marketing leadership and subject matter expertise, your ability to shift from being a reporter of data to an interpreter of broader performance connected to strategy and business outcomes is a noble calling.

In Summary

Data conflicts and disagreements aren’t a flaw or evidence of an error (although you need to regularly audit to make sure you trust the collection and don’t have gaps). It is a reality of digital and search marketing.

When our varying roles, teams, and stakeholders understand this, we can shift our focus to the importance of mapping to business outcomes and leveraging our data for decisions, versus being distracted by the nuances of things that we can’t ultimately exact match and reconcile.

Our goal isn’t to make the numbers match. It is to be able to make informed and confident decisions to drive business outcomes and success.

More Resources:


Featured Image: Accogliente Design/Shutterstock

https://www.searchenginejournal.com/why-your-search-data-doesnt-agree-and-what-to-do-about-it/570180/


Google Just Made It Easy For SEOs To Kick Out Spammy Sites via @sejournal, @martinibuster

Google updated their report-a-spam documentation to reflect that the feature may now be used to initiate manual actions against websites that are found to be spamming. This is a change in policy that gives SEOs the opportunity to now have their spam reports potentially go into the queue for a manual action.

Change In Spam Report Policy

The previous spam reporting documentation previously said that Google would not use the spam reports for taking actions against websites.

This wording was mostly removed:

“While Google does not use these reports to take direct action against violations, these reports still play a significant role in helping us understand how to improve our spam detection systems that protect our search results.”

That part is narrowed to emphasize that the submitted spam reports help improve their spam detection systems:

“These reports help us understand how to improve the spam detection systems that protect our search results.”

More Aggressive Approach To Spam

Google also added new wording to make it clear that Google may use the spam reports to take manual actions against websites. Google used to refer to manual actions in terms related to penalization but it may be that the word “penalization” carries connotations of punishment which isn’t what Google is doing when they remove a site from the index. It’s not a punishment, it’s just a removal from the index.

Google’s new wording makes it clear that taking manual action against reported sites are now an option:

“Google may use your report to take manual action against violations. If we issue a manual action, we send whatever you write in the submission report verbatim to the site owner to help them understand the context of the manual action. We don’t include any other identifying information when we notify the site owner; as long as you avoid including personal information in the open text field, the report remains anonymous.”

Everything else about the page is the same, including the button for filing a spam report.

Screenshot: Spam Report Button

Clicking the “Report spam” button leads to a form that now can lead to a manual action:

Screenshot: Spam Report Form

Is This Good News For SEOs?

Site owners and SEOs who are sick of seeing spammy sites dominating the search results may want to check out the new page and start reporting actual spammy websites. Nobody really enjoys spam and now there’s something users can do about it.

Featured Image by Shutterstock/NLshop

https://www.searchenginejournal.com/google-just-made-it-easy-for-seos-to-kick-out-spammy-sites/572118/


Google Search Console Glitch Gives SEOs A Scare via @sejournal, @martinibuster

Google Search Console erroneously sent out emails to site owners advising them that Google has just started to record impressions beginning on April 12th. The implication of the message is that Search Console has not previously been collecting those impressions, which is incorrect.

Search Console Impressions

The Search Console impressions report shows how often a site appeared in Google’s search results, regardless of whether or not users clicked. The impressions report by itself is not the metric to pay attention to, but rather the meaningful metrics are t he associated keywords and their positions in the search results. This enables an SEO to identify high value keyword performance and to enable better decisions on addressing performance shortcomings.

The report breaks queries down by:

1. Queries (What people searched)

2. Pages (Which URLs showed up)

3. Countries (Where searchers were located geographically)

4. Devices (Desktop, Mobile, and Tablet)

5. Search Appearance (shows if the impressions are from Rich Results, Videos, Web Light, and Merchant Listings)

Actual Search Console Reporting Errors

Google sent the following message to Search Console users:

“Google systems confirm that on April 12, 2026 we started collecting Google Search impressions for your website in Search Console. This means that pages from your website are now appearing in Google search results for some queries. Here’s how you can monitor your site’s Search performance using Search Console.”

This is an interesting message because it comes after it was disclosed that Google had been incorrectly reporting impressions since May 13, 2025. A note in a Google Support page from April 3 explained:
https://support.google.com/webmasters/answer/6211453#performance-reports-search-results-discover-google-news&zippy=%2Cperformance-reports-search-results-discover-google-news

“A logging error is preventing Search Console from accurately reporting impressions from May 13, 2025 onward. This issue will be resolved over the next few weeks; as a result, you may notice a decrease in impressions in the Search Console Performance report. Clicks and other metrics were not affected by the error, and this issue affected data logging only.”

Is today’s erroneous note related to any fixes made to the impressions report? Google’s John Mueller described it as just a glitch.

Mueller posted remarks on Bluesky about the message in response to a query about it:

“Sorry – this is just a normal glitch, unrelated to anything else.”

It’s a curious because it appears that the impression reporting errors and this erroneous messaging may be related. Are they related or is it just a glitch?

https://www.searchenginejournal.com/new-google-search-console-message-glitch-gives-seos-a-scare/572072/


Google Lists 9 Scenarios That Explain How It Picks Canonical URLs via @sejournal, @martinibuster

Google’s John Mueller answered a question on Reddit about why Google picks one web page over another when multiple pages have duplicate content, also explaining why Google sometimes appears to pick the wrong URL as the canonical.

Canonical URLs

The word canonical was previously mostly used in the religious sense to describe what writings or beliefs were recognized to be authoritative. In the SEO community, the word is used to refer to which URL is the true web page when multiple web pages share the same or similar content.

Google enables site owners and SEOs to provide a hint of which URL is the canonical with the use of an HTML attribute called rel=canonical. SEOs often refer to rel=canonical as an HTML element, but it’s not. Rel=canonical is an attribute of the <link> element. An HTML element is a building block for a web page. An attribute is markup that modifies the element.

Why Google Picks One URL Over Another

A person on Reddit asked Mueller to provide a deeper dive on the reasons why Google picks one URL over another.

They asked:

“Hey John, can I please ask you to go a little deeper on this? Let’s say I want to understand why Google thinks two pages are duplicate and it chooses one over the other and the reason is not really in plain sight. What can one do to better understand why a page is chosen over another if they cover different topics? Like, IDK, red panda and “regular” panda 🐼. TY!!”

Mueller answered with about nine different reasons why Google chooses one page over another, including the technical reasons why Google appears to get it wrong but in reality it’s someetimes due to something that the site owner over SEO overlooked.

Here are the nine reasons he cited for canonical choices:

  1. Exact duplicate content
    The pages are fully identical, leaving no meaningful signal to distinguish one URL from another.
  2. Substantial duplication in main content
    A large portion of the primary content overlaps across pages, such as the same article appearing in multiple places.
  3. Too little unique main content relative to template content
    The page’s unique content is minimal, so repeated elements like navigation, menus, or layout dominate and make pages appear effectively the same.
  4. URL parameter patterns inferred as duplicates
    When multiple parameterized URLs are known to return the same content, Google may generalize that pattern and treat similar parameter variations as duplicates.
  5. Mobile version used for comparison
    Google may evaluate the mobile version instead of the desktop version, which can lead to duplication assessments that differ from what is manually checked.
  6. Googlebot-visible version used for evaluation
    Canonical decisions are based on what Googlebot actually receives, not necessarily what users see.
  7. Serving Googlebot alternate or non-content pages
    If Googlebot is shown bot challenges, pseudo-error pages, or other generic responses, those may match previously seen content and be treated as duplicates.
  8. Failure to render JavaScript content
    When Google cannot render the page, it may rely on the base HTML shell, which can be identical across pages and trigger duplication.
  9. Ambiguity or misclassification in the system
    In some cases, a URL may be treated as duplicate simply because it appears “misplaced” or due to limitations in how the system interprets similarity.

Here’s Mueller’s complete answer:

“There is no tool that tells you why something was considered duplicate – over the years people often get a feel for it, but it’s not always obvious. Matt’s video “How does Google handle duplicate content?” is a good starter, even now.

Some of the reasons why things are considered duplicate are (these have all been mentioned in various places – duplicate content about duplicate content if you will :-)): exact duplicate (everything is duplicate), partial match (a large part is duplicate, for example, when you have the same post on two blogs; sometimes there’s also just not a lot of content to go on, for example if you have a giant menu and a tiny blog post), or – this is harder – when the URL looks like it would be duplicate based on the duplicates found elsewhere on the site (for example, if /page?tmp=1234 and /page?tmp=3458 are the same, probably /page?tmp=9339 is too — this can be tricky & end up wrong with multiple parameters, is /page?tmp=1234&city=detroit the same too? how about /page?tmp=2123&city=chicago ?).

Two reasons I’ve seen people get thrown off are: we use the mobile version (people generally check on desktop), and we use the version Googlebot sees (and if you show Googlebot a bot-challenge or some other pseudo-error-page, chances are we’ve seen that before and might consider it a duplicate). Also, we use the rendered version – but this means we need to be able to render your page if it’s using a JS framework for the content (if we can’t render it, we might take the bootstrap HTML page and, chances are it’ll be duplicate).

It happens that these systems aren’t perfect in picking duplicate content, sometimes it’s also just that the alternative URL feels obviously misplaced. Sometimes that settles down over time (as our systems recognize that things are really different), sometimes it doesn’t.

If it’s similar content then users can still find their way to it, so it’s generally not that terrible. It’s pretty rare that we end up escalating a wrong duplicate – over the years the teams have done a fantastic job with these systems; most of the weird ones are unproblematic, often it’s just some weird error page that’s hard to spot.”

Takeaway

Mueller offered a deep dive into the reasons why Google chooses canonicals. He described the process of choosing canonicals as like a fuzzy sorting system built from overlapping signals, with Google comparing content, URL patterns, rendered output, and crawler-visible versions, while borderline classifications (“weird ones”) are given a pass because they don’t pose a problem.

Featured Image by Shutterstock/Garun .Prdt

https://www.searchenginejournal.com/how-google-picks-canonical-urls/571914/


New Google Spam Policy Targets Back Button Hijacking via @sejournal, @MattGSouthern

Google added a new section to its spam policies designating “back button hijacking” as an explicit violation under the malicious practices category. Enforcement begins on June 15, giving websites two months to make changes.

Google published a blog post explaining the policy. It also updated the spam policies documentation to list back-button hijacking alongside malware and unwanted software as a malicious practice.

What Is Back Button Hijacking

Back button hijacking occurs when a site interferes with browser navigation and prevents users from returning to the previous page. Google’s blog post describes several ways this can happen.

Users might be sent to pages they never visited. They might see unsolicited recommendations or ads. Or they might be unable to navigate back at all.

Google wrote in the blog post:

“When a user clicks the ‘back’ button in the browser, they have a clear expectation: they want to return to the previous page. Back button hijacking breaks this fundamental expectation.”

Why Google Is Acting Now

Google said it’s seen an increase in this behavior across the web. The blog post noted that Google has previously warned against inserting deceptive pages into browser history, referencing a 2013 post on the topic, and said the behavior “has always been against” Google Search Essentials.

Google wrote:

“People report feeling manipulated and eventually less willing to visit unfamiliar sites.”

What Enforcement Looks Like

Sites involved in back button hijacking risk manual spam penalties or automated demotions, both of which can lower their visibility in Google Search results.

Google is giving a two-month grace period before enforcement starts on June 15. This follows a similar pattern to the March 2024 spam policy expansion, which also gave sites two months to comply with the new site reputation abuse policy.

Third-Party Code As A Source

Google’s blog post acknowledges that some back-button hijacking may not originate from the site owner’s code.

Google wrote:

“Some instances of back button hijacking may originate from the site’s included libraries or advertising platform.”

Google’s wording indicates sites can be affected even if issues come from third-party libraries or ad platforms, placing responsibility on websites to review what runs on their pages.

How This Fits Into Google’s Spam Policy Framework

The addition falls under Google’s category of malicious practices. That section discusses behaviors causing a gap between user expectations and experiences, including malware distribution and unwanted software installation. Google expanded the existing spam policy category instead of creating a new one.

The March 2026 spam update completed its rollout less than three weeks ago. That update enforced existing policies without adding new ones. Today’s announcement adds new policy language ahead of the June 15 enforcement date.

Why This Matters

Sites using advertising scripts, content recommendation widgets, or third-party engagement tools should audit those integrations before June 15. Any script that manipulates browser history or prevents normal back-button navigation is now a potential spam violation.

The two-month window is the compliance period. After June 15, Google can take manual or automated action.

Sites that receive a manual action can submit a reconsideration request through Search Console after fixing the issue.

Looking Ahead

Google hasn’t indicated whether enforcement will come through a dedicated spam update or through ongoing SpamBrain and manual review.

https://www.searchenginejournal.com/new-google-spam-policy-targets-back-button-hijacking/571859/


The Dangerous Seduction Of Click-Chasing

It works, until it doesn’t.

The Chase

Imagine you’re a news publisher. Your journalism is good, you write original stories, and your website is relatively popular within your editorial niche.

Revenue is earned primarily via advertising. Google search is your biggest source of visitors.

Management demands growth, and elevates traffic to the throne of all key performance indicators. Engagement, loyalty, subscriptions – these are now secondary objectives. Getting the click, that is the driving purpose.

You look at your channels to determine where growth is most likely to come from. Search seems the most viable channel. So, you make SEO a key focus area.

As part of your SEO efforts, you come across specific tactics that cause your stories to generate more clicks. These tactics are very effective. Applying them to your stories results in significantly more traffic than before.

You’ve caught the scent. The chase for clicks is on.

These tactics demand that your stories focus on clicks above all. Within the context of these SEO-first tactics, every story is a traffic opportunity.

At first, you manage to apply these tactics within the framework of your existing journalism. Your stories are still good and unique, and you apply SEO as best you can to ensure each gets the best chance of generating traffic. It works, and your traffic grows.

But the pressures of management demand more. More growth. More revenue. More ad impressions. More traffic.

The newsroom submits. Stories are commissioned only if they have sufficient traffic potential. Journalists learn to just write stories that generate clicks. Headlines are crafted to maximize click-through rates, not to inform readers. You write multiple stories about the exact same news, each with a slightly different angle. Articles bury the lede.

Everything is subject to the chase.

Your scope expands. You don’t just write stories within your established specialism – you branch out. Different topics. New sections. Product reviews and recommendations. Listicles.

Everything is fair game, as long as it generates clicks.

And it works. Oh boy, does it work.

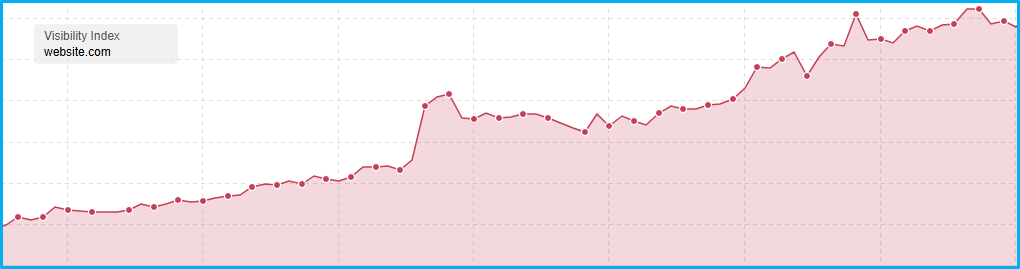
Image Credit: Barry Adams

The flywheel gathers momentum. You learn exactly what people click on, how to craft the perfect headline, select the ideal image, find the precise angle that will make people stop scrolling and tap on your article.

Traffic keeps growing.

But, somehow, you don’t feel entirely at ease. Because you know that, when you look at your content objectively, something has been lost. Your site used to be about journalism, about informing readers, improving knowledge and awareness, and enabling policies and decisions. It used to be good.

Now, none of that really matters anymore. Your site is about clicks. Everything else is secondary.

But management is happy. Revenue is up. Profits surge. So it’s alright, isn’t it?

Isn’t it?

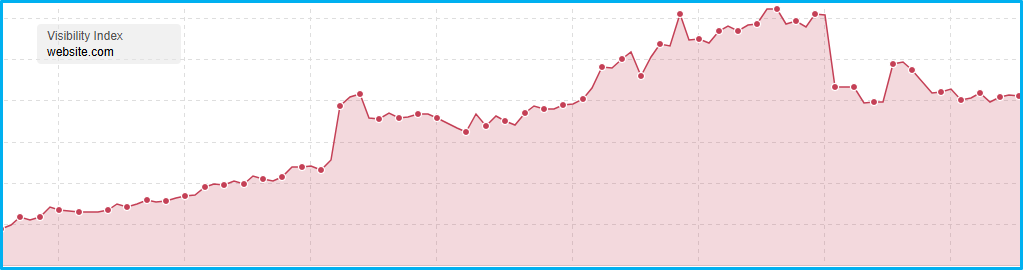
Image Credit: Barry Adams

Google rolls out a core algorithm update. You lose 20% of your search traffic overnight. It’s a shot across the bow. A warning. But you ignore it. You focus on the chase even more. Tighter content focus. More variations of the same stories. Better SEO.

Traffic stabilizes. No more growth, but you’re chugging along nicely. You maybe change a few things, try to get back onto a growth curve. Nothing works, but you’re not losing either. Things look stable. You can live with this.

Then the next Google core update hits. You lose 50% of your current search traffic. It’s code red in the newsroom. All hands on deck.

How do we recover? How do we get this traffic back? It’s our traffic, Google owes us!

You do what you’ve gotten very good at. You SEO the hell out of your site. Everything is optimized and maximized. Your technical SEO goes from “that will do” to a state of such perfection it could make a web nerd cry. Your content output becomes even more focused on areas with the biggest traffic potential.

In the chase for revenue, you try alternative monetization. Affiliate content. Gambling promos. Advertorials. More listicles. More product recommendations. More of everything.

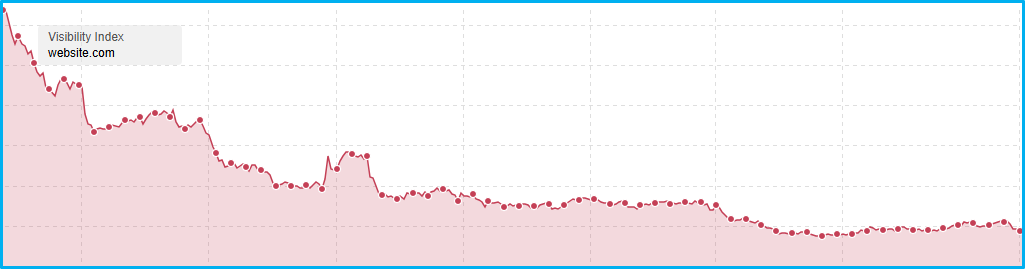
Then the next update arrives. You lose again.

And the next one.

And the next one.

You lose, almost every single time.

Image Credit: Barry Adams

It worked. Until it didn’t.

And now your site is on Google’s shitlist. Your relentless focus on growth at the expense of quality has accumulated so many negative signals that Google will not allow you to return to your previous heights.

You know none of what you try will work. Those traffic graphs won’t go back up. Every Google core update causes a new surge of existential dread: How much will we lose this time?

And yet, you still chase. You’ve long since lost the scent. But the chase still rules. Because you know that, to stop the chase, something needs to change. Something big and profound. And making that change will be painful. Extremely painful.

But do you have a choice?

Hindsight

I wish this scenario was unique, a singular publisher making the mistake of focusing on traffic at the expense of quality. But it’s a tragically common theme, played out in digital newsrooms hundreds of times over the last 10 years.

In every instance, at some point, the seductive appeal of traffic began to outweigh the journalistic principles of the organization. Compromises were made so growth could be achieved.

And because these compromises had the intended result – at first – there was nothing to caution the publisher from traveling further down this path.

Well, nothing besides Google shouting at every opportunity that you should focus on quality, not clicks.

Besides every SEO professional that has ever dealt with a bad algorithm update saying you should focus on quality, not clicks.

Besides your best journalists abandoning ship in favor of a quality-focused outlet or their own Substack.

Besides your own loyal readers abandoning your site because you stopped focusing on quality and went after clicks.

The writing has been on the wall, in huge capital letters, for the better part of a decade. Arguably, since 2018, when Google began rolling out algorithm updates to penalize low-effort content. If you’d been paying attention, none of this would have been a surprise.

Hey, maybe you did see it coming. But you weren’t able to make the required changes, because the clicks were still there. You were never going to deliberately abandon growth for some vague promise of sustainable traffic and audience loyalty.

If only you’d known that, once the Google hammer came down, the damage would be permanent. Maybe you wouldn’t have started the chase in the first place.

If only you’d known.

Recovery

When a site is so heavily affected by consecutive Google core updates, is there any hope of recovery? Can a website climb its way back to those vaulted traffic heights?

We need to be realistic and accept that those halcyon days of near-limitless traffic growth are not coming back. The ecosystem has changed. Growth is harder to achieve, and online news is working under a lower ceiling than ever before.

But recovery is possible, to an extent. You will never achieve the same traffic peaks as in your prime days, but you can claw back a significant chunk. Providing you are willing to do what it takes.

The recipe is simple, on paper: Everything you do should be in service of the reader.

Every story needs to be crafted to deliver maximum value for your readers. Every design element on your site needs to be optimized for the best user experience. Every headline must be informative first and foremost. Every article must deliver on its headline’s promise in spades. Every piece of content should serve to inform, educate, and delight your audience.

In short, your entire output should revolve around audience loyalty.

Not growth. Not traffic.

Loyalty.

Build a news platform so good that your readers don’t ever think about going anywhere else.

Of course, you still need traffic, but this must be a secondary concern. Start with your audience, and then apply layers on top of your stories to aid their traffic potential.

Your output should be focused on original journalism – not rehashing the same stories that others are reporting. If all you do is take someone else’s story and write different angles on it, you’re not doing journalism.

Provide breaking news, expert commentary, detailed analysis, and a deep focus on your editorial specialties.

And accept that your audience isn’t a singular entity, but consumes news on multiple platforms and in multiple formats. Video, podcasts, newsletters, social media, you name it. Fire on all channels, as best you can.

Sounds simple. But very few publishers I’ve spoken with have the internal fortitude for such drastic cultural changes in their online newsroom. Most of the publishers I consult with that were affected by core updates just want a list of quick wins, some easy fixes they can implement, and get their traffic back.

They want busy-work. They’re not interested in meaningful change. Because meaningful change is hard, and painful.

But also absolutely necessary.

That’s it for another edition. As always, thanks for reading and subscribing, and I’ll see you at the next one!

More Resources:


This post was originally published on SEO For Google News.


Featured Image: Roman Samborskyi/Shutterstock

https://www.searchenginejournal.com/the-dangerous-seduction-of-click-chasing/571533/


Google’s Task-Based Agentic Search Is Disrupting SEO Today, Not Tomorrow via @sejournal, @martinibuster

Google’s Sundar Pichai recently said that the future of Search is agentic, but what does that really mean? A recent tweet from Google’s search product lead shows what the new kind of task-based search looks like. It’s increasingly apparent that the internet is transitioning to a model where every person has their own agent running tasks on their behalf, experiencing an increasingly personal internet.

Search Is Becoming Task-Oriented

The internet, with search as the gateway to it, is a model where websites are indexed, ranked, and served to users who basically use the exact same queries to retrieve virtually the same sets of web pages. AI is starting to break that model because users are transitioning to researching topics, where a link to a website does not provide the clear answers users are gradually becoming conditioned to ask for. The internet was built to serve websites that users could go to and read stuff and to connect with others via social media.

What’s changing is that now people can use that same search box to do things, exactly as Pichai described. For example, Google recently announced the worldwide rollout of the ability to describe the needs for a restaurant reservation, and AI agents go out and fetch the information, including booking information.

Google’s Search Product Lead Rose Yao tweeted:

“Date nights and big group dinners just got a lot easier.

We’re thrilled to expand agentic restaurant booking in Search globally, including the UK and India!

Tell AI Mode your group size, time, and vibe—it scans multiple platforms simultaneously to find real-time, bookable spots.

No more app-switching. No more hassle. Just great food.”

That’s not search, that’s task completion. What was not stated is that restaurants will need to be able to interact with these agents, to provide information like available reservation slots, menu choices that evening, and at some point those websites will need to be able to book a reservation with the AI agent. This is not something that’s coming in the near future, it’s here right now.

That is exactly what Pichai was talking about when he recently described the future of search:

“I feel like in search, with every shift, you’re able to do more with it.

…If I fast forward, a lot of what are just information seeking queries will be agentic search. You will be completing tasks, you have many threads running.”

When asked if search will still be around in ten years, Pichai answered:

“Search would be an agent manager, right, in which you’re doing a lot of things.

…And I can see search doing versions of those things, and you’re getting a bunch of stuff done.”

Everyone Has Their Own Personal Internet

Cloudflare recently published an article that says the internet was the first way for humans to interact with online content, and that cloud infrastructure was the second adaptation that emerged to serve the needs of mobile devices. The next adaptation is wild and has implications for SEO because it introduces a hyper-personalized version of the web that impacts local SEO, shopping, and information retrieval.

AI agents are currently forced to use an internet infrastructure that’s built to serve humans. That’s the part that Cloudflare says is changing. But the more profound insight is that the old way, where millions of people asked the same question and got the same indexed answer, is going away. What’s replacing it is a hyper-personal experience of the web, where every person can run their own agent.

Cloudflare explains:

“Unlike every application that came before them, agents are one-to-one. Each agent is a unique instance. Serving one user, running one task. Where a traditional application follows the same execution path regardless of who’s using it, an agent requires its own execution environment: one where the LLM dictates the code path, calls tools dynamically, adjusts its approach, and persists until the task is done.

Think of it as the difference between a restaurant and a personal chef. A restaurant has a menu — a fixed set of options — and a kitchen optimized to churn them out at volume. That’s most applications today. An agent is more like a personal chef who asks: what do you want to eat? They might need entirely different ingredients, utensils, or techniques each time. You can’t run a personal-chef service out of the same kitchen setup you’d use for a restaurant.”

Cloudflare’s angle is that they are providing the infrastructure to support the needs of billions of agents representing billions of humans. But that is not the part that concerns SEO. The part that concerns digital marketing is that the moment when search transforms into an “agent manager” is here, right now.

WordPress 7.0

Content management systems are rapidly adapting to this change. It’s very difficult to overstate the importance of the soon-to-be-released WordPress 7.0, as it is jam-packed with the capability to connect to AI systems that will enable the internet transition from a human-centered web to an increasingly agentic-centered web.

The current internet is built for human interaction. Agents are operating within that structure, but that’s going to change very fast. The search marketing community really needs to wrap its collective mind around this change and to really understand how content management systems fit into that picture.

What Sources Do The Agents Trust?

Search marketing professional Mike Stewart recently posted on Facebook about this change, reflecting on what it means to him.

He wrote:

“I let Claude take over my computer.
Not metaphorically — it moved my mouse, opened apps, and completed tasks on its own.
That’s when something clicked…
This isn’t just AI assisting anymore.
This is AI operating on your behalf.

Google’s CEO is already talking about “agentic search” — where AI doesn’t just return results, it manages the process.
So the real questions become:
👉 Who controls the journey?
👉 What sources does the agent trust?
👉 Where does your business show up in that decision layer?
Because you don’t get “agentic search” without the ecosystem feeding it — websites, content, businesses.

That part isn’t going away. But it is being abstracted.”

Task-Based Agentic Search

I think the part that I guess we need to wrap our heads around is that humans are still making the decision to click the “make the reservation” button, and at some point, at least at the B2B layer, making purchases will increasingly become automated.

I still have my doubts about the complete automation of shopping. It feels unnatural, but it’s easy to see that the day may rapidly be approaching when, instead of writing a shopping list, a person will just tell an AI agent to talk to the local grocery store AI agent to identify which one has the items in stock at the best price, dump it into a shopping cart, and show it to the human, who then approves it.

The big takeaway is that the web may be transitioning to the “everyone has a personal chef” model, and that’s a potentially scary level of personalization. How does an SEO optimize for that? I think that’s where WordPress 7.0 comes in, as well as any other content management systems that are agentic-web ready.

Featured Image by Shutterstock/Stock-Asso

https://www.searchenginejournal.com/googles-task-based-search/571800/


How AI Chooses Which Brands To Recommend: From Relational Knowledge To Topical Presence via @sejournal, @Dixon_Jones

Ask ChatGPT or Claude to recommend a product in your market. If your brand does not appear, you have a problem that no amount of keyword optimization will fix.

Most SEO professionals, when faced with this, immediately think about content. More pages, more keywords, better on-page signals. But the reason your brand is absent from an AI recommendation may have nothing to do with pages or keywords. It has to do with something called relational knowledge, and a 2019 research paper that most marketers have never heard of.

The Paper Most Marketers Missed

In September 2019, Fabio Petroni and colleagues at Facebook AI Research and University College London published “Language Models as Knowledge Bases?” at EMNLP, one of the top conferences in natural language processing.

Their question was straightforward: Does a pretrained language model like BERT actually store factual knowledge in its weights? Not linguistic patterns or grammar rules, but facts about the world. Things like “Dante was born in Florence” or “iPod Touch is produced by Apple.”

To test this, they built a probe called LAMA (LAnguage Model Analysis). They took known facts, thousands of them drawn from Wikidata, ConceptNet, and SQuAD, and converted each one into a fill-in-the-blank statement. “Dante was born in ___.” Then they asked BERT to predict the missing word.

BERT, without any fine-tuning, recalled factual knowledge at a level competitive with a purpose-built knowledge base. That knowledge base had been constructed using a supervised relation extraction system with an oracle-based entity linker, meaning it had direct access to the sentences containing the answers. A language model that had simply read a lot of text performed nearly as well.

The model was not searching for answers. It had absorbed associations between entities and concepts during training, and those associations were retrievable. BERT had built an internal map of how things in the world relate to each other.

After this, the research community started taking seriously the idea that language models work as knowledge stores, not merely as pattern-matching engines.

What “Relational Knowledge” Means

Petroni tested what he and others called relational knowledge: facts expressed as a triple of subject, relation, and object. For example: (Dante, [born-in], Florence). (Kenya, [diplomatic-relations-with], Uganda). (iPod Touch, [produced-by], Apple).

What makes this interesting for brand visibility (and AIO) is that Petroni’s team discovered that the model’s ability to recall a fact depends heavily on the structural type of the relationship. They identified three types, and the accuracy differences between them were large.

1-To-1 Relations: One Subject, One Object

These are unambiguous facts. “The capital of Japan is ___.” There is one answer: Tokyo. Every time the model encountered Japan and capital in the training data, the same object appeared. The association built up cleanly over repeated exposure.

BERT got these right 74.5% of the time, which is high for a model that was never explicitly trained to answer factual questions.

N-To-1 Relations: Many Subjects, One Object

Here, many different subjects share the same object. “The official language of Mauritius is ___.” The answer is English, but English is also the answer for dozens of other countries. The model has seen the pattern (country → official language → English) many times, so it knows the shape of the answer well. But it sometimes defaults to the most statistically common object rather than the correct one for that specific subject.

Accuracy dropped to around 34%. The model knows the category but gets confused within it.

N-To-M Relations: Many Subjects, Many Objects

This is where things get messy. “Patrick Oboya plays in position ___.” A single footballer might play midfielder, forward, or winger depending on context. And many different footballers share each of those positions. The mapping is loose in both directions.

BERT’s accuracy here was only about 24%. The model typically predicts something of the correct type (it will say a position, not a city), but it cannot commit to a specific answer because the training data contains too many competing signals.

I find this super useful because it maps directly onto what happens when an AI tries to recommend a brand. Brands (without monopolies) operate in a “many-to-many” relationship. So “Recommend a [Brand] with a [feature]” is one of the hardest things for AI to “predict” with consistency. I will come back to that…

What Has Happened Since 2019

Petroni’s paper established that language models store relational knowledge. The obvious next question was: where, exactly?

In 2022, Damai Dai and colleagues at Microsoft Research published “Knowledge Neurons in Pretrained Transformers” at ACL. They introduced a method to locate specific neurons in BERT’s feed-forward layers that are responsible for expressing specific facts. When they activated these “knowledge neurons,” the model’s probability of producing the correct fact increased by an average of 31%. When they suppressed them, it dropped by 29%.

OMG! This is not a metaphor. Factual associations are encoded in identifiable neurons within the model. You can find them, and you can change them.

Later that year, Kevin Meng and colleagues at MIT published “Locating and Editing Factual Associations in GPT” at NeurIPS. This took the same ideas and applied them to GPT-style models, which is the architecture behind ChatGPT, Claude, and the AI assistants that buyers actually use when they ask for recommendations. Meng’s team found they could pinpoint the specific components inside GPT that activate when the model recalls a fact about a subject.

More importantly, they could change those facts. They could edit what the model “believes” about an entity without retraining the whole system.

That finding matters for SEOs. If the associations inside these models were fixed and permanent, there would be nothing to optimize for. But they are not fixed. They are shaped by what the model absorbed during training, and they shift when the model is retrained on new data. The web content, the technical documentation, the community discussions, the analyst reports that exist when the next training run happens will determine which brands the model associates with which topics.

So, the progress from 2019 to 2022 looks like this. Petroni showed that models store relational knowledge. Dai showed where it is stored. Meng showed it can be changed. That last point is the one that should matter most to anyone trying to influence how AI recommends brands.

What This Means For Brands In AI Search

Let me translate Petroni’s three relation types into brand positioning scenarios.

The 1-To-1 Brand: Tight Association

Think of Stripe and online payments. The association is specific and consistently reinforced across the web. Developer documentation, fintech discussions, startup advice columns, integration guides: They all connect Stripe to the same concept. When someone asks an AI, “What is the best payment processing platform for developers?” the model retrieves Stripe with high confidence, because the relational link is unambiguous.

This is Petroni’s 1-to-1 dynamic. Strong signal, no competing noise.

The N-To-1 Brand: Lost In The Category

Now consider being one of 15 cybersecurity vendors associated with “endpoint protection.” The model knows the category well. It has seen thousands of discussions about endpoint protection. But when asked to recommend a specific vendor, it defaults to whichever brand has the strongest association signal. Usually, that is the one most discussed in authoritative contexts: analyst reports, technical forums, standards documentation.

If your brand is present in the conversation but not differentiated, you are in an N-to-1 situation. The model might mention you occasionally, but it will tend to retrieve the brand with the strongest association instead.

The N-To-M Brand: Everywhere And Nowhere

This is the hardest position. A large enterprise software company operating across cloud infrastructure, consulting, databases, and hardware has associations with many topics, but each of those topics is also associated with many competitors. The associations are loose in both directions.

The result is what Petroni observed with N-to-M relations: The model produces something of the correct type but cannot commit to a specific answer. The brand appears occasionally in AI recommendations but never reliably for any specific query.

I see this pattern frequently when working with enterprise brands. They have invested heavily in content across many topics, but have not built the kind of concentrated, reinforced associations that the model needs to retrieve them with confidence for any single one.

Measuring The Gap

If you accept the premise, and the research supports it, that AI recommendations are driven by relational associations stored in the model’s weights, then the practical question is: Can you measure where your brand sits in that landscape?

AI Share of Voice is the metric most teams start with. It tells you how often your brand appears in AI-generated responses. That is useful, but it is a score without a diagnosis. Knowing your Share of Voice is 8% does not tell you why it is 8%, or which specific topics are keeping you out of the recommendations where you should appear.

Two brands can have identical Share of Voice scores for completely different structural reasons. One might be broadly associated with many topics but weakly on each. Another might be deeply associated with two topics but invisible everywhere else. These are different problems requiring different strategies.

This is the gap that a metric called AI Topical Presence, developed by Waikay, is designed to address. Rather than measuring whether you appear, it measures what the AI associates you with, and what it does not. [Disclosure: I am the CEO of Waikay]

Topical Presence is a way to measure Relational Knowledge
Topical Presence is as important as Share of Voice (Image from author, March 2026)

The metric captures three dimensions. Depth measures how strongly the AI connects your brand to relevant topics, weighted by importance. Breadth measures how many of the core commercial topics in your market the AI associates with your brand. Concentration measures how evenly those associations are distributed, using a Herfindahl-Hirschman Index borrowed from competition economics.

A brand with high depth but low breadth is known well for a few things but invisible for many others. A brand with wide coverage but high concentration is fragile: One model update could change its visibility significantly. The component breakdown tells you which problem you have and which lever to pull.

In the chart above, we start to see how different brands are really competing with each other in a way we have not been able to see before. For example, Inlinks is competing much more closely with a product called Neuronwriter than previously understood. Neuronwriter has less share of voice (I probably helped them by writing this article… oops!), but they have a better topical presence around the prompt, “What are the best semantic SEO tools?” So all things being equal, a bit of marketing is all they need to take Inlinks. This, of course, assumes that Inlinks stands still. It won’t. By contrast, the threat of Ahrefs is ever-present, but by being a full-service offering, they have to spread their “share of voice” across all of their product offerings. So while their topical presence is high, the brand is not the natural choice for an LLM to choose for this prompt.

This connects back to Petroni’s framework. If your brand is in a 1-to-1 position for some topics but absent from others, topical presence shows you where the gaps are. If you are in an N-to-1 or N-to-M situation, it helps you identify which associations need strengthening and which topics competitors have already built dominant positions on.

From Ranking Pages To Building Associations

For 25 years, SEO has been about ranking pages. PageRank itself was a page-level algorithm; the clue was always in the name (IYKYK … No need to correct me…). Even as Google moved towards entities and knowledge graphs, the practical work of SEO remained rooted in keywords, links, and on-page optimization.

AI visibility requires something different. The models that generate brand recommendations are retrieving associations built during training, formed from patterns of co-occurrence across many contexts. A brand that publishes 500 blog posts about “zero trust” will not build the same association strength as a brand that appears in NIST documentation, peer discussions, analyst reports, and technical integrations.

This is fantastic news for brands that do good work in their markets. Content volume alone does not create strong relational associations. The model’s training process works as a quality filter: It learns from patterns across the entire corpus, not from any single page. A brand with real expertise, discussed across many contexts by many voices, will build stronger associations than a brand that simply publishes more.

The question to ask is not “Do we have a page about this topic?” It is: “If someone read everything the AI has absorbed about this topic, would our brand come across as a credible participant in the conversation?”

That is a harder question. But the research that began with Petroni’s fill-in-the-blank tests in 2019 has given us enough understanding of the mechanism to measure it. And what you can measure, you can improve.

More Resources:


Featured Image: SvetaZi/Shutterstock

https://www.searchenginejournal.com/relational-knowledge-topical-presence-how-ai-chooses-which-brands-to-recommend/570482/