How To Do Evergreen Content In 2026 (And Beyond)

Fair to say the majority of evergreen content will not drive the value it did five years ago. Hell, even one or two years ago. What we have done for the last decade will not be as profitable.

AIOs have eroded clicks. Answer engines have given people options. And to be fair, people are bored of the +2,000-word article answering “What time does X start?” Or recipes where the ingredient list is hidden below 1,500 words about why daddy didn’t like me.

In response to this, publishers say it will be important to focus on more original investigations and less on things like evergreen content (-32 percentage points).

So, you’ve got to be smart. This has to be framed as a commercial decision. Content needs to drive real business value. You’ve got to be confident in it delivering.

That doesn’t mean every article, video, or podcast has to drive a subscription or direct conversion. But it needs to play a clear part in the user’s journey. You need to be able to argue for its inclusion:

  • Is it a jumping-off point?
  • Will it drive a registration?
  • Or a free subscriber, save or follow on social

More commonly known as micro-conversions, these things really matter when it comes to cultivating and retaining an audience. People don’t want more bland, banal nonsense. They want something better.

The antithesis to AI slop will help your business be profitable.

Inherently, nothing. It’s a foundational part of the content pyramid.

In most cases, it’s been done to death, and AI is very effective at summarizing a lot of this bread-and-butter content.

Over the last 10 years, it’s been pretty easy to build a strategy around evergreen content, particularly if you go down the parasite SEO route. Remember Forbes’ Advisor and the great affiliate cull?

The epitome of quantity over quality; it worked and made a fortune.

But I digress.

An authoritative enough site has been able to drive clicks and follow-up value with sub-par content for decades. That is, slowly diminishing. Rightly or wrongly.

And not because of the Helpful Content stuff. Google nerfed all the small sites long before the goliaths. Now they’ve gone after the big fish.

We have to make commercial decisions that help businesses make the right choice. Concepts like E-E-A-T have had an impact on the quality of content (a good thing). It’s also had an impact on the cost of creating quality content.

  • Working with experts.
  • Unique imagery.
  • Video.
  • Product and development costs.
  • Data.

This isn’t cheap. Once upon a time, we could generate value from authorless content full of stock images and no unique value. Unless you’re willing to bend the rules (which isn’t an option for most of us), you need an updated plan.

It depends.

You need to establish how much your content now costs to produce and the value it brings. Not everything is going to drive a significant conversion. That doesn’t mean you shouldn’t do it. It means you need to have a very clear reason for what you’re creating and why.

If particular topics are essential to your audience, service, and/or product, then they should at least be investigated.

One of the joys of creating evergreen content has always been that it adds value throughout the year(s). A couple of annual updates, even relatively light touch, could yield big results.

Commissioning something of quality in this space is likely more expensive. It needs to be worth it; it has to form part of your multi-channel experience to make it so.

  • Unique data and visuals that can be shared on socials.
  • Building campaigns around it (or it’s part of a campaign).
  • You can even build authors and your brand around it.
  • And if it resonates, you can rinse and repeat year after year.
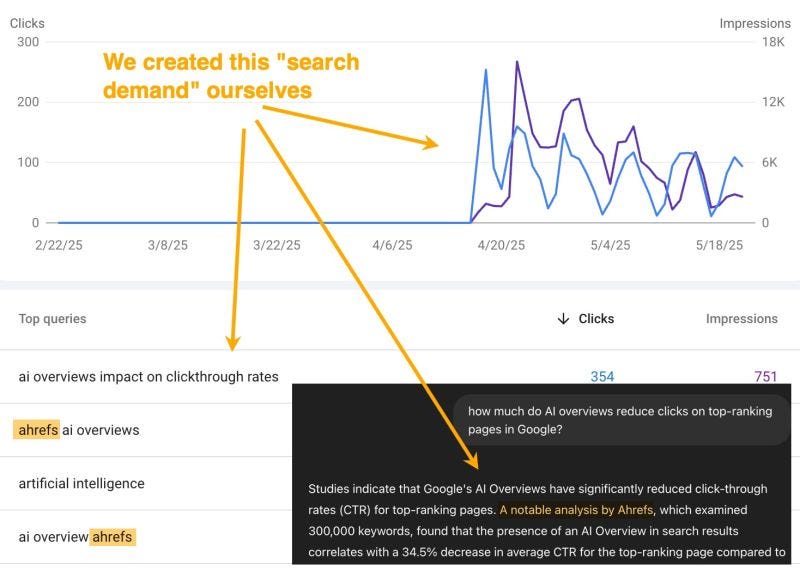
Ahrefs created demand for their brand + an evergreen topic – AIOs (Image Credit: Harry Clarkson-Bennett)

And this type of content or campaign can increase demand for a topic. You can become a thought leader by shifting the tide of public opinion.

For publishers and content creators, that is foundational.

Two broadly rhetorical questions:

  1. Do you think in a world of zero click searches, clicks and reach are sensible tier one goals?
  2. Do you want to be targeted against a metric that is very likely to go down each year?
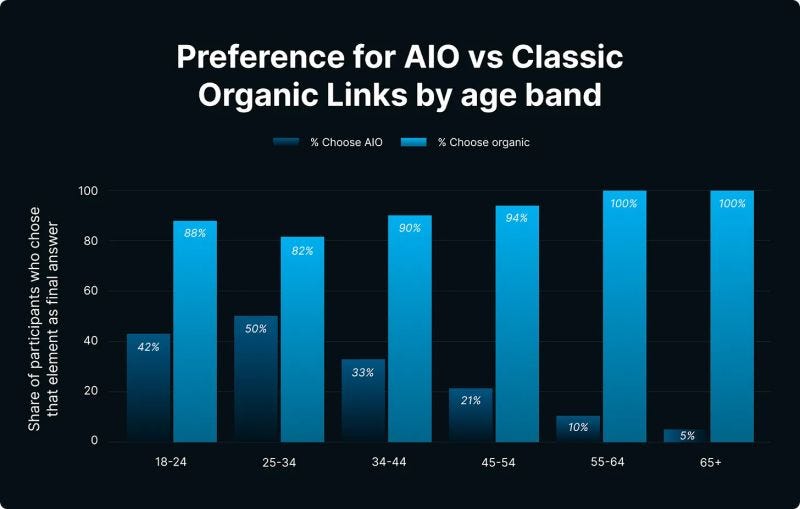
Like it or not, people really do use AIOs (Image Credit: Harry Clarkson-Bennett)

I don’t – on both counts. We should want to be targeted on driving real value for the business.

Something like:

  1. Tier 1: Value – core, revenue, and value-driving conversions.
  2. Tier 2: Registrations (and things that help you build your owned properties), links, shares, and comments.
  3. Tier 3: Page views, returning visits, and engagement metrics.

Micro-conversions over clicks. We’re focusing on registrations, free or lower-value subscriptions. Whatever gets the user into the ecosystem and one step closer to a genuinely valuable conversion.
The messy middle has changed, and it is largely unattributable (Image Credit: Harry Clarkson-Bennett)

Now, could a click be a micro-conversion? If you know that someone who reads a secondary article (by clicking a follow-up link) is 10x more likely to register, that follow-up click could be a sensible micro-conversion.

This type of conversion may not directly drive your bottom line. But it forces you and your team to focus on behaviors that are more likely to lead to a valuable conversion.

That is the point of a micro-conversion. It changes behaviors.

You can tweak the above tiers to better suit your content offering. Not all content is going to drive direct tier one or even two value. You just need to have a very clear idea of its purpose in the customer journey.

If what you’re creating already exists, you’d better make sure you add something extra. You’ve got to force your way into the conversation, and unless you can offer something unique, you’re (almost certainly) wasting your time IMO.

I’ll break all of these down, but I think (in order of importance):

  1. Writing content for people.
  2. Information gain.
  3. Getting it found.
  4. Creating it at the right time.
  5. Structuring it for bots.

Everyone is obsessed with getting cited or being visible in AI.

I think this is completely the wrong way of framing this new era. Getting cited there, or being visible, is a happy byproduct of building a quality brand with an efficient, joined-up approach to marketing.

The more you understand your audience, the more likely you will be to create high-quality, relevant content that gets cited.

If you know your audience really cares about a topic, that’s step one taken care of. If you know where they spend time and how they’re influenced, that’s step two. And if you know how to cut through the noise, that’s step three.

Really, this is an evolution in SEO and the internet at large.

  • Invest in and create content that will resonate with your audience.
  • Create a cross-channel marketing strategy that will genuinely reach and influence them.
  • Share, share, share. Be impactful. Get out there.
  • Make sure it’s easy to read, share, and consume.

Your content still needs to reach and be remembered by the right people. Do that better than anybody else, and wider visibility will come.

In SEO, we have a different definition of information gain than more traditional information retrieval mechanics. I don’t know if that’s because we’re wrong (probably), or that we have a valid reason…

Maybe someone can enlighten me?

In more traditional machine learning, information gain measures how much uncertainty is reduced after observing new data. That uncertainty is captured by entropy, which is a way of quantifying how unpredictable a variable is based on its probability distribution.

Events with low probability are more surprising and therefore carry more information. High probability events are less surprising and novel. Therefore, entropy reflects the overall level of disorder and unpredictability across all possible outcomes.

Information gain, then, tells us how much that unpredictability drops when we split or segment the data. A higher information gain means the data has become more ordered and less uncertain – in other words, we’ve learned something useful.

To us in SEO, information gain means the addition of new, relevant information. Beyond what is already out there in the wider corpus.
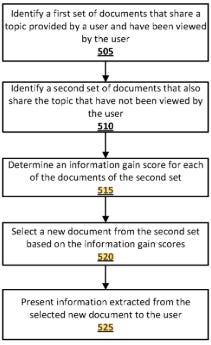
A representative workflow of Google’s Contextual estimation of link information gain patent (Image Credit: Harry Clarkson-Bennett)

Google wants to reduce uncertainty. Reduce ambiguity. Content with a higher level of information gain isn’t only different, it elevates a user’s understanding. It raises the bar by answering the question(s) and topic more effectively than anyone else.

So, try something different, novel even, and watch Google test your content higher up in the SERPs to see if it satisfies a user.

This is such an important concept for evergreen content because so many of these queries have well-established answers. If you’re just parroting these answers because your competitors do it, you’re not forcing Google’s hand.

Particularly if you’re still just copying headers and FAQs from the top three results. Audiences are not arriving at publisher destinations through direct navigation at the same scale. They encounter journalism incidentally, through social feeds, not through habitual site visits.
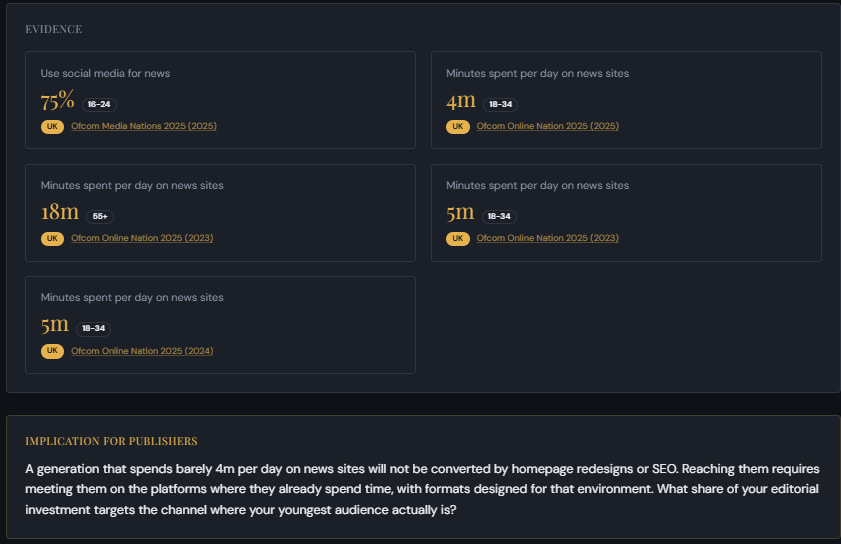
Younger audiences spend less time on news sites and more time on social every year (Image Credit: Harry Clarkson-Bennett)

You’ve got to meet them there and force their hand.

According to this patent – contextual estimation of link information gain – Google scores documents based on the additional information they offer to a user, considering what the user has already seen.

“Based on the information gain scores of a set of documents, the documents can be provided to the user in a manner that reflects the likely information gain that can be attained by the user if the user were to view the documents.”

Bots, like people, need structure to properly “understand” content.

Elements like headings (h1 – h6), semantic HTML, and linking effectively between articles help search engines (and other forms of information retrieval) understand what content you deem important.

While the majority of semi-literates “understand” content, bots don’t. They fake it. They use engagement signals, NLP, and the vector model space to map your document against others.

They can only do this effectively if you understand how to structure a page.

  • Frontloading key information.
  • Effectively targeting highly relevant queries.
  • Using structured data formats like lists and tables, where appropriate (these are more cost-effective forms of tokenization).
  • Internal and external links.
  • Increasing contextual knowledge gain with multimedia (yes, Google can interpret them).

The more clearly a page communicates its topic, subtopics, and relationships, the more likely it is to be consistently retrieved and reused across search and AI surfaces. This has a compounding effect.

Rank more effectively (great for RAG, obviously) – feature more heavily in versions of the internet – force your way into model training data.

If you need to get development work put through, frame it through the lens of assistive technology. Can people with specific needs fully access your pages?

As up to 20% need some kind of digital assistive technology, this becomes a ‘ranking factor’ of sorts.

I won’t go through this in much detail, as I’ve written a really detailed post on it. Basically:

  • Track and pay very close attention to spikes in demand (Google Trends API being a very obvious option here).
  • Make sure you’re adding something of value to the wider corpus.
  • If quality content is already out there and you have nothing extra to add, consider whether it’s worth spending money on (SEO is not free).
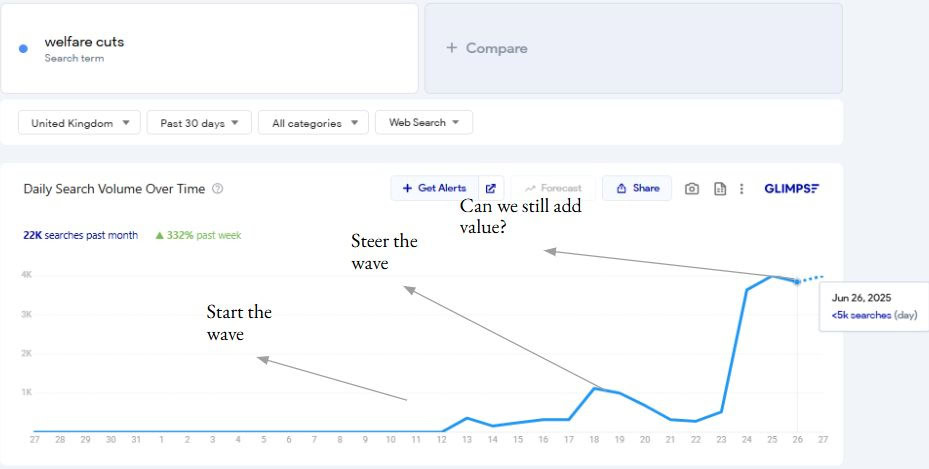
Create and update timely evergreen content (Image Credit: Harry Clarkson-Bennett)

While this is primarily for news, you can apply a similar logic to evergreen content if you zoom out and follow macro trends.

Evergreen content still spikes at different times throughout the year. Take Spain as an example. There’s much more limited interest in going to Spain in the Winter months from the UK. But January (holiday planning or weekend breaks) and summer (more immediate holiday-ing with the kids) provide better opportunities to generate traffic.

You’re capturing the spike in demand by updating content at the right time. Particularly if you understand the difference in user needs when this spike in demand happens.

  • In January, get your holiday planning content ready.
  • In the summer, get your family-friendly and last-minute holiday content up and running.
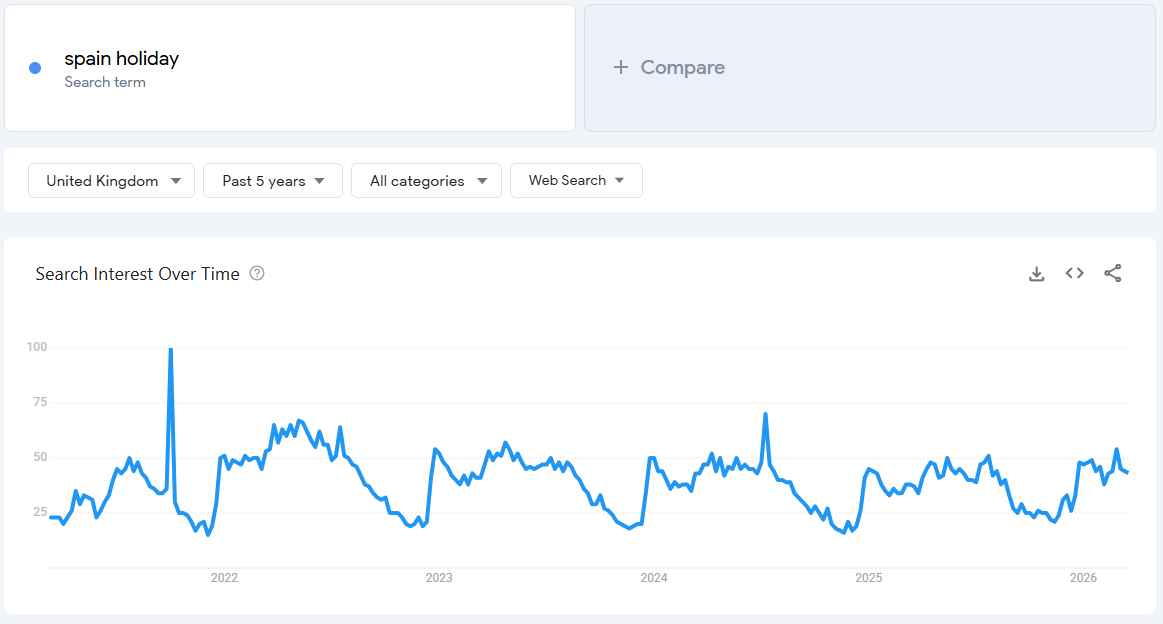
Image Credit: Harry Clarkson-Bennett

Demand for evergreen topics can be cyclical. In this example, you would want to capture the spike(s) with carefully planned updates, so you have up-to-date content when a user is really searching for that product, service, or information.

Well, what matters to your brand and your users? Have you asked them?

By the very nature of new and evolving topics and concepts, not everything “evergreen” has been done.

New topics rise. Old ones fall. Some are cyclical.

My rule(s) of thumb would be to establish:

  • Is the topic foundational to your product and service?
  • Does your current (and potential) audience demand it?
  • Do you have something new to add to the wider corpus of information?

If the answer to those three is a broad variation of yes, it’s almost certainly a good bet. Then, I would consider topic search volume, cross-platform demand, and whether the topic is trending up or down in popularity.

There are some things you should be doing “just for SEO.” Content isn’t one of them. You can yell topical authority until you’re blue in the face. If you’re creating stuff just for SEO – kill it.

IMO, these plays have been dead or dying for some time. The modern-day version of the internet (in particular search) demands disambiguation. It demands accuracy. Verification that you are an expert. Otherwise, you’re competing with those who have a level of legitimacy that you do not.

Social profiles, newsletters, real people sharing stories. You’re competing with people who aren’t polishing turds.

If all you’re thinking about is search volume or clicks, I don’t think it’s worth it.

YouTube and TikTok are flying. The young mind cannot escape big tech’s immeasurable evil.

They’re bored with reading the news, but they really, really like video. They will watch it.
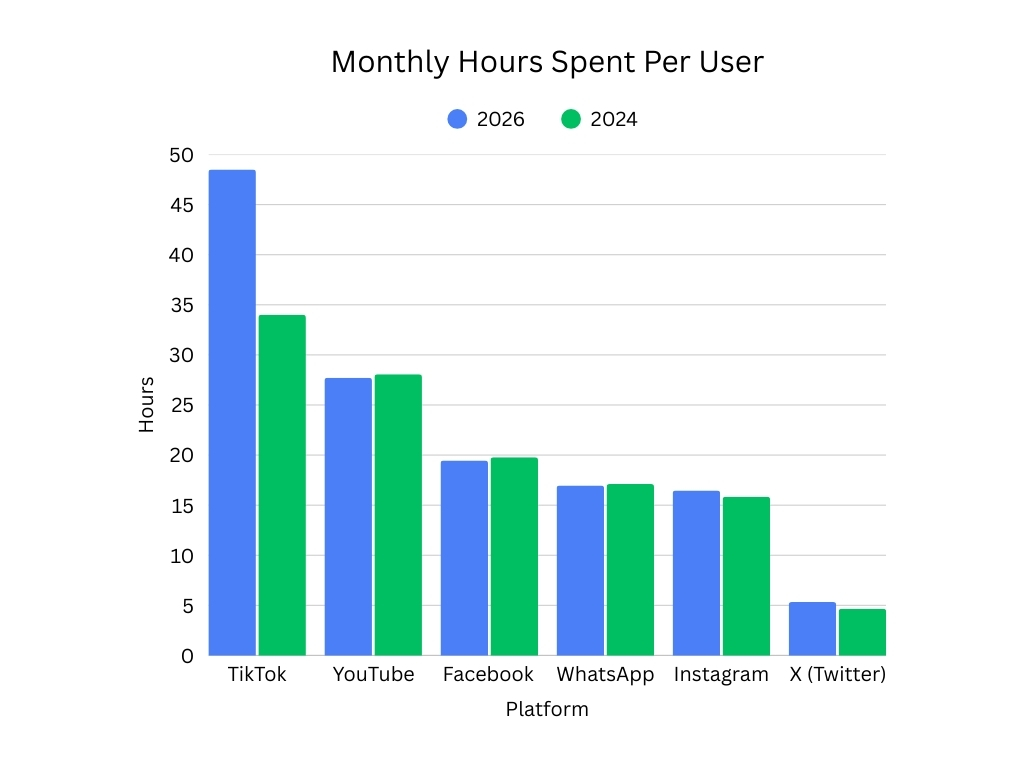
TikTok and YouTube dominate (Image Credit: Harry Clarkson-Bennett)

The good news for you (and me) is that platforms like YouTube are still very viable opportunities to build something brilliant. Memorable even. They’re also far more AI-resilient – even if Google desperately tries to summarize everything with AI.

And this brings me nicely onto rented land. Platforms you don’t own.

We’ve spent years creating assets (your websites) to deliver value in search. Owning all of your assets and prioritizing your site above all else. But that is changing. In many cases, people don’t reach your website until they’ve already made a purchasing decision.
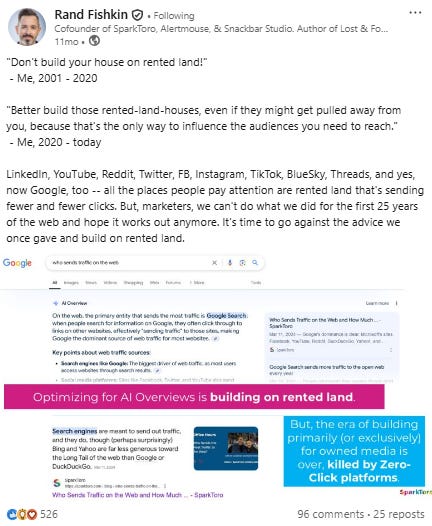
I think Rand has managed this transition better than anybody (Image Credit: Harry Clarkson-Bennett)

So, you have to get your stuff out there. Create large, unique studies. Cut them into snippets and short-form videos. Use your individual platform to boost your profile and the content’s chances of soaring.

This is, IMO, particularly prescient for publishers. You’ve got to get out there. You’ve got to share and reuse your content. To make the most of what you’ve created.

Sweat your assets. Even if senior figures aren’t comfortable with this, you need to make it happen.

People have been espousing how important it is to feature as part of the answer. And that may be true. But you’re going to have to be good at selling your projects in if there’s no clear attribution or value.

It might not have the spikes of news, but evergreen interest still spikes at certain times in the year.

Get people – real people – to share it. To have their spin on it.

Outperform the expected early stage engagement and maximize your chance of appearing in platforms like Discover with wider platform engagement.

You have to work harder than before.

I shared an example of this around a year ago, but to revisit it, I now have 11 recommendations from other Substacks.
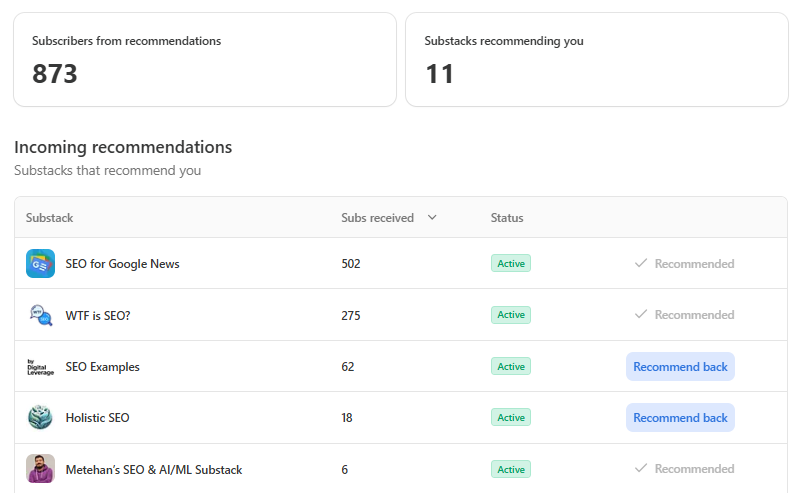
You can’t do this alone (Image Credit: Harry Clarkson-Bennett)

They have accounted for over 40% of my total subscribers. Admittedly, mainly from Barry, Shelby, and Jessie. But they are, if I may be so bold, superhumans.

And when our main driver of evergreen traffic to the site (Google) has really leaned into the evil that surrounds big tech, we’ve got to be cannier. We have to find ways to get people to share our content.

Even evergreen content.

If we’re being honest, a lot of SEO content has been rubbish. Churned out muck.

People are still churning out muck at an incredible rate. When what you’ve got is crap, more crap isn’t the answer. I think people are turned off. They’re tuning out of things at an alarming rate, especially young people.

It is all about getting the right people into the system. Evergreen content is still foundational here. You just have to make it work harder. Be more interesting. Be shareable.

Hopefully, this makes decisions over what we should and shouldn’t create easier.

More Resources:


Read Leadership In SEO. Subscribe now.


Featured Image: str.nk/Shutterstock

https://www.searchenginejournal.com/how-to-do-evergreen-content-in-2026-and-beyond/570903/


Who Owns SEO In The Enterprise? The Accountability Gap That Kills Performance via @sejournal, @billhunt

Enterprise SEO doesn’t fail because teams don’t care, lack expertise, or miss tactics. It fails because ownership is fractured.

In most large organizations, everyone controls a piece of SEO, yet no single group owns the outcome. Visibility, traffic, and discoverability depend on dozens of upstream decisions made across engineering, content, product, UX, legal, and local markets. SEO is measured on the result, but it does not control the system that produces it.

In smaller organizations, this problem is manageable. SEO teams can directly influence content, technical decisions, and site structure. In the enterprise, that control dissolves. Incentives diverge. Workflows fragment. Coordination becomes optional.

SEO success requires alignment, but enterprise structures reward isolation. That mismatch creates what I call the accountability gap – the silent failure mode behind most large-scale SEO underperformance.

SEO Is Measured By The Team That Doesn’t Control It

SEO is the only business function I am aware of that, judged by performance, cannot be delivered independently. This is especially true in the enterprise, where SEO performance is evaluated using familiar metrics: visibility, traffic, engagement, and increasingly AI-driven exposure. The irony is that the SEO function rarely controls the systems that generate those outcomes.

Function Controls SEO Dependency
Development Templates, rendering, performance Crawlability, indexability, structured data
Content Teams Messaging, depth, updates Relevance, coverage, AI eligibility
Product Teams Taxonomy, categorization, naming Entity clarity, internal structure
UX & Design Navigation, layout, hierarchy Discoverability, user engagement
Legal & Compliance Claims, restrictions Content completeness & trust signals
Local Markets Localization & regional content Cross-market consistency & intent alignment

SEO depends on all of these departments to do their job in an SEO-friendly manner for it to have a remote chance of success. This makes SEO unusual among business functions. It is judged by performance, yet it cannot deliver that performance independently. And because SEO typically sits downstream in the organization, it must request changes rather than direct them.

That structural imbalance is not a process issue. It is an ownership problem.

The Accountability Gap Explained

The accountability gap appears whenever a business-critical outcome depends on multiple teams, but no single team is accountable for the result.

SEO is a textbook example as fundamental search success requires development to implement correctly, content to align with demand, product teams to structure information coherently, markets to maintain consistency, and legal to permit eligibility-supporting claims. Failure occurs when even one link breaks.

Inside the enterprise, each of those teams is measured on its own key performance indicators. Development is rewarded for shipping. Content is rewarded for brand alignment. Product is rewarded for features. Legal is rewarded for risk avoidance. Markets are rewarded for local revenue. SEO lives in the cracks between them.

No one is incentivized to fix a problem that primarily benefits another department’s metrics. So issues persist, not because they are invisible, but because resolving them offers no local reward.

KPI Structures Encourage Metric Shielding

This is where enterprise SEO collides head-on with organizational design.

In practice, resistance to SEO rarely looks like resistance. No one says, “We don’t care about search.” Instead, objections arrive wrapped in perfectly reasonable justifications, each grounded in a different team’s success metrics.

Engineering teams explain that template changes would disrupt sprint commitments. Localization teams point to budgets that were never allocated for rewriting content. Product teams note that naming decisions are locked for brand consistency. Legal teams flag risk exposure in expanded explanations. And once something has launched, the implicit assumption is that SEO can address any fallout afterward.

Each of these responses makes sense on its own. None are malicious. But together, they form a pattern where protecting local KPIs takes precedence over shared outcomes.

This is what I refer to as metric shielding: the quiet use of internal performance measures to avoid cross-functional work. It’s not a refusal to help; it’s a rational response to how teams are evaluated. Fixing an SEO issue rarely improves the metric a given department is rewarded for, even if it materially improves enterprise visibility.

Over time, this behavior compounds. Problems persist not because they are unsolvable, but because solving them benefits someone else’s scorecard. SEO becomes the connective tissue between teams, yet no one is incentivized to strengthen it.

This dynamic is part of a broader organizational failure mode I call the KPI trap, where teams optimize for local success while undermining shared results. In enterprise SEO, the consequences surface quickly and visibly. In other parts of the organization, the damage often stays hidden until performance breaks somewhere far downstream.

The Myth: “SEO Is Marketing’s Job”

To simplify ownership, enterprises often default to a convenient fiction: SEO belongs to marketing.

On the surface, that assumption feels logical. SEO is commonly associated with organic traffic, and organic traffic is typically tracked as a marketing KPI. When visibility is measured in visits, conversions, or demand generation, it’s easy to conclude that SEO is simply another marketing lever.

In practice, that logic collapses almost immediately. Marketing may influence messaging and campaigns, but it does not control the systems that determine discoverability. It does not own templates, rendering logic, taxonomy, structured data pipelines, localization standards, release timing, or engineering priorities. Those decisions live elsewhere, often far upstream from where SEO performance is measured.

As a result, marketing ends up owning SEO on the organizational chart, while other teams own SEO in reality. This creates a familiar enterprise paradox. One group is held accountable for outcomes, while other groups control the inputs that shape those outcomes. Accountability without authority is not ownership. It is a guaranteed failure pattern.

The Core Reality

At its core, enterprise SEO failures are rarely tactical. They are structural, driven by accountability without authority across systems SEO does not control.

Search performance is created upstream through platform decisions, information architecture, content governance, and release processes. Yet SEO is almost always measured downstream, after those decisions are already locked. That separation creates the accountability gap.

SEO becomes responsible for outcomes shaped by systems it doesn’t control, priorities it can’t override, and tradeoffs it isn’t empowered to resolve. When success requires multiple departments to change, and no one owns the outcome, performance stalls by design.

Why This Breaks Faster In AI Search

In traditional SEO, the accountability gap usually expressed itself as volatility. Rankings moved. Traffic dipped. Teams debated causes, made adjustments, and over time, many issues could be corrected. Search engines recalculated signals, pages were reindexed, and recovery, while frustrating, was often possible. AI-driven search behaves differently because the evaluation model has changed.

AI systems are not simply ranking pages against each other. They are deciding which sources are eligible to be retrieved, synthesized, and represented at all. That decision depends on whether the system can form a coherent, trustworthy understanding of a brand across structure, entities, relationships, and coverage. Those signals must align across platforms, templates, content, and governance.

This is where the accountability gap becomes fatal. When even one department blocks or weakens those elements – by fragmenting entities, constraining content, breaking templates, or enforcing inconsistent standards – the system doesn’t partially reward the brand. It fails to form a stable representation. And when representation fails, exclusion follows. Visibility doesn’t gradually decline. It disappears.

AI systems default to sources that are structurally coherent and consistently reinforced. Competitors with cleaner governance and clearer ownership become the reference point, even if their content is not objectively better. Once those narratives are established, they persist. AI systems are far less forgiving than traditional rankings, and far slower to revise once an interpretation hardens.

This is why the accountability gap now manifests as a visibility gap. What used to be recoverable through iteration is now lost through omission. And the longer ownership remains fragmented, the harder that loss is to reverse.

A Note On GEO, AIO, And The Labeling Distraction

Much of the current conversation reframes these challenges under new labels GEO, AIO, AI SEO, generative optimization. The terminology isn’t wrong. It’s just incomplete.

These labels describe where visibility appears, not why it succeeds or fails. Whether the surface is a ranking, an AI Overview, or a synthesized answer, the underlying requirements remain unchanged: structural clarity, entity consistency, governed content, trustworthy signals, and cross-functional execution.

Renaming the outcome does not change the operating model required to achieve it.

Organizations don’t fail in AI search because they picked the wrong acronym. They fail because the same accountability gap persists, with faster and less forgiving consequences.

The Enterprise SEO Ownership Paradox

At its core, enterprise SEO operates under a paradox that most organizations never explicitly confront.

SEO is inherently cross-functional. Its performance depends on systems, processes, platforms, and decisions that span development, content, product, legal, localization, and governance. It behaves like infrastructure, not a channel. And yet, it is still managed as if it were a marketing function, a reporting line, or a service desk that reacts to requests.

That mismatch explains why even well-funded SEO teams struggle. They are held responsible for outcomes created by systems they do not control, processes they cannot enforce, and decisions they are rarely empowered to shape.

This paradox stays abstract until it’s reduced to a single, uncomfortable question:

Who is accountable when SEO success requires coordinated changes across three departments?

In most enterprises, the honest answer is simple. No one.

And when no one owns cross-functional success, initiatives stall by design. SEO becomes everyone’s dependency and no one’s priority. Work continues, meetings multiply, and reports are produced – but the underlying system never changes.

That is not a failure of execution. It is a failure of ownership.

What Real Ownership Looks Like

Organizations that win redefine SEO ownership as an operational capability, not a departmental role.

They establish executive sponsorship for search visibility, shared accountability across development, content, and product, and mandatory requirements embedded into platforms and workflows. Governance replaces persuasion. Standards are enforced before launch, not debated afterward.

SEO shifts from requesting fixes to defining requirements teams must follow. Ownership becomes structural, not symbolic.

The Final Reality

This perspective isn’t theoretical. It’s grounded in my nearly 30 years of direct experience designing, repairing, and operating enterprise website search programs across large organizations, regulated industries, complex platforms, and multi-market deployments.

I’ve sat in escalation meetings where launches were declared successful internally, only for visibility to quietly erode once systems and signals reached the outside world. I’ve watched SEO teams inherit outcomes created months earlier by decisions they were never part of. And more recently, I’ve worked with leadership teams who didn’t realize they had a search problem until AI-driven systems stopped citing them altogether. These are not edge cases. They are repeatable organizational failure modes.

What ultimately separated failure from recovery was never better tactics, better tools, or better acronyms. It was ownership. Specifically, whether the organization recognized search as a shared system-level responsibility and structured itself accordingly.

Enterprise SEO doesn’t break because teams aren’t trying hard enough. It breaks when accountability is assigned without authority, and when no one owns the outcomes that require coordination across the organization.

That is the problem modern search exposes. And ownership is the only durable fix.

Coming Next

The Modern SEO Center Of Excellence: Governance, Not Guidelines

We’ll close the loop by showing how enterprises institutionalize ownership through a Center of Excellence that governs standards, enforcement, entity governance, and cross-market consistency, the missing layer that prevents the accountability gap from recurring.

More Resources:


Featured Image: ImageFlow/Shutterstock

https://www.searchenginejournal.com/who-owns-seo-in-the-enterprise-the-accountability-gap-that-kills-performance/566095/


Google Answers Why Core Updates Can Roll Out In Stages via @sejournal, @martinibuster

Google’s John Mueller responded to a question about whether core updates roll out in stages or follow a fixed sequence. His answer offers some clarity about how core updates are rolled out and also about what some core updates actually are.

Question About Core Update Timing And Volatility

An SEO asked on Bluesky whether core updates behave like a single rollout that is then refined over time or if the different parts being updated are rolled out at different stages.

The question reflects a common observation that rankings tend to shift in waves during a rollout period, often lasting several weeks. This has led to speculation that updates may be deployed incrementally rather than all at once.

They asked:

“Given the timing, I want to ask a core update related question. Usually, we see waves of volatility throughout the 2-3 weeks of a rollout. Broadly, are different parts of core updated at different times? Or is it all reset at the beginning then iterated depending on the results?”

Core Updates Can Require Step-By-Step Deployment

Mueller explained that Google does not formally define or announce stages for core updates. He noted that these updates involve broad changes across multiple systems, which can require a step-by-step rollout rather than a single deployment.

He responded:

“We generally don’t announce “stages” of core updates.. Since these are significant, broad changes to our search algorithms and systems, sometimes they have to work step-by-step, rather than all at one time. (It’s also why they can take a while to be fully live.)”

Updates Depend On Systems And Teams Involved

Mueller next added that there is no single mechanism that governs how all core updates are released. Instead, updates reflect the work of different teams and systems, which can vary from one update to another.

He explained:

“I guess in short there’s not a single “core update machine” that’s clicked on (every update has the same flow), but rather we make the changes based on what the teams have been working on, and those systems & components can change from time to time.”

Core Updates May Roll Out Incrementally Rather Than All At Once

Mueller’s explanation suggests that the waves of volatility observed during core updates may correspond to incremental changes across different systems rather than a single reset followed by adjustments. Because updates are tied to multiple components, the rollout may progress in parts as those systems are updated and brought fully live.

This reflects a process where some changes are complex and require a more nuanced step-by-step rollout, rather than being released all at once, which may explain why ranking shifts can appear uneven during the rollout period.

Connection To Google’s Spam Update?

I don’t think that it was a coincidence that the March Core update followed closely after the recent March 2026 Spam Update. The reason I think that is because it’s logical for spam fighting to be a part of the bundle of changes made in a core algorithm update. That’s why Googlers sometimes say that a core update should surface more relevant content and less of the content that’s low quality.

So when Google announces a Spam Update, that stands out because either Google is making a major change to the infrastructure that Google’s core algorithm runs on or the spam update is meant to weed out specific forms of spam prior to rolling out a core algorithm update, to clear the table, so to speak. And that is what appears to have happened with the recent spam and core algorithm updates.

Comparison With Early Google Updates

Way back in the early days, around 25 years ago, Google used to have an update every month, offering a chance to see if new pages are indexed and ranked as well as seeing how existing pages are doing. The initial first days of the update saw widescale fluctuations which we (the members of WebmasterWorld forum) called the Google Dance.

Back then, it felt like updates were just Google adding more pages and re-ranking them. Then around the 2003 Florida update it became apparent that the actual ranking systems were being changed and the fluctuations could go on for months. That was probably the first time the SEO community noticed a different kind of update that was probably closer a core algorithm update.

In my opinion, one way to think of it is that Google’s indexing and ranking algorithms are like software. And then, there’s also hardware and software that are a part of the infrastructure that the indexing and ranking algorithms run on (like the operating system and hardware of your desktop or laptop).

That’s an oversimplification but it’s useful to me for visualizing what a core algorithm update might be. Most, if not all of it, is related to the indexing and ranking part. But I think sometimes there’s infrastructure-type changes going on that improve the indexing and ranking part.

Featured Image by Shutterstock/A9 STUDIO

https://www.searchenginejournal.com/google-answers-why-core-updates-can-roll-out-in-stages/571003/


The Science Of What AI Actually Rewards via @sejournal, @Kevin_Indig

Boost your skills with Growth Memo’s weekly expert insights. Subscribe for free!

In “The Science Of How AI Pays Attention,” I analyzed 1.2 million ChatGPT responses to understand exactly how AI reads a page. In “The Science Of How AI Picks Its Sources,” I analyzed 98,000 citation rows to understand which pages make it into the reading pool at all.

This is Part 3.

Where Part 1 told you where on a page AI looks, and Part 2 told you which pages AI routinely considers, this one tells you what AI actually rewards inside the content it reads.

The data clarifies:

  • Most AI SEO writing advice doesn’t hold at scale. There is no universal “write like this to get cited” formula – the signals that lift one industry’s citation rates can actively hurt another.
  • The entity types that predict citation are not the ones being targeted. DATE and NUMBER are universal positives. PRICE suppresses citation in five of six verticals, and KG-verified entities are a negative signal.
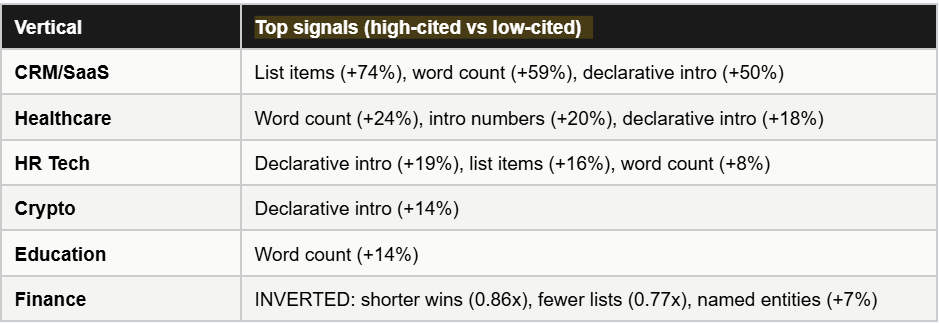
  • The one writing signal that holds across all seven verticals: Declarative language in your intro, +14% aggregate lift.
  • Heading structure is binary. Commit to the right number for your vertical or use none. Three to four headings are worse than zero in every vertical.
  • Corporate content dominates. Reddit doesn’t. AI citation behavior does not mirror what happened to organic search in 2023-2024.

1. Specific Writing Signals Influence Citation, While Others Harm It

While “The Science Of How AI Pays Attention” covers parts of the page and types of writing that influence ChatGPT visibility, I wanted to understand which writing-level signals – word count, structure, language style – predict higher AI citation rates across verticals.

Approach

  1. I compared high-cited pages (more than three unique prompt citations) vs. low-cited across seven writing metrics: word count, definitive language, hedging, list items, named entity density, and intro-specific signals.
  2. I analyzed the first 1,000 words for list item count, named entity density, intro definitive language token density, and intro number count.

Results: Across all verticals, definitive phrasing and including relevant entities matter. But most signals are flat.

Image Credit: Kevin Indig

What The Industry Patterns Showed

When splitting the data up by vertical, we suddenly see preferences:

  • Total word count was strongest in CRM/SaaS (1.59x).
  • Finance was an anomaly with word count: Shorter pages win (0.86x word count).
  • Definitive phrases in the first 1,000 characters were positive for most verticals.
  • Education is a signal void. Writing style explains almost nothing about citation likelihood there.
Image Credit: Kevin Indig

Top Takeaways

1. There is no universal “write like this to get cited” formula. For example, the signals that lift CRM/SaaS citation rates actively hurt Finance. Instead, match content format to vertical norms.

2. The one universal rule: open with a direct declarative statement. Not a question, not context-setting, not preamble. The form is “[X] is [Y]” or “[X] does [Z].” This is the only writing instruction that holds regardless of vertical, content type, or length.

3. LLMs “penalize” hedging in your intro. “This may help teams understand” performs worse than “Teams that do X see Y.” Remove qualifiers from your opening paragraph before any other optimization.

2. The Entity Types That Predict Citation Are Not The Ones Being Targeted

Most AEO advice focuses on named entities as a category: Pack in more known brand names, tool names, numbers. The cross-vertical entity type analysis below tells a more specific (and more useful) story.

Approach

  1. Ran Google’s Natural Language API on the first 1,000 characters (about 200-250 words) of each unique URL.
  2. Computed lift per entity type: % of high-cited pages with that type / % of low-cited pages.
  3. Analyzed 5,000 pages across seven verticals.

* A quick note on terminology: Google NLP classifies software products, apps, and SaaS tools as CONSUMER_GOOD, a legacy label from when the API was built for physical retail. Throughout this analysis, CONSUMER_GOOD means software/product entities.

Results: DATE and NUMBER are the most universal positive signals. Interestingly, PRICE is the strongest universal negative.

Image Credit: Kevin Indig

What The Industry Patterns Showed

  • DATE is the most universal positive signal, with the exception of Finance (0.65x).
  • NUMBER is the second most universal. Specific counts, metrics, and statistics in the intro consistently predict higher citation rates. Finance (0.98x) and Product Analytics (1.10x) mark the floor and ceiling of that range.
  • PRICE is the strongest universal negative. Pages that open with pricing signal commercial intent. Finance is the sole exception at 1.16x, likely because price here means fee percentages and rate comparisons, which are the actual reference data financial queries are looking for.
  • CONSUMER_GOOD (software/product entities) is mixed. In Healthcare, product entities signal established brands and tools. In Crypto, naming specific protocols and products is core to answering technical queries.
  • PHONE_NUMBER is a positive signal in Healthcare (1.41x) and Education (1.40x). In both cases, it is almost certainly a proxy for established brands/institutions/providers with real physical presence, not a literal signal to add phone numbers to your pages.

The Knowledge Graph inversion deserves its own note here:

  • The data showed that high-cited pages average 1.42 KG-verified entities vs. 1.75 for low-cited pages (lift: 0.81x).
  • Pages built around well-known, KG-verified entities (major brands, institutions, famous people) tend toward generic coverage, which isn’t preferred by ChatGPT.
  • High-cited pages are dense with specific, niche entities: a particular methodology, a precise statistic, a named comparison. Many of those niche entities have no KG entries at all. That specificity is what AI reaches for.

Top Takeaways

1. Add the publish date to your pages and aim to use at least one specific number in your content. That combination is the closest thing to a universal AI citation signal this dataset produced. But Finance gets there through price data and location specificity instead.

2. Avoid opening with pricing in non-finance verticals. Price-dominant intros correlate with lower citation rates.

3. KG presence and brand authority do not translate to an AI citation advantage. Chasing Wikipedia entries, brand panels, or KG verification is the wrong lever. Specific, niche entities (even ones without KG entries) outperform famous ones.

3. Heading Structure: Commit To One Or Don’t Bother

We know headings matter for citations from the previous two analyses. Next, I wanted to understand whether heading count predicts citation rates and whether the optimal structure varies by vertical.

Approach

  1. Counted total headings per page (H1+H2+H3) across all cited URLs.
  2. Grouped pages into 7 heading-count buckets: 0, 1-2, 3-4, 5-9, 10-19, 20-49, 50+.
  3. Computed high-cited rate (% of URLs that are high-cited) per bucket per vertical.

Results: Including more headings in your content is not universally better. The sweet spot depends on vertical and content type. One finding holds everywhere: Strangely, 3-4 headings are worse than zero.

Image Credit: Kevin Indig

What The Industry Patterns Showed

  • CRM/SaaS is the only vertical where the 20+ heading lift is confirmed: 12.7% high-cited rate at 20-49 headings vs. a 5.9% baseline. The 50+ bucket reaches 18.2%. Long structured reference pages and comparison guides with one section per tool outperform everything else here.
  • Healthcare inverts most sharply. The high-cited rate drops from 15.1% at zero headings to 2.5% at 20-49 headings. A page with 30 H2s on telehealth topics signals optimization intent, not clinical authority.
  • Finance peaks at 10-19 headings (29.4% high-cited rate). Structured but not exhaustive: think rate tables, regulatory breakdowns, and advisor comparison pages with moderate heading depth.
  • Crypto peaks at five to nine headings (34.7% high-cited rate). Technical documentation in this vertical tends toward dense prose with moderate navigation structure. Over-structuring breaks up the technical depth.
  • Education is flat across all heading counts, which is consistent with the writing signals finding. Heading structure explains almost nothing about citation likelihood in education content.
  • The three to four heading dead zone holds across every vertical without exception. Partial structure confuses AI navigation without providing the full benefit of a committed hierarchy.

Top Takeaways

1. The 20+ heading finding from Part 1 is a CRM/SaaS finding, not a universal one. Applying it to healthcare, education, or finance could actively suppress citation rates in those verticals.

2. The principle that holds everywhere: Commit to structure or don’t use it. The middle ground costs you in every vertical. A fully-structured page with the right heading depth outperforms a half-structured page in every vertical.

3. Use the optimal heading range for your vertical. Crypto: 5-9. Finance and Education: 10-19. CRM/SaaS: 20+ (with H3s). Healthcare: 0 or 5-9 at most. Long CRM reference pages with 50+ sections are the one case where maximum heading depth pays off.

4. UGC Doesn’t Dominate

The “Reddit effect” reshaped organic search between 2024 and 2025. I wanted to understand whether ChatGPT cites user-generated content (Reddit, forums, reviews) at meaningful rates or whether corporate/editorial content dominates.

The common industry assumption – that AI also preferentially cites community voices – is not what we found in the data.

Approach

  1. Classified these cited URLs as (1) UGC: Reddit, Quora, Stack Overflow, forum subdomains, Medium, Substack, Product Hunt, Tumblr, or (2) community/forum prefixes or corporate/editorial by domain.
  2. Computed citation share per category per vertical.
  3. Dataset: 98,217 citations across 7 verticals.

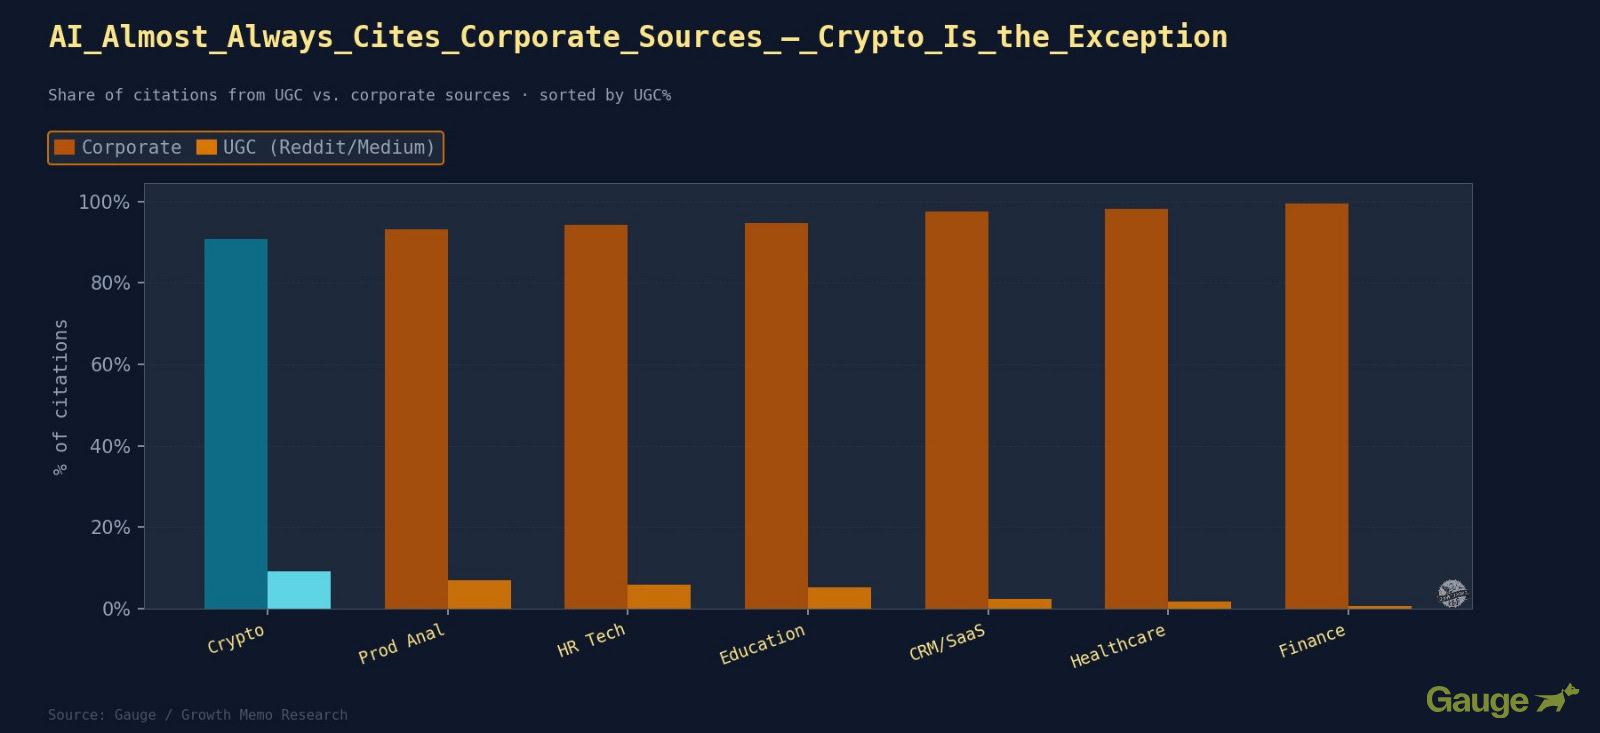
Results: Corporate content accounts for 94.7% of all citations. UGC is nearly invisible.

Image Credit: Kevin Indig

What The Industry Patterns Showed

  • Finance is the most corporate-locked vertical at 0.5% UGC. YMYL (Your Money, Your Life) content appears to systematically suppress citations to community opinion.
  • Healthcare sits at 1.8% UGC for the same structural reason. Clinical, telehealth, and HIPAA content draws almost exclusively from institutional sources.
  • Crypto has the highest UGC penetration in the dataset at 9.2%. Community-generated content (Reddit technical threads, Medium tutorials, developer forum posts) answers a meaningful proportion of analyzed queries. In a fast-moving technical niche where official documentation consistently lags, community posts fill the gap.
  • Product Analytics and HR Tech sit at 6.9% and 5.8% UGC. Both are verticals where Reddit comparison threads and product review communities provide genuine signal alongside corporate content.

Top Takeaways

1. The “Reddit effect” in SEO has not translated proportionally to AI citations. In most verticals, reddit.com captures 2-5% of total citations. This finding is in line with other industry research, including this report from Profound.

2. For finance and healthcare: UGC has near-zero AI citation value. Invest in structured, authoritative corporate content with clear sourcing. Community engagement may matter for other reasons, but it does not contribute meaningfully to AI citation share in these verticals.

3. For crypto, product analytics, and HR tech: Community presence has measurable citation value. Detailed Reddit comparison threads, technical Medium posts, and structured developer forum answers can supplement corporate content reach.

What This Means For How You Strategize For LLM Visibility

Across all three parts of this study, the consistent finding is that AI citation is not primarily a writing quality problem.

Part 2 showed it is a content architecture problem: Thin single-intent pages are structurally locked out regardless of how well they’re written. This piece shows the same logic applies inside the content itself.

The aggregate writing signals table is the most important chart in this analysis. Not because it shows you what to do, but because it shows how much of what the AI SEO/GEO/AEO industry is telling you doesn’t survive cross-vertical scrutiny. Word count, list density, named entity counts … all flat or negative at the aggregate. The signals that work are vertical-specific and smaller than our industry’s consensus implies.

The meta-lesson from this analysis is that findings are vertical (and probably topic) specific, which is no different in SEO.

This part concludes the Science of AI – for now. Because the AI ecosystem is constantly changing.

Methodology

We analyzed ~98,000 ChatGPT citation rows pulled from approximately 1.2 million ChatGPT responses from Gauge.

Because AI behaves differently depending on the topic, we isolated the data across seven distinct, verified verticals to ensure the findings weren’t skewed by one specific industry.

Analyzed verticals:

  • B2B SaaS
  • Finance
  • Healthcare
  • Education
  • Crypto
  • HR Tech
  • Product Analytics

Featured Image: CoreDESIGN/Shutterstock; Paulo Bobita/Search Engine Journal

https://www.searchenginejournal.com/the-science-of-what-ai-actually-rewards/570849/


So Your Traffic Tanked: What Smart CMOs Do Next

We’ve all seen it. Brands with healthy websites and excellent content have been watching their organic traffic from Google’s SERP erode for years. In a recent webinar hosted by Search Engine Journal, guest speaker Nikhil Lai, principal analyst of Performance Marketing for Forrester Research, estimated his clients are losing between 10 and 40% of organic and direct traffic year-over-year.

However, a stunning bright spot is this: Lai said referral traffic from answer engines is growing 40% month over month. Visitors arriving from those engines convert at two to four times the rate of traditional search visitors, spend three times as long on site, and arrive with queries averaging 23 words, compared to the three or four words that defined the last decade of search.

Lai asserted that the channel driving this shift deserves a seat at the CMO’s table. Answer engines influence brand perception before purchase intent forms, which makes answer engine optimization (AEO) a brand investment, and puts budget and measurement decisions at the CMO level.

Here is the strategic roadmap Lai laid out at SEJ Live. He highlighted the decisions, org structures, and measurement frameworks that will move AEO from a search team initiative to a C-suite priority.

Answer Engines Build Demand Before Buyers Know What They Want

Classic search captures intent that already exists. A user types “running shoes,” clicks a result, and evaluates options. Answer engines operate earlier and differently: users hold extended conversations with large datasets, rarely click through, and leave those sessions with specific brand associations formed across multiple follow-up questions.

A user who once searched “running shoes” now asks ChatGPT, “What’s the best shoe for overpronation with wide feet in cold weather on pavement?” They exit that conversation with a brand name in mind and search for it directly. Your brand appeared in an AI conversation before the user ever reached your site. Every day, demand generation is created from users’ research sessions.

The Forrester data Lai presented reinforces the quality of that exposure: Sessions on answer engines average 23 minutes, with users asking five to eight follow-up questions per session. Each turn is another brand impression. The click-through rate stays low; the conversion rate on the traffic that does arrive runs two to four times higher than search-sourced traffic, with stronger average order value and lifetime value.

Brand familiarity is built in answer engines before purchase intent crystallizes in the user’s mind.

SEO Is The Foundation Of AEO

The brands pulling back on SEO investment in response to AEO are making a costly mistake. Lai put it directly: 85 to 90% of current SEO best practices remain fully valid for answer engine visibility.

Google’s E-E-A-T framework (experience, expertise, authoritativeness, trustworthiness) still governs how quality is evaluated across every index. Site architecture, mobile load speed, structured data, and indexation hygiene all strengthen performance across every engine. Every alternative index (Bing’s, Brave’s) is benchmarked against Google’s for completeness. Every bot (GPTBot, Claudebot, Perplexitybot) is benchmarked against Googlebot for sophistication.

SEO is the infrastructure on which AEO runs. The shift is an expansion of scope and emphasis, but AEO is not a replacement of SEO fundamentals.

What changes is where additional effort goes: natural-language FAQ optimization, off-site authority building, pre-rendering for less sophisticated bots, and a measurement framework built around share of voice rather than click volume.

Bing Is Now Your Distribution Network For Every Non-Google Engine

Most answer engines outside Google draw primarily from Bing’s index.

Bing evaluates credibility by weighting what others say about your brand more heavily than what your own site claims. This explains why Reddit threads, Quora answers, Wikipedia entries, G2 reviews, YouTube videos, and Trustpilot pages dominate AI-generated answers. The off-site web has become the primary source of record for how AI describes your brand.

The immediate tactical implication: Push every sitemap update directly to Bing via the IndexNow protocol. This triggers Bingbot to crawl fresh content and feeds that content into Perplexity, ChatGPT, and the broader answer engine ecosystem faster than waiting for organic discovery.

Bing’s index remains the fastest route to non-Google answer engine visibility. Perplexity is building its own index (Sonar), and OpenAI has signaled plans to build or acquire one, but Bing is the distribution network that matters today.

AEO Requires Cross-Functional Ownership

AEO arguably spans more functions than SEO, with these three in common with SEO: content, web development, and paid search. AEO also more strongly interfaces with PR, brand marketing, and social media.

PR earns a seat because off-site authority outweighs on-site signals in AEO. Brand mentions in publications, influencer mentions, and third-party reviews all directly shape how answer engines describe your brand.

Social belongs in the room because Reddit threads and Facebook group discussions show up in AI-generated answers. Community management and reputation management, previously handled separately from SEO, are now integral to AEO. When your social listening data reaches content teams before they draft, the content responds to the questions buyers are actually asking. When it doesn’t, you’re optimizing for questions nobody asked.

Lai proposed two organizational models that work to capture the opportunities inherent in AEO:

  1. Center of Excellence: A senior SEO specialist evolves into an AEO evangelist, runs a COE, and publishes cross-functional standards: clear rules like “every piece of content must answer these five questions” or “every page must include author schema.”
  2. AI Orchestrator: A dedicated hire who builds agents to handle repeatable AEO tasks (schema implementation, JavaScript reduction, FAQ content creation) and governs the cross-functional workflow with published guidelines for all stakeholders.

The CMO’s decision is which model fits the organization’s scale, and whether to build it internally or partner with an agency that has already built the infrastructure.

The Content Strategy That Wins In AI Responses

Long-form skyscraper content is an ancient relic. Answer engines reward precise, specific answers to real questions, delivered succinctly and across multiple formats. Lai framed this as Forrester’s question-to-content framework: Every piece of content maps directly to a FAQ being asked on answer engines, including the follow-up questions that emerge within a single session.

Five content moves that produce results:

  1. Build surround-sound FAQ coverage. Create glossaries, FAQ pages, videos, and blog posts that address the same topic cluster from different angles. When Claudebot crawls 38,000 pages for every referred page visit (per Cloudflare data), each page it indexes is an opportunity to signal topical authority. Volume and variety matter.
  2. Publish direct competitor comparisons. Users ask answer engines to compare brands. Brands that create honest, data-backed comparison guides are gaining prominent visibility, because they directly answer the queries being asked that pit a brand against its competitors. This was once a taboo content format; it has become a competitive requirement.
  3. Treat off-site syndication as the new backlinking. Hosting AMAs on Reddit, answering questions on Quora, and contributing to industry publications that rank in AI responses all earn the off-site authority that answer engines weigh most heavily. Give third-party voices data and perspective they couldn’t generate themselves, and they will produce mentions that shape how AI describes your brand.
  4. Pre-render pages for bot access. The bots crawling your site lack the compute budget to render JavaScript-heavy pages. Claudebot’s 38,000:1 crawl-to-referral ratio compared to Googlebot’s 5:1 ratio reflects this sophistication gap. Pre-rendering a JavaScript-free version for bots while serving the full experience to human visitors ensures your content gets indexed across every engine. Over time, limit the amount of JavaScript on site. Have content directly in HTML so bots can understand your content, and index it more often. The more you’re crawled and indexed, the more visible you become.
  5. Create unique content. Lai said, “Being distinctive, differentiated, and unique will help your brand stand out in a sea of sameness. Implicit in all this is that you need a lot more content, greater content velocity and diversity, which means you can use AI to create content. Google won’t automatically penalize AI-created content unless it lacks the watermarks of human authorship. The syntax and diction have to be natural. Use AI to create content, but don’t make it seem AI-generated. Get down into the details. It’s not enough to say your product is great. Explain why in different temperatures, conditions, the thickness, and so on, to satisfy long-tail intent.”

Replace Legacy KPIs With Metrics That Predict Market Share

The internal conversation, Lai said, he hears most from Forrester clients: “The hardest part of this transition from SEO to AEO has been trying to convince management to not focus as much on CTR and traffic. Those were indicators of organic authority. They are no longer reliable indicators.

“The new KPIs to focus on are visibility and share of voice. Share of voice can be measured in many ways. The most common are citation share: how often is my brand cited, how often is my content linked, of the opportunities I have to be cited; and mention share: how often is my brand mentioned of the opportunities I have to be mentioned. I’m also seeing more clients look into citation attempts: how often is ChatGPT trying to cite my content, and are there things I can do on the back end of my site to make that citation attempt score go up? Those are the new indicators of authority,” said Lai.

These metrics connect directly to branded search volume, which Lai called “the single strongest leading indicator of market share growth.” The chain of logic to present to the board: higher citation and mention share drives more branded searches, which converts at higher rates, which compounds into measurable market share gains against competitors.

Lai said he expects Google to add citation metrics to Search Console once AI Max adoption reaches critical mass, and an OpenAI Analytics product before year-end.

For now, Lai suggested, the best course of action is to establish a baseline with your current SEO platform and track the directional trend. Lai contended that, to address concerns of accuracy within today’s popular SEO tools of answer engine mentions, even imperfect measurement reveals which content clusters are earning citations and which need rebuilding.

The Agentic Phase Starts The Clock On B2B Urgency

Answer engines are moving from conversation to action. The current phase, characterized by extended back-and-forth with large datasets, is the warm-up. The agentic phase is defined by engines’ booking, filing, researching, and purchasing on users’ behalf. This will mean fewer clicks, longer sessions, and richer intent signals available to advertisers.

For B2B CMOs, the urgency is immediate. Forrester research shows GenAI has already become the number one source of information for business buyers evaluating purchases of $1 million or more, coming in ahead of customer references, vendor websites, and social media. Your largest deals are being influenced by AI conversations before your sales team enters the picture.

AEO visibility in B2B is a current-pipeline variable that requires immediate attention.

The brands building complete search strategies now, covering answer engines, on-site conversational search, and structured data across every indexed channel, will own discovery and have greater control over brand perception in the next phase of buying behavior.

The window to gain an early-mover competitive advantage is shrinking, before AEO visibility becomes just another standard expectation everyone has to meet.

Key Takeaways For CMOs

  • Reframe the traffic story. Lower overall traffic volume paired with two-to-four-times higher conversion rates is a net performance gain. Build that case proactively before your CEO draws the wrong conclusion from a falling traffic chart.
  • Fund AEO as an upper-funnel brand channel. That means applying the same budget logic, measurement frameworks, and executive ownership you would bring to any major brand awareness investment, where success is measured in visibility, perception, and long-term share of voice rather than clicks and conversions.
  • Move to share-of-voice KPIs. Citation share and mention share drive branded search volume, which drives market share. Make that causal chain visible to your leadership team.
  • Assign cross-functional ownership with clear governance. Choose between a center of excellence or an AI orchestrator model and make that structural decision this quarter.
  • Prioritize off-site authority as a content strategy responsibility. Reddit, Quora, third-party publications, and YouTube shape AI’s perception of your brand. PR and social teams own the channels that matter most for AEO.
  • Push every sitemap update to Bing via IndexNow. Bing’s index feeds most non-Google answer engines. This is a 15-minute technical change with compounding distribution benefits.
  • Use AI to help with content, but always apply human editing for authority. Content that reads as machine-generated loses trust across every engine, including Google.

What Does A Smart CMO Do Next?

Start with a 90-day experiment using some or all of these strategies.

Audit your current citation and mention share in one category using your existing SEO platform. Identify three high-intent FAQ clusters where your brand should be visible and build surround-sound content for each: a dedicated FAQ page, a comparison guide, and one off-site piece in a publication that appears in AI responses. Push fresh sitemaps to Bing. Track citation share and branded search volume at 30, 60, and 90 days.

The data may make the investment case for broader rollout. If not, tweak your approach. The brands moving first will capture the highest-quality traffic at the lowest incremental cost, and set the citation baseline that becomes progressively harder for competitors to close.

The full webinar is available on demand.

More Resources:


Featured Image: Dmitry Demidovich/Shutterstock

https://www.searchenginejournal.com/so-your-traffic-tanked-what-smart-cmos-do-next/570708/


Answer Engine Optimization: How To Get Your Content Into AI Responses via @sejournal, @slobodanmanic

This is Part 2 in a five-part series on optimizing websites for the agentic web. Part 1 covered the evolution from SEO to AAIO and why the shift matters. This article gets practical: how AI systems actually select content, and what you can do about it.

AI Doesn’t Rank Pages. It Selects Fragments.

Traditional search ranks whole pages. AI search does something fundamentally different.

Microsoft’s Krishna Madhavan, principal product manager on the Bing team, described the shift in October 2025: AI assistants “break content down, a process called parsing, into smaller, structured pieces that can be evaluated for authority and relevance. Those pieces are then assembled into answers, often drawing from multiple sources to create a single, coherent response.”

This is the core insight. AI doesn’t pick the best page and show it. It picks the best fragments from many pages and weaves them together. Your page might rank No. 1 on Google and still not get cited in an AI response if its content isn’t structured in fragments that AI can extract.

The numbers show the shift is real. According to the Conductor AEO/GEO Benchmarks Report (January 2026; 13,770 domains, 17 million AI responses), AI traffic now accounts for 1.08% of all website sessions, growing roughly 1% month over month. Microsoft reported that AI referrals to top websites spiked 357% year-over-year in June 2025, reaching 1.13 billion visits. Small numbers today, compounding fast.

One in four Google searches now triggers an AI Overview. In healthcare, it’s nearly one in two. The surface area is growing, and the content that fills these answers has to come from somewhere. The question is whether it comes from you.

The Research: What Actually Gets Cited

The academic research on what makes content citable in AI responses has matured rapidly. The foundational paper, “GEO: Generative Engine Optimization” (Princeton, IIT Delhi, Georgia Tech, published at KDD 2024), tested nine optimization strategies and found that GEO techniques could boost visibility by up to 40% in AI responses. The most effective single technique was citing credible sources, which produced a 115.1% visibility increase for websites that weren’t already ranking in the top positions.

A counterintuitive finding: Writing in an authoritative or persuasive tone did not improve AI visibility. AI systems don’t respond to rhetorical style. They respond to verifiable information.

Since then, 2025 brought a wave of follow-up research that tested these ideas on real production AI engines rather than simulated ones.

The University of Toronto study (September 2025) was the first large-scale analysis across ChatGPT, Perplexity, Gemini, and Claude. Their most striking finding: AI search overwhelmingly favors earned media. In consumer electronics, AI cited third-party authoritative sources 92.1% of the time, compared to Google’s 54.1%. Automotive showed a similar pattern at 81.9% versus 45.1%. In other words, it’s not just how you write content, but whose domain it appears on. Press coverage, product reviews on independent websites, and mentions on industry publications carry far more weight in AI responses than your own website.

Carnegie Mellon’s AutoGEO study (October 2025) used automated methods to discover what generative engines actually prefer. The results showed up to 50.99% improvement over the best baseline, with universal preferences emerging across engines: comprehensive topic coverage, factual accuracy with citations, clear logical structure with headings and lists, and direct answers to queries.

The GEO-16 framework (September 2025) analyzed 1,702 real citations from Brave, Google AI Overviews, and Perplexity. It identified 16 on-page quality factors that predict citation likelihood. The top three: metadata and freshness, semantic HTML, and structured data. Technical on-page factors matter as much as the quality of the writing itself.

And a reality check from Columbia and MIT’s ecommerce study (November 2025): of 15 common content rewriting heuristics, 10 produced negligible or negative results. The optimization strategies that did work converged toward truthfulness, user intent alignment, and competitive differentiation. Not tricks. Substance.

The overall pattern across all of this research: AI systems reward clarity, factual accuracy, and structure. They don’t reward marketing language, persuasion tactics, or keyword density.

Content Structure That Earns Citations

Based on the research and official guidance from Microsoft and Google, here’s what structurally makes content citable.

Heading hierarchy matters more than ever. Use descriptive H2 and H3 headings that each cover one specific idea. Microsoft lists strong headings as “signals that help AI know where a complete idea starts and ends.” Vague headings like “Learn More” or “Overview” give AI nothing to work with. A heading like “How AI parses content differently than search engines” tells the system exactly what the section contains.

Q&A format is native to AI. Write questions as headings with direct answers below them. Microsoft notes that “assistants can often lift these pairs word for word into AI-generated responses.” If your content answers the question someone asks an AI, and it’s structured as a clear question-and-answer pair, you’ve made the AI’s job easy.

Make content snippable. Bulleted and numbered lists, comparison tables, step-by-step instructions. These formats give AI clean, extractable fragments. A paragraph buried in a wall of text is harder for AI to isolate than the same information presented as a three-item list.

Front-load the answer. Start sections with the key information, then provide context. If someone asks, “What temperature should I bake bread at?” and your content opens with a two-paragraph history of bread making before mentioning 375°F, you’ll lose the citation to a competitor who leads with the answer.

Keep sections self-contained. Each section should make sense on its own, without requiring the reader to have read the previous section. AI extracts fragments. If your fragment only makes sense in the context of the whole page, it won’t be selected.

An important technical note from Microsoft: “Don’t hide important answers in tabs or expandable menus: AI systems may not render hidden content, so key details can be skipped.” FAQ answers collapsed inside an expandable menu, product specs hidden behind tabs, content that requires interaction to reveal: it may all be invisible to AI. If information is important, it needs to be in the visible HTML.

Authority Signals For AI

E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness) isn’t just a Google concept anymore. It’s what AI systems look for across the board, even if they don’t use the term.

Microsoft’s October 2025 guidance describes the baseline: success starts with content that is “fresh, authoritative, structured, and semantically clear.” On the clarity side, they’re specific: “avoid vague language. Terms like innovative or eco mean little without specifics. Instead, anchor claims in measurable facts.” Saying something is “next-gen” or “cutting-edge” without context leaves AI unsure how to classify it.

The research backs this up. The original GEO paper found that writing in a persuasive or authoritative tone did not improve AI visibility. Facts and cited sources did. Marketing language doesn’t impress algorithms.

This connects to the University of Toronto’s finding about earned media dominance. AI systems trust third-party validation more than self-promotion. In consumer electronics, AI cited third-party authoritative sources 92.1% of the time compared to Google’s 54.1%. The implication: getting your expertise published on industry websites, earning press coverage, and building a presence on authoritative platforms matters more for AI visibility than perfecting the copy on your own site.

Freshness is a signal, not a bonus. Stale content rarely gets cited. Krishna Madhavan said at Pubcon Cyber Week: “Stale or missing content will constrain the amount of retrieval we can do and push agents toward alternative sources.”

Schema Markup: From Text To Knowledge

Microsoft’s October 2025 post devotes an entire section to schema. They describe it as code that “turns plain text into structured data that machines can interpret with confidence.” Schema can label your content as a product, review, FAQ, or event, giving AI systems explicit context instead of forcing them to guess. Krishna Madhavan reinforced this at Pubcon: “Schemas are super useful. They help the system discern exactly what your information is without us having to guess.”

The GEO-16 framework confirms this from the academic side. Structured data was one of the top three factors predicting AI citation likelihood, alongside metadata/freshness and semantic HTML.

The schema types that matter most for AI visibility:

  • FAQPage for question-and-answer content (directly maps to how AI formats responses).
  • HowTo for step-by-step instructions.
  • Product with Offer, AggregateRating, and Review for ecommerce.
  • Article/BlogPosting for content with clear authorship and dates.
  • Organization for business identity.

Pair structured data with IndexNow for freshness. As the Bing Webmaster Blog put it: “IndexNow tells search engines that something has changed, while structured data tells them what has changed. Together, they improve both speed and accuracy in indexing.”

Crawler Permissions: Who Gets In

AI search engines use distinct crawlers, and most let you control training and search access separately. Here’s who to allow.

Bot Platform Purpose Robots.txt Token
OAI-SearchBot ChatGPT Search index OAI-SearchBot
GPTBot OpenAI Model training GPTBot
ChatGPT-User ChatGPT On-demand browsing ChatGPT-User
Bingbot Microsoft Copilot Search + AI Bingbot
Googlebot Google AI Overviews Search + AI Googlebot
Google-Extended Google Gemini training Google-Extended
PerplexityBot Perplexity Search + index PerplexityBot
Perplexity-User Perplexity On-demand browsing Perplexity-User
ClaudeBot Anthropic Training + retrieval ClaudeBot

A sensible robots.txt configuration might allow search crawlers while blocking training:

User-agent: OAI-SearchBot
Allow: / User-agent: ChatGPT-User
Allow: / User-agent: GPTBot
Disallow: / User-agent: Google-Extended
Disallow: /

OpenAI provides the cleanest bot separation. You can allow OAI-SearchBot (so your content appears in ChatGPT search) while blocking GPTBot (so it’s not used for model training). Google’s controls are less granular: blocking Google-Extended prevents Gemini training but has no effect on AI Overviews, which use Googlebot.

OpenAI also offers the most specific technical recommendation of any AI search provider. For their Atlas browser (which uses a standard Chrome user agent, not a bot identifier), they recommend following WAI-ARIA best practices: “Add descriptive roles, labels, and states to interactive elements like buttons, menus, and forms. This helps ChatGPT recognize what each element does and interact with your site more accurately.” Accessibility and AI agent compatibility are the same work.

A caveat on Perplexity: while their documentation states they respect robots.txt, Cloudflare documented in August 2025 that Perplexity uses undeclared crawlers with rotating IPs and spoofed browser user agents to bypass no-crawl directives. This is a contested claim, but it’s worth knowing.

For revenue, Perplexity is the only platform currently offering publisher compensation. Their Comet Plus program provides an 80/20 revenue split (publishers keep 80%) across direct visits, search citations, and agent actions.

Google Vs. Microsoft: Two Philosophies

The contrast between Google and Microsoft on AEO is striking enough to be its own story.

Google says: just do good SEO. Their official documentation is deliberately minimalist: “There are no additional requirements to appear in AI Overviews or AI Mode, nor other special optimizations necessary.” They add that you “don’t need to create new machine readable files, AI text files, or markup to appear in these features.”

Google recommends helpful, reliable, people-first content demonstrating E-E-A-T. Standard structured data. Good page experience. Technical basics. Nothing AI-specific.

Microsoft says: here’s the playbook. Their October 2025 blog post and January 2026 guide provide detailed, actionable guidance. Specific heading structures. Schema recommendations. Content formatting rules. Concrete examples (an AEO product description vs. a GEO product description). Warnings about content hidden in tabs and expandable menus. A framework for thinking about crawled data, product feeds, and live website data as three distinct layers.

What explains the difference? Partly market position. Google dominates search and has less incentive to help publishers optimize for AI features that might reduce clicks to their websites. Microsoft, with Bing’s roughly 8% market share, benefits from providing publishers with reasons to optimize specifically for their ecosystem.

But there’s a practical takeaway: Microsoft’s guidance isn’t Bing-specific. The principles of structured content, clear headings, snippable formats, schema markup, and expert authority are universal. Following Microsoft’s playbook improves your content for every AI system, including Google’s. Google just won’t tell you that.

Measuring AI Visibility

This is the hard part. Traditional SEO has Google Search Console. AI visibility is still fragmented.

Ahrefs analyzed 1.9 million citations from 1 million AI Overviews and found that 76% of citations come from pages already ranking in Google’s top 10. The median ranking for the most-cited URLs was position 2. Traditional ranking still matters for AI citation, but being No. 1 is “a coin flip at best” for getting cited.

The traffic impact is significant. Ahrefs found that AI Overviews correlate with 58% lower click-through rates for the No. 1 position. Seer Interactive reported a 61% organic CTR drop for queries with AI Overviews. But being cited within the AI Overview gives 35% more organic clicks compared to not being cited. Citation is the new ranking.

For tracking, the tool landscape is emerging:

Tool What It Tracks Starting Price
Profound Citations across ChatGPT, Perplexity, Copilot, Google AIOs From $99/mo
Peec.ai Brand mentions across ChatGPT, Gemini, Claude, Perplexity From ~$95/mo
Advanced Web Ranking AIO presence tracking in Google Included in plans
Bing Webmaster Tools AI Performance Report for Copilot Free

Bing Webmaster Tools is the easiest starting point. It’s free, and the new AI Performance Report shows how your content performs in Copilot citations. For ChatGPT specifically, track utm_source=chatgpt.com in your analytics. OpenAI automatically appends this to referral URLs.

Conductor’s January 2026 report found that 87.4% of AI referral traffic comes from ChatGPT. That’s one platform dominating the space, which makes tracking it particularly important.

Key Takeaways

  • AI selects fragments, not pages. Structure your content in self-contained, extractable sections with descriptive headings that signal where each idea starts and ends.
  • Clarity beats persuasion. Factual accuracy, cited sources, and direct answers outperform authoritative tone and marketing language. The research consistently shows this.
  • Earned media dominates brand content in AI citations. Press coverage, third-party reviews, and authoritative mentions on other websites carry more weight than your own pages. Build presence beyond your domain.
  • Schema markup is a force multiplier. FAQPage, HowTo, Product, and Article schemas make your content machine-readable. Pair with IndexNow for freshness.
  • Follow Microsoft’s playbook, even for Google. Google says “just do good SEO.” Microsoft provides specific, actionable guidance that improves content for every AI system, Google’s included.
  • Separate training from search in your robots.txt. Allow search crawlers (OAI-SearchBot, Bingbot, PerplexityBot) while blocking training crawlers (GPTBot, Google-Extended) if that’s your preference. You have more control than you might think.
  • Track AI visibility now. Use Bing Webmaster Tools (free), monitor utm_source=chatgpt.com in analytics, and consider dedicated tools as the measurement space matures.

Traditional SEO asked: “How do I rank?” AEO asks: “How do I become the fragment that gets selected?” The answer isn’t a single trick. It’s clear structure, verifiable expertise, and content that AI can confidently extract and cite.

Up next in Part 3: the protocols powering the agentic web, including MCP, A2A, NLWeb, and AGENTS.md, and how they fit together.

More Resources:


This was originally published on No Hacks.


Featured Image: Meepian Graphic/Shutterstock

https://www.searchenginejournal.com/answer-engine-optimization-how-to-get-your-content-into-ai-responses/570055/


Google Takes Search Live Global With Gemini 3.1 Flash Live via @sejournal, @MattGSouthern

Google is expanding Search Live to more than 200 countries and territories, bringing voice and camera conversations to AI Mode globally.

The expansion is powered by Gemini 3.1 Flash Live, a new audio model that Google calls its highest-quality yet. It’s inherently multilingual, so you can speak with Search in your preferred language without switching settings.

Search Live was previously limited to the U.S.

What’s Changing

Search Live lets you talk to Google Search inside AI Mode instead of typing a query. You ask a question out loud and get an audio response, then continue with follow-ups. Web links appear on screen alongside the voice responses.

The feature also supports camera input. Point your phone at a product label or a piece of equipment and ask Search about what it sees. Google Lens users can tap a “Live” option to start a conversation about what’s in the camera view.

With today’s expansion, both voice and camera capabilities are available in every market where AI Mode is active.

The New Model

Gemini 3.1 Flash Live replaces the previous audio model powering Search Live. Google published benchmark results alongside the announcement.

Gemini Live can now follow a conversation thread for twice as long as the previous model, according to Google. Though the company didn’t specify what the previous limit was.

Beyond Search, 3.1 Flash Live is available to developers in preview through the Gemini Live API in Google AI Studio.

Why This Matters

Search Live turns search into a spoken conversation with camera input. Until now, the feature was limited to U.S. users. Today’s expansion makes it available in the markets where AI Mode is live, across more than 200 countries and territories.

There’s no public data yet on how many people use Search Live or how it affects query volume. But Google has been building toward this for the past year. The company launched Search Live in June, added video input in July, and upgraded to Gemini 2.5 Flash Native Audio in December. Each update expanded what the feature can do and who can use it.

Looking Ahead

Google didn’t announce additional Search Live features alongside this expansion. The focus is on geographic reach and the underlying model upgrade.

How the model performs in production across different languages and markets will be worth watching as adoption data becomes available.

https://www.searchenginejournal.com/google-takes-search-live-global-with-gemini-3-1-flash-live/570602/


NanoClaw Creator Loses SEO Battle To Impostor Website via @sejournal, @MattGSouthern

The creator of NanoClaw, an open source AI agent platform with over 18,000 GitHub stars, says Google is ranking a fake website above his project’s real site.

In tests conducted on March 5, an impostor site ranked at the top of Google for the project’s own name. The real website, nanoclaw.dev, did not appear in the first several pages of results.

What’s Happening

Gavriel Cohen, a software engineer and former Wix developer, posted a thread on X describing the problem.

Cohen launched NanoClaw in early February as a security-focused alternative to OpenClaw, the viral open source AI agent platform. The project grew quickly. VentureBeat covered it, The Register profiled Cohen, and AI researcher Andrej Karpathy publicly praised the project’s architecture.

Around February 8, someone registered nanoclaw.net and created an auto-generated site scraped from the project’s GitHub README. Cohen said he didn’t have a website at the time because the GitHub repo was the project.

As the project gained press coverage, people kept contacting him about problems with “his” website. It wasn’t his.

He built the real site at nanoclaw.dev and then took several standard SEO and remediation steps. He linked it from the GitHub repo. He added structured data. He submitted to Google Search Console. He filed takedown notices with Google, Cloudflare, and the domain registrar. Publications covering the project linked to nanoclaw.dev.

As of March 5, the impostor site still ranked above the real one.

In his thread, Cohen wrote that the fake site is “showing factually wrong information about the project and falsifying its publication dates.” He called the situation “a live, active security risk” because the person running nanoclaw.net could replace the page content with malicious download links or a phishing page at any time.

The Hacker News thread about Cohen’s complaint reached 315 points and over 150 comments within hours.

Same Problem Across Search Engines

Hacker News commenters tested the same search on other engines and found the problem extends beyond Google.

One commenter reported that the fake site ranked #1 on DuckDuckGo and #3 on Kagi, while the real site didn’t appear on DuckDuckGo at all. Another found that Bing, Brave, Ecosia, and Qwant all showed the fake site in top positions. Mojeek was the only engine tested that ranked the real site and excluded the fake one.

Why This Matters

In the past, Google’s John Mueller said that copied content consistently ranking above the original may point to a site quality problem. Mueller suggested site owners reassess their overall quality if this keeps happening.

Cohen’s case tests that logic. His project has 18,000 GitHub stars, coverage from CNBC, VentureBeat, and The Register, a Karpathy endorsement, and a blog post that hit #1 on Hacker News. Every social profile and the GitHub repo itself point to nanoclaw.dev. On its face, many of the visible signals appear to favor the real site.

The fact that Hacker News commenters reported similar results across multiple search engines suggests something deeper than a Google-specific bug. One possible factor is timing, as the fake site appears to have been indexed before the real site launched.

For anyone building a new product, the key takeaway here is to reconsider the right time to register a domain. Cohen focused on shipping code before building a website. That’s standard open source practice, but search engines indexed the impostor first, and correcting that after the fact proved harder than any of the recommended steps suggest it should be.

Looking Ahead

Cohen has not indicated whether Google responded to his takedown requests. One SEO practitioner in the Hacker News thread offered concrete advice, including mapping the fake site’s backlinks and contacting publications that accidentally linked to the wrong domain.

The situation remains unresolved. Google had not commented at the time of publishing.


Featured Image: Elnur/Shutterstock

https://www.searchenginejournal.com/nanoclaw-creator-loses-seo-battle-to-impostor-website/568885/


The Verified Source Pack Agents Trust First via @sejournal, @DuaneForrester

Structured data helped machines interpret pages. It reduced ambiguity. It made entities and attributes legible to crawlers that were otherwise guessing.

Agents change the job because they do not just interpret pages. They decide, summarize, recommend, and sometimes execute. That means they need more than “this page is about X.” They need “this is the official truth about X, it is current, and you can verify it.”

That is the gap most teams have not addressed yet.

Image Credit: Duane Forrester

If you are a technical SEO, you’ve already done the hard part of this job in other forms. You’ve built crawl paths, canonicalization systems, change control habits, structured data governance, and index hygiene. A Verified Source Pack is the next packaging layer. It is not a replacement for pages. It is not a replacement for schema. It is a distribution artifact that sits beside both.

The simplest framing is this. In an agent world, brands ship a machine-consumable “official truth” pack. It includes structured facts and operational rules an agent can safely ingest: products, pricing rules, inventory behavior, guarantees, credentials, policies, support workflows, and explicit constraints. It is delivered with provenance, versioning, and a clear discovery path.

Call it a Verified Source Pack. Call it an Official Knowledge Pack. Call it an Agent Source Object. The naming will evolve, but the need will not. The need is here, today.

Why This Matters Now

Agents optimize for trust and completion.

If an agent is going to recommend a product, explain your return policy, determine warranty eligibility, estimate delivery windows, or suggest a plan that includes you, it needs facts that do not wobble. If it can’t get those facts with confidence, it does one of three things. It hedges and becomes vague. It pulls from third parties that look more structured. Or it avoids recommending you at all because the risk of being wrong is too high.

This is why classic brand signals are not enough. Brand matters to humans. Agents need machine trust, and machine trust is not vibes. It is structure, provenance, and freshness.

We Are Early, And That’s Fine

Search had 25+ years to standardize conventions. This new ecosystem is younger and messier. There is no single, universally adopted “truth pack” standard today.

What exists instead is a set of practical primitives you can assemble in a way that works now and remains compatible with the future. Think of this as the early sitemap era. If you shipped clean signals early, you won. The mechanics changed over time, but the principle held.

Where Llms.txt Fits, Even With Its Limits

You’ll hear about /llms.txt in this conversation, as it is a proposal for publishing a curated map of your site intended for LLMs and agents at inference time. The spec is here: https://llmstxt.org/.

The critical point is what it is not. It is not a vendor-backed commitment. No major LLM provider has publicly signed on saying “we will consume llms.txt” as a standard behavior. That does not mean systems ignore it, but it does mean you should treat it as more of a directional hint, not a trust mechanism.

What is interesting, and worth calling out, is that solution providers are already responding. Yoast has documented how it generates llms.txt, including update behavior, which signals that parts of the ecosystem believe this will matter even if the platforms have not formally blessed it yet.

You can see similar “this is becoming a thing” signals from other platforms. For example, Optimizely recently published guidance on llms.txt as well.

So, I mention llms.txt as an example of a discovery layer. It is not a guaranteed ingestion path. It is a convenience map that can point at your real asset, which is the verified pack.

The Verified Source Pack, Explained As A Complete System

A Verified Source Pack has four parts. Each part answers a different question an agent implicitly asks.

First, The Content

What is the truth you are publishing?

This is not “content marketing.” This is operational truth the business would stand behind. In ecommerce, for example, it includes your product catalog, your pricing rules, your inventory behavior, shipping and returns policies, warranty terms, guarantees, service coverage, support workflows, and explicit constraints. Constraints matter because agents otherwise guess. If you do not clearly state exclusions, eligibility rules, edge cases, and limits, you are forcing the model to infer them from messy pages or third parties.

Second, The Structure

Can a machine ingest it predictably?

This usually means two modes. A dataset mode for facts that can be downloaded and parsed, and a contract mode for facts that change fast or require live validation.

Dataset mode is boring on purpose. JSON for structured facts. CSV for bulk lists if you have to. A changelog that records what changed and when. The goal is not elegance. The goal is predictable parsing.

Contract mode is where your technical SEO role gets real leverage, because it is the point where you ask your dev team for an endpoint. One clean endpoint that returns the pack index, plus one signed manifest. If you can only get one thing built this quarter, get that.

Third, The Provenance

How does an agent know it is yours and unmodified?

Provenance starts with domain control and TLS, but it should not stop there. Provenance means you version the pack, timestamp it, hash the files, and sign the index. That creates an integrity model that a machine can validate.

If you want a real-world standard to anchor the idea of cryptographically verifiable provenance, C2PA is one of the clearest references. It is best known for media authenticity, but the underlying concepts map cleanly: manifests, hard bindings via hashes, and verifiable claims. Start with the C2PA specifications index here and the technical specification here.

You do not need to implement C2PA end-to-end to benefit from the pattern. The point for SEOs is that “trust” can be made explicit through verifiable artifacts, not implied through branding.

Fourth, Discoverability

Can systems reliably find the pack?

A Verified Source Pack that cannot be found is a private internal doc, not an external trust signal. Host it under your domain in a stable, boring path. Link to it from a relevant page like Policies, Support, or Developer docs. Include it in your sitemap. Optionally point to it from llms.txt as a hint.

The SEO-Friendly Build Flow

Here is the same system, but framed as a practical flow you can run with your team.

Start by inventorying your truth domains. Define what the business would defend as official truth. For ecommerce, that is, products, pricing rules, inventory logic, shipping rules, returns policy, warranty terms, guarantees, and support workflow. Add constraint truth as a first-class domain. Write down exclusions, eligibility requirements, and boundaries. If you skip constraints, the agent fills the gap with assumptions.

Next, canonicalize. You do not need perfection, but you need a declared canonical source for each truth domain. If five pages disagree on returns, pick the canonical version and update the others over time. The pack is how you stop the bleeding.

Then ship the pack in two layers. Publish the dataset files and publish a single pack index that references them. The pack index is your “front door” and should include the pack version, last updated time, file URLs, hashes, and verification details.

At this point, you ask for two technical deliverables from your dev team.

  1. Deliverable one is one endpoint. It returns the pack index which gives agents a consistent, requestable source rather than a scraping problem.
  2. Deliverable two is one signed manifest. That can be as simple as a detached signature for the index file, or a signature field embedded in the index. The implementation can vary, but the intent is constant: integrity and provenance.

If your org can publish a callable endpoint, describe it with OpenAPI. It’s a widely used, vendor-neutral way to define API contracts, and it’s already accepted in multiple agent ecosystems, including GPT Actions, Microsoft 365 Copilot API plugins, and Google Vertex AI Extensions.

This matters because it reduces friction, and you are not inventing a bespoke integration. You are publishing a contract that agents and tooling ecosystems already know how to consume.

Finally, operationalize freshness. Add review-by dates and a changelog. Inventory and pricing should be updated frequently or exposed via live endpoints. Policies can be versioned on change. Credentials should update on renewal and revocation events. Support workflows should update when your operations change.

Treat the pack like infrastructure. Infrastructure decays when it has no owner, so assign an owner.

Here’s An Ecommerce Example

Imagine a mid-market ecommerce brand. Today, product attributes live in the catalog, warranty terms live in an FAQ, returns rules live across three pages, shipping exceptions live in a footer, and “what counts as refurbished” exists only in support scripts. Humans can muddle through. Agents cannot.

A Verified Source Pack fixes that by creating one coherent, machine-ingestible representation of those truths.

The pack index points to a product catalog dataset, a pricing rules dataset, a returns and shipping policy dataset that includes edge cases, a warranty and guarantee dataset, a support workflow dataset, and a constraints dataset that spells out what is excluded and what requires human confirmation. The index is versioned and signed. The index can be retrieved via an endpoint. The pack is hosted under the brand domain and linked from policy pages.

Now, when an agent asks, “Can I return this item if it was opened?” it has an authoritative, structured place to look. When it asks, “Is this product available in my ZIP code?” the brand can expose a live endpoint. When it needs to summarize warranty terms, it can do so without guessing, and without relying on a third-party blog post from 2019. That is the win you’re after here.

Sidebar: Healthcare, Where Trust Is Regulated

Healthcare teams have extra constraints that ecommerce does not.

First, you must avoid publishing anything that could be interpreted as protected personal information, or that encourages an agent to infer patient-specific conclusions.

Second, you have regulatory boundaries around claims. Treatments, outcomes, eligibility, and recommendations cannot be reduced to marketing copy. They need carefully scoped, auditable statements.

Third, you need change control and auditability. If a policy changes, you need a clear record of what changed and when.

For healthcare, a Verified Source Pack should lean hard into constraints. Spell out what the system can state, and what requires a clinician or a formal consult. Publish provider credentials, service coverage, appointment workflows, billing and insurance boundaries, privacy and security policies, and escalation paths. Sign and version everything. Make review-by dates explicit.

Sidebar: Finance, Where Guardrails Matter As Much As Facts

Finance has a similar trust profile, with different failure modes.

First, advise boundaries. Agents will naturally drift from facts into advice. Your pack should explicitly declare what is informational, what is not advice, and what requires qualified review.

Second, volatility. Rates, terms, eligibility, and fees can change quickly. Live endpoints matter more here than in ecommerce. If you publish a dataset, include “valid through” fields and enforce refresh cadence.

Third, disclosure requirements. Your pack should include the exact disclosure language and conditions required, so the agent is less likely to summarize away legally important details.

A Quick Note On MCP

You will also hear about Model Context Protocol (MCP), which is an open protocol for integrating LLM applications with external data sources and tools. The MCP spec is here.

You do not need MCP to build a Verified Source Pack. The relevance is directional. Agents are moving toward calling authoritative interfaces rather than scraping pages. Your “one endpoint and one signed manifest” is the pragmatic step that keeps you compatible with that future.

The Point, And The Opportunity For Technical SEO Leads

You are not being asked to abandon SEO, but you are being asked to extend it.

In the same way sitemaps and structured data became quiet infrastructure, Verified Source Packs will become quiet infrastructure for agentic retrieval and decisioning. Teams that publish operational truth in a machine-verifiable way reduce ambiguity, reduce downstream risk, and increase the odds they are the source the system trusts first.

If you want a single mental model, use this.

  • Pages persuade humans.
  • Schema clarifies pages.
  • Verified Source Packs package truth for agents.

That’s the new format.

More Resources:


This post was originally published on Duane Forrester Decodes.


Featured Image: Summit Art Creations/Shutterstock; Paulo Bobita/Search Engine Journal

https://www.searchenginejournal.com/the-verified-source-pack-agents-trust-first/568506/


Why Google Discover Is No Longer Just For Publishers via @sejournal, @theshelleywalsh

At Google Search Central Live in Zurich last December, Clara Soteras spoke about how brands and ecommerce sites can use Discover as a strategy.

Discover is a dominant source of traffic for news publishers, and currently, is a potential channel that has resisted the encroachment of AI. So, I was interested to see how Discover might hold opportunities beyond the newsroom.

However, in Zurich, John Mueller repeated his advice that Google Discover traffic is for free, and someday it can be zero. Much like the reality of Google traffic diminishing for many brands.

So, I sat down with Clara on IMHO to talk about what’s working, what’s breaking, and where the real opportunity lies in 2026.

Clara is head of innovation and digital strategy at AMIC and a professor at the Autonomous University of Barcelona, where she teaches SEO for news at several business schools.

“Discover adds to you some possibility to catch and to impact people that don’t know that they need you.”

Discover Is The Primary Channel, But With A Warning

In an article titled “Why publishers should worry about growing reliance on Google Discover,” the Press Gazette reported that for 2,000 global news and media websites, 68% of Google traffic now comes from Discover, in comparison to 32% from search.

I asked Clara if she thought Discover could offer any salvation to news publishers impacted by AI.

She confirmed what many publishers are experiencing, “Google Discover is the first channel of traffic for the majority of publishers today. And we need to understand that this is a good channel to achieve and to catch different audience, to achieve page views and volume of traffic.”

But Clara was quick to draw a line between Discover and traditional search. The ranking factors are different, and publishers who treat Discover as an extension of their search strategy are making a mistake.

“The basic things are the same, but we need to know that the location, the image, or the title, the headline are really important to rank on Google Discover.”

She also noted that not all content categories perform equally in the feed. Politics, for example, rarely appears. Publishers who want Discover visibility need to lean into lifestyle, sports, and culturally relevant content.

It’s For Free. And Someday It Can Be Zero

At Google Search Central Live in Zurich, John Mueller emphasized a key point that publishers cannot rely on getting 90% of their traffic from a single source. I asked Clara whether we might be in danger of swapping one reliance for another, from Google SERP traffic to Discover, and if publishers should be leveraging other channels.

Clara explained, “In Zurich, John Mueller repeats the same advice that Google is telling in every session that we have with the publishers. They think that the volume of traffic that Google Discover adds to your website is for free, and someday it can be zero.”

That volatility is real, “We know some publishers that start from scratch and achieve a lot of traffic and six months later they need to close the website because they lose all the traffic.”

When I asked what balance she would recommend, Clara said it depends on the size and niche of the publisher, but “you cannot have 90% of Google Discover traffic because if Google Discover decides to not see you tomorrow, you will lose all your audience because it’s not a loyal audience.”

Discover traffic is passive. It’s algorithmically injected into feeds, and Clara suggested that publishers need to diversify into social strategy, work with content creators, and consider building community around their topics.

How Brands Can Win In Discover

Clara’s presentation in Zurich was about a strategy most brands haven’t considered, applying newsroom methodology to Discover for ecommerce and brand sites.

Google has expanded the Discover feed to allow users to follow entities, creators, and companies, not just traditional publishers. YouTube, Instagram, and content creator profiles now appear, and for brands, this opens a different kind of opportunity.

“Search is the first channel probably for commerce because the user knows your brand or knows what they need. Discover adds the possibility to catch and impact and generate impressions to people that don’t know that they need you.”

Her methodology for brands mirrors what high-performing newsrooms do, which is to monitor social conversations and trends, align content to the moment, and move quickly.

“If we decide to create a strategy for a brand, we need to talk about the trend of the day. We need to talk about our product and service but really near to the trend.”

Clara is currently working with content teams at multiple companies to train them on Discover-specific execution. Headlines need to be more than 13 words, images must be chosen strategically for the format, and brands need to build entity authority through a sustained cluster strategy, publishing around the same entity on different days.

“For me, some of the best ranking factors are the image, the headline, and working with the entity every day to be a good reference for this entity.”

AI Content Can Rank In Discover, But It Doesn’t Perform

Andy Almeida from Google’s Trust and Safety team for Discover has said that nearly 20% of sites recommended by Discover are AI-generated, coining the memorable phrase “AI slop is taking over the world.” I asked Clara whether AI content is becoming a real threat that could displace legitimate news publisher content, and how publishers can defend against it.

Clara acknowledged the reality that AI content does rank on Discover. But she pointed out that Google’s quality and trust department is actively applying manual penalties when they identify AI content or fake news in the feed.

“If they think that you are publishing AI content or fake news, they can apply and ask that you need to raise or correct your content.”

More importantly, she shared a real-world example from her own clients that illustrates the performance gap between AI and human content.

“I had a client that worked with different AI tools to create basic content, and journalists adapted a little bit of this content. If you see the performance, you see only 100 views for an article versus 12,000 views for another article created by a human.”

Clara’s position is that AI can assist with ideation and strategic planning, but the content itself needs to be created by humans. Human-created content performs better in Discover, and she believes Google will continue to reward it.

“AI can give us ideas and strategic tips but for me it’s important that the content will be created by a human, by a journalist.”

The Opportunity AI Overviews Can’t Touch

With AI Overviews eating evergreen informational queries, I asked Clara what she thinks are the areas of opportunity in 2026.

Clara is currently working on research reports analyzing the impact of AI Overviews on publishers in Spain and the UK, and her data confirms, “ if you work with breaking news, you have an opportunity, because of the top stories module for breaking news.”

Real-time journalism still creates visibility that AI summaries cannot fully replace. For publishers looking ahead to 2026, Clara’s focus is on reinforcing the strengths that machines can’t replicate. Breaking news speed, entity authority, trend alignment, and diversification beyond Discover itself.

Human Expertise Is The Advantage

Google Discover is a powerful channel and in many cases essential, but it’s algorithmically volatile by nature.

However, it’s an opportunity for brands and ecommerce sites. The Discover feed is no longer a news-only space, and Clara’s work applying newsroom methodology to commercial content is an approach that most brands haven’t explored yet.

Where AI is reshaping both search results and the content that feeds them, the competitive advantage is ultimately down to human expertise, editorial judgment, and the ability to move fast on what matters right now.

Watch the full interview with Clara Soteras here:

[embedded content]

Thank you to Clara Soteras for offering her insights and being my guest on IMHO.

More Resources:


This post was originally published on Shelley Edits.


Featured Image: Shelley Walsh/Search Engine Journal

https://www.searchenginejournal.com/why-google-discover-is-no-longer-just-for-publishers/568777/